1
AUTOMATIC1111 / stable-diffusion-webui
Stable Diffusion web UI
View AUTOMATIC1111/stable-diffusion-webuiThe image board collects GitHub projects that work with pictures: generation and diffusion models, computer vision, upscaling, background removal, OCR, annotation and the plumbing around them. Entries come from GitHub topic pages for image generation, stable diffusion and computer vision, ranked by total stars, so the list mixes well-known model repositories with newer tools that are still gaining ground. Every card shows the language, star and fork counts, and opens a detail page with the project description, license, last push date and README, plus related image projects drawn from the same board. If you are choosing a library to build on, check the last push date on the detail page before you commit — the board is about popularity, not maintenance.
Stable Diffusion web UI
View AUTOMATIC1111/stable-diffusion-webui
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
View Comfy-Org/ComfyUI →
Local UI to run and train LLMs and diffusion models. Supports GGUF, MLX, Qwen3.8, DeepSeek-V4.1, MiniMax-H3, Gemma 4, FLUX and more.
View unslothai/unsloth
Ultralytics YOLO27, YOLO26, YOLO11, YOLOv8 — object detection, instance segmentation, semantic segmentation, image classification, pose estimation, object tracking
View ultralytics/ultralyticsUltralytics YOLOv5 in PyTorch for object detection, instance segmentation, classification, training, and export.
View ultralytics/yolov5 →
LocalAI is the open-source AI engine. Run any model - LLMs, vision, voice, image, video - on any hardware. No GPU required.
View mudler/LocalAI
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch.
View huggingface/diffusers
OpenPose: Real-time multi-person keypoint detection library for body, face, hands, and foot estimation
View CMU-Perceptual-Computing-Lab/openpose
🚀 AI 全自动短视频引擎 | AI Fully Automated Short Video Engine
View ATH-MaaS/Pixelle-Video
AI-agent Skill for generating polished HTML slide decks: editorial magazine and Swiss layouts, image prompts, social covers, and a WebGL/low-power presentation runtime.
View op7418/guizang-ppt-skill
Invoke is a leading creative engine for Stable Diffusion models, empowering professionals, artists, and enthusiasts to generate and create visual media using the latest AI-driven technologies.
View invoke-ai/InvokeAI
Implementation of Vision Transformer, a simple way to achieve SOTA in vision classification with only a single transformer encoder, in Pytorch
View lucidrains/vit-pytorch
Image-to-Image Translation in PyTorch
View junyanz/pytorch-CycleGAN-and-pix2pix
Original reference implementation of "3D Gaussian Splatting for Real-Time Radiance Field Rendering"
View graphdeco-inria/gaussian-splatting
Image inpainting tool powered by SOTA AI Model. Remove any unwanted object, defect, people from your pictures or erase and replace(powered by stable diffusion) any thing on your pictures.
View Sanster/IOPaint →
短剧、漫剧制作工具 Toonflow:开源 AI 视频创作平台,集成剧本创作、智能分镜、角色与场景资产管理、图像生成和视频生成。融合无限画布、AI Agent 与可视化工作流,支持本地部署、自选模型、跨平台客户端、MCP 与插件扩展。Open-source AI short drama and motion comic creation tool with an infinite canvas
View HBAI-Ltd/Toonflow-app →
Instant neural graphics primitives: lightning fast NeRF and more
View NVlabs/instant-ngp
CVAT is a leading data annotation platform for image, video, audio, and 3D datasets. It offers open-source, cloud, and enterprise products, as well as labeling services, with AI-assisted labeling
View cvat-ai/cvat
Image annotation with Python. Supports polygon, rectangle, circle, line, point, and AI-assisted annotation.
View wkentaro/labelme
stable diffusion webui colab
View camenduru/stable-diffusion-webui-colab
State-of-the-Art Deep Learning scripts organized by models - easy to train and deploy with reproducible accuracy and performance on enterprise-grade infrastructure.
View NVIDIA/DeepLearningExamples →
Formerly KrillinAI, VideoTranslation and Dubbing Tool for 120+ Languages. Open-source AI workspace for creators, powered by Codex.
View krillinai/OpenCreator
Diffusion Bee is the easiest way to run Stable Diffusion locally on your M1 Mac. Comes with a one-click installer. No dependencies or technical knowledge needed.
View divamgupta/diffusionbee-stable-diffusion-ui →
Advanced AI Explainability for computer vision. Support for CNNs, Vision Transformers, Classification, Object detection, Segmentation, Image similarity and more.
View jacobgil/pytorch-grad-cam
Drench yourself in Deep Learning, Reinforcement Learning, Machine Learning, Computer Vision, and NLP by learning from these exciting lectures!!
View kmario23/deep-learning-drizzleSoftware that can generate photos from paintings, turn horses into zebras, perform style transfer, and more.
View junyanz/CycleGAN →
Semantic segmentation models with 500+ pretrained convolutional and transformer-based backbones.
View qubvel-org/segmentation_models.pytorch
Visualize, query, and stream to train on multimodal robotics data.
View rerun-io/rerun →
 →
X-AnyLabeling: A lightweight, efficient, and unified cross-platform desktop application for annotating text, image, video, point cloud and multimodal data
View CVHub520/X-AnyLabeling
Streamlined interface for generating images with AI in Krita. Inpaint and outpaint with optional text prompt, no tweaking required.
View Acly/krita-ai-diffusion
Image-to-image translation with conditional adversarial nets
View phillipi/pix2pix
🦙 LaMa Image Inpainting, Resolution-robust Large Mask Inpainting with Fourier Convolutions, WACV 2022
View advimman/lamaRF-DETR is a real-time object detection and segmentation model architecture developed by Roboflow, SOTA on COCO, designed for fine-tuning. [ICLR 2026]
View roboflow/rf-detr
Best Practices, code samples, and documentation for Computer Vision.
View microsoft/computervision-recipes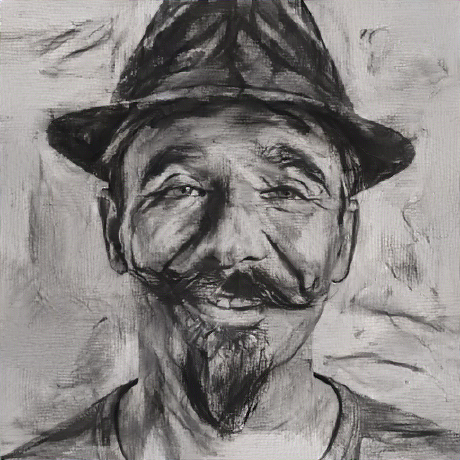
Turn your two-bit doodles into fine artworks with deep neural networks, generate seamless textures from photos, transfer style from one image to another, perform example-based upscaling, but wait...
View alexjc/neural-doodle
Robust Video Matting in PyTorch, TensorFlow, TensorFlow.js, ONNX, CoreML!
View PeterL1n/RobustVideoMatting
Hello AI World guide to deploying deep-learning inference networks and deep vision primitives with TensorRT and NVIDIA Jetson.
View dusty-nv/jetson-inference
Multi-Platform Package Manager for Stable Diffusion
View LykosAI/StabilityMatrix
Text-to-3D & Image-to-3D & Mesh Exportation with NeRF + Diffusion.
View ashawkey/stable-dreamfusion
[NeurIPS 2024 Best Paper Award][GPT beats diffusion🔥] [scaling laws in visual generation📈] Official impl. of "Visual Autoregressive Modeling: Scalable Image Generation via Next-Scale Prediction".
View FoundationVision/VAR
Leading free and open-source face recognition system
View exadel-inc/CompreFace →
 →
PaddlePaddle GAN library, including lots of interesting applications like First-Order motion transfer, Wav2Lip, picture repair, image editing, photo2cartoon, image style transfer, GPEN, and so on.
View PaddlePaddle/PaddleGAN
Run Stable Diffusion on Mac natively
View MochiDiffusion/MochiDiffusion🪧 Claude Code / Codex skill — generate Xiaohongshu carousels & WeChat 21:9+1:1 cover pairs. Editorial × Swiss visual systems, 28 layouts, 10 themes, single-file HTML → PNG. 小红书图文 + 公众号封面对
View op7418/guizang-social-card-skill
fast-stable-diffusion + DreamBooth
View TheLastBen/fast-stable-diffusion
Diffusion model(SD,Flux,Wan,Qwen Image,Z-Image,...) inference in pure C/C++
View leejet/stable-diffusion.cpp
Implementation of Dreambooth (https://arxiv.org/abs/2208.12242) with Stable Diffusion
View XavierXiao/Dreambooth-Stable-Diffusion
Using Low-rank adaptation to quickly fine-tune diffusion models.
View cloneofsimo/lora
Go package for computer vision using OpenCV 4 and beyond. Includes support for DNN, CUDA, OpenCV Contrib, and OpenVINO.
View hybridgroup/gocv
OpenMMLab Multimodal Advanced, Generative, and Intelligent Creation Toolbox. Unlock the magic 🪄: Generative-AI (AIGC), easy-to-use APIs, awsome model zoo, diffusion models
View open-mmlab/mmagic →
SD.Next: All-in-one WebUI for AI generative image and video creation, captioning and processing
View vladmandic/sdnext
A user-friendly plug-in that makes it easy to generate stable diffusion images inside Photoshop using either Automatic or ComfyUI as a backend.
View AbdullahAlfaraj/Auto-Photoshop-StableDiffusion-Plugin
Easy Docker setup for Stable Diffusion with user-friendly UI
View AbdBarho/stable-diffusion-webui-dockerReal-Time High-Resolution Background Matting
View PeterL1n/BackgroundMattingV2
An APP that integrates mainstream large language models and image generation models, built with Flutter, with fully open-source code.
View mylxsw/aidea
Official Implementation of OCR-free Document Understanding Transformer (Donut) and Synthetic Document Generator (SynthDoG), ECCV 2022
View clovaai/donutSynthesizing and manipulating 2048x1024 images with conditional GANs
View NVIDIA/pix2pixHD
记录每天整理的计算机视觉/深度学习/机器学习相关方向的论文
View amusi/daily-paper-computer-vision →
open Multiple View Geometry library. Basis for 3D computer vision and Structure from Motion.
View openMVG/openMVG
Remove visible and invisible AI watermarks from images and video, and AI provenance metadata from images, video, and audio.
View wiltodelta/remove-ai-watermarks
SD-Trainer. LoRA & Dreambooth training scripts & GUI use kohya-ss's trainer, for diffusion model.
View Akegarasu/lora-scripts →
GPT Image 2/2.5 prompt gallery, image prompt library, agentic skill, and CLI for OpenAI image generation/editing
View wuyoscar/GPT-Image2-Skill
A Unified Toolkit for Deep Learning Based Document Image Analysis
View Layout-Parser/layout-parser
An agent skill that finds where a photo was taken — OpenStreetMap geometry, elevation skylines, satellite imagery and street view — and shows its work.
View Oldcircle/geo-sleuth
SUPIR aims at developing Practical Algorithms for Photo-Realistic Image Restoration In the Wild. Our new online demo is also released at suppixel.ai.
View Fanghua-Yu/SUPIR →
【🔞🔞🔞 内含不适合未成年人阅读的图片】基于我擅长的编程、绘画、写作展开的 AI 探索和总结:StableDiffusion 是一种强大的图像生成模型,能够通过对一张图片进行演化来生成新的图片。ChatGPT 是一个基于 Transformer 的语言生成模型,它能够自动为输入的主题生成合适的文章。而 Github Copilot 是一个智能编程助手,能够加速日常编程活动。
View phodal/understand-prompt→
Structured data extraction, instruction calling and agentic workflows with ML, LLM and Vision LLM
View katanaml/sparrow
An autonomous, context-aware AI desktop companion. Built with Python, featuring real-time screen vision, custom ONNX voice synthesis, active window tracking
View AhmadHassan-BTed/B
Clarity AI | AI Image Upscaler & Enhancer - free and open-source Magnific Alternative
View philz1337x/clarity-upscaler
基于图像识别的自动化黑盒测试框架 | An automation black-box testing framework based on image recognition
View MaaXYZ/MaaFramework
Tiled Diffusion and VAE optimize, licensed under CC BY-NC-SA 4.0
View pkuliyi2015/multidiffusion-upscaler-for-automatic1111
StableSwarmUI, A Modular Stable Diffusion Web-User-Interface, with an emphasis on making powertools easily accessible, high performance, and extensibility.
View Stability-AI/StableSwarmUI
Unofficial Implementation of DragGAN - "Drag Your GAN: Interactive Point-based Manipulation on the Generative Image Manifold" (DragGAN 全功能实现,在线Demo,本地部署试用,代码、模型已全部开源,支持Windows, macOS, Linux)
View OpenGVLab/DragGAN🔎 Super-scale your images and run experiments with Residual Dense and Adversarial Networks.
View idealo/image-super-resolution
SwarmUI (formerly StableSwarmUI), A Modular Stable Diffusion Web-User-Interface, with an emphasis on making powertools easily accessible, high performance, and extensibility.
View mcmonkeyprojects/SwarmUI
AI 助手全套开源解决方案,自带运营管理后台,开箱即用。集成了 ChatGPT, Azure, ChatGLM,讯飞星火,文心一言等多个平台的大语言模型。支持 MJ AI 绘画,Stable Diffusion AI 绘画,微博热搜等插件工具。采用 Go + Vue3 + element-plus 实现。
View yangjian102621/geekai
Create 🔥 videos with Stable Diffusion by exploring the latent space and morphing between text prompts
View nateraw/stable-diffusion-videos
PHP library allowing thumbnail, snapshot or PDF generation from a url or a html page. Wrapper for wkhtmltopdf/wkhtmltoimage
View KnpLabs/snappy
A lite C++ AI toolkit: 100+ models with MNN, ORT and TRT, including Det, Seg, Stable-Diffusion, Face-Fusion.
View xlite-dev/lite.ai.toolkit
OmniGen: Unified Image Generation. https://arxiv.org/pdf/2409.11340
View VectorSpaceLab/OmniGen
Official implementations for paper: Anydoor: zero-shot object-level image customization
View ali-vilab/AnyDoor
Qwen-Image 2.1 NSFW/姿势出图 skill:作者级提示词配方 + NSFW LoRA + 136 姿势 VNCCS 人偶控制;适用 Claude Code / Codex / Cursor / OpenClaw
View Arekejoker/qwen21-nsfw-pose-skill
基于 OpenAI gpt-image-2.5 API 的图片生成与编辑工具
View CookSleep/gpt_image_playground
Unofficial implementation of Image Super-Resolution via Iterative Refinement by Pytorch
View Janspiry/Image-Super-Resolution-via-Iterative-Refinement →
 →
 →
 →
 →
 →