1
 →
Open-source industrial-grade ASR models supporting Mandarin, Chinese dialects and English, achieving a new SOTA on public Mandarin ASR benchmarks
FireRedTeam/FireRedASR is an open-source project on GitHub, mainly written in Python. Open-source industrial-grade ASR models supporting Mandarin, Chinese dialects and English, achieving a new SOTA on public Mandarin ASR benchmarks It currently holds 1,993 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
Git Homed tracks it on the Audio Trending board and on the AI Audio Trending list.
[[Paper]](https://arxiv.org/pdf/2501.14350) [[Model]](https://huggingface.co/fireredteam) [[Blog]](https://fireredteam.github.io/demos/firered_asr/) [[Demo]](https://huggingface.co/spaces/FireRedTeam/FireRedASR)
FireRedASR2S has been open-sourced! Welcome to try it! https://github.com/FireRedTeam/FireRedASR2S
FireRedASR2S is a state-of-the-art (SOTA), industrial-grade, all-in-one ASR system with ASR, VAD, LID, and Punc modules. All modules achieve SOTA performance.
FireRedASR is a family of open-source industrial-grade automatic speech recognition (ASR) models supporting Mandarin, Chinese dialects and English, achieving a new state-of-the-art (SOTA) on public Mandarin ASR benchmarks, while also offering outstanding singing lyrics recognition capability.
FireRedASR is designed to meet diverse requirements in superior performance and optimal efficiency across various applications. It comprises two variants:
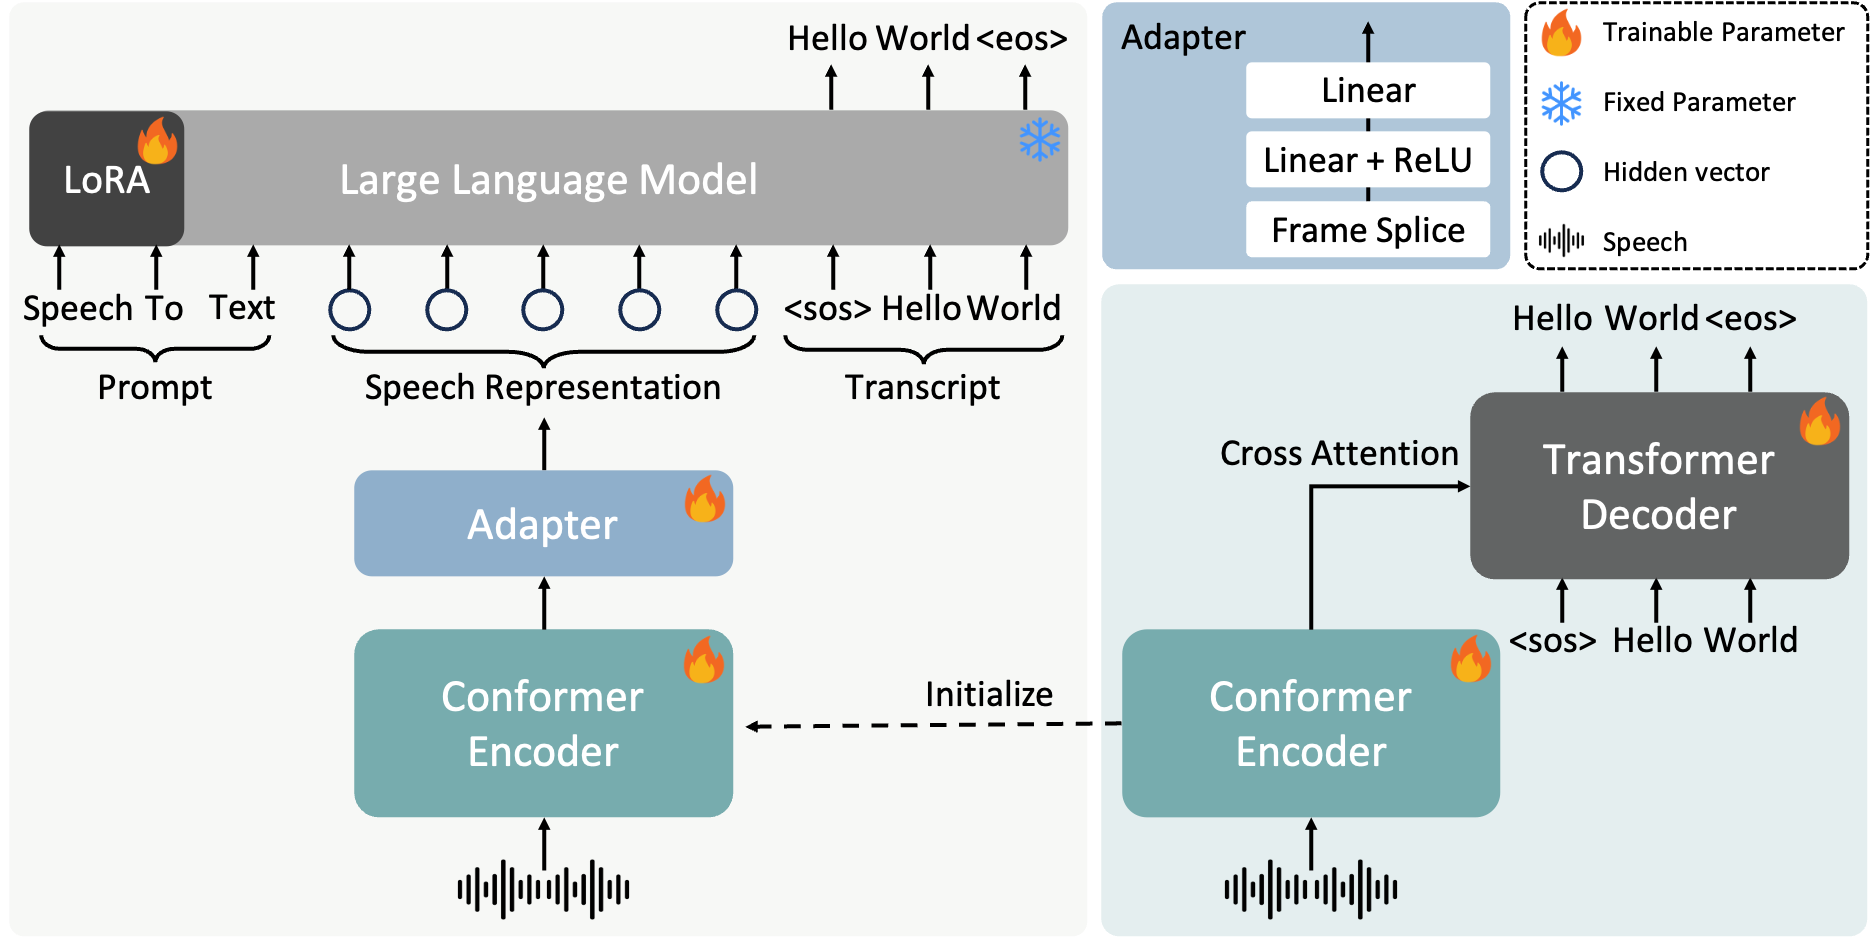
ws means WenetSpeech.
pretrained_models.
If you want to use FireRedASR-LLM-L, you also need to download Qwen2-7B-Instruct and place it in the folder pretrained_models. Then, go to folder FireRedASR-LLM-L and run $ ln -s ../Qwen2-7B-Instruct
$ git clone https://github.com/FireRedTeam/FireRedASR.git
$ conda create --name fireredasr python=3.10
$ conda activate fireredasr
$ pip install -r requirements.txt
Set up Linux PATH and PYTHONPATH
$ export PATH=$PWD/fireredasr/:$PWD/fireredasr/utils/:$PATH
$ export PYTHONPATH=$PWD/:$PYTHONPATH
Convert audio to 16kHz 16-bit PCM format
ffmpeg -i input_audio -ar 16000 -ac 1 -acodec pcm_s16le -f wav output.wav
$ cd examples
$ bash inference_fireredasr_aed.sh
$ bash inference_fireredasr_llm.sh
$ speech2text.py --help
$ speech2text.py --wav_path examples/wav/BAC009S0764W0121.wav --asr_type "aed" --model_dir pretrained_models/FireRedASR-AED-L
$ speech2text.py --wav_path examples/wav/BAC009S0764W0121.wav --asr_type "llm" --model_dir pretrained_models/FireRedASR-LLM-L
from fireredasr.models.fireredasr import FireRedAsr
batch_uttid = ["BAC009S0764W0121"]
batch_wav_path = ["examples/wav/BAC009S0764W0121.wav"]
FireRedASR-AED
model = FireRedAsr.from_pretrained("aed", "pretrained_models/FireRedASR-AED-L")
results = model.transcribe(
    batch_uttid,
    batch_wav_path,
    {
        "use_gpu": 1,
        "beam_size": 3,
        "nbest": 1,
        "decode_max_len": 0,
        "softmax_smoothing": 1.25,
        "aed_length_penalty": 0.6,
        "eos_penalty": 1.0
    }
)
print(results)
FireRedASR-LLM
model = FireRedAsr.from_pretrained("llm", "pretrained_models/FireRedASR-LLM-L")
results = model.transcribe(
    batch_uttid,
    batch_wav_path,
    {
        "use_gpu": 1,
        "beam_size": 3,
        "decode_max_len": 0,
        "decode_min_len": 0,
        "repetition_penalty": 3.0,
        "llm_length_penalty": 1.0,
        "temperature": 1.0
    }
)
print(results)
batch_size to 1 to avoid the repetition issue.@article{xu2025fireredasr,
title={FireRedASR: Open-Source Industrial-Grade Mandarin Speech Recognition Models from Encoder-Decoder to LLM Integration},
author={Xu, Kai-Tuo and Xie, Feng-Long and Tang, Xu and Hu, Yao},
journal={arXiv preprint arXiv:2501.14350},
year={2025}
}
 →
 →
 →
 →
 →
 →
 →