1
 →

🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.




English | 简体中文 | 繁體中文 | 한국어 | Español | 日本語 | हिन्दी | Русский | Português | తెలుగు | Français | Deutsch | Italiano | Tiếng Việt | العربية | اردو | বাংলা | فارسی | Română | Türkçe
State-of-the-art pretrained models for inference and training
Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer vision, audio, video, and multimodal models, for both inference and training.
It centralizes the model definition so that this definition is agreed upon across the ecosystem. transformers is the
pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from transformers.
We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be simple, customizable, and efficient.
There are over 1M+ Transformers model checkpoints on the Hugging Face Hub you can use.
Explore the Hub today to find a model and use Transformers to help you get started right away.
Transformers works with Python 3.10+, and PyTorch 2.5+.
Create and activate a virtual environment with venv or uv, a fast Rust-based Python package and project manager.
# venv
python -m venv .my-env
source .my-env/bin/activate
uv
uv venv .my-env
source .my-env/bin/activate
Install Transformers in your virtual environment.
# pip
pip install "transformers[torch]"
uv
uv pip install "transformers[torch]"
Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the latest version may not be stable. Feel free to open an issue if you encounter an error.
git clone https://github.com/huggingface/transformers.git
cd transformers
pip
pip install '.[torch]'
uv
uv pip install '.[torch]'
Get started with Transformers right away with the Pipeline API. The Pipeline is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.
Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.
from transformers import pipeline
pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")
[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to Pipeline) between you and the system.
[!TIP]
You can also chat with a model directly from the command line, as long as transformers serve is running.
> transformers chat Qwen/Qwen2.5-0.5B-Instruct
import torch
from transformers import pipeline
chat = [
    {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
    {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
]
pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
response = pipeline(chat, max_new_tokens=512)
print(response[0]["generated_text"][-1]["content"])
Expand the examples below to see how Pipeline works for different modalities and tasks.
from transformers import pipeline
pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
from transformers import pipeline
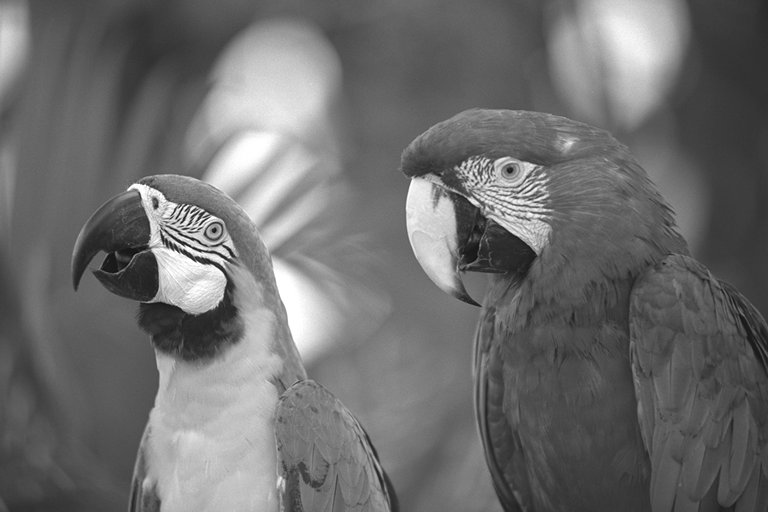
pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer")
pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
[{'label': 'macaw', 'score': 0.997848391532898},
 {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',
  'score': 0.0016551691805943847},
 {'label': 'lorikeet', 'score': 0.00018523589824326336},
 {'label': 'African grey, African gray, Psittacus erithacus',
  'score': 7.85409429227002e-05},
 {'label': 'quail', 'score': 5.502637941390276e-05}]
from transformers import pipeline
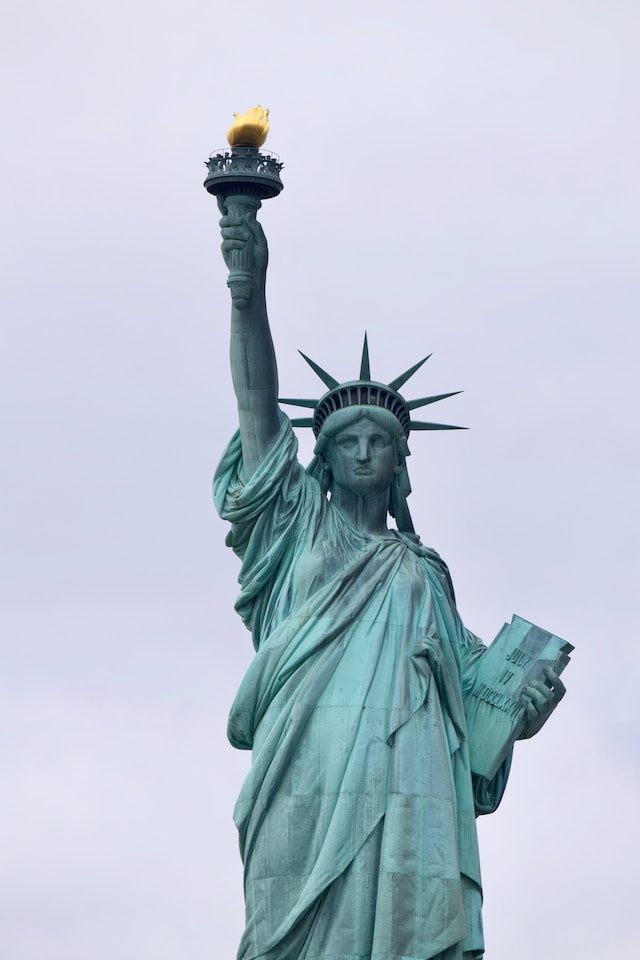
pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
pipeline(
    image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
    question="What is in the image?",
)
[{'answer': 'statue of liberty'}]
1. Easy-to-use state-of-the-art models:
Transformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the Hugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone else to build their dream projects.
In order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the community with the awesome-transformers page which lists 100 incredible projects built with Transformers.
If you own or use a project that you believe should be part of the list, please open a PR to add it!
You can test most of our models directly on their Hub model pages.
Expand each modality below to see a few example models for various use cases.
We now have a paper you can cite for the 🤗 Transformers library:
@inproceedings{wolf-etal-2020-transformers,
    title = "Transformers: State-of-the-Art Natural Language Processing",
    author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush",
    booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
    month = oct,
    year = "2020",
    address = "Online",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2020.emnlp-demos.6/",
    pages = "38--45"
}
 →
 →
 →
 →
 →