1
 →
🐸💬 - a deep learning toolkit for Text-to-Speech, battle-tested in research and production

🐸TTS is a library for advanced Text-to-Speech generation.
🚀 Pretrained models in +1100 languages.
🛠️ Tools for training new models and fine-tuning existing models in any language.
📚 Utilities for dataset analysis and curation. ______________________________________________________________________
 [![License]()](https://opensource.org/licenses/MPL-2.0)



 [![Docs]()](https://tts.readthedocs.io/en/latest/)
______________________________________________________________________
| Type | Platforms | | ------------------------------- | --------------------------------------- | | 🚨 Bug Reports | [GitHub Issue Tracker] | | 🎁 Feature Requests & Ideas | [GitHub Issue Tracker] | | 👩💻 Usage Questions | [GitHub Discussions] | | 🗯 General Discussion | [GitHub Discussions] or [Discord] |
[github issue tracker]: https://github.com/coqui-ai/tts/issues [github discussions]: https://github.com/coqui-ai/TTS/discussions [discord]: https://discord.gg/5eXr5seRrv [Tutorials and Examples]: https://github.com/coqui-ai/TTS/wiki/TTS-Notebooks-and-Tutorials
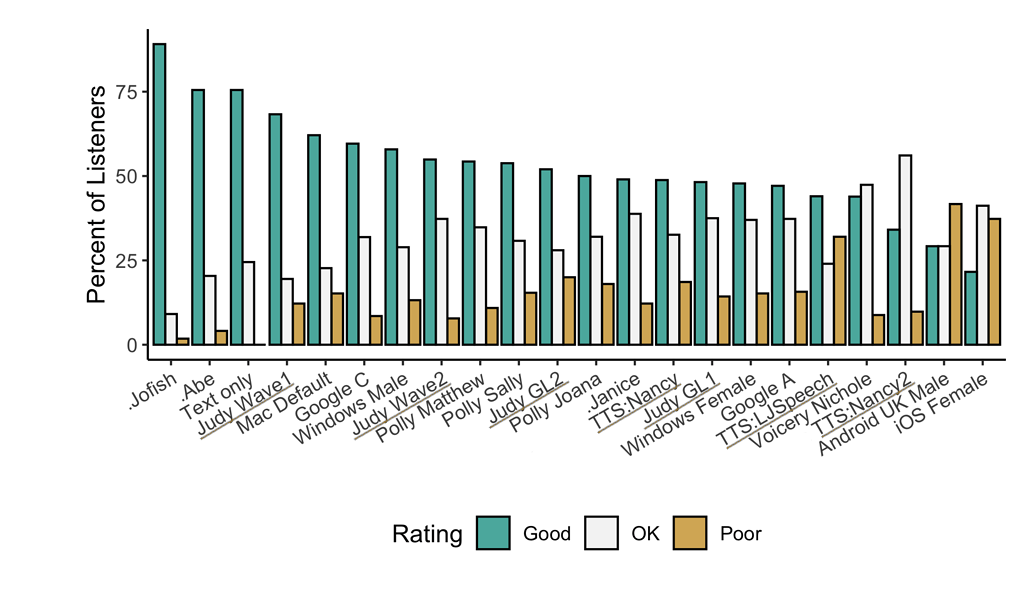
Underlined "TTS*" and "Judy*" are internal 🐸TTS models that are not released open-source. They are here to show the potential. Models prefixed with a dot (.Jofish .Abe and .Janice) are real human voices.
Trainer API.dataset_analysis``.If you are only interested in synthesizing speech with the released 🐸TTS models, installing from PyPI is the easiest option.
pip install TTS
If you plan to code or train models, clone 🐸TTS and install it locally.
git clone https://github.com/coqui-ai/TTS
pip install -e .[all,dev,notebooks]  # Select the relevant extras
If you are on Ubuntu (Debian), you can also run following commands for installation.
$ make system-deps  # intended to be used on Ubuntu (Debian). Let us know if you have a different OS.
$ make install
If you are on Windows, 👑@GuyPaddock wrote installation instructions here.
docker run --rm -it -p 5002:5002 --entrypoint /bin/bash ghcr.io/coqui-ai/tts-cpu
python3 TTS/server/server.py --list_models #To get the list of available models
python3 TTS/server/server.py --model_name tts_models/en/vctk/vits # To start a server
You can then enjoy the TTS server here More details about the docker images (like GPU support) can be found here
import torch
from TTS.api import TTS
Get device
device = "cuda" if torch.cuda.is_available() else "cpu"
List available 🐸TTS models
print(TTS().list_models())
Init TTS
tts = TTS("tts_models/multilingual/multi-dataset/xtts_v2").to(device)
Run TTS
❗ Since this model is multi-lingual voice cloning model, we must set the target speaker_wav and language
Text to speech list of amplitude values as output
wav = tts.tts(text="Hello world!", speaker_wav="my/cloning/audio.wav", language="en")
Text to speech to a file
tts.tts_to_file(text="Hello world!", speaker_wav="my/cloning/audio.wav", language="en", file_path="output.wav")
# Init TTS with the target model name
tts = TTS(model_name="tts_models/de/thorsten/tacotron2-DDC", progress_bar=False).to(device)
Run TTS
tts.tts_to_file(text="Ich bin eine Testnachricht.", file_path=OUTPUT_PATH)
Example voice cloning with YourTTS in English, French and Portuguese
tts = TTS(model_name="tts_models/multilingual/multi-dataset/your_tts", progress_bar=False).to(device)
tts.tts_to_file("This is voice cloning.", speaker_wav="my/cloning/audio.wav", language="en", file_path="output.wav")
tts.tts_to_file("C'est le clonage de la voix.", speaker_wav="my/cloning/audio.wav", language="fr-fr", file_path="output.wav")
tts.tts_to_file("Isso é clonagem de voz.", speaker_wav="my/cloning/audio.wav", language="pt-br", file_path="output.wav")
Converting the voice in source_wav to the voice of target_wav
tts = TTS(model_name="voice_conversion_models/multilingual/vctk/freevc24", progress_bar=False).to("cuda")
tts.voice_conversion_to_file(source_wav="my/source.wav", target_wav="my/target.wav", file_path="output.wav")
tts = TTS("tts_models/de/thorsten/tacotron2-DDC")
tts.tts_with_vc_to_file(
    "Wie sage ich auf Italienisch, dass ich dich liebe?",
    speaker_wav="target/speaker.wav",
    file_path="output.wav"
)
tts_models//fairseq/vits.
You can find the language ISO codes here
and learn about the Fairseq models here.
# TTS with on the fly voice conversion
api = TTS("tts_models/deu/fairseq/vits")
api.tts_with_vc_to_file(
    "Wie sage ich auf Italienisch, dass ich dich liebe?",
    speaker_wav="target/speaker.wav",
    file_path="output.wav"
)
ttsSynthesize speech on command line.
You can either use your trained model or choose a model from the provided list.
If you don't specify any models, then it uses LJSpeech based English model.
$ tts --list_models
$ tts --model_info_by_name "<model_type>///<model_name>"
    $ tts --model_info_by_name tts_models/tr/common-voice/glow-tts
    $ tts --model_info_by_name vocoder_models/en/ljspeech/hifigan_v2
$ tts --model_info_by_idx "<model_type>/<model_query_idx>"
For example:
$ tts --model_info_by_idx tts_models/3
$ tts --model_info_by_name "<model_type>///<model_name>"
$ tts --text "Text for TTS" --out_path output/path/speech.wav
$ tts --text "Text for TTS" --pipe_out --out_path output/path/speech.wav | aplay
$ tts --text "Text for TTS" --model_name "<model_type>///<model_name>" --out_path output/path/speech.wav
For example:
$ tts --text "Text for TTS" --model_name "tts_models/en/ljspeech/glow-tts" --out_path output/path/speech.wav
$ tts --text "Text for TTS" --model_name "<model_type>///<model_name>" --vocoder_name "<model_type>///<model_name>" --out_path output/path/speech.wav
For example:
$ tts --text "Text for TTS" --model_name "tts_models/en/ljspeech/glow-tts" --vocoder_name "vocoder_models/en/ljspeech/univnet" --out_path output/path/speech.wav
$ tts --text "Text for TTS" --model_path path/to/model.pth --config_path path/to/config.json --out_path output/path/speech.wav
  $ tts --text "Text for TTS" --model_path path/to/model.pth --config_path path/to/config.json --out_path output/path/speech.wav
      --vocoder_path path/to/vocoder.pth --vocoder_config_path path/to/vocoder_config.json
$ tts --model_name "//<model_name>" --list_speaker_idxs
$ tts --text "Text for TTS." --out_path output/path/speech.wav --model_name "//<model_name>" --speaker_idx <speaker_id>
$ tts --text "Text for TTS" --out_path output/path/speech.wav --model_path path/to/model.pth --config_path path/to/config.json --speakers_file_path path/to/speaker.json --speaker_idx <speaker_id>
$ tts --out_path output/path/speech.wav --model_name "//<model_name>" --source_wav --target_wav
|- notebooks/       (Jupyter Notebooks for model evaluation, parameter selection and data analysis.)
|- utils/           (common utilities.)
|- TTS
    |- bin/             (folder for all the executables.)
      |- train*.py                  (train your target model.)
      |- ...
    |- tts/             (text to speech models)
        |- layers/          (model layer definitions)
        |- models/          (model definitions)
        |- utils/           (model specific utilities.)
    |- speaker_encoder/ (Speaker Encoder models.)
        |- (same)
    |- vocoder/         (Vocoder models.)
        |- (same)
 →
 →
 →
 →
 →