promptslab/Awesome-Prompt-Engineering
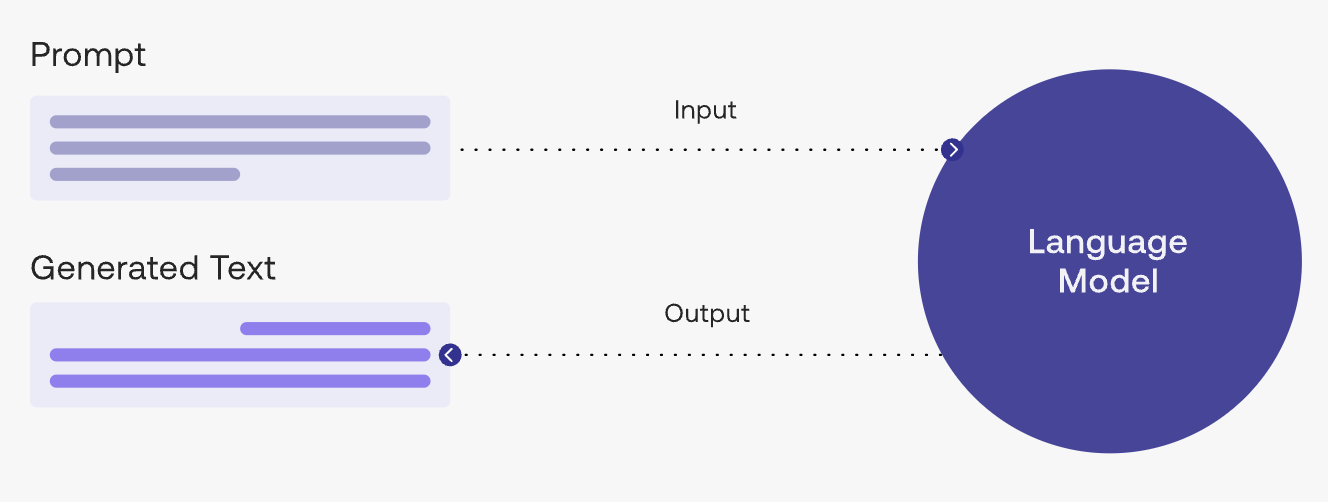
This repository contains a hand-curated resources for Prompt Engineering with a focus on Generative Pre-trained Transformer (GPT), ChatGPT, PaLM etc
README
Awesome Prompt Engineering 🧙♂️
A hand-curated collection of resources for Prompt Engineering and Context Engineering — covering papers, tools, models, APIs, benchmarks, courses, and communities for working with Large Language Models.
https://promptslab.github.io
Master Prompt Engineering. Join the Course at https://promptslab.github.io
---
🚀 Start Here
New to prompt engineering? Follow this path:
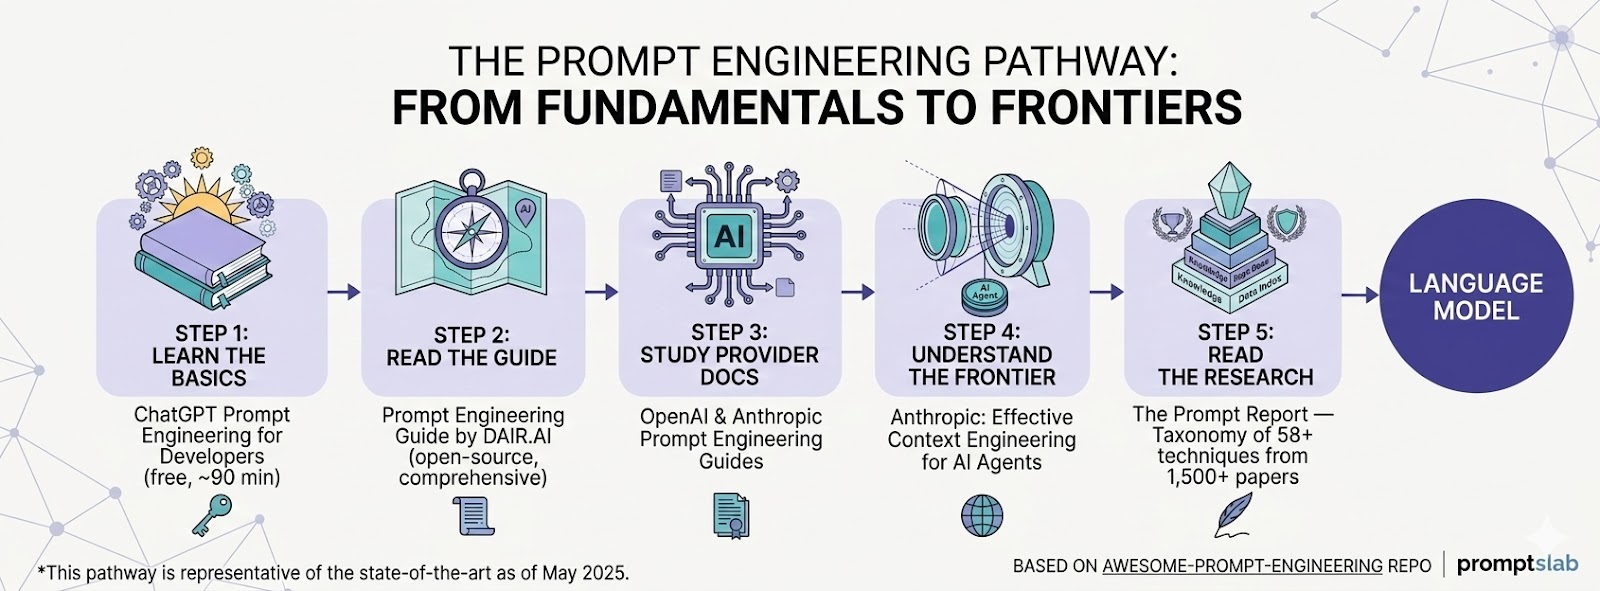
1. Learn the basics → ChatGPT Prompt Engineering for Developers (free, ~90 min) 2. Read the guide → Prompt Engineering Guide by DAIR.AI (open-source, comprehensive) 3. Study provider docs → OpenAI Prompt Engineering Guide · Anthropic Prompt Engineering Guide 4. Understand where the field is heading → Anthropic: Effective Context Engineering for AI Agents 5. Read the research → The Prompt Report — taxonomy of 58+ prompting techniques from 1,500+ papers
---
Table of Contents
- Papers
- Major Surveys
- Prompt Optimization and Automatic Prompting
- Prompt Compression
- Reasoning Advances
- In-Context Learning
- Agentic Prompting and Multi-Agent Systems
- Multimodal Prompting
- Structured Output and Format Control
- Prompt Injection and Security
- Applications of Prompt Engineering
- Text-to-Image Generation
- Text-to-Music/Audio Generation
- Foundational Papers (Pre-2024)
- Tools and Code
- Prompt Management and Testing
- LLM Evaluation Tools
- Agent Frameworks
- Prompt Optimization Tools
- Red Teaming and Prompt Security
- MCP (Model Context Protocol)
- Vibe Coding and AI Coding Assistants
- CLI-Based Coding Agents
- AI Code Editors / IDEs
- IDE Extensions / Plugins
- AI Coding Platforms / Cloud Agents
- Open-Source Coding Agent Frameworks
- Other Notable Repositories
- APIs
- Datasets and Benchmarks
- Models
- AI Content Detectors
- Books
- Courses
- Tutorials and Guides
- Videos
- Communities
- Autonomous Research & Self-Improving Agents
- How to Contribute
Papers
📄Major Surveys
- The Prompt Report: A Systematic Survey of Prompting Techniques [2024] — Most comprehensive survey: taxonomy of 58 text and 40 multimodal prompting techniques from 1,500+ papers. Co-authored with OpenAI, Microsoft, Google, Stanford.
- A Systematic Survey of Prompt Engineering in Large Language Models: Techniques and Applications [2024] — 44 techniques across application areas with per-task performance summaries.
- A Survey of Prompt Engineering Methods in LLMs for Different NLP Tasks [2024] — 39 prompting methods across 29 NLP tasks.
- A Survey of Automatic Prompt Engineering: An Optimization Perspective [2025] — Formalizes auto-PE methods as discrete/continuous/hybrid optimization problems.
- Efficient Prompting Methods for Large Language Models: A Survey [2024] — Survey of efficiency-oriented prompting (compression, optimization, APE) for reducing compute and latency.
- Navigate through Enigmatic Labyrinth: A Survey of Chain of Thought Reasoning [2023, ACL 2024] — Systematic CoT survey.
- Demystifying Chains, Trees, and Graphs of Thoughts [2024] — Unified framework for multi-prompt reasoning topologies.
- Towards Goal-oriented Prompt Engineering for Large Language Models: A Survey [2024] — Focuses on prompts designed around explicit task goals.
- Towards Reasoning Era: A Survey of Long Chain-of-Thought for Reasoning LLMs [2025] — Distinguishes Long CoT from Short CoT in o1/R1-era models.
Prompt Optimization and Automatic Prompting
- OPRO: Large Language Models as Optimizers [2023, NeurIPS 2024] — Uses LLMs as optimizers via meta-prompts; optimized prompts outperform human-designed ones by up to 50% on BBH.
- DSPy: Compiling Declarative Language Model Calls into Self-Improving Pipelines [2023, ICLR 2024] — Framework for programming (not prompting) LLMs with automatic prompt optimization.
- MIPRO: Optimizing Instructions and Demonstrations for Multi-Stage Language Model Programs [2024, EMNLP 2024] — Bayesian optimization for multi-stage LM programs; up to 13% accuracy gains.
- TextGrad: Automatic "Differentiation" via Text [2024] — Treats compound AI systems as computation graphs with textual feedback as gradients. Published in Nature.
- EvoPrompt [2023, ACL 2024] — Evolutionary algorithm approach for automatically optimizing discrete prompts.
- Meta Prompting for AI Systems [2023, ICLR 2024 Workshop] — Example-agnostic structural templates formalized using category theory.
- Prompt Engineering a Prompt Engineer (PE²) [2024, ACL Findings] — Uses LLMs to meta-prompt themselves, refining prompts with step-by-step templates to significantly improve reasoning.
- Large Language Models Are Human-Level Prompt Engineers [2022] — Automatic prompt generation via APE.
- Hard Prompts Made Easy: Gradient-Based Discrete Optimization for Prompt Tuning [2023]
- SPO: Self-Supervised Prompt Optimization [2025] — Competitive performance at 1–6% of the cost of prior methods.
Prompt Compression
- LLMLingua-2: Data Distillation for Efficient and Faithful Task-Agnostic Prompt Compression [2024, ACL 2024] — 3x–6x faster than LLMLingua with GPT-4 data distillation.
- LongLLMLingua [2023, ACL 2024] — Question-aware compression for long contexts; 21.4% performance boost with 4x fewer tokens.
- Prompt Compression for Large Language Models: A Survey [2024] — Comprehensive survey of hard and soft prompt compression methods.
Reasoning Advances
- Scaling LLM Test-Time Compute Optimally [2024] — Shows optimal test-time compute allocation can outperform 14x larger models.
- DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning [2025] — Pure RL-trained reasoning model matching o1; open-source with distilled variants.
- s1: Simple Test-Time Scaling [2025] — SFT on just 1,000 examples creates competitive reasoning model via "budget forcing."
- Reasoning Language Models: A Blueprint [2025] — Systematic framework organizing reasoning LM approaches.
- Demystifying Long Chain-of-Thought Reasoning in LLMs [2025] — Analyzes long CoT behavior in modern reasoning models.
- Graph of Thoughts: Solving Elaborate Problems with LLMs [2023, AAAI 2024] — Models thoughts as arbitrary graphs; 62% quality improvement over ToT on sorting.
- Tree of Thoughts: Deliberate Problem Solving with LLMs [2023, NeurIPS 2023] — Tree search over reasoning paths.
- Everything of Thoughts [2023] — Integrates CoT, ToT, and external solvers via MCTS.
- Skeleton-of-Thought [2023] — Parallel decoding via answer skeleton generation for up to 2.69x speedup.
- Chain of Thought Prompting Elicits Reasoning in Large Language Models [2022] — The foundational CoT paper.
- Self-Consistency Improves Chain of Thought Reasoning [2022] — Aggregating multiple CoT outputs for reliability.
- Large Language Models are Zero-Shot Reasoners [2022] — "Let's think step by step" as a zero-shot reasoning trigger.
- ReAct: Synergizing Reasoning and Acting in Language Models [2022] — Interleaving reasoning and tool use.
In-Context Learning
- Many-Shot In-Context Learning [2024, NeurIPS 2024 Spotlight] — Significant gains scaling ICL to hundreds/thousands of examples; introduces Reinforced and Unsupervised ICL.
- Many-Shot In-Context Learning in Multimodal Foundation Models [2024] — Scales multimodal ICL to ~2,000 examples across 14 datasets.
- Rethinking the Role of Demonstrations: What Makes In-Context Learning Work? [2022]
- Fantastically Ordered Prompts and Where to Find Them [2021] — Overcoming few-shot prompt order sensitivity.
- Calibrate Before Use: Improving Few-Shot Performance of Language Models [2021]
Agentic Prompting and Multi-Agent Systems
- Agentic Large Language Models: A Survey [2025] — Comprehensive survey organizing agentic LLMs by reasoning, acting, and interacting capabilities.
- Large Language Model based Multi-Agents: A Survey of Progress and Challenges [2024] — Covers profiling, communication, and growth mechanisms.
- Multi-Agent Collaboration Mechanisms: A Survey of LLMs [2025] — Reviews debate and cooperation strategies in LLM-based multi-agent systems.
- AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversation [2023] — Microsoft's foundational multi-agent framework paper.
- ToolLLM: Facilitating Large Language Models to Master 16000+ Real-World APIs [2023, ICLR 2024] — Trains LLMs to use massive real-world API collections.
- SWE-bench: Can Language Models Resolve Real-World GitHub Issues? [2023, ICLR 2024] — The benchmark driving agentic coding progress.
- AgentBench: Evaluating LLMs as Agents [2023, ICLR 2024] — Benchmark across 8 environments.
- PAL: Program-aided Language Models [2023] — Offloading computation to code interpreters.
Multimodal Prompting
- Visual Prompting in Multimodal Large Language Models: A Survey [2024] — First comprehensive survey on visual prompting methods in MLLMs.
- Set-of-Mark Prompting Unleashes Extraordinary Visual Grounding in GPT-4V [2023] — Visual markers dramatically improve visual grounding.
- A Comprehensive Survey and Guide to Multimodal Large Language Models in Vision-Language Tasks [2024] — Covers text, image, video, audio MLLMs.
- Multimodal Chain-of-Thought Reasoning in Language Models [2023]
- From Prompt Engineering to Prompt Craft [2024] — Design-research view of prompt "craft" for diffusion models.
Structured Output and Format Control
- Let Me Speak Freely? A Study on the Impact of Format Restrictions on Performance of LLMs [2024] — Examines how constraining outputs to structured formats impacts reasoning performance.
- Batch Prompting: Efficient Inference with LLM APIs [2023]
- Structured Prompting: Scaling In-Context Learning to 1,000 Examples [2022]
Prompt Injection and Security
- Formalizing and Benchmarking Prompt Injection Attacks and Defenses [2023, USENIX Security 2024] — Formal framework with systematic evaluation of 5 attacks and 10 defenses across 10 LLMs.
- The Instruction Hierarchy: Training LLMs to Prioritize Privileged Instructions [2024] — OpenAI's priority-level training for injection defense.
- AgentDojo: A Dynamic Environment to Evaluate Prompt Injection Attacks and Defenses [2024] — Realistic agent scenario benchmark.
- InjecAgent: Benchmarking Indirect Prompt Injections in Tool-Integrated LLM Agents [2024]
- SecAlign: Defending Against Prompt Injection with Preference Optimization [2024] — DPO-based defense.
- WASP: Benchmarking Web Agent Security Against Prompt Injection [2025] — Security benchmark for web/computer-use agents.
- Many-Shot Jailbreaking [2024] — Scaling harmful examples in long-context windows enables jailbreaking (Anthropic Technical Report).
- Constitutional AI: Harmlessness from AI Feedback [2022]
- Ignore Previous Prompt: Attack Techniques For Language Models [2022]
- Artificial Intelligence and Cybersecurity: Documented Risks, Enterprise Guardrails, and Emerging Threats in 2024–2025 [2025] — Survey of real prompt-injection incidents with practical governance prompt patterns.
Applications of Prompt Engineering
- Rephrase and Respond: Let Large Language Models Ask Better Questions for Themselves [2023]
- Legal Prompt Engineering for Multilingual Legal Judgement Prediction [2023]
- Conversing with Copilot: Exploring Prompt Engineering for Solving CS1 Problems [2022]
- Commonsense-Aware Prompting for Controllable Empathetic Dialogue Generation [2023]
- PLACES: Prompting Language Models for Social Conversation Synthesis [2023]
- Medical Image Segmentation Using Transformer Encoders and Prompt-Based Learning: A Systematic Review [2025]
- TableRAG: A Retrieval Augmented Generation Framework for Heterogeneous Document Reasoning [2025] — SQL-based interface preserving tabular structure for multi-hop queries.
Text-to-Image Generation
- A Taxonomy of Prompt Modifiers for Text-To-Image Generation [2022]
- Design Guidelines for Prompt Engineering Text-to-Image Generative Models [2021]
- High-Resolution Image Synthesis with Latent Diffusion Models [2021]
- DALL·E: Creating Images from Text [2021]
- Investigating Prompt Engineering in Diffusion Models [2022]
Text-to-Music/Audio Generation
- MusicLM: Generating Music From Text [2023]
- ERNIE-Music: Text-to-Waveform Music Generation with Diffusion Models [2023]
- AudioLM: A Language Modeling Approach to Audio Generation [2023]
- Make-An-Audio: Text-To-Audio Generation with Prompt-Enhanced Diffusion Models [2023]
Foundational Papers (Pre-2024)
These papers established the core concepts that modern prompt engineering builds on:
- Language Models are Few-Shot Learners (GPT-3) [2020] — Demonstrated few-shot prompting at scale.
- Prefix-Tuning: Optimizing Continuous Prompts for Generation [2021]
- The Power of Scale for Parameter-Efficient Prompt Tuning [2021]
- Prompt Programming for Large Language Models: Beyond the Few-Shot Paradigm [2021]
- Show Your Work: Scratchpads for Intermediate Computation with Language Models [2021]
- Generated Knowledge Prompting for Commonsense Reasoning [2021]
- Making Pre-trained Language Models Better Few-shot Learners [2021]
- AutoPrompt: Eliciting Knowledge from Language Models with Automatically Generated Prompts [2020]
- How Can We Know What Language Models Know? [2020]
- A Prompt Pattern Catalog to Enhance Prompt Engineering with ChatGPT [2023]
- Synthetic Prompting: Generating Chain-of-Thought Demonstrations for LLMs [2023]
- Progressive Prompts: Continual Learning for Language Models [2023]
- Successive Prompting for Decompleting Complex Questions [2022]
- Decomposed Prompting: A Modular Approach for Solving Complex Tasks [2022]
- PromptChainer: Chaining Large Language Model Prompts through Visual Programming [2022]
- Ask Me Anything: A Simple Strategy for Prompting Language Models [2022]
- Prompting GPT-3 To Be Reliable [2022]
- On Second Thought, Let's Not Think Step by Step! Bias and Toxicity in Zero-Shot Reasoning [2022]
Tools and Code
🔧Prompt Management and Testing
| Name | Description | Link | |:-----|:-----------|:----:| | Promptfoo | Open-source CLI for testing, evaluating, and red-teaming LLM prompts. YAML configs, CI/CD integration, adversarial testing. ~9K+ ⭐ | GitHub | | Promptify | Solve NLP Problems with LLM's & Easily generate different NLP Task prompts for popular generative models like GPT, PaLM, and more with Promptify | [[Github]](https://github.com/promptslab/Promptify) | | Agenta | Open-source LLM developer platform for prompt management, evaluation, human feedback, and deployment. | GitHub | | PromptLayer | Version, test, and monitor every prompt and agent with robust evals, tracing, and regression sets. | Website | | Helicone | Production prompt monitoring and optimization platform. | Website | | LangGPT | Framework for structured and meta-prompt design. 10K+ ⭐ | GitHub | | ChainForge | Visual toolkit for building, testing, and comparing LLM prompt responses without code. | GitHub | | LMQL | A query language for LLMs making complex prompt logic programmable. | GitHub | | Promptotype | Platform for developing, testing, and managing structured LLM prompts. | Website | | PromptPanda | AI-powered prompt management system for streamlining prompt workflows. | Website | | Promptimize AI | Browser extension to automatically improve user prompts for any AI model. | Website | | PROMPTMETHEUS | Web-based "Prompt Engineering IDE" for iteratively creating and running prompts. | Website | | Better Prompt | Test suite for LLM prompts before pushing to production. | GitHub | | OpenPrompt | Open-source framework for prompt-learning research. | GitHub | | Prompt Source | Toolkit for creating, sharing, and using natural language prompts. | GitHub | | Prompt Engine | NPM utility library for creating and maintaining prompts for LLMs (Microsoft). | GitHub | | PromptInject | Framework for quantitative analysis of LLM robustness to adversarial prompt attacks. | GitHub | | LynxPrompt | Self-hostable platform for managing AI IDE config files (.cursorrules, CLAUDE.md, copilot-instructions.md). Web UI, REST API, CLI, and federated blueprint marketplace for 30+ AI coding assistants. | GitHub | | flompt | Visual AI prompt builder that decomposes prompts into 12 semantic blocks (role, context, constraints, examples, etc.) and compiles them into optimized XML. Browser extension for ChatGPT/Claude/Gemini, and MCP server for Claude Code agents. Free, open-source. | Website |
LLM Evaluation Tools
| Name | Description | Link | |:-----|:-----------|:----:| | DeepEval | Open-source evaluation framework covering RAG, agents, and conversations with CI/CD integration. ~7K+ ⭐ | GitHub | | Ragas | RAG evaluation with knowledge-graph-based test set generation and 30+ metrics. ~8K+ ⭐ | GitHub | | LangSmith | LangChain's platform for debugging, testing, evaluating, and monitoring LLM applications. | Website | | Langfuse | Open-sour