1
 →
[AutoArk] GPA (General Purpose Audio) can do ASR, TTS and voice conversion with one tiny model!
[
]()
GPA stands for General Purpose Audio.
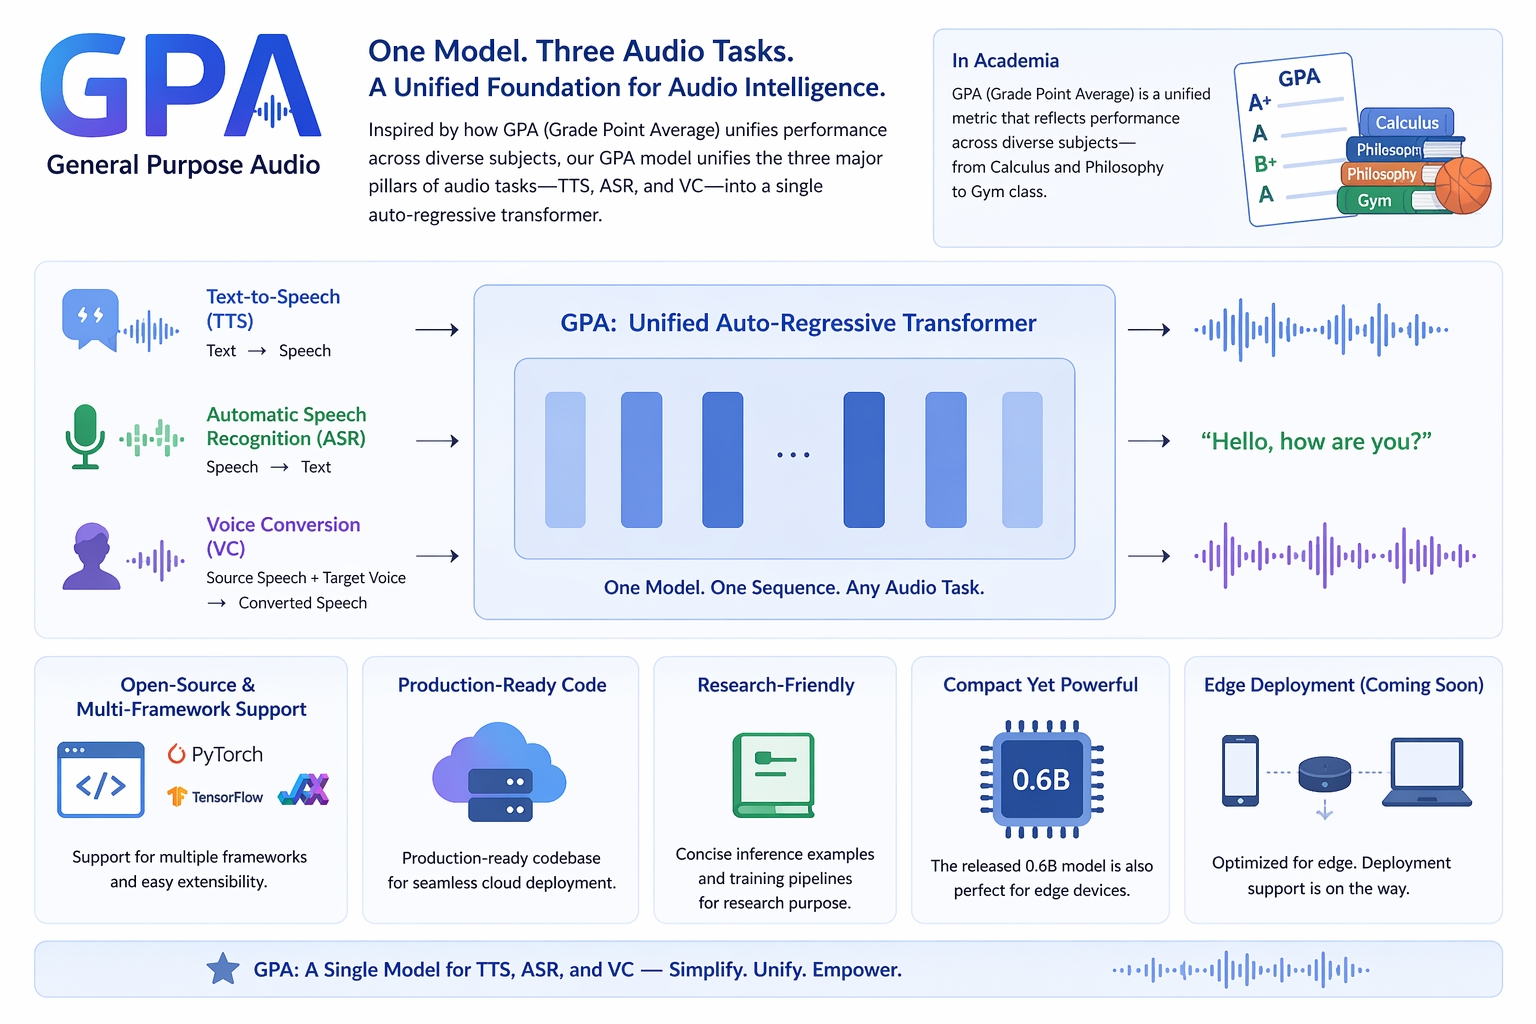
A student’s GPA unifies performance across diverse subjects—from Calculus to Gym—into a single metric. Likewise, our GPA model integrates the three core audio tasks—TTS, ASR, and Voice Conversion—into one auto-regressive transformer.
GPA-v1.5 now delivers near-SOTA performance on ASR and TTS in a single unified model, with VC support on the roadmap.
🗺️ Roadmap · 🚀 GPA-v1.5 Release · 🎙️ GPA-TTS · 🧭 GPA-v1.0 Archive · 📊 GPA-v1.5 Evaluation · 🔗 Citation
| Category | Item | Status | | :--- | :--- | :---: | | Core Features | Unified LLM-based audio generation & understanding | ✅ | | | Native GPA-v1.5 Inference Pipeline | ✅ | | | Native GPA-v1.5 Training Pipeline | ✅ | | | GPA-v1.5 ONNX Runtime CLI/API/UI | ✅ | | | GPA-v1.5 Interactive Demo | ⬜ | | | GPA-v1.5 Basic Service Deployment (vLLM/FastAPI) | ⬜ | | | Paper (ArXiv) | ✅ | | Model Releases | GPA-0.3B-preview | ✅ | | | GPA-v1.5 — major mainline release | ✅ | | | GPA-TTS — Lightweight TTS runtime (INT8/FP16/FP32 + INT4 ONNX) | ✅ | | GPA-v1.5 Next Steps | Voice Conversion native path | ⬜ | | | Expanded deployment recipes | ⬜ | | Frameworks | torch | ✅ | | | vllm | ✅ | | | llama-cpp | ✅ | | | sglang | ✅ | | | mlx-lm | ✅ | | | rknn | ⬜ |
GPA-v1.5 is the new mainline release of GPA: a larger, cleaner, more capable unified audio model for ASR and TTS, with native PyTorch workflows and ONNX runtime deployment now available.
| | GPA-v1.5 |
| :--- | :--- |
| Checkpoint | Open-sourced on Hugging Face |
| Native Inference | Direct PyTorch / Hugging Face execution for ASR and TTS |
| Native Training | Fine-tuning and continued training with Hugging Face Trainer |
| ONNX Runtime | CLI inference, FastAPI service, browser UI, voice registration, and runtime validation |
| Planned | Voice Conversion support in the native v1.5 path |
📖 GPA-v1.5 README → | 🏋️ Training Guide → | 🎧 Inference Guide → | ⚙️ ONNX Runtime Guide → | 🤗 Download from HuggingFace
We noticed that TTS is by far the most popular feature in our online demo. While GPA-v1.5 ships as a larger unified model, we extracted the TTS component into a standalone, self-contained runtime:
| | GPA-TTS | | :--- | :--- | | Quantization | Qwen INT4 + Detokenizer INT8 / FP16 / FP32 (ONNX Runtime) | | Voice Cloning | Zero-shot, from a short reference audio | | Decoder Precision | Selectable at runtime — INT8 (edge), FP16 (balanced), FP32 (highest quality) | | Footprint | Among the smallest open-source TTS runtimes with cloning support | | Optimized for | Local CPU inference (Mac / Linux / Edge) |
The original GPA-0.3B-preview homepage has been preserved for users who still rely on the v1.0 quick start, deployment recipes, benchmarks, and evaluation tables.
| | GPA-v1.0 | | :--- | :--- | | Model | GPA-0.3B-preview | | Docs | Original quick start, checkpoint download, inference, training, deployment, performance, and evaluation | | Best for | Reproducing the initial release or maintaining existing v1.0 integrations | | Downloads | Hugging Face and ModelScope links from the original release |
| Model | Open-Source | Model Size | test-zh CER (%) ↓ | test-zh Sim (%) ↑ | test-en WER (%) ↓ | test-en Sim (%) ↑ | | :--- | :---: | :---: | :---: | :---: | :---: | :---: | | Multi-Stage or NAR Methods | | | | | | | | Human | - | - | 1.26 | 75.5 | 2.14 | 73.4 | | Seed-TTS | ❌ | - | 1.12 | 79.6 | 2.25 | 76.2 | | MiniMax-Speech | ❌ | - | 0.83 | 78.3 | 1.65 | 69.2 | | F5-TTS | ✅ | 0.3B | 1.52 | 74.1 | 2.00 | 64.7 | | CosyVoice2 | ✅ | 0.5B | 1.45 | 75.7 | 2.57 | 65.9 | | FireRedTTS2 | ✅ | 1.5B | 1.14 | 73.2 | 1.95 | 66.5 | | Index-TTS2 | ✅ | 1.5B | 1.03 | 76.5 | 2.23 | 70.6 | | VibeVoice-1.5B | ✅ | 1.5B | 1.16 | 74.4 | 3.04 | 68.9 | | VibeVoice-Realtime | ✅ | 0.5B | - | - | 2.05 | 63.3 | | HiggsAudio-v2 | ✅ | 3B | 1.50 | 74.0 | 2.44 | 67.7 | | VoxCPM | ✅ | 0.5B | 0.93 | 77.2 | 1.85 | 72.9 | | GLM-TTS | ✅ | 1.5B | 1.03 | 76.1 | - | - | | GLM-TTS RL | ✅ | 1.5B | 0.89 | 76.4 | - | - | | Fun-CosyVoice3-0.5B-2512 | ✅ | 0.5B | 1.21 | 78.0 | 2.24 | 71.8 | | Fun-CosyVoice3-0.5B-2512_RL | ✅ | 0.5B | 0.81 | 77.4 | 1.68 | 69.5 | | One-Stage AR Methods | | | | | | | | Spark TTS | ✅ | 0.5B | 1.20 | 66.0 | 1.98 | 57.3 | | GPA-v1.5 | ✅ | 0.6B | 1.03 | 70.2 | 1.43 | 63.5 |
Note: ASR results on LibriSpeech, AISHELL-1, test_Meeting, and test_Net. WER (%) is reported for LibriSpeech; CER (%) is reported for AISHELL-1. The additional test_Meeting and test_Net columns follow the corresponding benchmark metric used in our evaluation.
| Model | Model Size | LibriSpeech test-clean | LibriSpeech test-other | AISHELL-1 | test_Meeting | test_Net | | :--- | :---: | :---: | :---: | :---: | :---: | :---: | | Whisper-S | 0.24B | 3.43 | 7.63 | - | - | - | | GPA-v1.5 | 0.6B | 2.78 | 5.02 | 2.83 | 7.40 | 6.49 | | Fun-ASR-nano | 0.8B | 1.76 | 4.33 | 1.80 | 6.60 | 6.01 | | FireRed-ASR | 1.1B | 1.84 | 4.52 | 0.54 | 4.95 | 4.94 | | GLM-ASR-nano | 1.5B | 2.00 | 4.19 | 1.81 | 6.73 | - | | GLM-ASR-nano* | 1.5B | 2.17 | 4.43 | 2.17 | 8.21 | 6.33 | | Whisper-L | 1.55B | 1.86 | 3.43 | 4.72 | 18.39 | 11.89 | | Kimi-Audio | - | 1.32 | 2.63 | 0.71 | 6.24 | 6.45 | | Step-Audio2 | - | 1.17 | 2.42 | 0.63 | 4.75 | 4.67 | | Seed-ASR | - | 1.58 | 2.84 | 0.68 | 5.69 | 4.66 | | Seed-ASR* | - | 2.80 | 5.69 | 1.63 | 7.07 | 4.84 | | Fun-ASR | 7.7B | 1.51 | 3.03 | 1.22 | 6.17 | 5.46 |
If you find GPA useful for your research or projects, please cite us:
@misc{cai2026unifyingspeechrecognitionsynthesis,
      title={Unifying Speech Recognition, Synthesis and Conversion with Autoregressive Transformers},
      author={Runyuan Cai and Yu Lin and Yiming Wang and Chunlin Fu and Xiaodong Zeng},
      year={2026},
      eprint={2601.10770},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2601.10770},
}
 →
 →
 →
 →
 →