1
 →
Codebase intelligence for AI and humans: code health scores, auto-generated docs, git analytics, dead code detection, and architectural decisions via MCP.
repowise-dev/repowise is an open-source project on GitHub, mainly written in Python. Codebase intelligence for AI and humans: code health scores, auto-generated docs, git analytics, dead code detection, and architectural decisions via MCP. It currently holds 7,520 stars and 841 forks with 298 open issues, and was last pushed on 2026-10-11 (repository created 2026-03-23).
Git Homed tracks it on the Today's Trending board, currently at rank #53 with 68 new stars today.
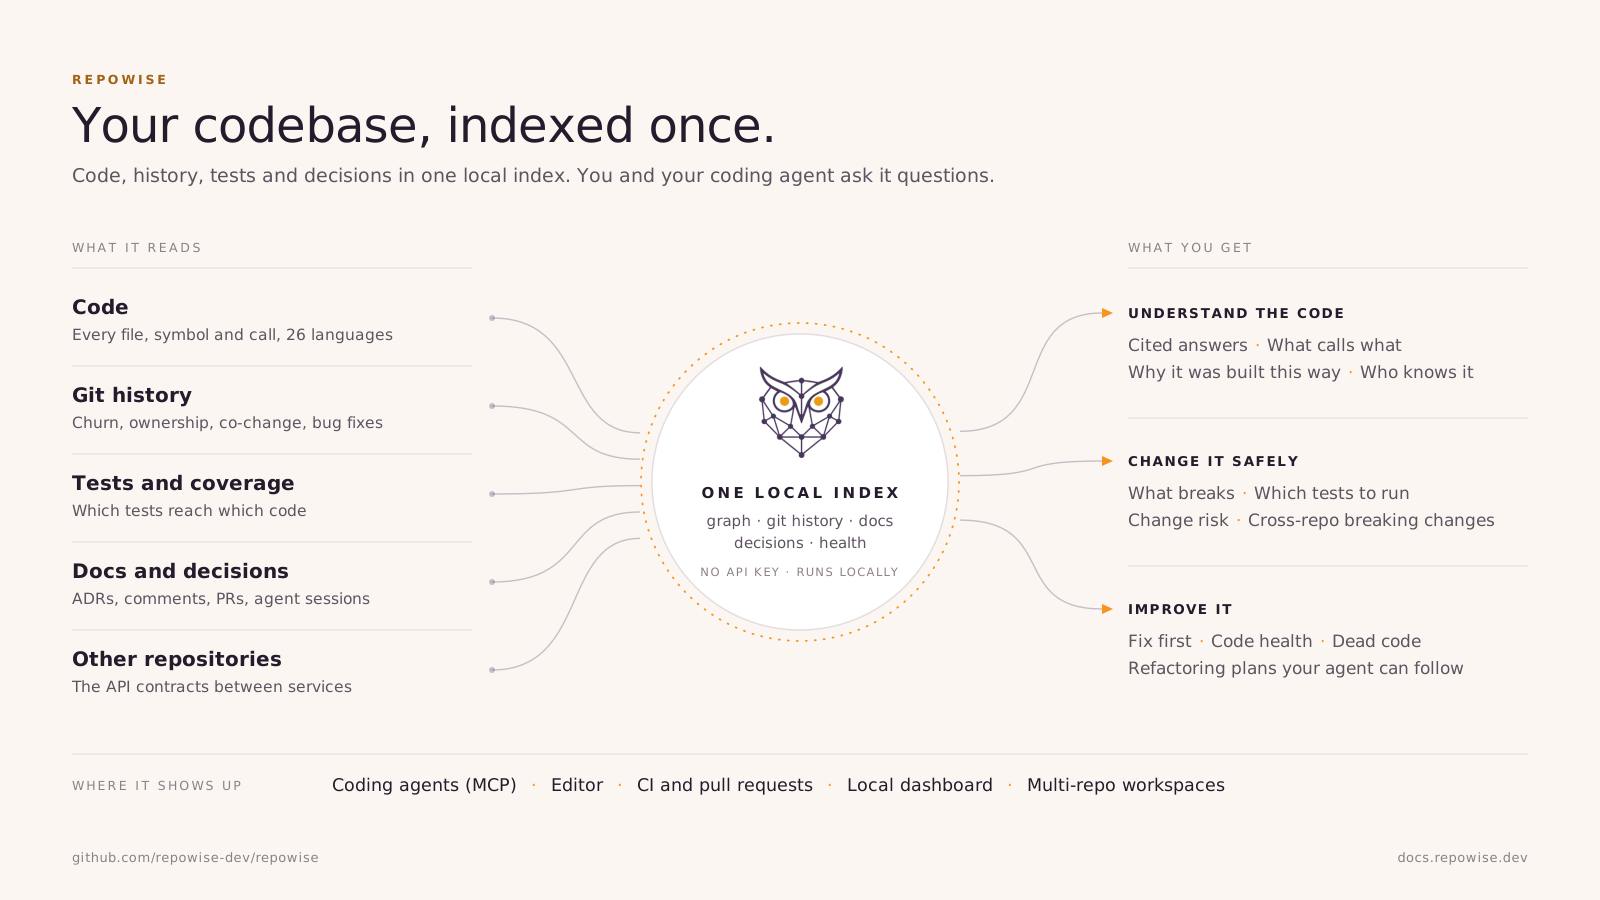
Repowise indexes your code, call graph, git history, tests, docs and design
decisions once, on your machine. Then you and your coding agent ask it things:
what calls this, what breaks if I change it, what is dead, what to fix first, and why it was built this way.
−31.6% |
2.3× |
58,924 |
| less agent output 3.8 vs 7.2 tool calls 43 questions · p<0.0001 |
more defects surfaced than CodeScene same 20% review budget 2,770 files · p=0.003 |
files indexed in one run dotnet/runtime, one laptop 120 min · 11.7 GiB peak |
Call graph checked against the compiler: 0.976 to 0.995 precision on Go and TypeScript,
and no tool that finds as much of the graph gets more of it right, in 7 of 7 comparisons.
5 tools · 37,853 compiler edges · every losing row published
Graph, risk, health, tests and dead code make zero LLM calls · no API key needed · free and self-hosted · AGPL-3.0 or commercial


What it does · Quickstart · Agents · Changes · Code health · Workspaces · Evidence · Enterprise · Docs
---
Repowise is an ambitious project. We want every engineer, and every agent working beside them, to understand a codebase the way the person who has maintained it for five years does: what calls what, what tends to break, what nobody uses anymore, and why it was built this way. Cutting tokens was never the goal. It happens anyway, because an agent that can ask the index stops searching, opening and re-reading files to find out. Measured against the other context tools on the same agent tasks, it is also the largest saving.
Open Claude Code, Codex, Cursor or any MCP-capable agent in your repository and paste:
Read https://docs.repowise.dev/setup.md and set up Repowise in this repository.
The agent installs Repowise, indexes the repo with no API key, wires itself to the index, and asks you before anything costs money. Prefer to do it yourself:
uv tool install repowise          # or: pipx install repowise / pip install repowise
cd /path/to/your/repo
repowise init --yes --no-prose    # graph, git, health, dead code, docs. No key, no spend.
repowise serve                    # local dashboard + MCP server
init wires Claude Code automatically. Then ask your agent *"Use Repowise
get_overview to summarize this repository" or "What breaks if I change
src/auth.py?"*
Full setup, every agent, optional model-written docs →
---
One index, three ways to use it. Find the question you came with; each one links to the page that answers it.
| You ask | Repowise gives you |
|---|---|
| How does checkout work in this repo? | A cited answer built from the call graph and the generated docs, in one call. Search and answers |
| What calls this function, and what does it call? | A call graph across 26 parsed languages, every edge stamped with how it was resolved and how far to trust it, plus traced execution flows from each entry point. The graph |
| Can I get docs for this codebase? | A wiki for every module and file, rendered from the code's structure with no key, or written by a model when you choose. It updates incrementally after each commit. Docs |
| Which of our docs are wrong? | Markdown checked against the tree: every reference to a file or symbol the code no longer has, with the line to edit. Doc drift |
| Why is it built this way? | Decisions mined from ADRs, # WHY: comments, commit and PR history and your agent sessions, each tied to the code it governs and flagged when it goes stale. Decisions |
| Who knows this code? | Owners, bus factor, knowledge-loss risk when the main author goes quiet, and suggested reviewers. Ownership |
| Can I see the architecture? | An explorable dependency map, C4 views, and a Structurizr export, no model involved. Dashboard |
| You ask | Repowise gives you | |---|---| | What breaks if I change this? | Symbol-level blast radius: the callers of what you changed, the files that historically change with it but are missing from your diff, and the tests that reach it. Change risk | | How risky is this PR? | Where the change ranks against your repository's own recent commits, with the reasons, as a directive your agent can act on. Change risk | | Which tests should run? | The tests a diff actually exercises, from a coverage report if you have one and from the call graph if you do not. Test intelligence | | Did this PR add untested lines? | Patch coverage, branch coverage on changed lines and path-scoped gates in CI, on GitHub, GitLab or any runner. CI gates | | Will this API change break another repo? | HTTP, gRPC, topic and OpenAPI contracts matched across repositories, with a breaking-change guard and the consumer files it affects. Workspaces | | Is anyone else editing these files? | Other open branches touching the same files or their co-change partners, each with the reason it is listed. Branch overlap | | Did we just commit a secret? | Keys, tokens and risky calls found in the working tree and in full git history, with a pre-commit check and a CI gate. Security signals |
| You ask | Repowise gives you | |---|---| | What should we fix first? | A ranked queue weighing impact against effort, using churn, fan-in, coverage and bug history. Fix first | | Where is the debt? | A 1 to 10 score for every file from 53 deterministic detectors, split into defect risk, maintainability and performance, validated against real bug history. Code health | | Why is this slow? | N+1 queries, I/O in loops, blocking calls inside async code and quadratic loops, traced across function and file boundaries. Performance | | How do I break this up safely? | Concrete refactoring plans: Extract Method, Extract Class, Move Method, Split File, Break Cycle, with the exact symbols that move and what moves with them. Ready to hand to an agent. Refactoring | | What can we delete? | Unreachable files, unused exports and unused packages, each with a confidence tier and the evidence behind it. Dead code | | Where do bugs keep landing? | Bug-fix commits traced to files and symbols, and a warning when your agent edits a bug magnet. Bug history | | Are our tests testing anything? | Tests with no assertions, tests that only check their own mocks, and untested hotspots. Test-quality smells |
CLAUDE.md and AGENTS.md from the real index and keeps themrepowise distill pytestexpand command
restores any cut.
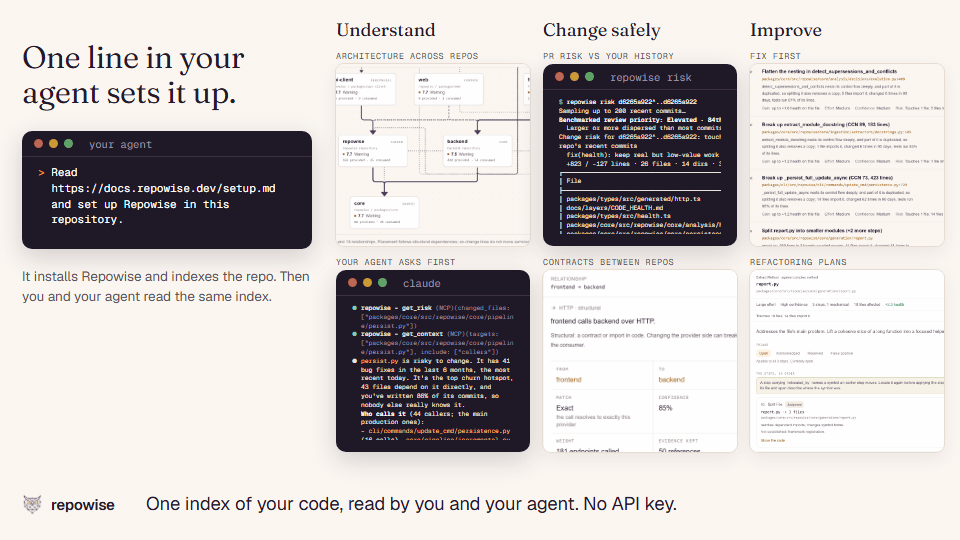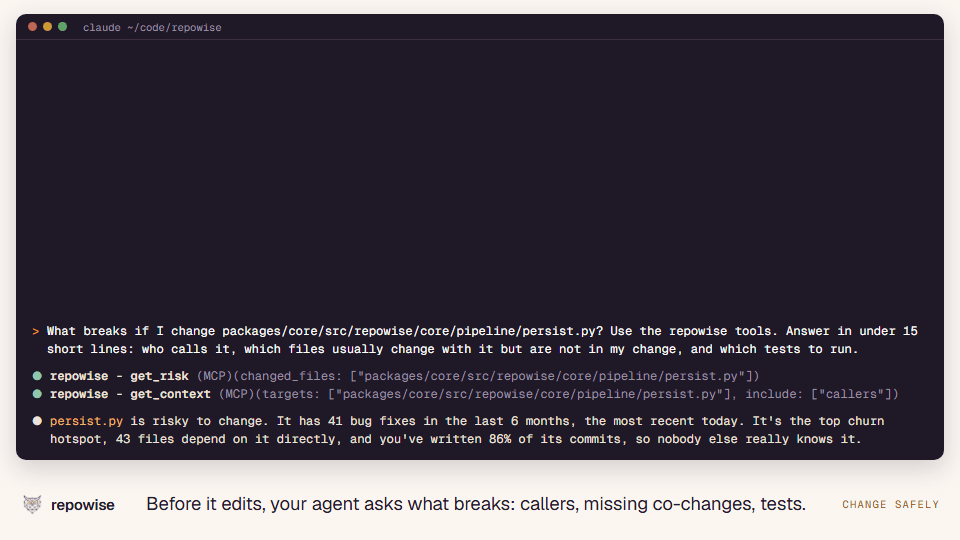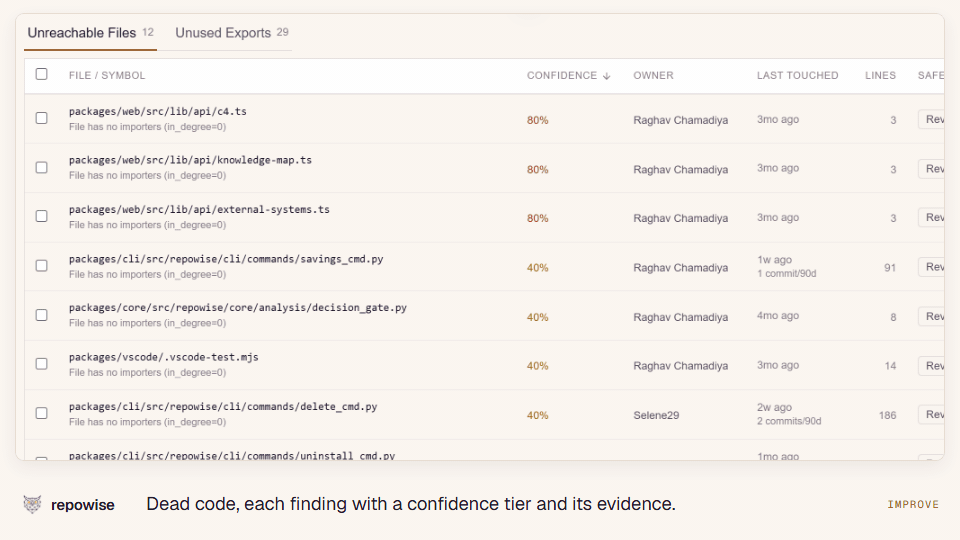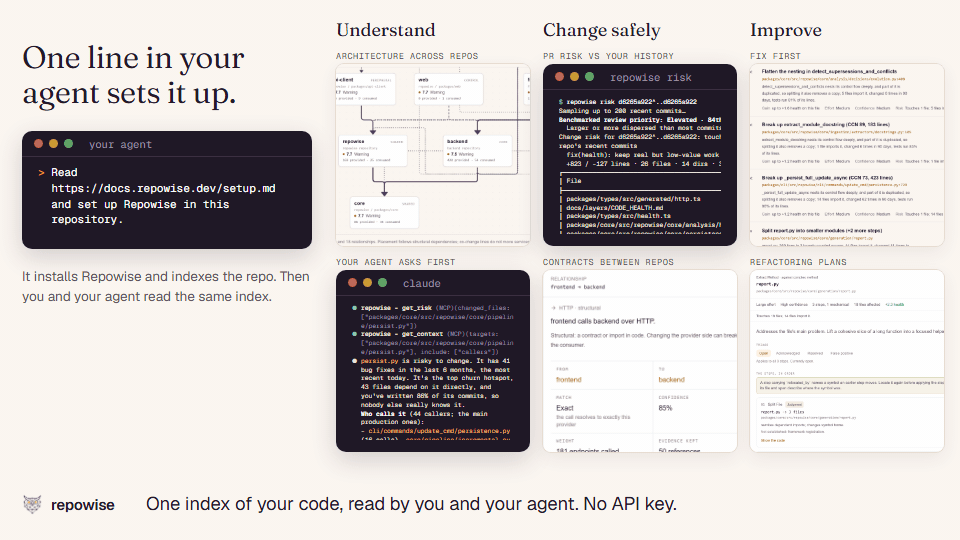
Recorded on this repository and its workspace: an agent asking the index, then the dashboard and CLI on the same local index. No API key and nothing uploaded.
| If you care about... | Start here | |---|---| | A coding agent that knows the repository | Task-shaped context in fewer calls, with decisions and risk delivered before the agent asks. For agents ↓ | | Safer pull requests and faster CI | Change risk, symbol-level callers, missing co-changes and the tests a diff needs. Change intelligence ↓ | | Paying down the code most likely to hurt you | A defect-validated health score, then the concrete fix. Code health ↓ | | An estate of many repositories | Contracts matched across repos, breaking-change guards, architecture rules in CI, one MCP endpoint for everything. Workspaces ↓ | | Rolling it out across a company | Self-hosted with nothing leaving your network, per-language accuracy, sizing, compliance status and licensing in one place. Teams and enterprise ↓ |
---
Every question your agent asks about a repository has an answer that could have been computed ahead of time. *Who calls this function? What breaks if I change it? Why is it written this way? Which files are actually dangerous?* Without an index, the agent rediscovers that answer on every task: grep, read, re-read, forget.
Repowise gives Claude Code, Codex, Cursor, VS Code and any other MCP host ten task-shaped MCP tools backed by one index of graph, git, docs and decisions. Most code tools are built around data entities, one file or one symbol at a time, which pushes agents into long chains of sequential calls. These are built around tasks: pass several targets in one call and get the whole picture back. The tool list ↓
About tokens. Every tool in this category promises to cut your token bill, and
there are a lot of tools in this category. We think tokens are a symptom. An agent
burns them because it does not know the codebase, so it searches, opens files, opens
more files, and searches again. Give it an index that already knows, and the savings
show up on their own. They also happen to be the best we have measured: in a paired
agent loop over 43 questions on django/django, Repowise cut the agent's own output
by 31.6% (p<0.0001) and got there in 3.8 tool calls instead of 7.2, ahead
of every other context tool in the same run. On 42 sealed retrieval tasks it found
0.876 of the files a fix needed, against 0.610 for the next tool.
Method and every row we lose →
Context arrives before the agent asks. Optional hooks push it into the session when it matters: the governing decision when your agent edits a file that decision covers, a warning when it touches a file with a run of recent bug fixes, a short briefing at session start, and a correction when it reaches for a path that does not exist.
It learns from how you work. Switch on transcript capture
(repowise decision source set session --on) and Repowise reads your own agent
transcripts for the corrections you keep making, turning the durable ones into
tracked decisions it delivers back later. Transcripts never leave your machine; one
batched model call per update turns the candidates that clear the deterministic
gates into records, and --no-llm keeps the gates and drops that call.
Five layers, one index:
| Layer | What it contributes | |---|---| | 1. Graph | File and symbol dependencies across 26 AST-parsed languages, confidence-stamped call resolution, communities, centrality, cycles and execution flows | | 2. Git history | Hotspots, ownership, co-change, bus factor and bug-fix history: behavioural signals static analysis cannot see | | 3. Docs | A wiki for every module and file, hybrid search, and your own markdown checked against the tree for claims the code no longer supports | | 4. Decisions | Architectural rationale from ADRs, inline markers, commits, PRs and agent sessions, each claim traced to evidence | | 5. Health and change | 53 deterministic detectors across defect risk, maintainability and performance, change risk, test impact, dead code and concrete refactoring plans |
The structural wiki needs no model. Model-written prose is an optional upgrade, one page or directory at a time.
Most of what an agent reads back from a shell command is noise: 300 lines of passing
tests wrapped around 4 failures, full commit bodies when it asked what changed
recently. repowise distill compresses command output before the agent reads
it, errors first, exit code preserved.
repowise distill pytest          # 61% fewer tokens, all 11 failure lines kept
repowise distill git log -50     # 89% fewer tokens
repowise saved                   # what distillation saved you, in tokens and dollars
Every omission leaves an inline [repowise#] marker that repowise expand
reverses in full, so the agent can pull the detail back without re-running the
command. Small outputs pass through untouched. An opt-in hook rewrites noisy commands
for the agent automatically.
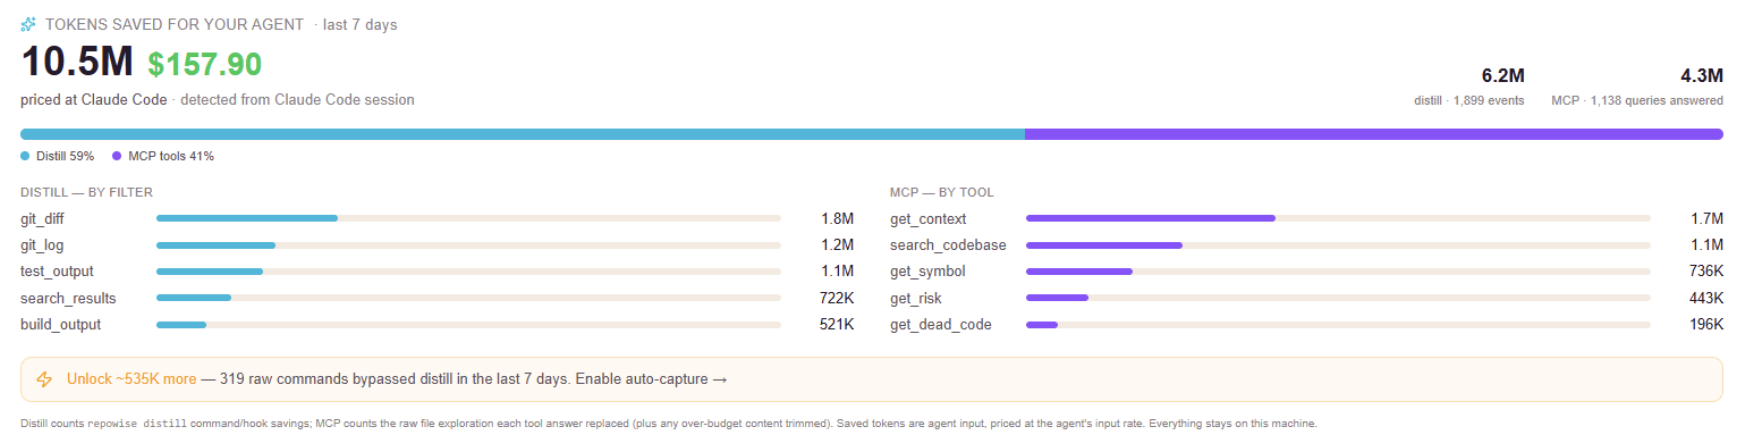
The Costs dashboard tallies both savings surfaces. Every event is priced from the model that produced it, and where the evidence is ambiguous it declines to claim a saving. Example from a week of heavy local use.
Full guide: docs/agent/DISTILL.md →
---
Four deterministic signals, all computed from the graph and git history, no LLM:
base..HEAD range 0-10 from the shape ofmay_break, missing_cochanges, missing_tests,
tests_to_run. One command: repowise risk main..HEAD.
(reference →)
repowise overlap and repowise risk.
(reference →)
Ingest LCOV, Cobertura, Clover, JaCoCo or a Go coverprofile and you get the measured answer. Most repositories never produce one, so the graph answers instead: a test file that imports a source file reaches it, which is a recorded edge, where most tools fall back to matching file names.
repowise impacted-tests main..HEAD   # only the tests this diff exercises
repowise health                      # untested hotspots, graph-aware
Checked against a real coverage run --contexts=test on this repository:
95.7% precision on what reaches a file and 97.5% on the run
list. Every row is stamped basis: "measured" or
"inferred", measured wins where both can answer, and an empty answer means
unknown, never "no tests".
Test intelligence →
Patch coverage, doc drift, security and change risk run as gates in your own pipeline through the GitHub Action, a GitLab template or plain CLI commands anywhere else, with annotations, SARIF and GitLab Code Quality output. The gates need no API key. Repowise in CI →
On GitHub you can also install the free Repowise PR Bot, a hosted GitHub App that puts the same analysis on every pull request. One comment, edited in place on every push, and a green PR gets no comment at all. It shows symbol-level blast radius (the contracts the PR changed and every caller outside the PR), the tests and co-change partners missing from the change, change risk against the repository's own history, and a public analysis page per PR. Zero LLM calls, so the same diff always gets the same review.
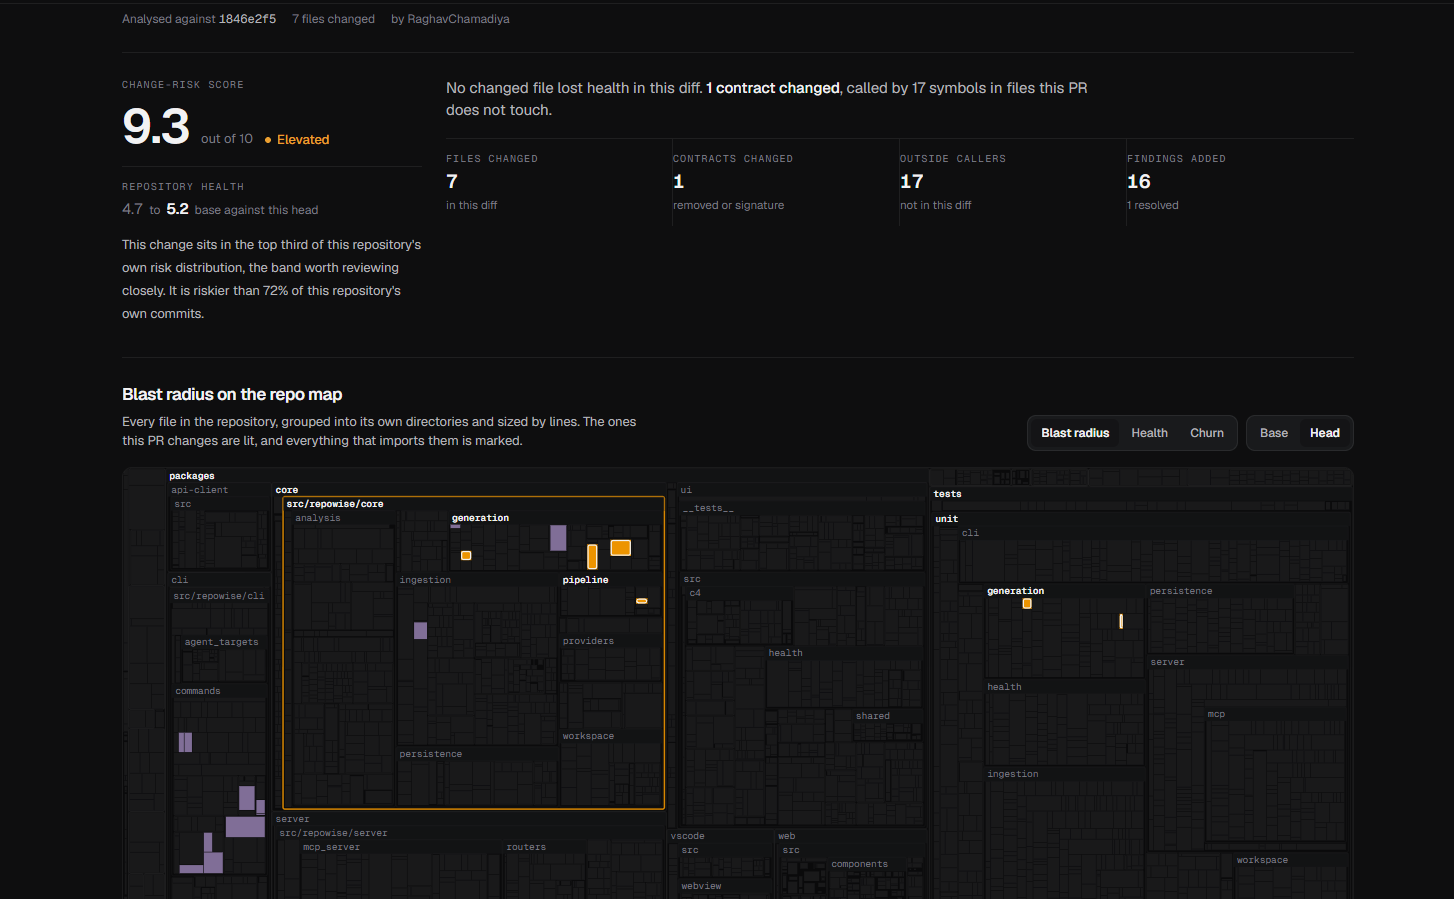
A real comment on a real PR: repowise-dev/repowise#1204 · its analysis page → · install the PR bot →
---
A score that says "this file is risky" is where most tools stop. Repowise scores every file, finds where the risk concentrates, and names the specific fix.
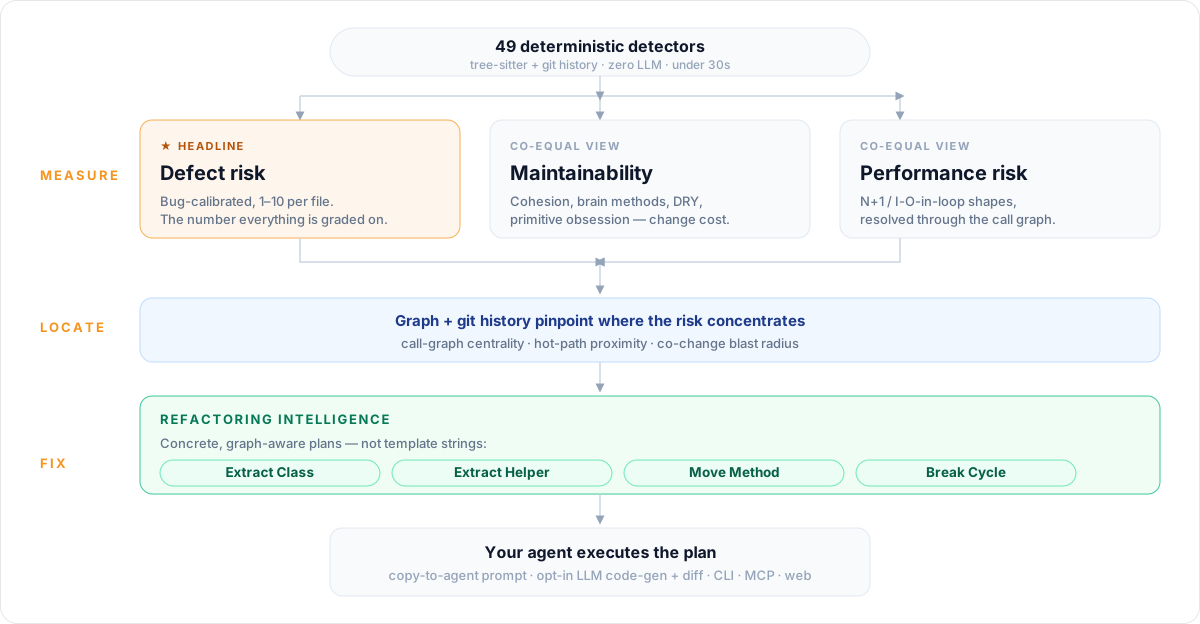
Every file is scored 1-10 by 53 deterministic detectors (McCabe complexity, brain methods, LCOM4 cohesion, god classes, clone detection, untested hotspots, change entropy, prior-defect history and more), read through three lenses: defect risk, maintainability and performance. Performance findings such as N+1 queries and I/O in loops are traced across functions and files through the call graph, which is where file-local linters lose them. Only 25 of the 53 detectors move the defect score, because that is the number carrying published accuracy claims.
Zero LLM calls, zero cloud. Detector weights are calibrated against a real
defect corpus, not hand-tuned: every file scored at a commit before the bug
window so nothing leaks backward, with file size as an explicit control, so a
detector only earns weight for defect lift beyond a file being big.
It checks itself on your repository. After every index, Repowise compares its own flags with your git history and tells you what it found: *"16 of the 20 lowest-health files had a bug fix in the last 6 months, 3.3x the 24% baseline."* If that number is bad on your codebase, you will see it.
Then it names the fix. Extract Class, Extract Helper, Move Method, Break Cycle, Split File or Extract Method, with the exact methods, edges and symbols that move, the callers and co-changing files that move with them, and a ranking that puts a fix on a central hub above the same fix on a leaf. Extract Method runs a dataflow pass over the function to lift the exact span and infer a behaviour-preserving s
→ →
 →
 →
 →
 →
 →
 →