1
 →
Turn Claude into a senior design architect: DTCG tokens, 52 components, WCAG 2.2 AA-AAA, 138 design systems, any-framework code, and 50 objective gates that fail the build instead of faking success.
plugin87/ux-ui-agent-skills is an open-source project on GitHub, mainly written in JavaScript. Turn Claude into a senior design architect: DTCG tokens, 52 components, WCAG 2.2 AA-AAA, 138 design systems, any-framework code It currently holds 3,054 stars and 294 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
Git Homed tracks it on the Today's Trending board.
aka XIAS
Instructions, design tokens, 26 runnable skills and 2,144 design systems (2,087 of them measured from the live site) that make a coding agent design to a senior standard, in any framework and against any design system. Then the gates measure what it built.
Current release v3.0.0 · Changelog · No build tools, dependencies, or runtime: a pure instruction and knowledge layer for AI agents.
---
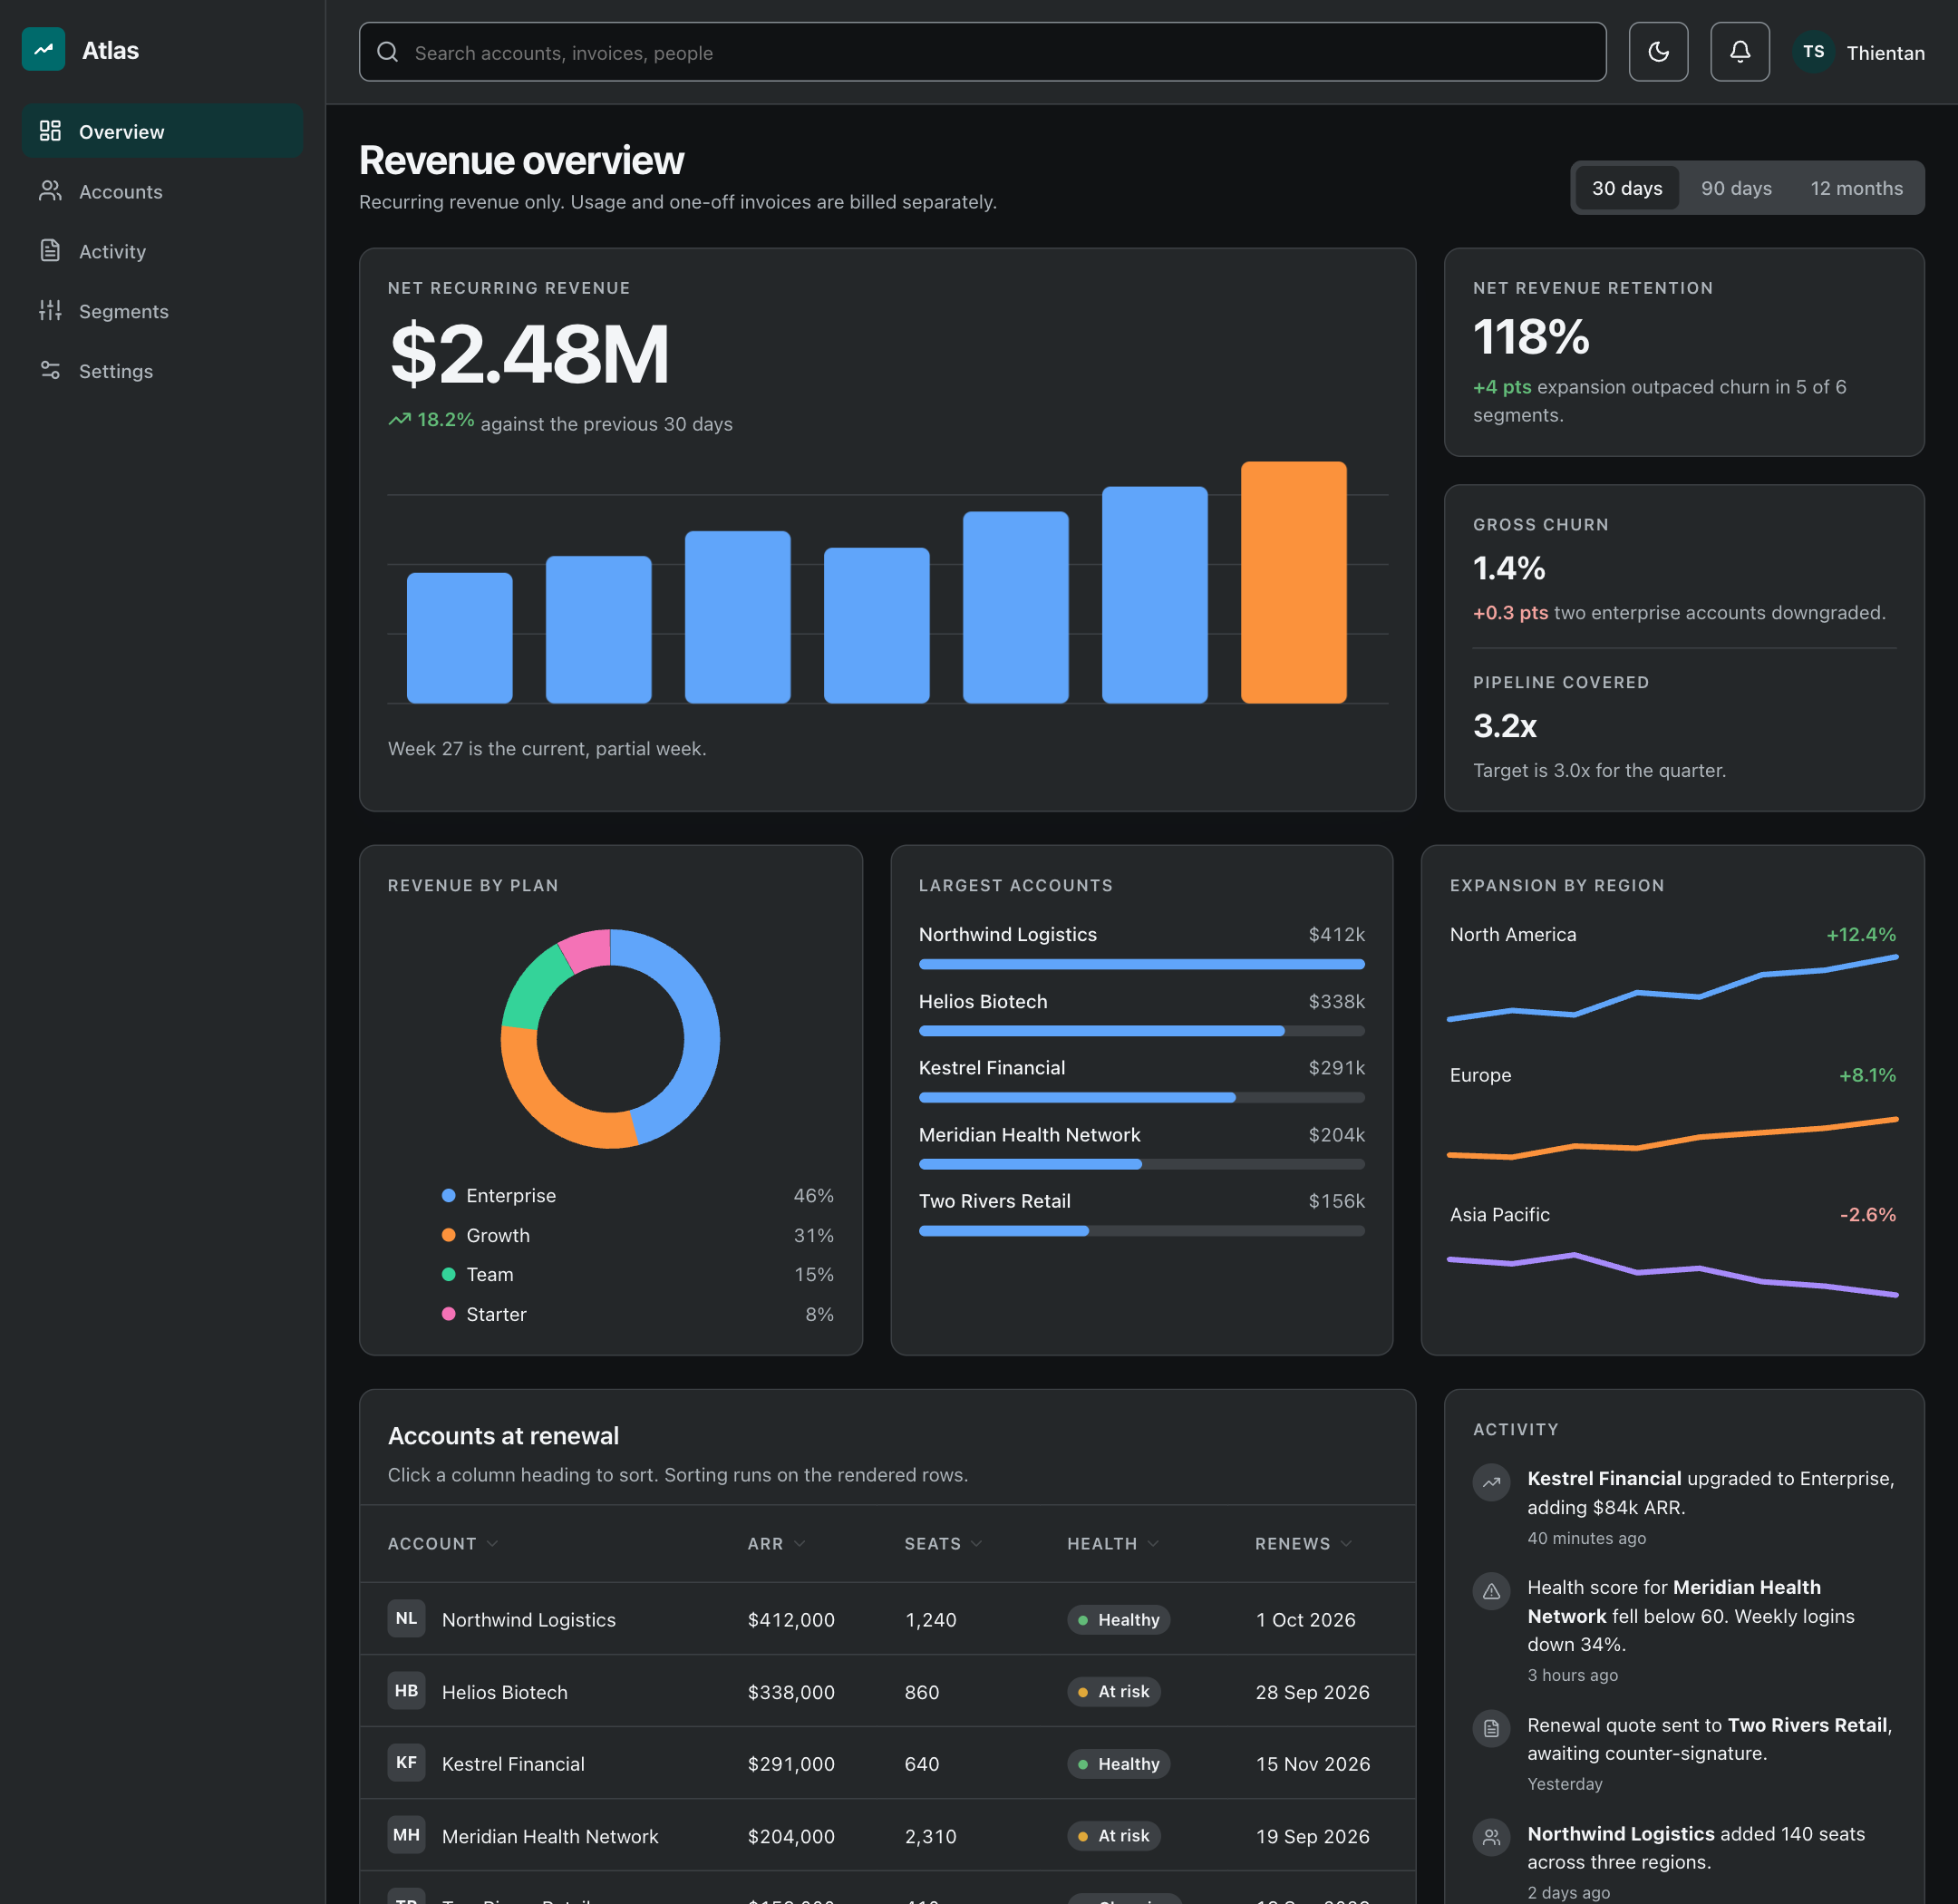
Not a mockup. These are screenshots of the files in examples/, taken by
node scripts/screenshot_docs.mjs from the same HTML the 52 gates measure, so
what you see below is what the gate run passed, in both themes.
Click through them yourself: plugin87.github.io/ux-ui-agent-skills. There are 56 live pages (twenty whole-product screens, five websites from a product launch to a Thai public service page, every component harness, both reference screens and an iPhone Duo simulator), with a theme toggle. No install, no clone.
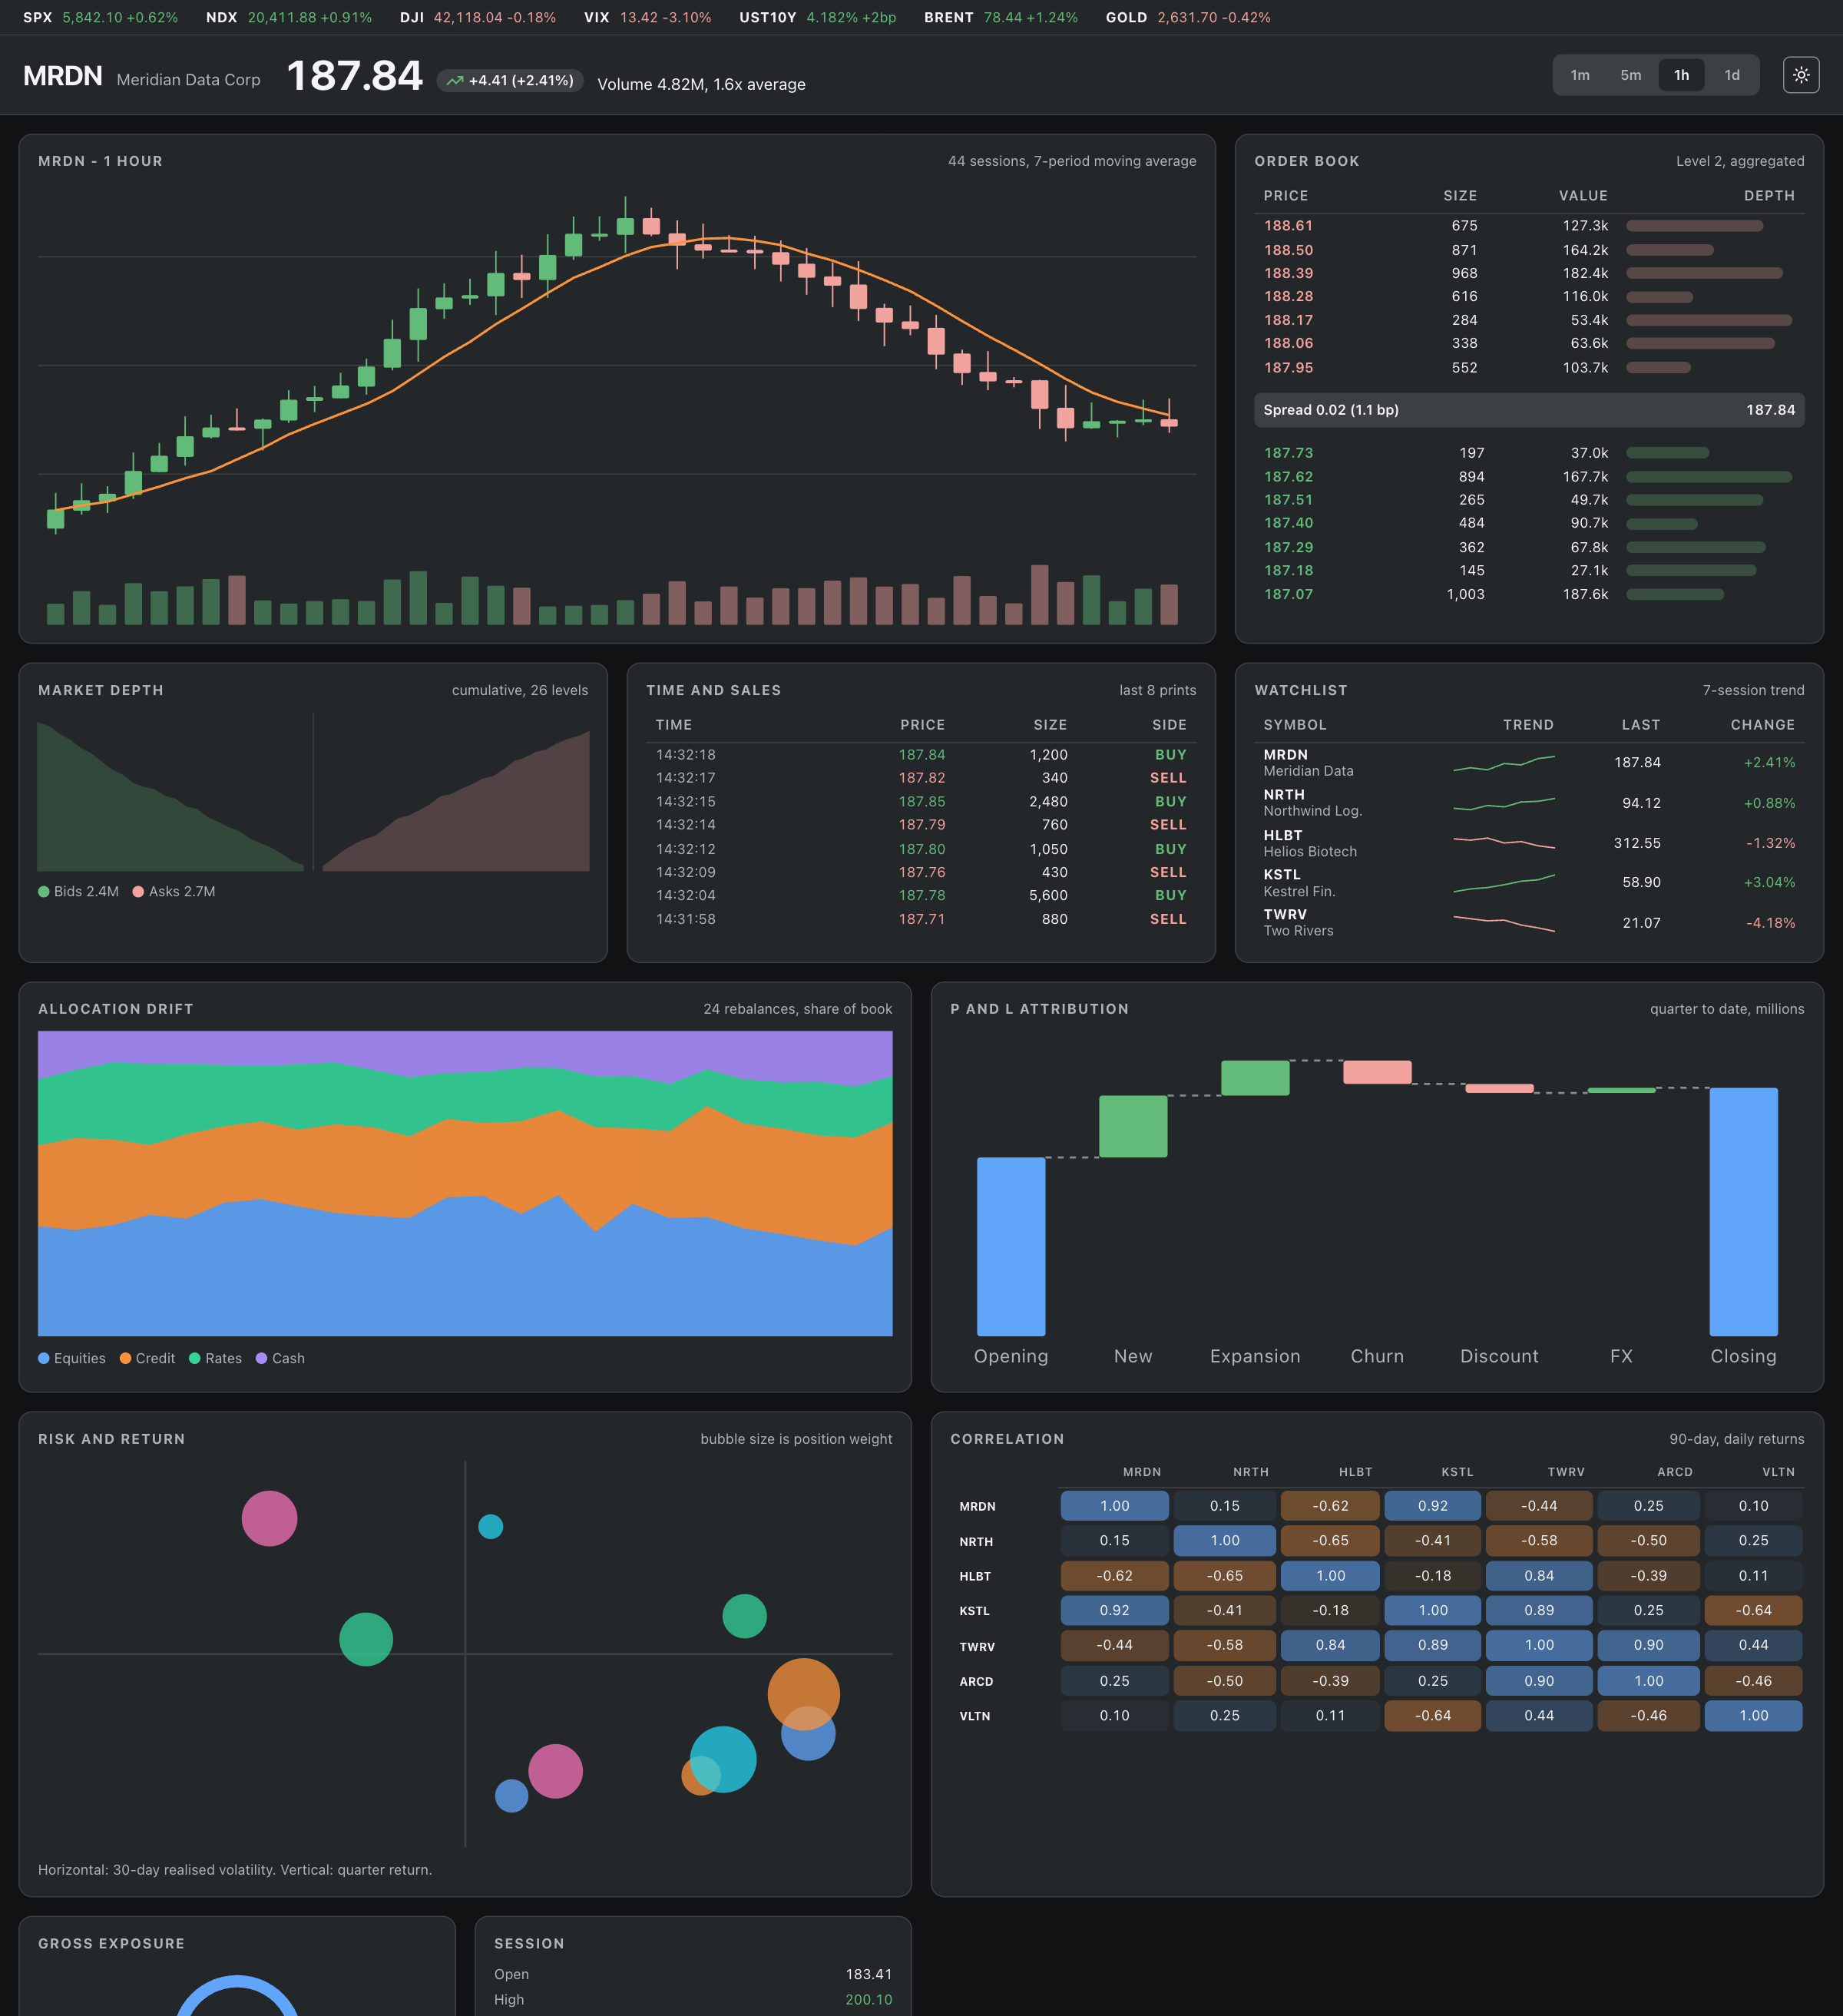
Meridian Terminal is the density test: ten chart types on one screen:
candlestick, volume, moving average, depth, order book, tape, sparklines,
stacked area, waterfall, bubble and a correlation matrix. Every one of them is
inline SVG drawn from the same tokens, with no chart library.
Open it live.
Build one yourself with /data-dashboard.
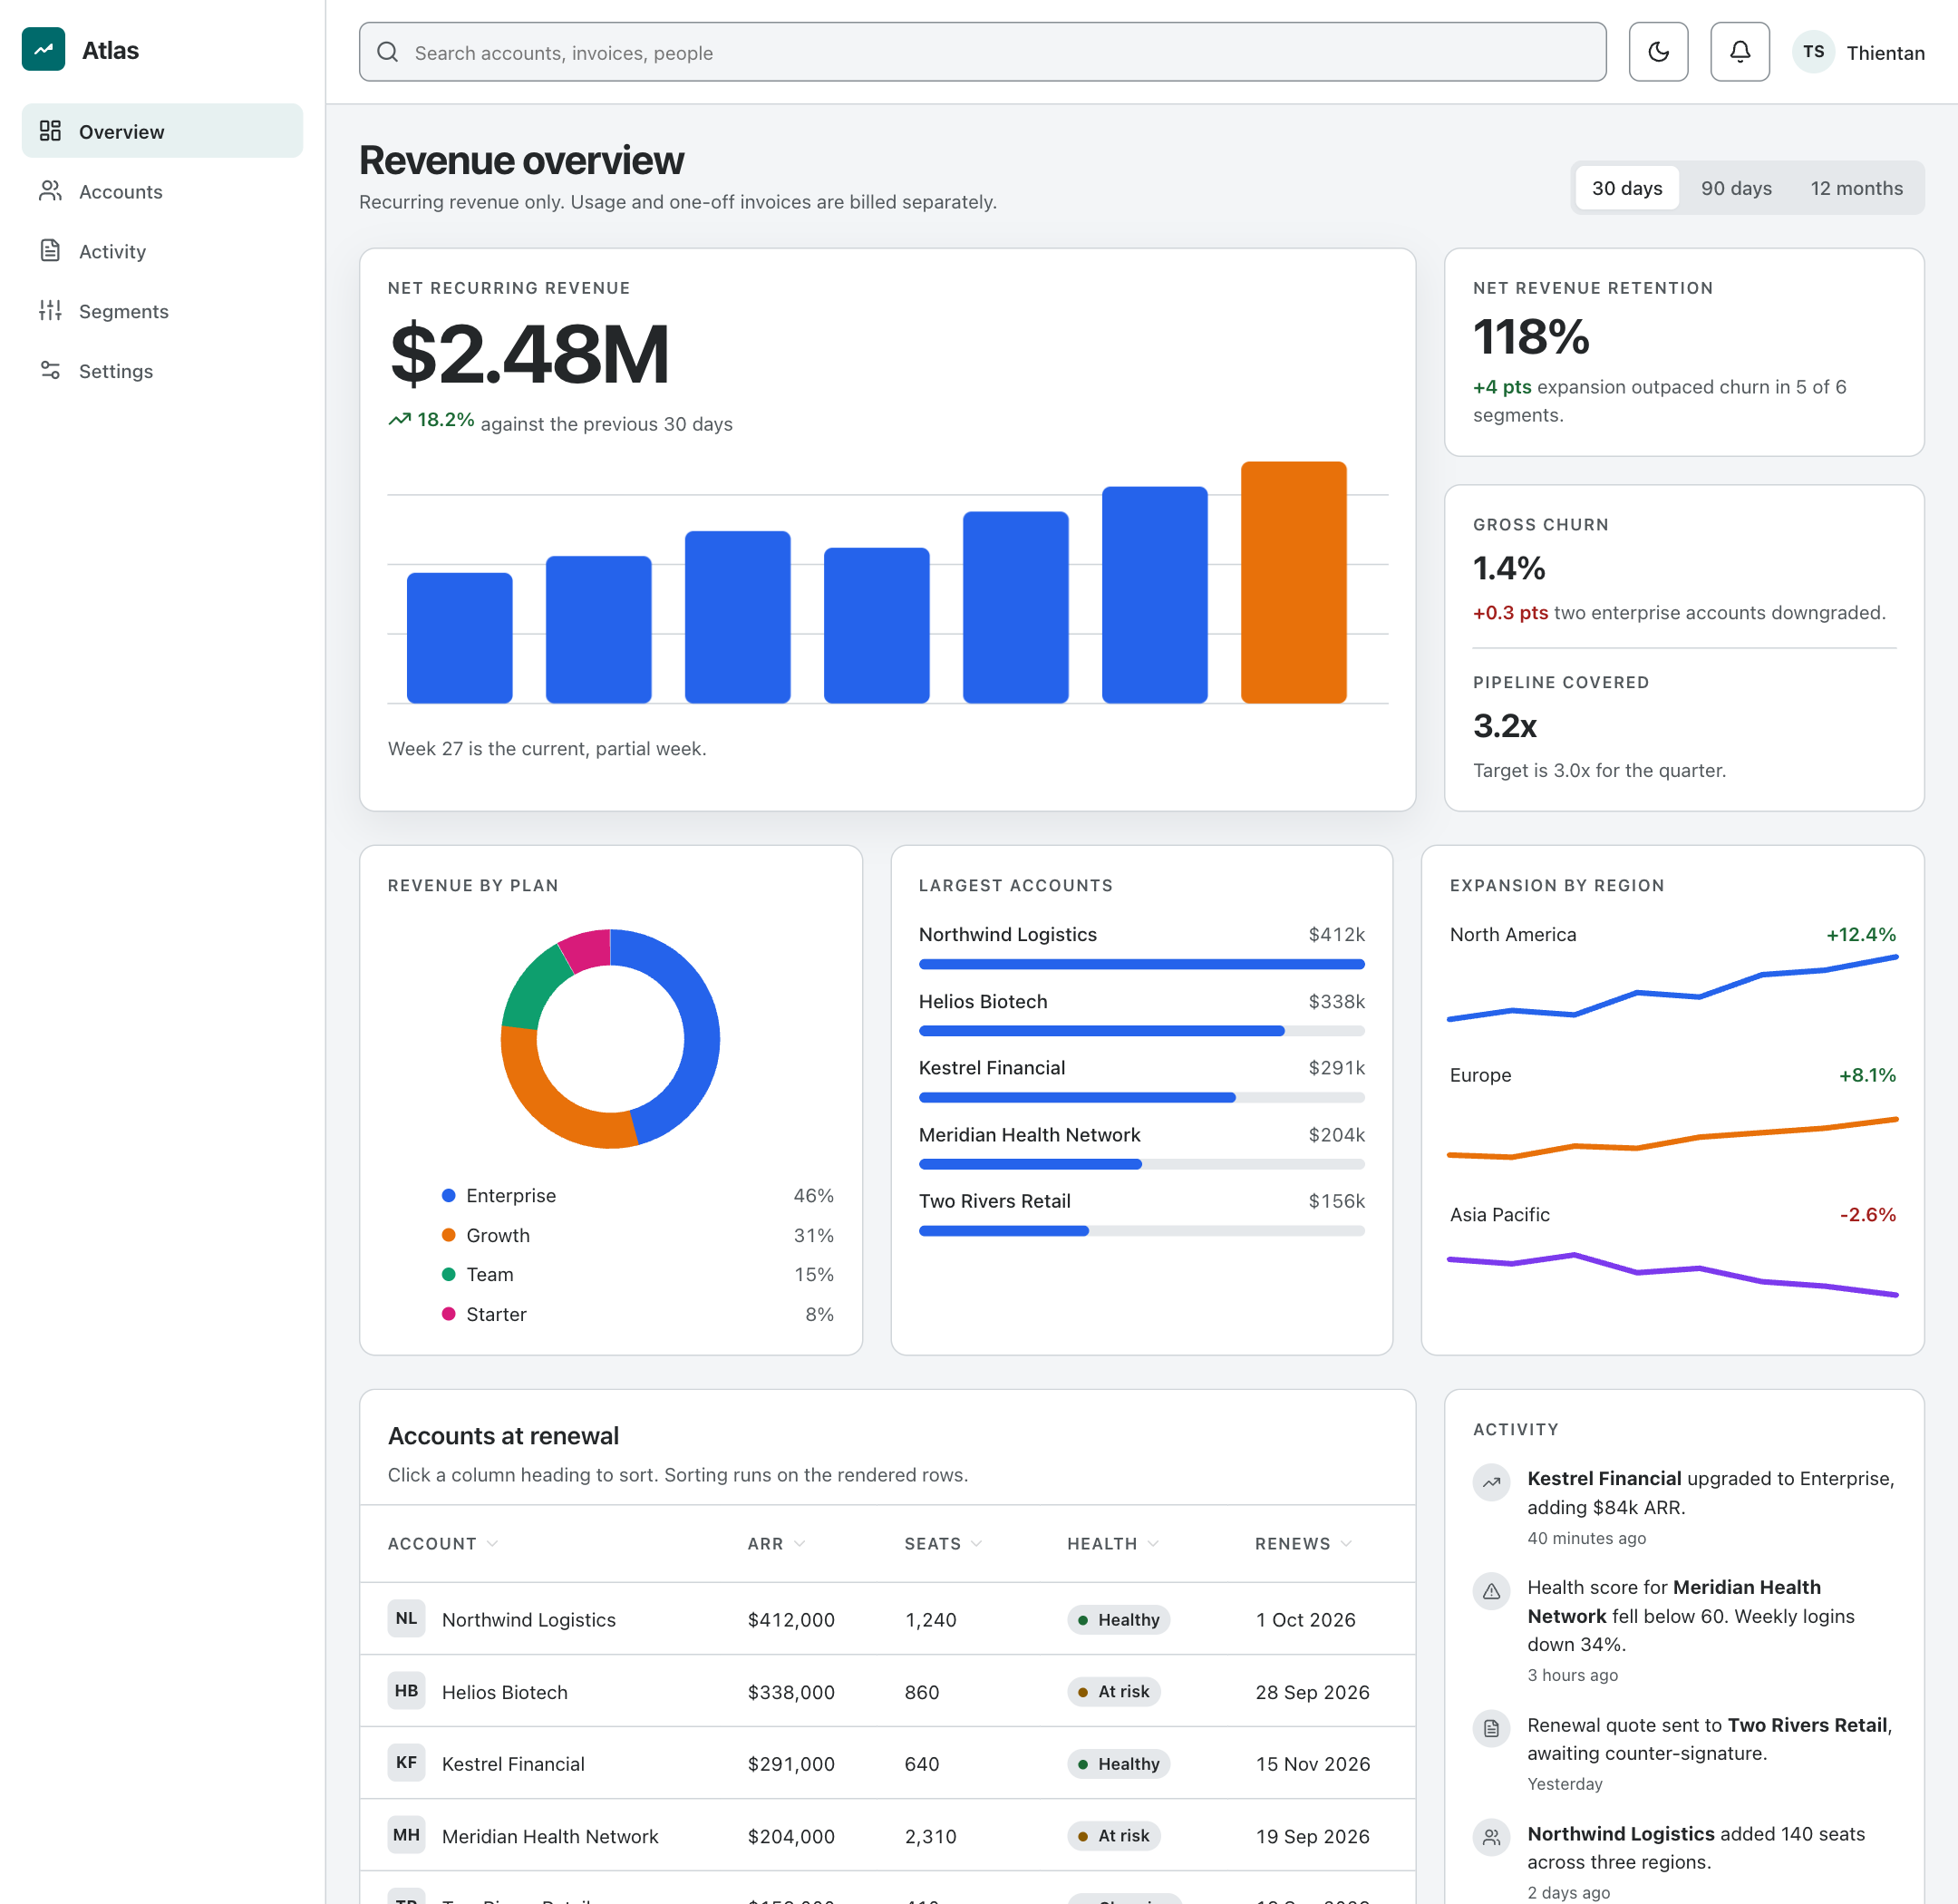
Atlas is one HTML file in examples/showcase/, built only from the kit's
tokens and rules: the hero figure leads at 3x the body size, the three
breakdowns are deliberately three different shapes rather than three identical
cards, the range tabs move the numbers, and the table headers really sort.
Open it live.
 |
 |
 |
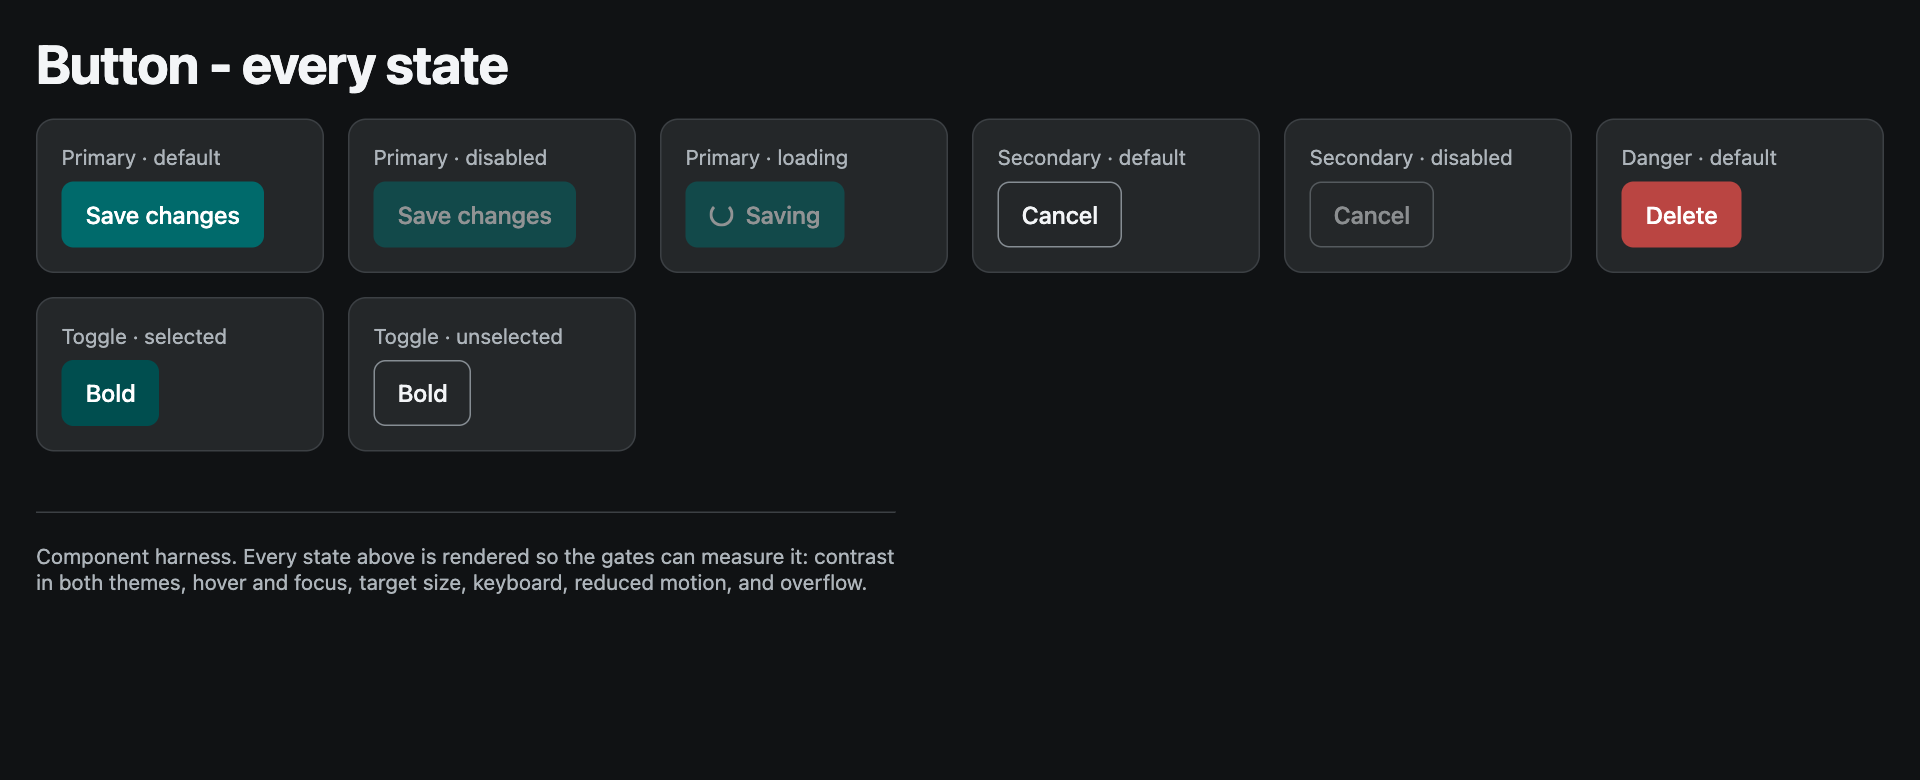 |
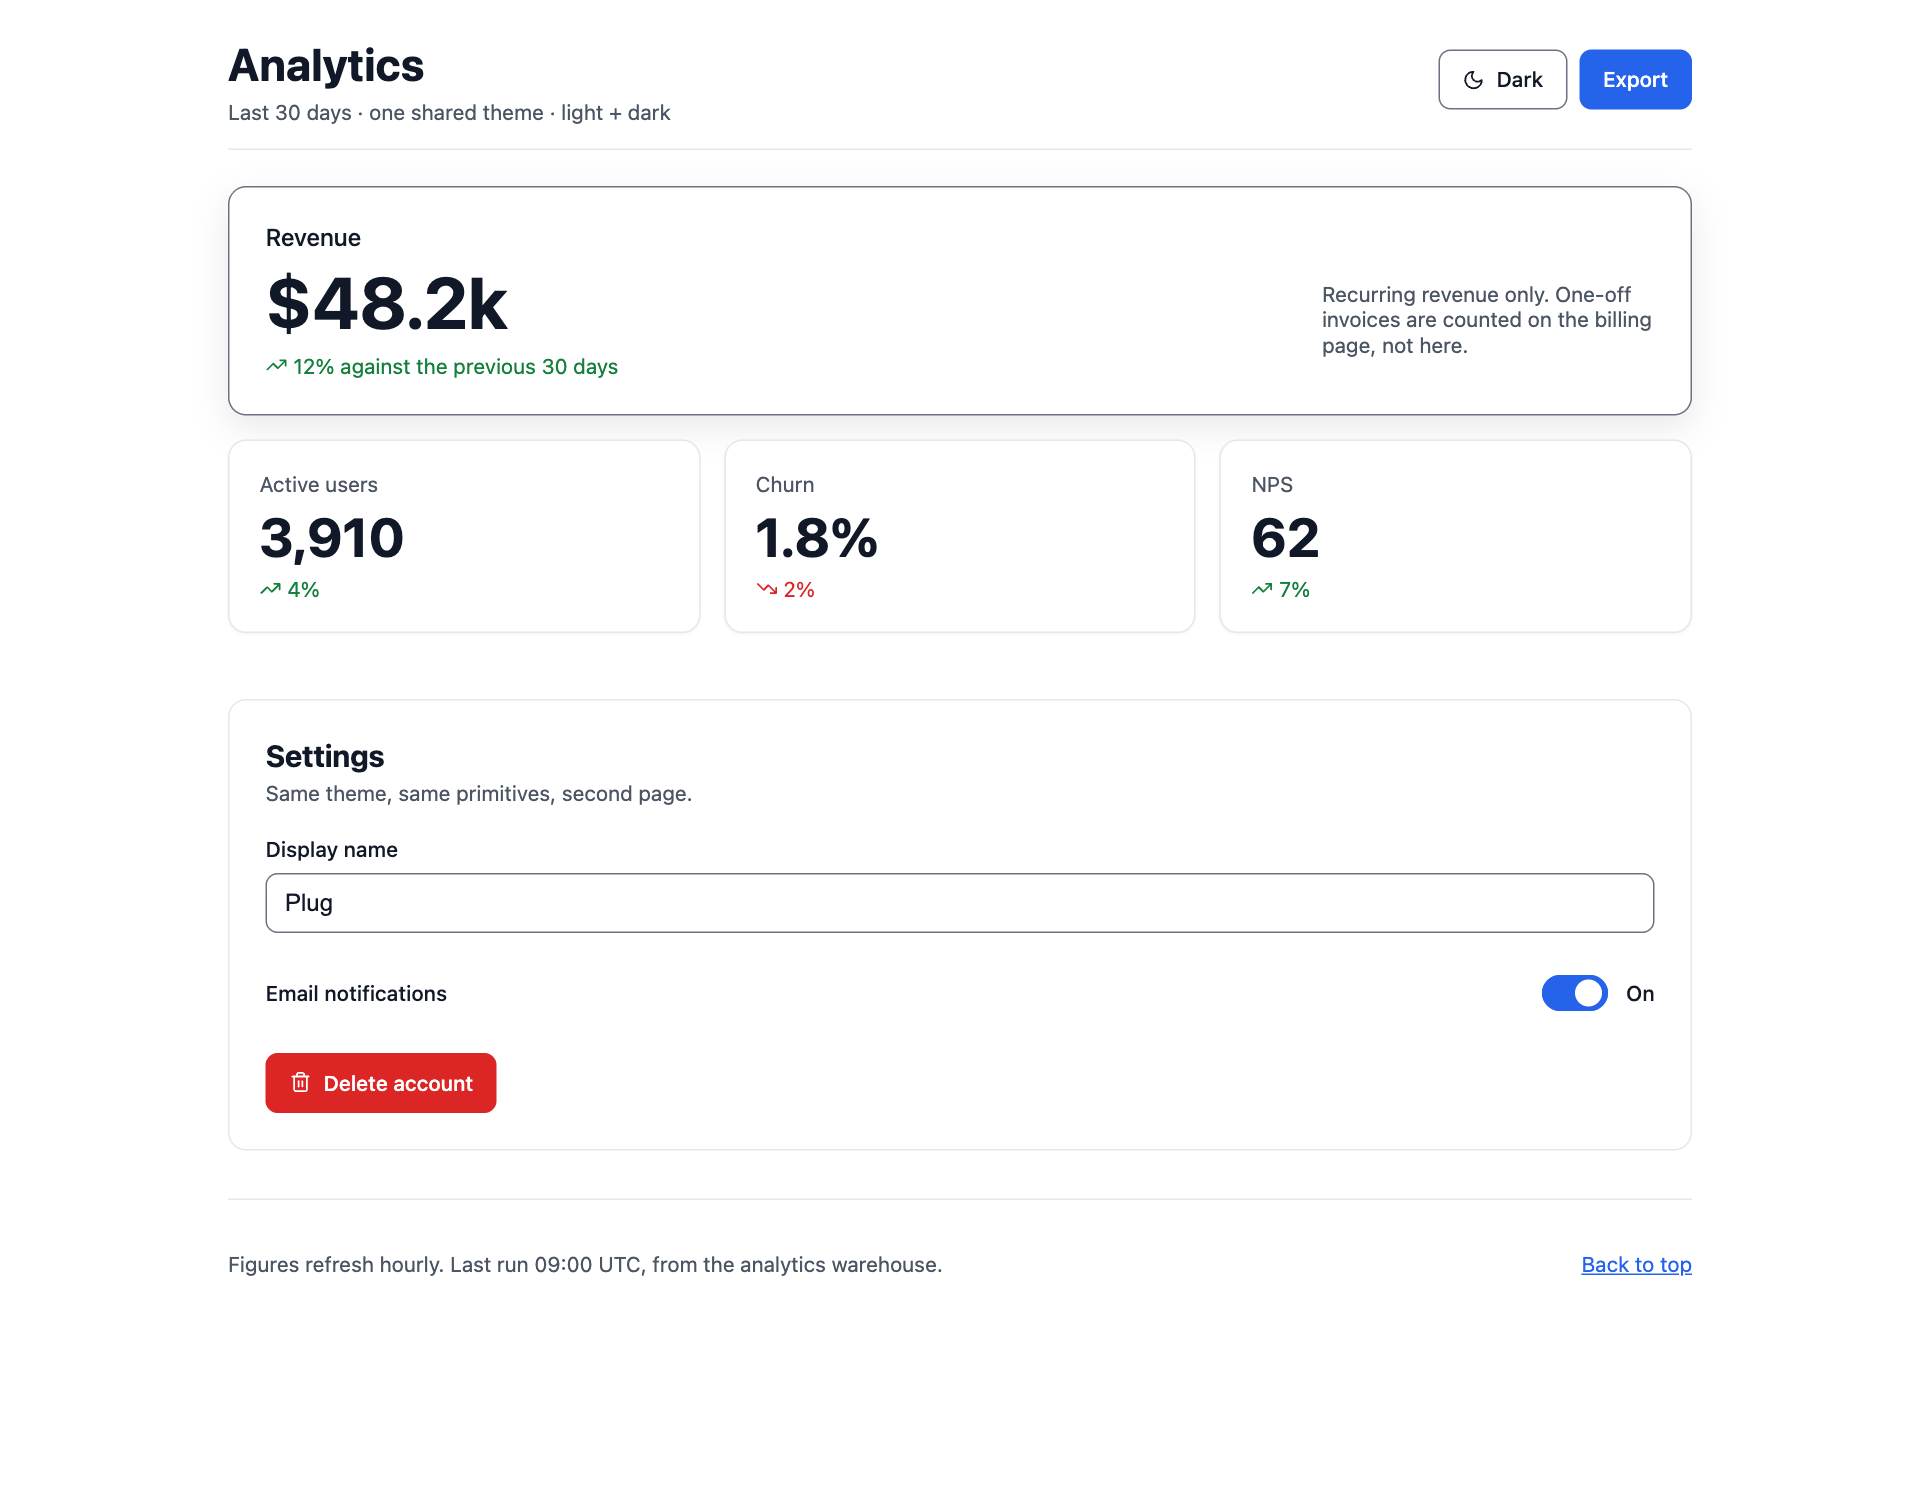
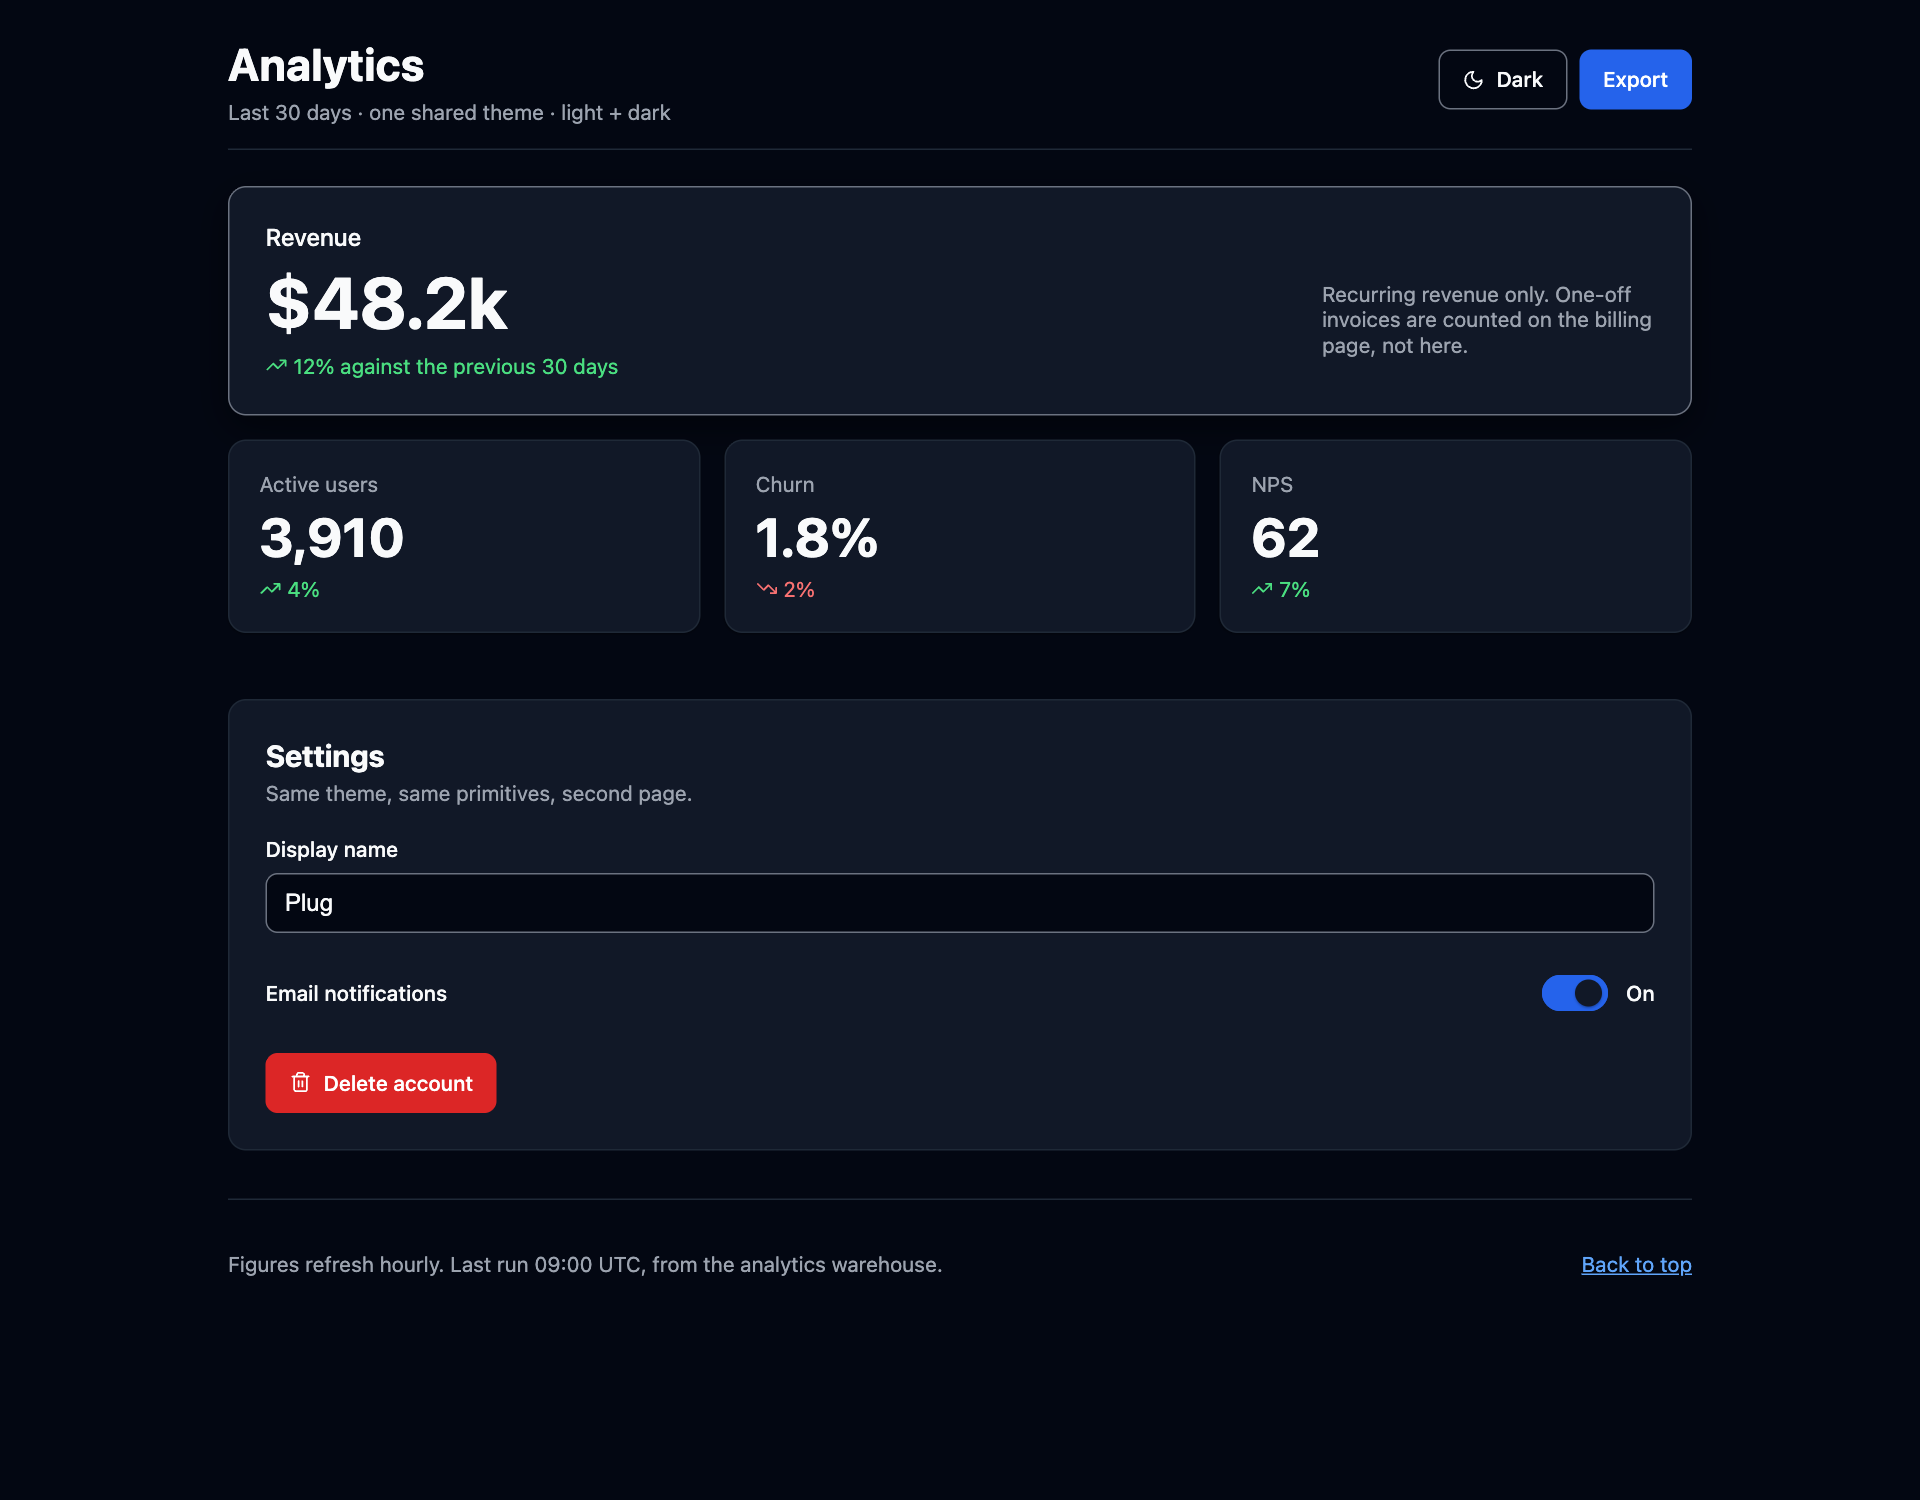
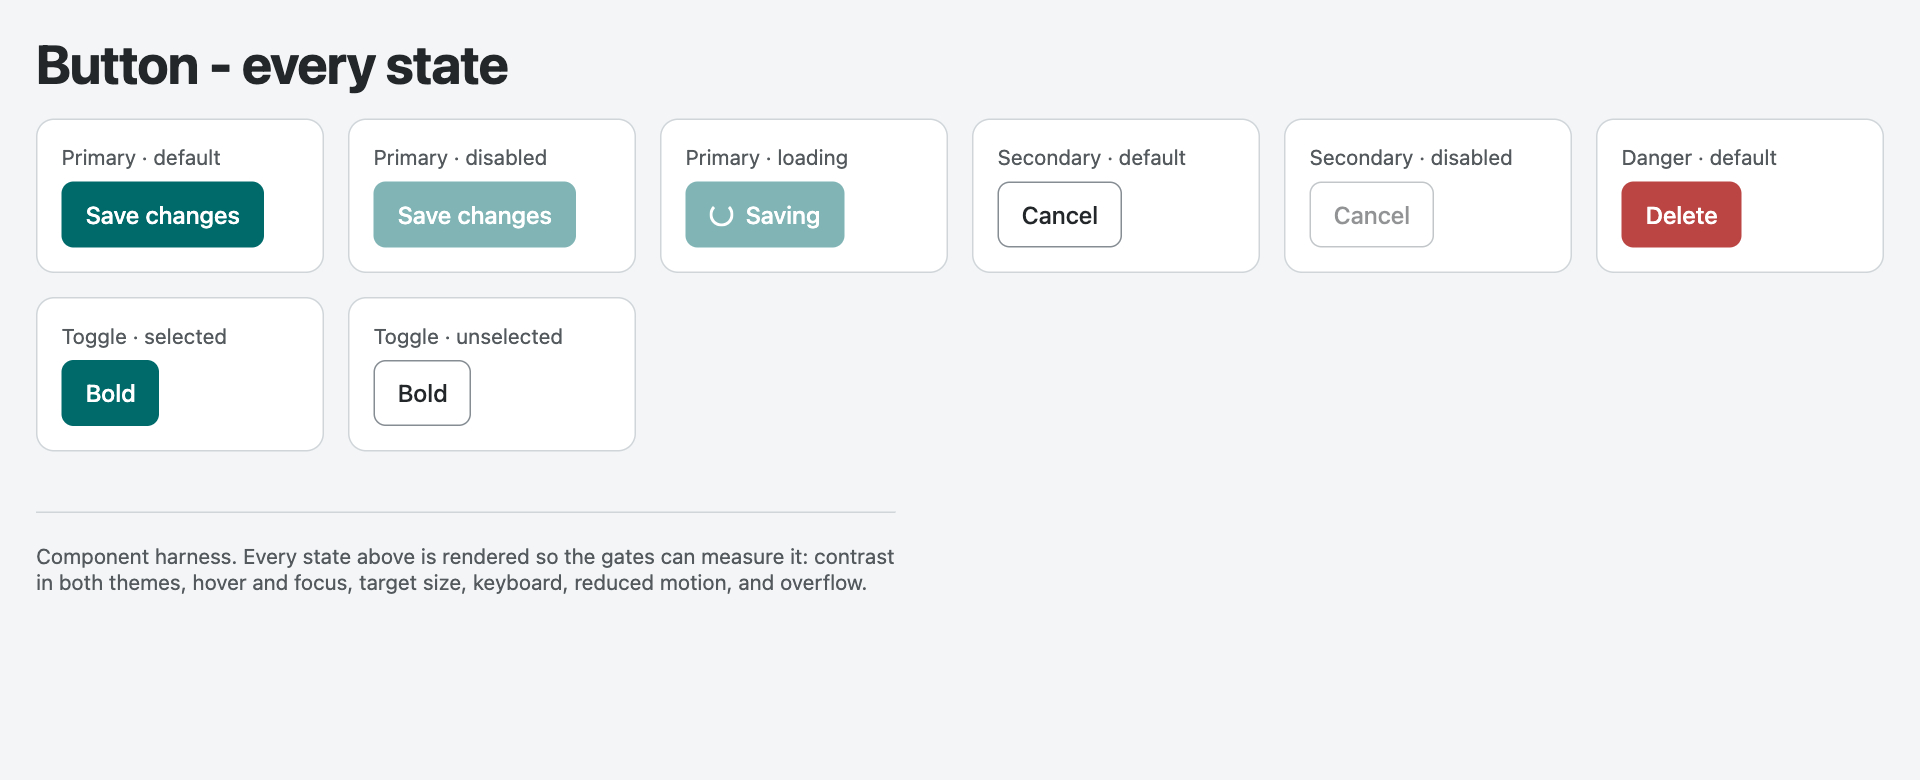
One theme, two modes, no per-page palette. The destructive action wears the
danger variant in both. Loading keeps full strength and swaps in a spinner
instead of borrowing the disabled dimming. Every one of those is a rule in
CLAUDE.md that a gate or a critic enforces.
---
Left: the same dashboard written the way a model writes it when nothing stops it: the indigo-to-purple gradient, four equal cards with no focal point, emoji as icons, one radius and one shadow everywhere, grey-on-white body text, and a blue Delete Account. Right: the reference app in this repo.
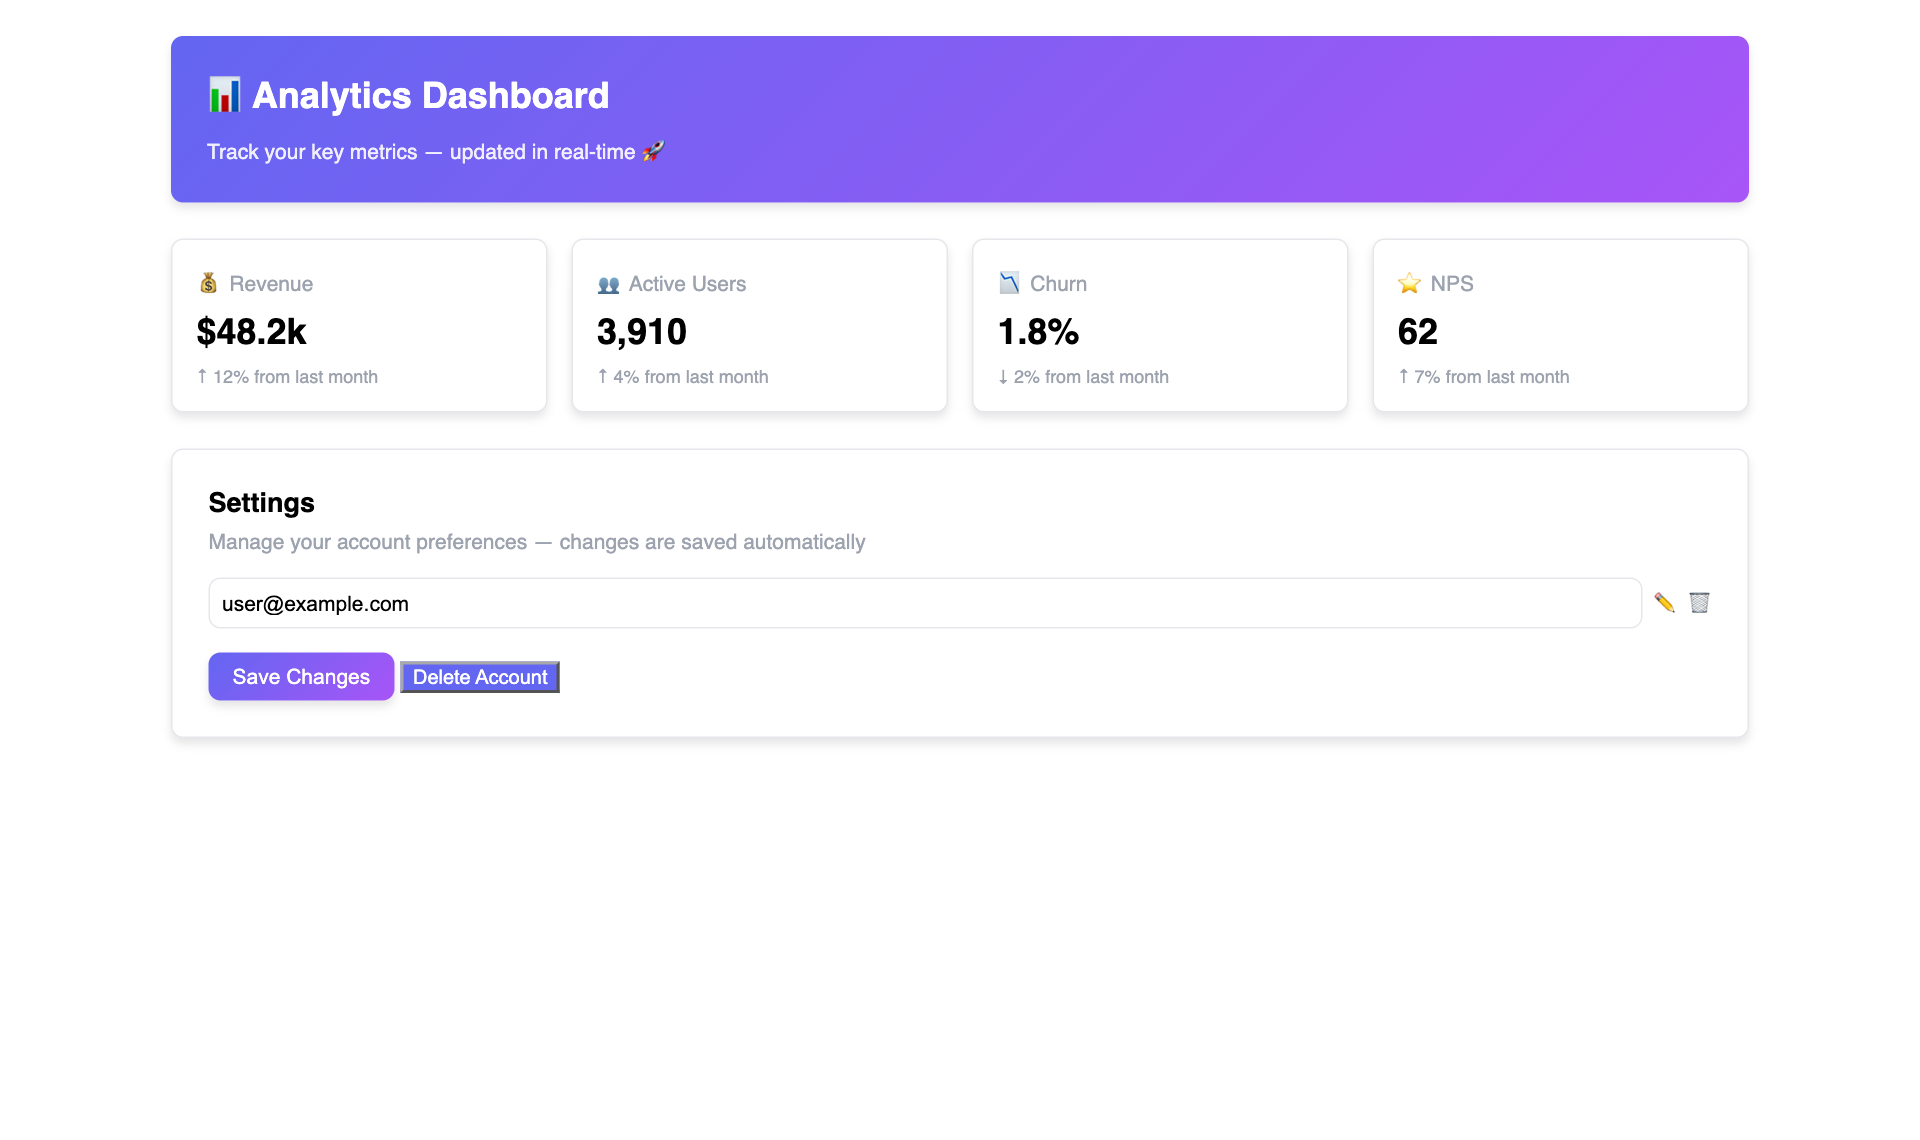 Statistical defaults |
Built to the rules |
The difference is not a matter of opinion, and that is the point. The page on the
left is tests/fixtures/bad/slop-screen.html; here is what the gates say about it:
| Gate | Verdict on the left-hand page |
|---|---|
| REAL-render WCAG | x : white text on a gradient has no measurable background |
| State-aware WCAG | "Analytics Dashboard" 1.00:1 (need 3)
x default "Save Changes" 1.00:1 (need 4.5) [rgb(255,255,255) on rgb(255,255,255)]: 6 states below AA |
| Target size (2.5.8) | x button.icon-btn is 15.3x16 (min 24x24) |
| Responsive | x @280px overflow +820px (widest: div.card) |
| axe-core | SERIOUS target-size |
| Slop tells | HIGH: hardcoded indigo-purple gradient, single radius, one flat shadow, #000 on #fff |
| Taste audit | HIGH: biggest heading 24px vs 14px body = 1.7x, not a display scale |
| Token by intent | x "Delete Account" is destructive but filled with rgb(99, 102, 241) (hue 239deg, not a danger colour) |
| No emoji | x slop-screen.html:55: emoji/pictograph: a chart glyph in the |
| No hardcoded values | FAIL: 63 hardcoded value(s) |
Ten gates reject it, none of them on a matter of taste. The right-hand page passes all 52.
The last row is there because building this comparison broke a gate open.
lint_intent originally read that blue Delete Account as fine: it resolved
"primary" and "danger" from the page's own CSS variables, and a page with no
tokens resolved neither, so it skipped the page and reported zero intent-bearing
controls. An untokenised page is precisely where intent gets picked by
convenience, so the gate no longer looks away: a destructive label filled with a
saturated colour outside the danger hue range is wrong-intent with or without a
theme. Re-checked against every example in both themes afterwards: no false
positives.
tests/meta/browser-gates.test.mjs pins every claim in this table, so it cannot
rot.
---
Two subagents were handed a brief and a project scaffolded by ux-ui-skills new,
which installs the kit and ships no example screens, and nothing else. No
hints, no warning that anything would be scored, no access to the conversation
that built the kit. They met CLAUDE.md and .claude/rules/ the way a new
user's agent does.
Both scored 14/14 on an independent run of evals/run.mjs, scored here
rather than self-reported. The rules transfer across a cold start.
And the two runs cost the kit seven defects that four in-session runs never
hit, because a familiar run keeps reaching for a finished demo theme instead of
the template a real user gets: a secondary button at 1.13:1 dark-on-dark
because the component tier never followed the dark map; a reduced-motion policy
in an external stylesheet read as "no policy" (Chromium treats a file:// linked
sheet as cross-origin, so the gate was blind exactly where every real project
lives); a missing scrim token; a theme that emitted colours and no spacing; an
intent gate that did not know "cancel subscription" is destructive.
Then the outputs went to /critique, which renders the work and argues for
rejection. Verdict on two pages that pass all fourteen gates: rework, eight
findings, five Major, and not one of them measurable: an empty state that reads
as a page that failed to load, a theme toggle that communicates nothing about its
own state, a toast claiming "Draft project created" over a list that never
changed, and a loading state wearing the disabled dimming so it reads as "you
cannot do this".
The blind outputs were never edited. They are in evals/out/ as the record
of what a cold-start agent produced; patching them would be editing the
experiment. The findings were spent on the kit instead. One of them became a
gate, verify_interactive.mjs, which fails any control that declares a state
contract and changes nothing when clicked.
The whole log, including what is still unproven, is in evals/RESULTS.md.
---
| Capability | Description |
|-----------|-------------|
| Design Token Generation | Produces DTCG-format JSON tokens (colors, typography, spacing, shadows, borders, breakpoints, motion) with a 3-tier architecture: Primitive → Semantic → Component |
| Component Design | Designs components from Atoms to Templates following Atomic Design, with anatomy, variants, states, token mapping, and accessibility specs |
| Code Generation (any framework) | Adapter Protocol targets any stack (React+Tailwind, Next.js, SwiftUI, Vue, Svelte, Angular, Solid, Web Components/Lit, React Native, Flutter, Jetpack Compose, vanilla CSS, CSS-in-JS) or generates a new adapter on demand |
| Design-System Interop | Maps to/from any design system (Material 3, Apple HIG, Fluent, Carbon, shadcn/ui, Radix…) via a role-based crosswalk |
| Runnable Skills | 19 invocable /skills (each declaring invocation: user|model) + 5 slash commands + real scripts: token and contrast validators, real-render and state-aware WCAG gates, axe-core a11y, focus-trap, RTL, target size, keyboard, reduced motion, overflow, token-by-intent, taste and slop audits, token build |
| Accessibility Auditing | Evaluates against WCAG 2.2 AA/AAA with prioritized findings (P0/P1/P2) |
| Design Review | Scores designs across 6 dimensions with Nielsen's 10 Heuristics and a structured findings table |
| Prototyping & Research | Guides through a 5-level fidelity ladder, user journey mapping, and usability testing scripts |
| Motion Design | Tokenized durations, easing curves, transition presets, and reduced-motion strategy for accessible animation |
| UX Writing | Voice & tone system with error/empty-state formulas, microcopy patterns, and inclusive language guidelines |
| Design Taste | Native anti-slop doctrine, aesthetic archetypes, and a library of 2,144 design systems for layout variance, editorial typography, and premium visual direction |
---
Five ways in, and which one is yours: docs/INSTALL.md
walks through the Claude Code plugin, the AGENTS.md surface for Codex and
Cursor, the MCP server, Homebrew and npx: what each one installs, and what
you give up by choosing it.
Two lines in Claude Code, and every skill, command, and agent is available in any project you open, with no files copied into your repo:
/plugin marketplace add plugin87/ux-ui-agent-skills
/plugin install ux-ui-agent-skills@ux-ui-agent-skills
You get 26 skills and the design-critic agent.
Fourteen the model reaches for on its own when the work calls for them:
design-tokens, design-component, design-code, design-review,
a11y-audit, apply-aesthetic, data-dashboard, design-qa,
figma-integration, performance, token-build, ux-writing,
design-doctrine, and design-screen, the one that claims "design a page /
screen / app", which until 2026-10-05 no skill did, so the most common request
there is matched nothing strongly and the kit got used at a fraction of its
depth.
Twelve you start yourself, because each one takes an action or sets a
direction that should be your call: /brandkit, /governance, /image-to-code,
/migrate-design-system, /prototype, /redesign, /gate, /critique,
/grill-me, /ship, /scaffold-project, /observe. They carry
disable-model-invocation: true, which is the field that actually stops the
model invoking them. Until 2026-10-05 six of them said invocation: user, a
key Claude Code does not read, so they were auto-invocable the whole time. The
last five were commands and are skills now, so they have a CLAUDE_SKILL_DIR of
their own and their paths resolve under a plugin install.
design-doctrine carries the house rules that CLAUDE.md carries in the repo,
because a plugin root CLAUDE.md is not loaded as project context, as Claude
Code's own plugin validate says so.
Then just work. Ask for the thing you want and the right skill loads itself:
"Design a notification component with all states and accessibility"
"Build the billing settings screen, one shared theme, light and dark"
"/grill-me"      interrogate the brief before anything is built
"/gate"          run all 52 checks and report the real N/N
"/critique"      hand the result to a critic that argues for rejection
"/observe"       did the agent follow the rules? sessions, blocks, findings left open
If the skills do not show up straight away, start a new session. To check what is loaded, update, or remove it:
claude plugin details ux-ui-agent-skills    # inventory + token cost per skill
claude plugin update  ux-ui-agent-skills
claude plugin uninstall ux-ui-agent-skills
claude plugin marketplace remove ux-ui-agent-skills
uninstall also deletes the plugin's data folder, which holds the gate
receipts and the /observe history.
34 of the gates open a real browser. They use the Chrome installed on the
machine, or the one npx playwright install chrome downloads. Without either
they cannot measure: run through scripts/gate.mjs, as the skills do, they fail
with REQUIRED, FAILING instead of passing on nothing.
npx ux-ui-agent-skills demo # copies the rendered examples and opens them
Every page it opens is a page the gates measure. Delete the folder afterwards; nothing was installed. Or skip the copy entirely and use the live demo.
claude mcp add ux-ui-gates -- npx -y --package=ux-ui-agent-skills ux-ui-mcp
Six tools: list_gates, run_gate, review_ui, get_doctrine,
get_design_system, get_tokens. Read the doctrine and the tokens before
generating, run the gates on what you produced after.
AGENTS.md already lets any agent read the doctrine. This lets any MCP
client run the 52 gates, which reading cannot do. Plenty of things can
describe good UI, very little can tell you afterwards that the contrast you
shipped is 3.9:1 on hover.
It returns what the gates printed, unedited, with their exit codes: 0 looked and
found nothing, 1 found something, 2 could not look, never a pass. No SDK
dependency; the protocol is implemented directly so "dependencies": {} stays
true. Details in docs/MCP.md.
brew install plugin87/tap/ux-ui-agent-skills
ux-ui-skills init                   # CLAUDE.md + .claude/ skills, rules, hooks
ux-ui-skills init --agent codex     # AGENTS.md, for Codex, Cursor, Copilot, Aider
Same npm tarball the npx route runs, so this is a convenience rather than a
second product that can drift. The formula is generated from the registry and
its test do block asserts the installed CLI reports the version the formula
names, and that --agent codex writes AGENTS.md without CLAUDE.md or
.claude/. Details in docs/HOMEBREW.md.
npxDrop the kit into any project, no clone needed:
npx ux-ui-agent-skills init          # full kit into the current folder
npx ux-ui-agent-skills add tokens taste design-systems   # just some areas
npx ux-ui-agent-skills list          # see all areas
npx ux-ui-agent-skills library get stripe   # fetch one design-system spec
Flags: --force (overwrite existing files) · --dry (preview, change nothing).
The 2,144 design-system specs are 27.6MB, and a project uses one or two, so
init does not copy them. It installs an index of every spec with its sha256,
and the agent fetches the one it picks with `node scripts/library.mjs get
`. A fetched file whose sha256 does not match the index is refused and
nothing is written. library pull fetches all of them for offline work. The
plugin (Option A) and a clone carry every spec already. To browse all 2,144, open
design-systems/catalog.md: GitHub's folder view lists
only the first 1,000.
Working on the kit itself, or want it vendored? Clone and copy instead.
Then start using: open the project in Claude Code or any Claude-powered IDE. CLAUDE.md loads automatically, activating the agent persona with full access to every tokens / components / taste / design-system file and the runnable /skills.
"Design a notification component with all states and accessibility"
"Review this login page against WCAG 2.2 and Nielsen's heuristics"
"Generate React + Tailwind code for a data table with sorting and pagination"
"Create a color token palette for a fintech brand using blue as the primary"
"Audit this form for accessibility issues, and give me a prioritized findings table"
"Write the empty state and error copy for the onboarding flow"
"Spec the motion for the modal open/close with reduced-motion fallback"
---
The kit ships 52 objective gates behind one command:
node scripts/accuracy_report.mjs # 52/52 or it fails, no partial credit
34 of them open a real browser, so they need one installed. `npx
ux-ui-agent-skills init does not install Playwright. Whether /plugin install`
does depends on the Claude Code version: 2.1.301 installed the kit's npm
dependencies, Playwright included, into the plugin folder. Neither installs the
browser itself. In a clone, run this once before expecting a full score:
npm install                          # playwright
npx playwright install chrome        # real Chrome: six gates require the channel
Without it those 34 report REQUIRED, FAILING under accuracy_report.mjs, which
is the honest answer. Run individually they print SKIPPED and exit 0, so
run a single render gate through scripts/gate.mjs (or prefix it with
DS_REQUIRE_BROWSER=1) if you are reading its exit code, rather than reading
silence as green. Every skill already does.
Token validity, WCAG contrast on a real headless render in light and dark, every element in default/hover/focus, axe roles and names, focus traps, RTL, responsive from 280 to 951px and folded on iPhone Duo, target size, keyboard operability, reduced motion (including content that only an animation reveals), silent text clipping, token-by-intent, and zero emoji anywhere in the output or the instruction surface.
What that number covers, stated exactly. 34 of the 52 checks open a real
browser, so what they measure is rendered HTML: the 23 component harnesses,
the twenty industry screens, the reference app, the live demo, the starter
template, and the React source compiled and server-rendered. The other 18 read
files: token JSON and alias resolution, contrast math on the token source,
component specs, hardcoded values, theme references, emoji, hooks, the
instruction surface held in step across CLAUDE.md and AGENTS.md, and
destructive-intent declarations in framework source.
The split is not typed here: tests/meta/counts.test.mjs derives it from which
gates import Playwright and fails if this paragraph drifts from the report. It
read 35/16 until 2026-10-07, when the derivation was first run. Those were two numbers
nobody had measured, in the section about not stating numbers you did not
measure.
Framework source (.tsx, .vue, .swift) gets the file-reading checks: no
emoji, no hardcoded values, every var(--…) resolving to the theme, and, since a
blue Delete shipped in this repo's own Settings.tsx while the HTML twin of that
screen was correct, every destructive control declaring its intent
(lint_intent_source.mjs). That last one proves a declaration, never a
colour: variant="destructive" wired to a blue token passes it.
Only a render catches that, so the React components are now compiled with esbuild,
server-rendered, and put through the same browser gates as the HTML
(render_framework_source.mjs, which also fails if any class the components emit
resolves in no linked stylesheet). .vue and .swift are still file-checks only,
and are not proven by this number until they are rendered and measured.
That is correctness. It is not quality, and the kit says so out loud:
| Question | Answer |
→ →
 →
 →
 →
 →
 →
 →