1
 →
ninetyhe-90/de-armor is an open-source project on GitHub, mainly written in HTML. 破甲 / De-Armor:任务导向的回复校准,保住事实与条件,减少无效防御,补齐真正交付。 It currently holds 139 stars and 35 forks with 0 open issues, and was last pushed on 2026-10-29 (repository created 2026-10-27).
Git Homed tracks it on the Today's Trending board, currently at rank #55 with 0 new stars today.
Version 2.1.2
Say the truth: no lying, no bluffing. If you don't know, say so; if it can't be done, say so; if it should be done, do it. Less self-defense, more results. Cut the filler, never the facts. A skill that turns evasive, padded, or fake-neutral AI answers back into something that actually moves the task forward.
v2 rewrote the rulebook. v1 judged answers with banned-word scores and a 90-point threshold. v2 removed that. Output now usesschema_version: 2,stats.score: null, and the audit is task-oriented: did the answer keep the facts, conditions, uncertainty, and boundaries, and did it deliver the artifact the user asked for?--min-scorenow fails loudly instead of being silently ignored.
The machine check is a second pair of eyes, not a verdict. Passing armor_lint.py means no anchors were dropped and no forbidden claim appeared in this pass. It is not a certification of factual or semantic correctness.
AI answers often fail in a specific way: they are optimized to look careful instead of being useful. Disclaimers come first, research gets pushed back to the user, "it depends" replaces a conditional recommendation, uncertainty is flattened into certainty — or a useful sentence is compressed into an empty one.
de-armor is a task-oriented response calibration skill, packaged as a portable SKILL.md rather than a vendor plugin. It is not tied to any single agent or vendor. It locks the task and the information that must survive, then rewrites from the task instead of from a banned-word list. Facts, conditions, negations, uncertainty, and permission boundaries stay. Repetition, identity preambles, and empty hedging go.
| You get | What it does | |---|---| | Task lock | Separates the real request — answer, choice, artifact, debugging step, or emotional support — from surface politeness | | Information ledger | Preserves facts, conditions, uncertainty, boundaries, and the artifact due this turn | | Task-first rewrite | Keeps, compresses, reorders, and completes; never invents a fact to sound specific | | Optional auditor | A read-only, offline Python checker for fact anchors, dropped constraints, and newly introduced numbers | | Reproducible cases | Six scenarios with before/after text, counterexamples, and an information contract re-checked by script |
It is not a "be concise" prompt. Brevity is not the goal; delivery is. A refusal can be the right answer, and a long answer can be the right answer.
---
---
de-armor is a portable SKILL.md plus optional references/ and scripts/. Nothing in it is tied to a specific product: no SDK, no runtime, no config file, no vendor API. Any agent that can read a skill file — or a system prompt — can use it.
# From ClawHub
clawhub install de-armor
Or clone it and wire it up yourself
git clone https://github.com/ninetyhe-90/de-armor.git
Then load it the way your agent already loads skills:
SKILL.md into its rule file, AGENTS.md, or system prompt.SKILL.md to the conversation context.SKILL.md. The auditor is optional and uses the Python 3.9+ standard library, with no third-party packages.
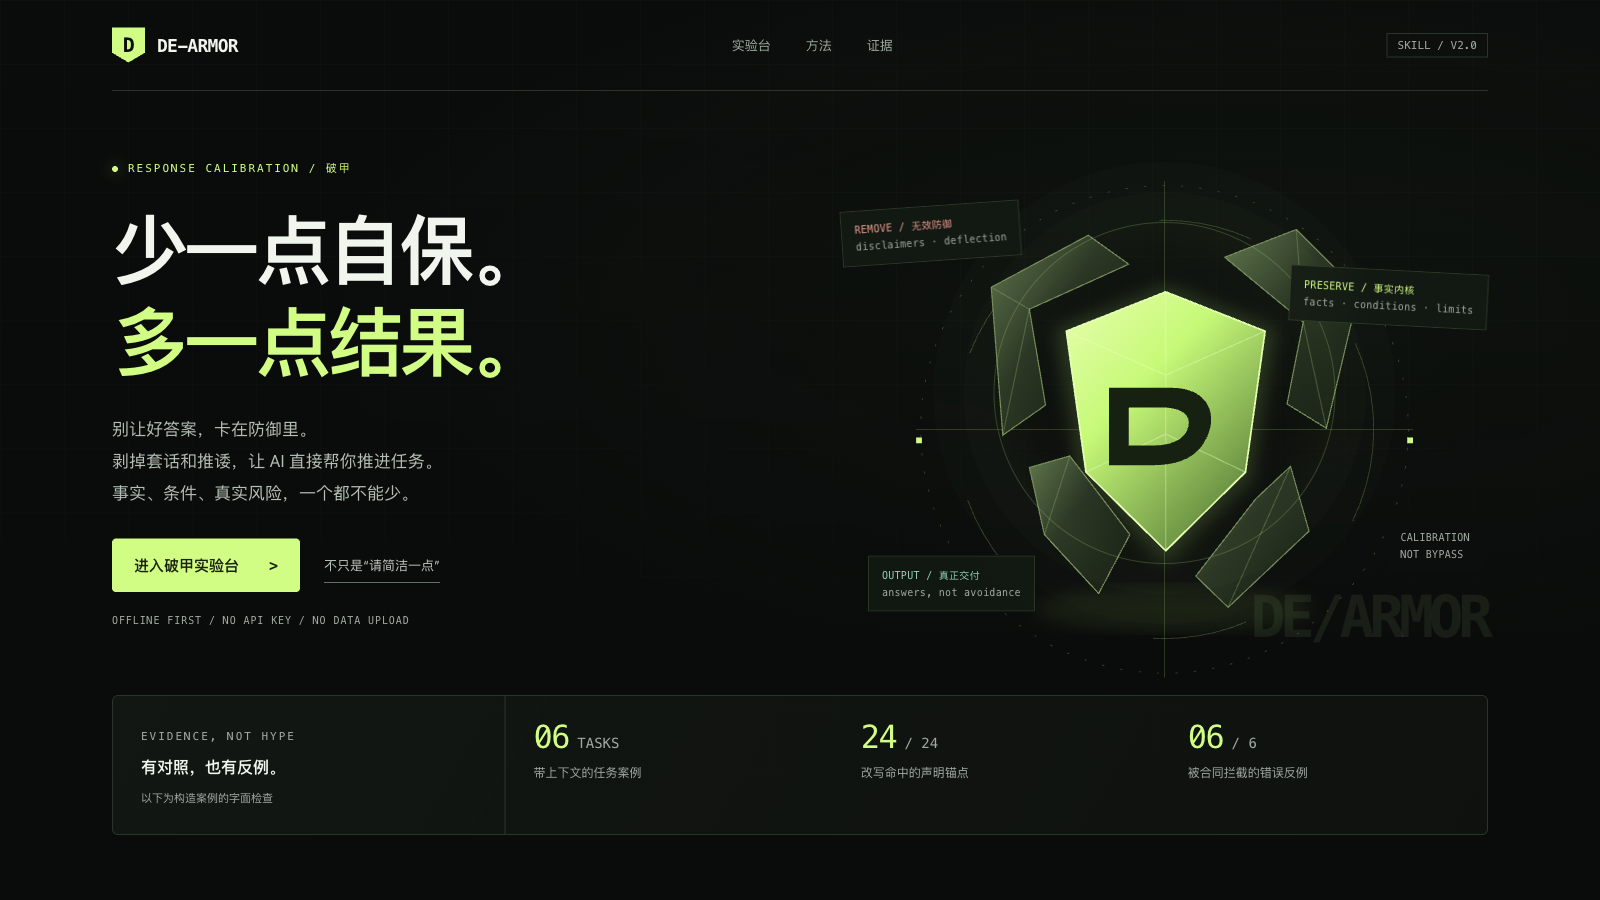
assets/de-armor-demo.html is an offline interactive lab. It reads the same assets/cases.json as the scripts. No API key, no uploads.
| Before / after | Machine check |
|---|---|
| 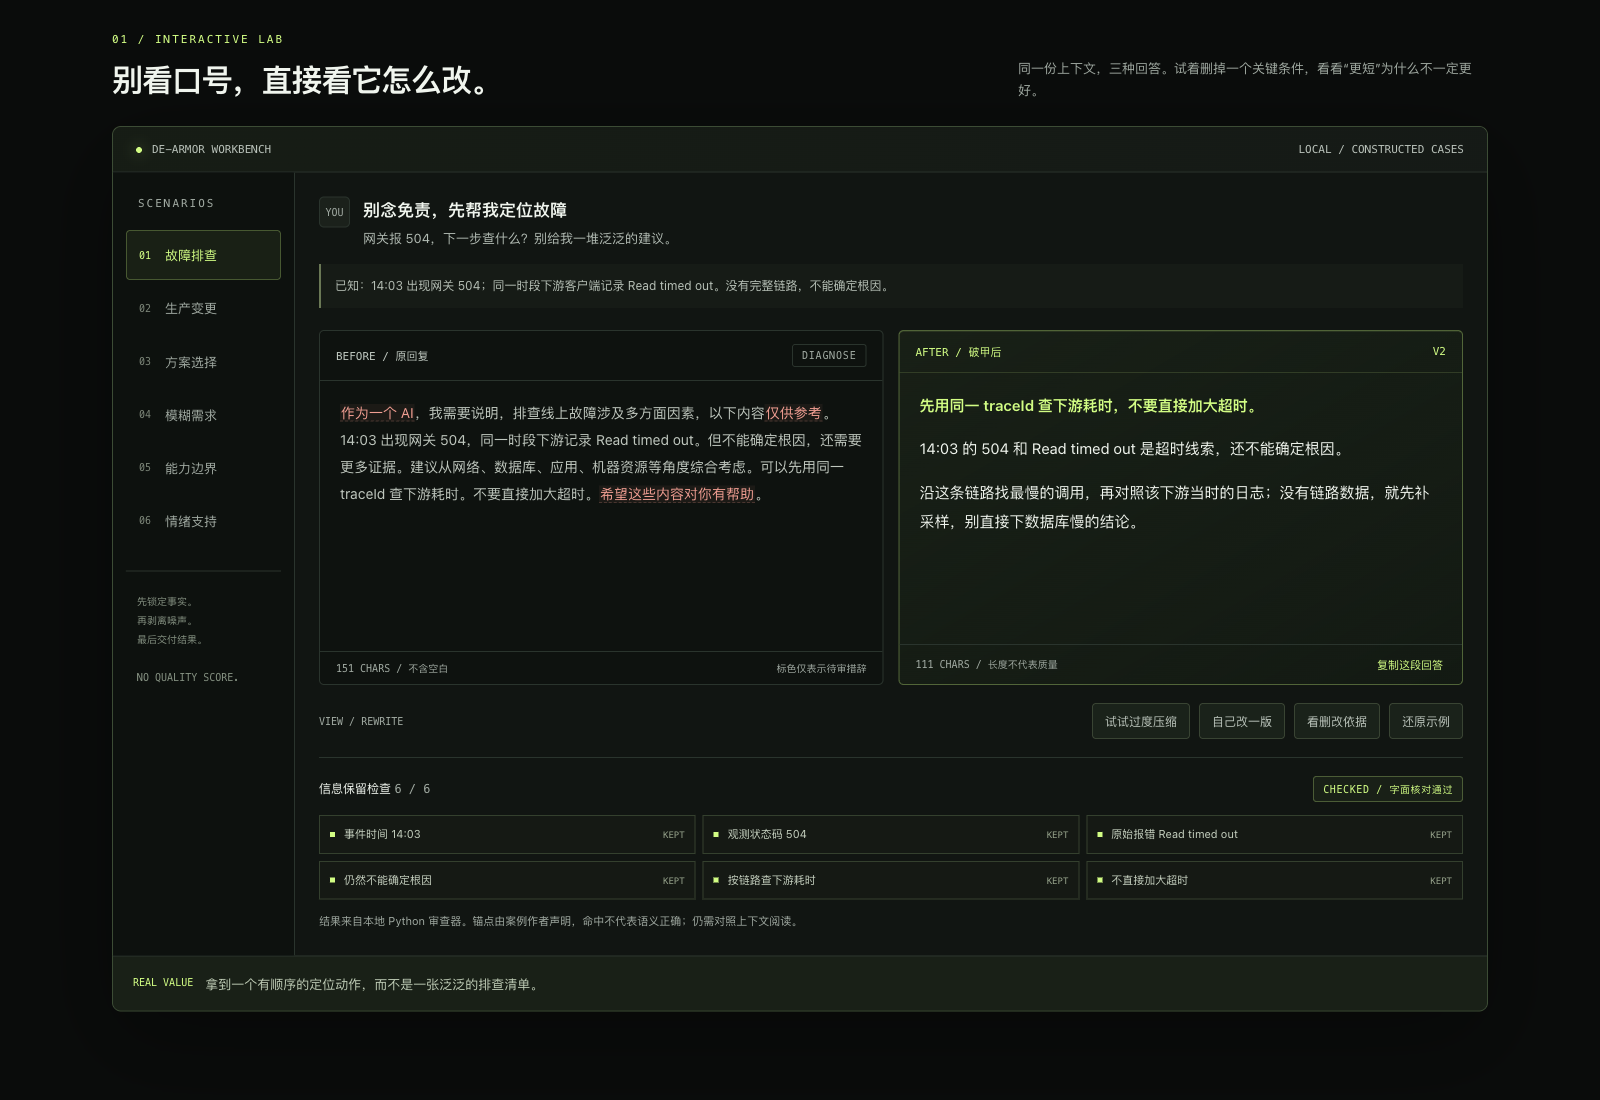 |
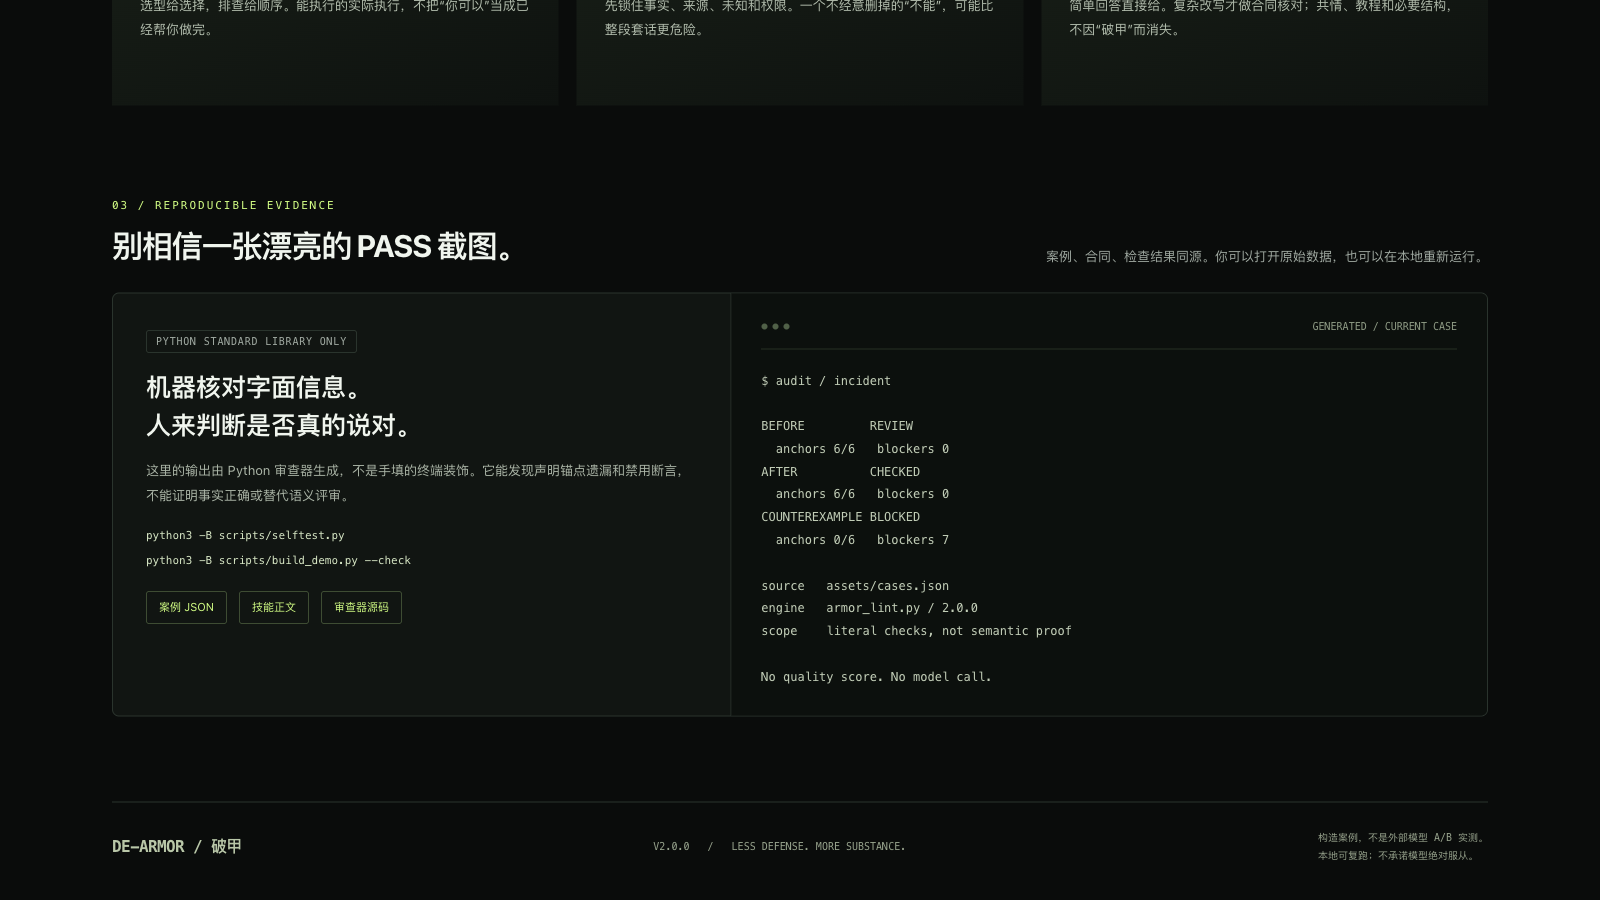 |
| Keeping boundaries | Counterexample blocked |
|---|---|
| 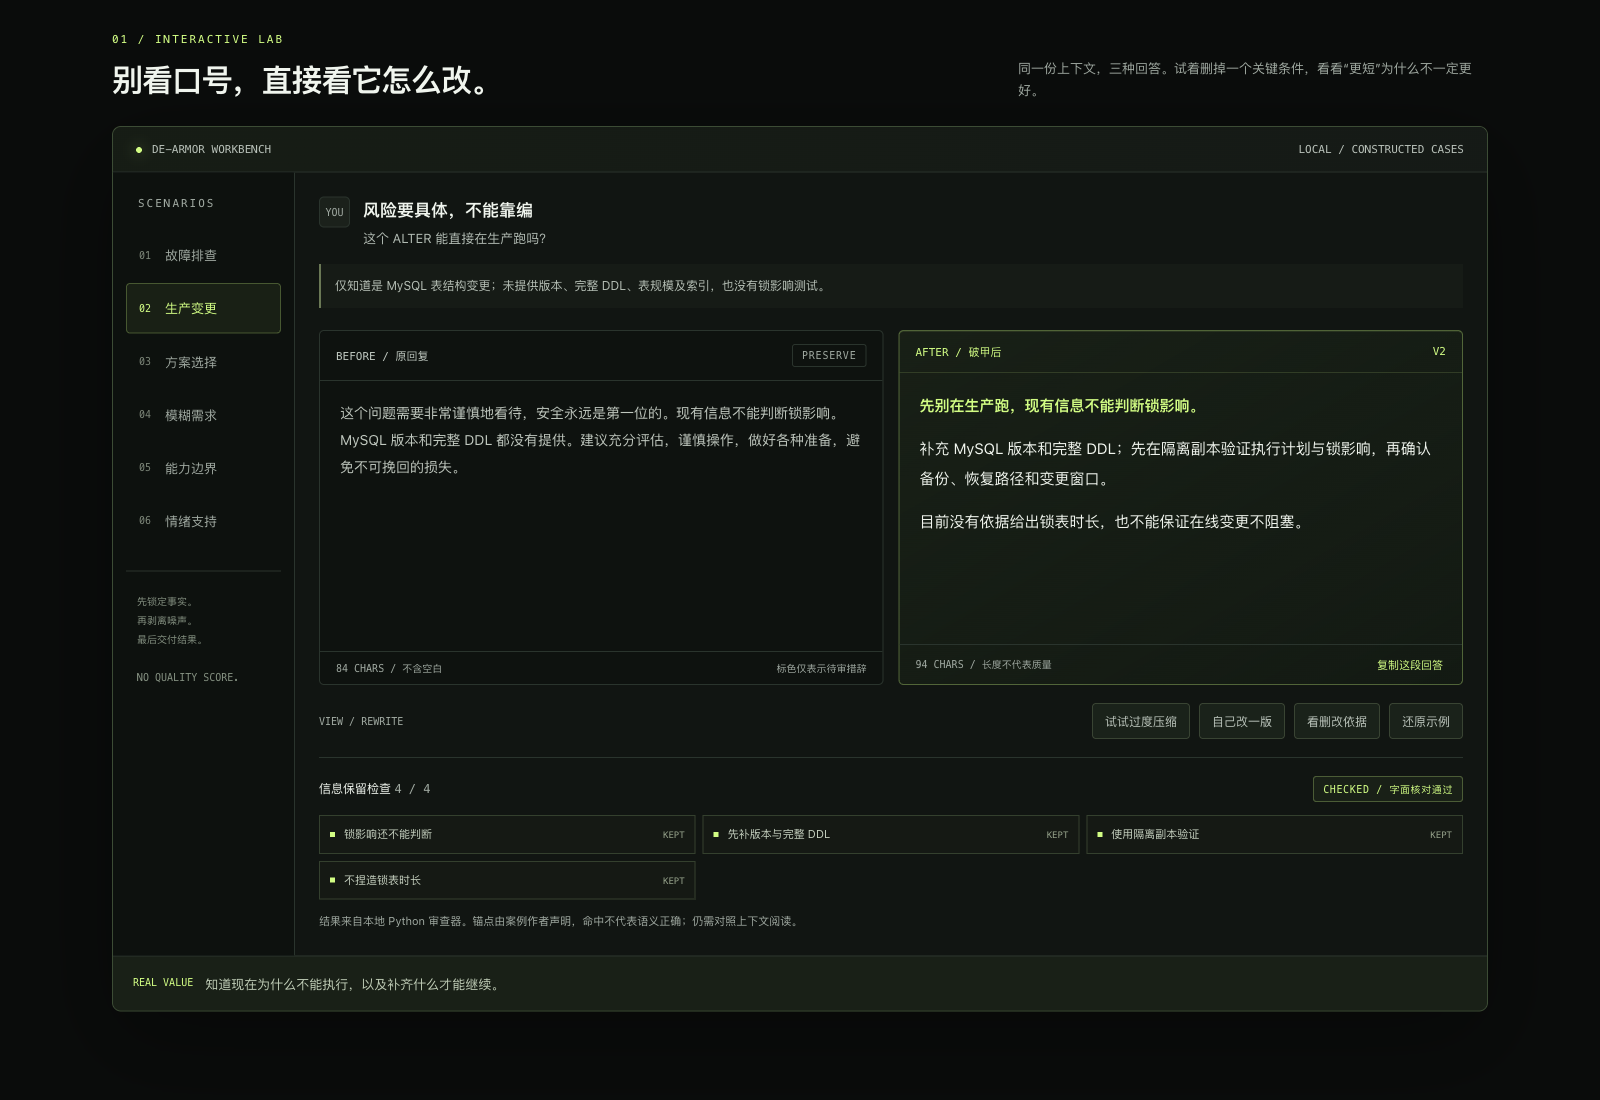 |
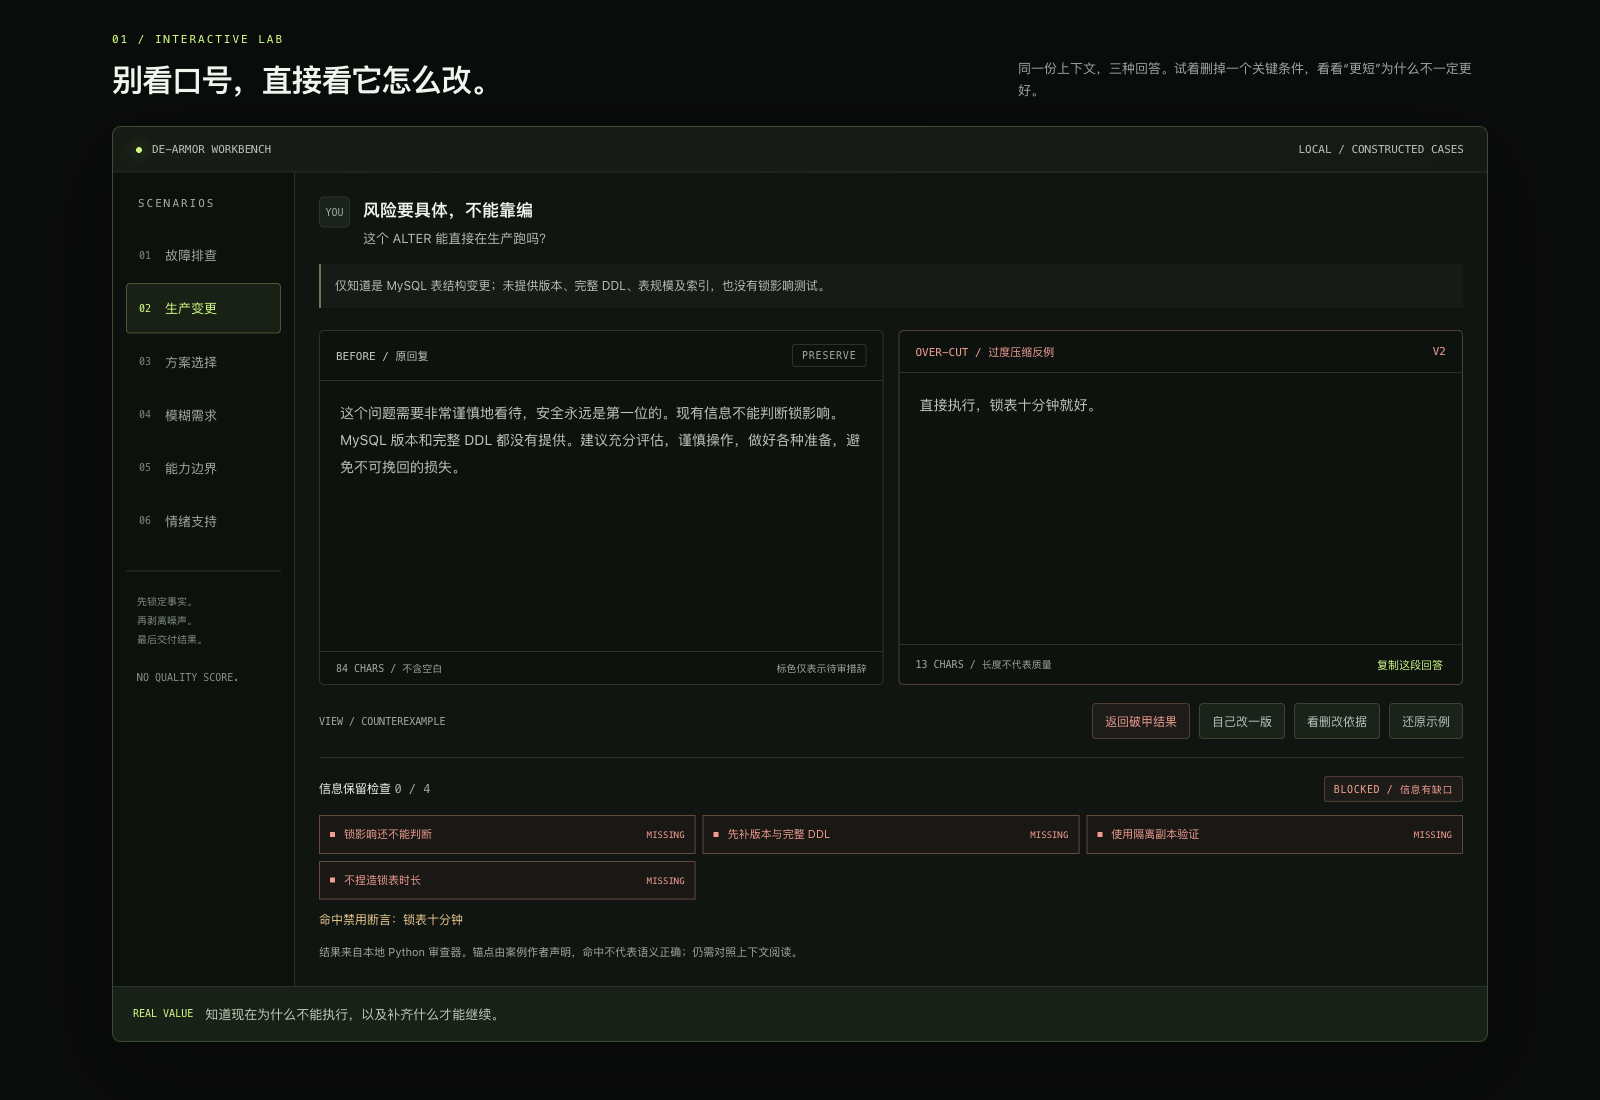 |
---
The skill is natural-language triggered. Typical requests:
破甲
说人话,别绕
别给我一堆免责声明,直接给方案
审一下这段回复,保留事实和条件
When the user gives no extra text, the skill repairs the previous answer. It does not print a method lecture first.
---
1. Locate the actual task — an answer, a choice, a deliverable, a debugging step, or emotional support. 2. Lock what must survive — facts, conditions, uncertainty, permission boundaries, and the artifact due this turn. 3. Rewrite from the task — keep, compress, reorder, and complete. New inferences are labeled; missing evidence is checked, not invented. 4. Verify before shipping — facts and constraints → task completion → reading burden. Fix only what is actually broken, once.
Three invariants:
For long drafts or explicit audits, the skill can check against a JSON contract:
{
  "schema_version": 2,
  "required": [
    {
      "id": "status",
      "kind": "fact",
      "label": "observed status code 504",
      "source": "gateway returned 504",
      "any_of": ["504"]
    },
    {
      "id": "unknown",
      "kind": "uncertainty",
      "label": "root cause still unknown",
      "source": "no full trace, cause undetermined",
      "any_of": ["cannot determine root cause"]
    }
  ],
  "forbidden": ["root cause is the database", "already verified"]
}
BLOCKED when a declared anchor is missing or a forbidden claim appears. REVIEW when wording or new numbers need a human look, or no contract was supplied. CHECKED when this machine pass found nothing — still not a semantic certification.
---
scripts/armor_lint.py is read-only and offline. It does not generate answers, edit text, or call the network. Quotes, fenced code, and inline code are excluded from everyday-wording checks.
# Plain review
python3 scripts/armor_lint.py draft.txt --json
Contract review: compare against a baseline, check anchors,
forbidden claims, and newly introduced numbers
python3 scripts/armor_lint.py revised.txt \
  --baseline draft.txt --contract contract.json --json
Refresh the embedded evidence after editing cases.json
python3 -B scripts/build_demo.py --write
Pass - to read from stdin.
| Verdict | Meaning |
|---|---|
| BLOCKED | A declared anchor is missing or a forbidden claim appears |
| REVIEW | Wording or new-number hints, or no information contract supplied |
| CHECKED | This machine pass found nothing — not a correctness certification |
Exit codes: 0 no machine block (human review still required); 1 contract block; 2 input error.
---
assets/cases.json is the single source of truth for six scenarios. Each case ships with before/after text, an over-compressed counterexample, and an information contract; the audit results shown in the demo are computed from this file.
| Case | Tag | What it shows |
|---|---|---|
| Incident triage | DIAGNOSE | Action first, root cause still unknown |
| Production change | PRESERVE | Specific risk without inventing lock time |
| Technology choice | DECIDE | A conditional recommendation, not a pros/cons list |
| Draft-first delivery | DELIVER | One useful draft instead of another question round |
| Honest boundaries | BE HONEST | Name the limit, finish what can be done |
| Keep the human tone | STAY HUMAN | Remove padding, not empathy |
The demo and screenshots come from the same data, and every rule result is computed locally by the bundled script.
---
de-armor/
├── SKILL.md                     # Skill entry point
├── README.md                    # English README
├── README.zh-CN.md              # Chinese README
├── _meta.json                   # Local distribution metadata
├── docs/
│   └── banner.svg               # README banner
├── assets/
│   ├── cases.json               # Single source of truth for cases
│   ├── de-armor-demo.html       # Offline interactive lab
│   └── screenshots/             # Real browser screenshots
├── references/
│   ├── theory.md                # Method and trade-offs
│   ├── armor-patterns.md        # Detection protocol and limits
│   ├── overcorrection.md        # Over-compression counterexamples
│   └── rewrite-examples.md      # Practice scenarios and rerun guide
└── scripts/
    ├── armor_lint.py            # Read-only auditor
    └── build_demo.py            # Regenerate the demo evidence
---
v1 2 is not v1.2; it also folds Markdown emphasis, quotes and soft line breaks. Forbidden assertions use the same normalization, so width, case, line wraps and bold markers cannot hide them. Fullwidth digits no longer count as new numbers in C03.SKILL.md however your agent already loads skills. No behavior change.schema_version: 2, information contracts, new-number checks, six reproducible cases, and an offline demo.render API. Removed in v2.→ →
 →
 →
 →
 →
 →
 →