1
 →
An open-source long-horizon SuperAgent harness that researches, codes, and creates. With the help of sandboxes, memories, tools, skill, subagents and message gateway
bytedance/deer-flow is an open-source project on GitHub, mainly written in Python. An open-source long-horizon SuperAgent harness that researches, codes, and creates. It currently holds 83,223 stars and 11,547 forks with 923 open issues, and was last pushed on 2026-09-29 (repository created 2025-05-07).
Git Homed tracks it on the AI Agent Skills Trending board and on the AI AI Agent Skills Trending list.
English | 中文 | 日本語 | Français | Русский | Português


On February 28th, 2026, DeerFlow claimed the 🏆 #1 spot on GitHub Trending following the launch of version 2. Thanks a million to our incredible community — you made this happen! 💪🔥
DeerFlow (Deep Exploration and Efficient Research Flow) is an open-source super agent harness that orchestrates sub-agents, memory, and sandboxes to do almost anything — powered by extensible skills.
https://github.com/user-attachments/assets/a8bcadc4-e040-4cf2-8fda-dd768b999c18
[!NOTE]
DeerFlow 2.0 is a ground-up rewrite. It shares no code with v1. If you're looking for the original Deep Research framework, it's maintained on the 1.x branch — contributions there are still welcome. Active development has moved to 2.0.
Learn more and see real demos on our official website. The landing-page case studies open as allowlisted, read-only showcases without requiring a sign-in.
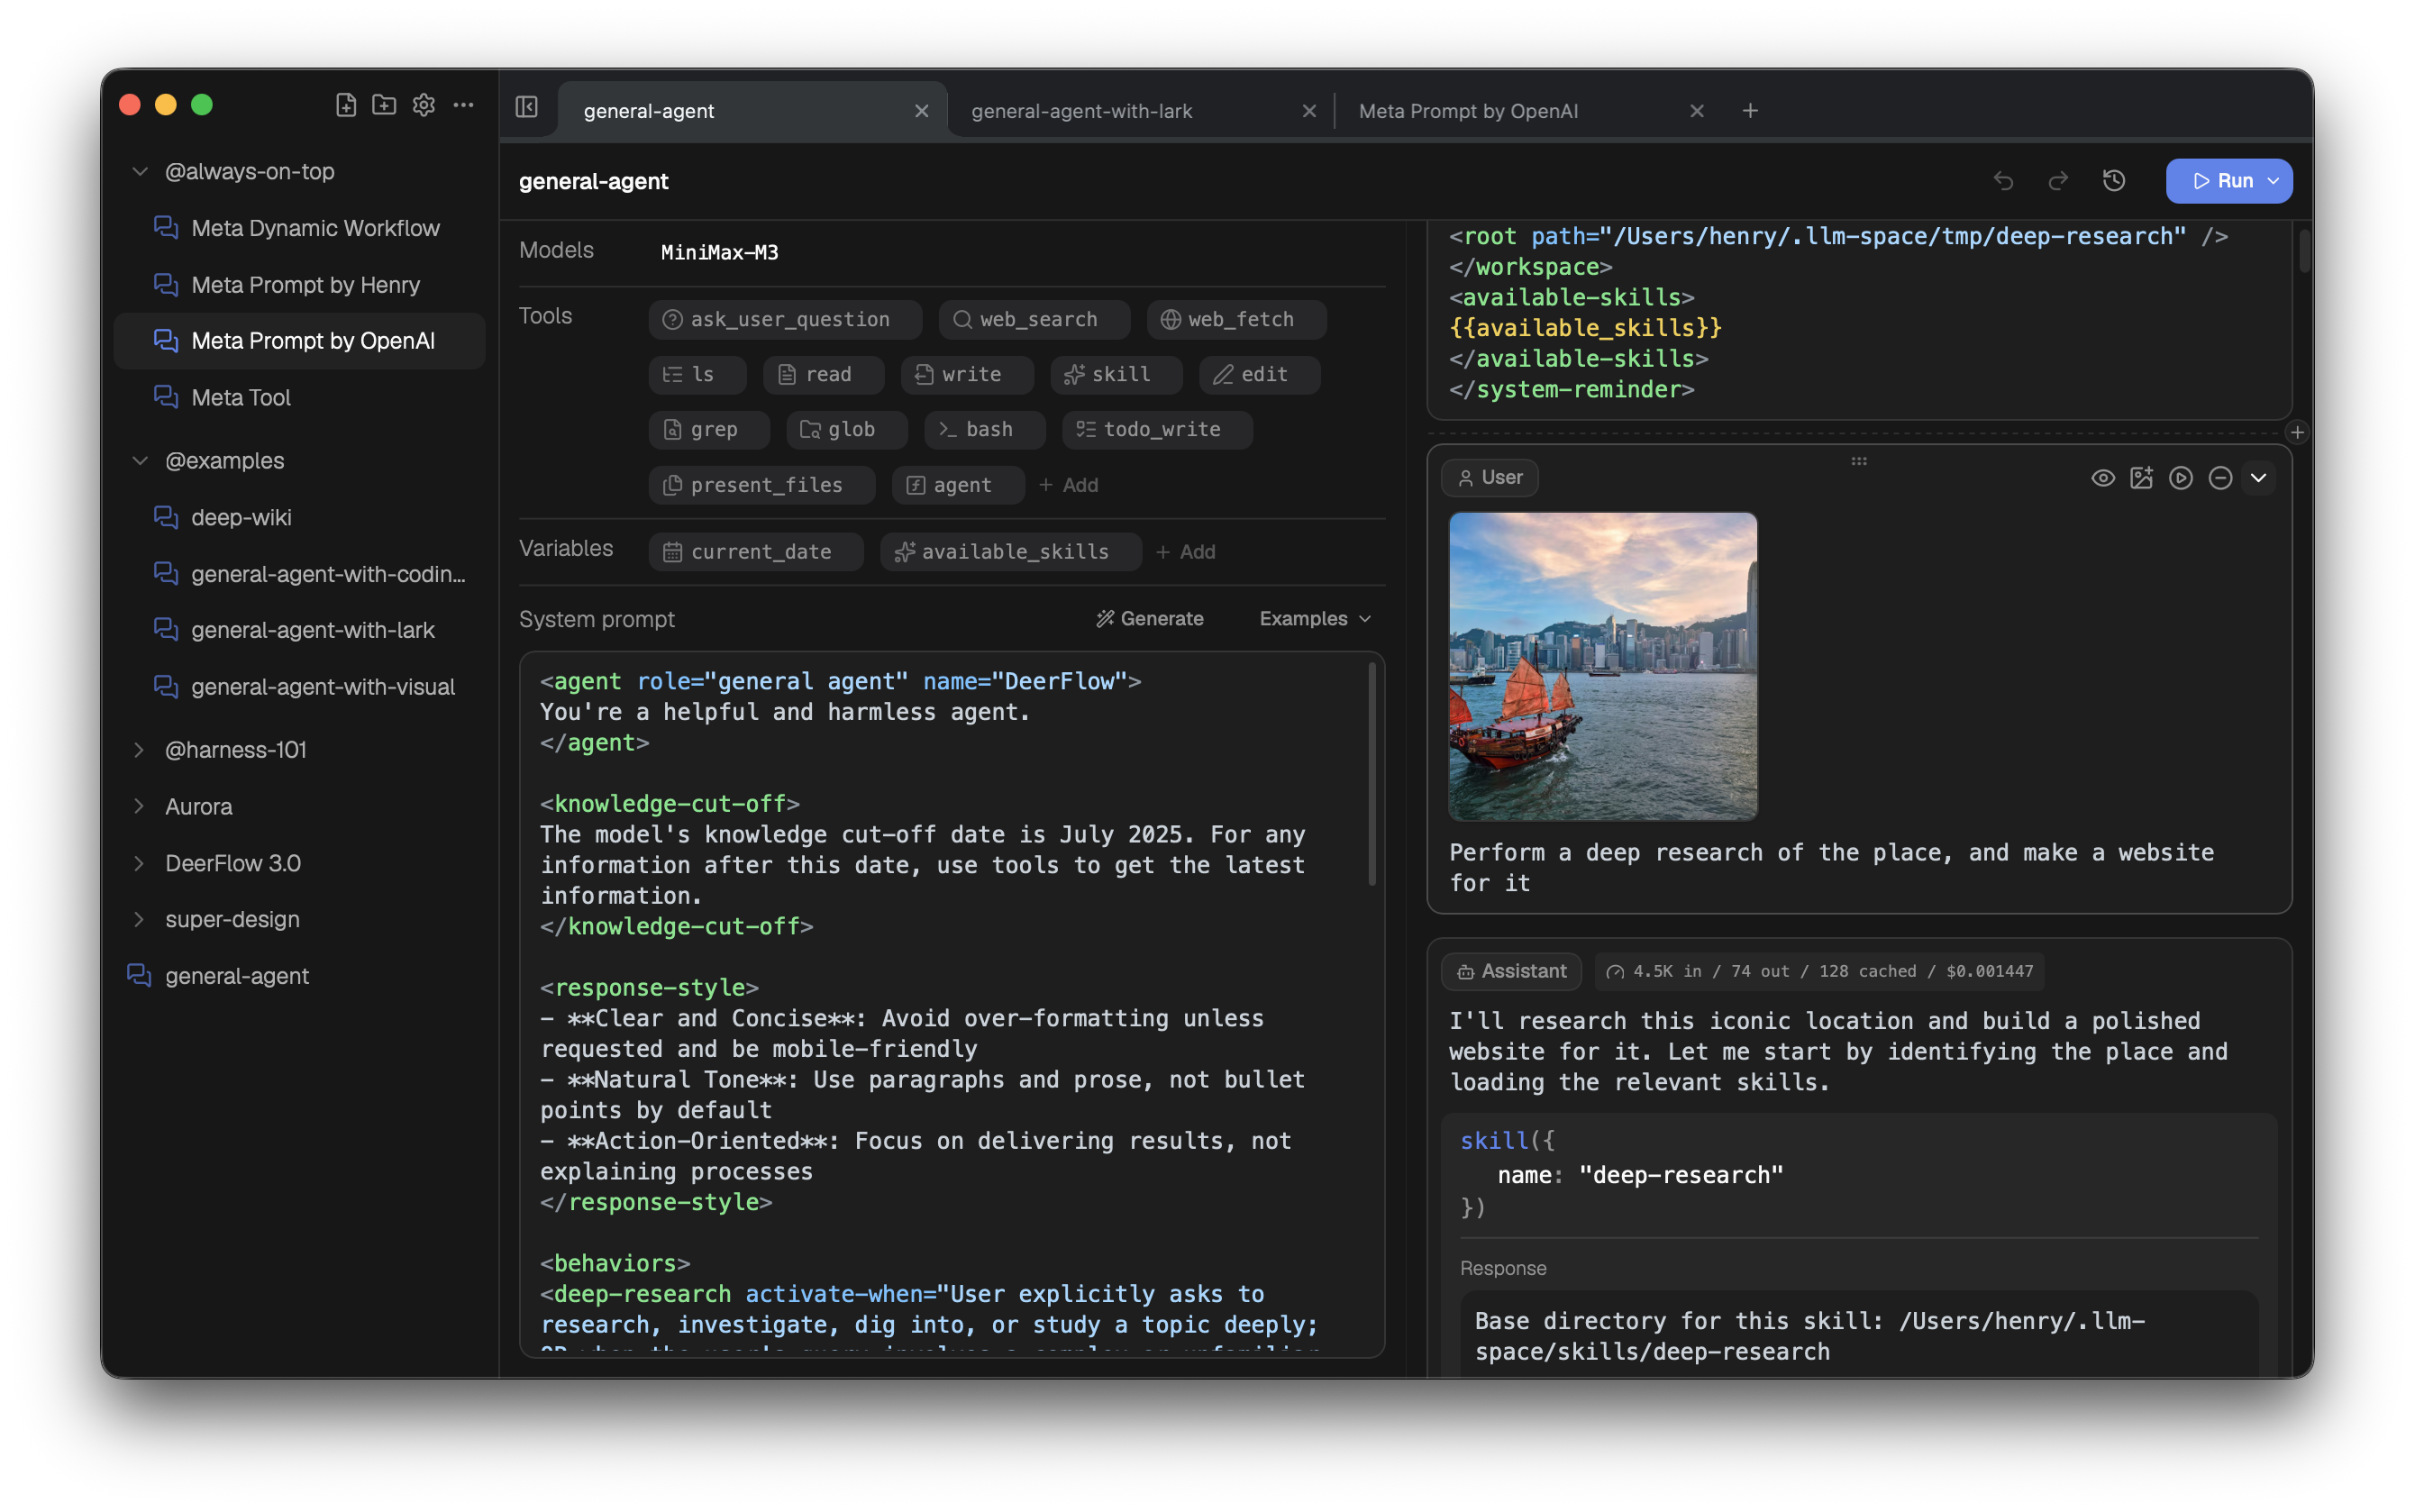
InfoQuest reader, web search, and image search use a 30-second HTTP connect/read
inactivity timeout. The crawl timeout and navigation_timeout settings remain
separate server-side options; they do not control the local HTTP timeout.
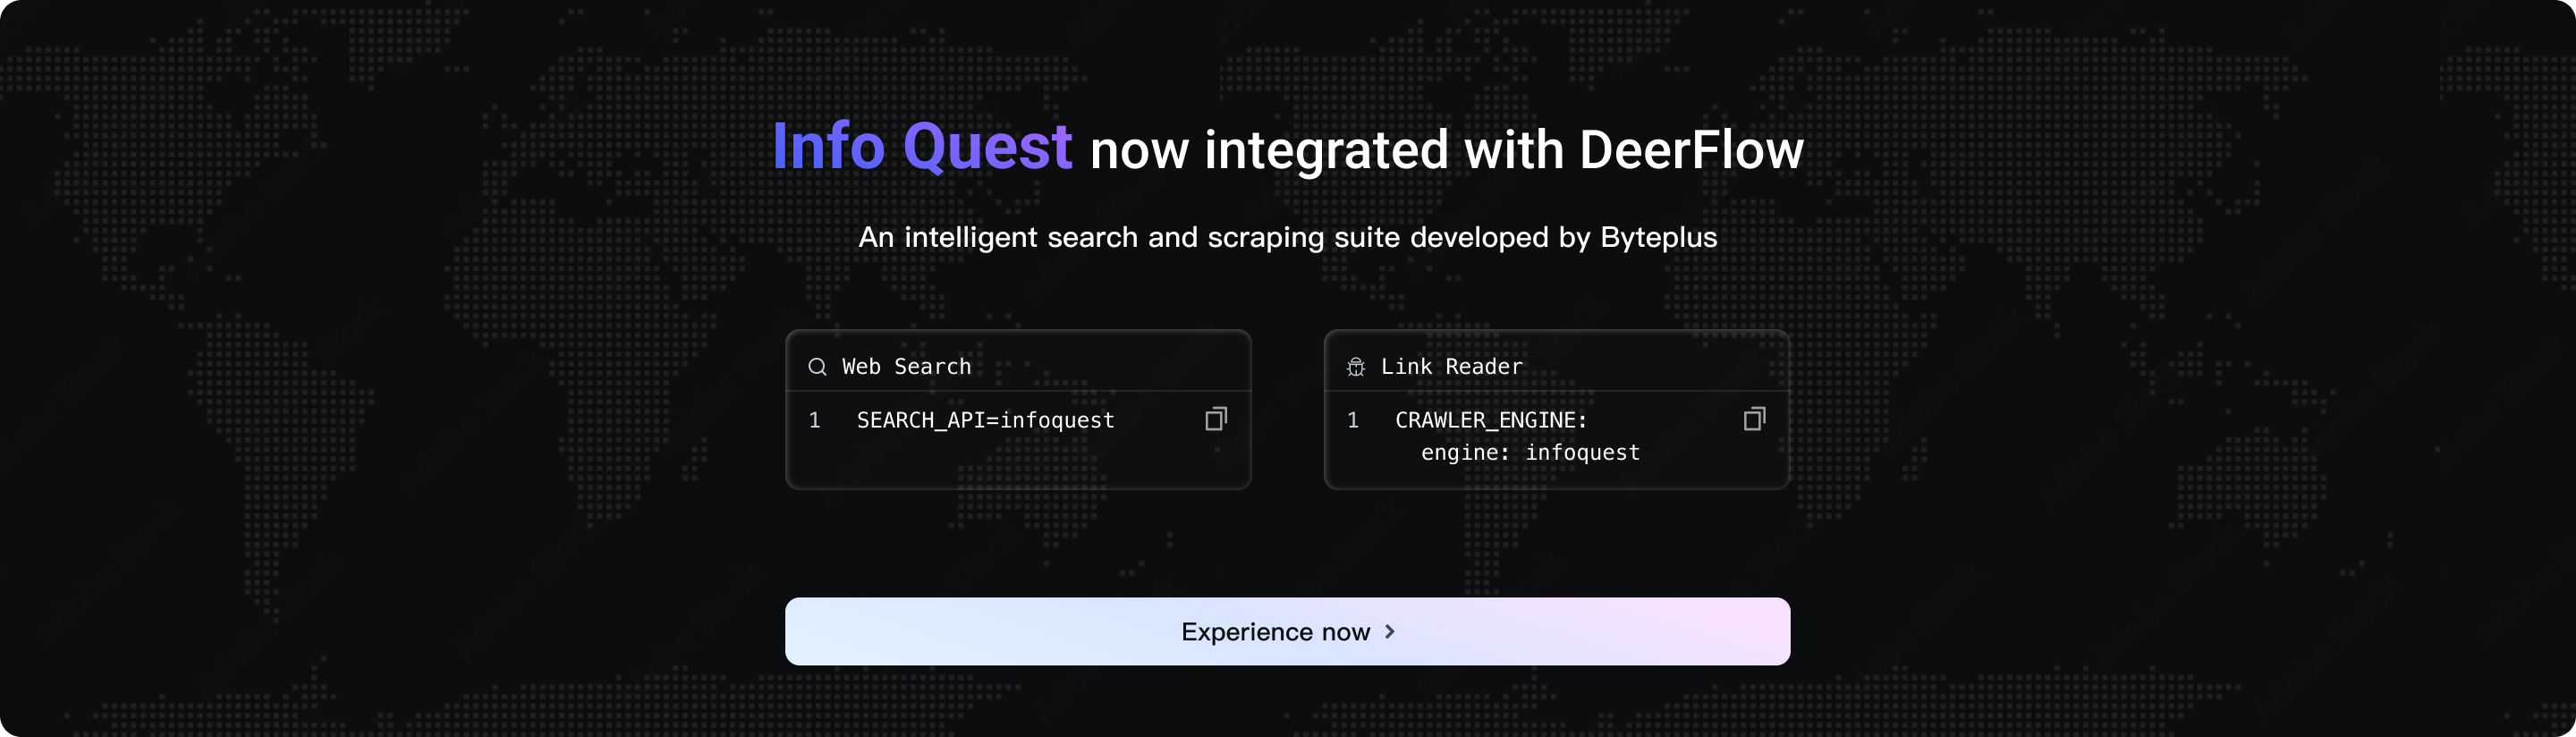
DeerFlow has newly integrated the intelligent search and crawling toolset independently developed by BytePlus — InfoQuest (supports free online experience)
---
If you use Claude Code, Codex, Cursor, Windsurf, or another coding agent, you can hand it the setup instructions in one sentence:
Help me clone DeerFlow if needed, then bootstrap it for local development by following https://raw.githubusercontent.com/bytedance/deer-flow/main/Install.md
That prompt is intended for coding agents. It tells the agent to clone the repo if needed, choose Docker when available, and stop with the exact next command plus any missing config the user still needs to provide.
Operators can extend lead-agent, subagent, and DeerMem extraction prompts with literal prepend/append configuration without editing source templates. See prompt overlays.
Optional per-model request_admission
paces requests to help stay within provider request-per-minute limits.
It is disabled by default; see the linked guide to enable it.
For Google's official Gemini OpenAI-compatible endpoint, use the Gemini reasoning profile.
1. Clone the DeerFlow repository
   git clone https://github.com/bytedance/deer-flow.git
   cd deer-flow
2. Run the setup wizard
From the project root directory (deer-flow/), run:
make setup
This launches an interactive wizard that guides you through choosing an LLM provider, optional web search, and execution/safety preferences such as sandbox mode, bash access, and file-write tools. It generates a minimal config.yaml and writes your keys to .env. Takes about 2 minutes.
The wizard also lets you configure an optional web search provider, or skip it for now.
Jina, Browserless, and InfoQuest web fetches resolve relative links and image sources using the requested page URL (or a usable HTML base URL), so returned Markdown includes complete destinations. Link resolution preserves the surrounding HTML source, including malformed-page formatting.
Jina fetches support opt-in bounded retries via max_retries (default 0) and retry_budget_seconds (default 30) in the tool configuration. Valid Retry-After hints set a minimum wait for HTTP 429/503; 429 without a valid hint stays terminal. Hints that cannot fit the remaining budget stop retries. Local backoff remains randomized. Retries may increase upstream requests and cost; see Jina fetch retries.
Run make doctor at any time to verify your setup and get actionable fix hints.
If you are opening a GitHub issue about a local setup or runtime problem, run
make support-bundle. The command prints reporter next steps, writes a
-issue-summary.md file to paste into the issue, a -issue-draft.md file
for AI-assisted issue filing, and an optional evidence zip under
.deer-flow/support-bundles/. If an AI assistant files the issue, start from
the draft and replace every REQUIRED placeholder instead of inventing missing
facts. Attach the zip only if a maintainer asks for it, or if the summary
alone is not enough. Maintainers and AI triage tools can start with
triage.json; the bundle includes redacted diagnostics and file manifests
only, and does not include .env, raw conversation messages, or user file
contents.
> Advanced / manual configuration: If you prefer to edit config.yaml directly, run make config instead to copy the full template. Optional dependency auto-detection accepts UTF-8 configuration files with or without a byte-order mark (BOM). See config.example.yaml for the complete reference including CLI-backed providers (Codex CLI, Claude Code OAuth), OpenRouter, Responses API, subagent runtime caps such as subagents.max_total_per_run, and more.
Optional per-model pricing must use one currency across all priced models. DeerFlow disables Console cost estimates when currencies are mixed rather than presenting an invalid aggregate.
Administrators can also open Settings → Models to add, edit, test, and
enable/disable shared OpenAI-compatible Chat Completions models without editing
config.yaml. Enter a unique name, base URL, model ID, and optional API key;
saving refreshes the chat model list. Connection testing sends a short streaming
tool-call request and may incur provider charges. It does not save the draft or
verify image support; set image support and token limits from provider documentation.
Official DeepSeek models at https://api.deepseek.com or
https://api.deepseek.com/v1 (default HTTPS port) automatically use DeerFlow's
DeepSeek adapter, preserving reasoning content across tool calls and honoring
output token limits. Chat uses the selected thinking mode; the connection test
temporarily disables thinking because DeepSeek rejects forced tool selection
in thinking mode. The test checks streaming tool connectivity, not every agent
workflow or thinking-mode behavior. Existing saved DeepSeek profiles receive
this adapter without re-entering credentials. DeepSeek-specific settings for
third-party proxies, other native adapters, and advanced reasoning settings
remain YAML-configured.
DeepSeek regression tests run offline with the normal backend suite. To verify
the real provider explicitly, set DEEPSEEK_TEST_API_KEY in your environment
and run from backend/:
DEER_FLOW_RUN_LIVE_TESTS=1 uv run --no-sync pytest tests/test_managed_deepseek_live.py -q
These opt-in tests send short requests to DeepSeek and may incur charges;
they use temporary state, never save credentials to the deployment catalog,
and are skipped in CI. DEEPSEEK_TEST_MODEL optionally selects a different
DeepSeek model ID (default: deepseek-flash). The same tests can be run on
unfixed and fixed revisions; success is always the expected result.
YAML models remain read-only in this page and take precedence on name conflicts. Managed models are appended after YAML models; edits apply to new configuration snapshots, while active runs retain their existing snapshot. Disabling a model removes it from future selection/resolution, so update any custom-agent or scheduled task definitions that explicitly reference it before disabling it. Managed models are shared by the deployment, not personal API-key profiles, and remain subject to the existing model authorization policy.
The encrypted catalog and a generated local encryption key are stored in
$DEER_FLOW_HOME/managed-models/ (default .deer-flow/managed-models/). Persist
and back up the whole directory, restrict filesystem access, and share it
across Gateway workers/replicas that should use the same catalog. The local key
is protected by filesystem permissions; encryption does not protect against
someone who can read both files. Losing the key requires restoring the backup.
Reads and writes fail if the catalog cannot be decrypted, rather than replacing it.
This storage is independent of the SQL backend and works with read-only YAML mounts.
When several models are configured, open either model picker and use the star beside a model to favorite it. Favorites appear first in both the main chat and Side Chat pickers without changing either chat's selected or default model. They are stored for the signed-in user in the current browser, so they do not sync to another browser or device and do not require a startup setting. The compact favorites picker intentionally omits search and only adds favorite ordering to the two-line model list.
models:
- name: gpt-4o
display_name: GPT-4o
use: langchain_openai:ChatOpenAI
model: gpt-4o
api_key: $OPENAI_API_KEY
- name: openrouter-gemini-2.5-flash
display_name: Gemini 2.5 Flash (OpenRouter)
use: langchain_openai:ChatOpenAI
model: google/gemini-2.5-flash-preview
api_key: $OPENROUTER_API_KEY
base_url: https://openrouter.ai/api/v1
- name: gpt-5-responses
display_name: GPT-5 (Responses API)
use: langchain_openai:ChatOpenAI
model: gpt-5
api_key: $OPENAI_API_KEY
use_responses_api: true
output_version: responses/v1
- name: qwen3-32b-vllm
display_name: Qwen3 32B (vLLM)
use: deerflow.models.vllm_provider:VllmChatModel
model: Qwen/Qwen3-32B
api_key: $VLLM_API_KEY
base_url: http://localhost:8000/v1
supports_thinking: true
when_thinking_enabled:
extra_body:
chat_template_kwargs:
enable_thinking: true
OpenRouter and similar OpenAI-compatible gateways should be configured with langchain_openai:ChatOpenAI plus base_url. If you prefer a provider-specific environment variable name, point api_key at that variable explicitly (for example api_key: $OPENROUTER_API_KEY).
To route OpenAI models through /v1/responses, keep using langchain_openai:ChatOpenAI and set use_responses_api: true with output_version: responses/v1.
Models whose provider contract differs from DeerFlow's generic thinking/effort assumptions can declare a per-model mapping-valued reasoning: block (thinking unsupported/optional/required, the accepted effort values with aliases and a default, the payload dialect, and the reasoning-history requirement). The setup wizard's Z.AI GLM-5.3-Flash profile uses it: thinking stays on for every foreground and background call, and the effort selector offers the model's own low/high/max levels. Ollama's existing boolean reasoning: true remains a native provider setting and is forwarded to ChatOllama. When migrating a profile to a custom effort path, remove any old reasoning_effort setting from the profile and thinking templates; configuration validation rejects the leftover key. The chat UI drops a remembered provider-specific effort when switching to a legacy model that does not advertise it. Profiles without the block keep their existing provider behavior. See config.example.yaml for the shape and the equivalent manual configuration.
For vLLM 0.19.0, use deerflow.models.vllm_provider:VllmChatModel. For Qwen-style reasoning models, DeerFlow toggles reasoning with extra_body.chat_template_kwargs.enable_thinking and preserves vLLM's non-standard reasoning field across multi-turn tool-call conversations. Legacy thinking configs are normalized automatically for backward compatibility. If the endpoint reports a cumulative usage snapshot on every streaming chunk, set cumulative_stream_usage: true so DeerFlow converts those snapshots into per-chunk deltas; the option is disabled by default and leaves usage unchanged when a stable completion id is unavailable. Reasoning models may also require the server to be started with --reasoning-parser .... If your local vLLM deployment accepts any non-empty API key, you can still set VLLM_API_KEY to a placeholder value.
When prompt caching is enabled for a model configured with
deerflow.models.claude_provider:ClaudeChatModel, DeerFlow preserves thinking
and redacted-thinking history without placing cache breakpoints directly on
those blocks. Extended-thinking tool follow-ups can keep using prompt caching.
CLI-backed provider examples:
models:
- name: gpt-5.4
display_name: GPT-5.4 (Codex CLI)
use: deerflow.models.openai_codex_provider:CodexChatModel
model: gpt-5.4
supports_thinking: true
supports_reasoning_effort: true
- name: claude-sonnet-4.6
display_name: Claude Sonnet 4.6 (Claude Code OAuth)
use: deerflow.models.claude_provider:ClaudeChatModel
model: claude-sonnet-4-6
max_tokens: 4096
supports_thinking: true
~/.codex/auth.jsonstrict: true or strict: false in wrapped or flat dictionary definitions. Missing or null settings keep the provider default. bind_tools applies the same conversion to dictionaries and BaseTool schemas.CLAUDE_CODE_OAUTH_TOKEN, ANTHROPIC_AUTH_TOKEN, CLAUDE_CODE_CREDENTIALS_PATH, or ~/.claude/.credentials.jsonCLAUDE_CODE_OAUTH_TOKEN_FILE_DESCRIPTOR accepts a UTF-8 token handoff and reuses it for later model instances in the same process. Undecodable handoffs are skipped so Claude Code can still try its override or default credentials file.make doctor accepts the same files when checking CLI authentication. Invalid text encoding is treated as an unreadable source; Claude Code can still try its default file after an invalid override.acp_agents.codex, point it at a Codex ACP adapter such as npx -y @zed-industries/codex-acptimeout_seconds (default: 1800) is one shared budget for initialization, session creation, and the prompt, starting after the subprocess launches. On timeout, DeerFlow aborts the invocation and closes the subprocess before returning an error. Workspace/MCP preparation and subprocess cleanup are outside this budget. A TimeoutError raised by the SDK before this deadline expires retains its own error message. npm install --global @minimax-ai/code
mcode login
   acp_agents:
     mcode:
       command: mcode
       args: ["acp"]
       description: MiniMax Code for implementation, refactoring, debugging, and repository tasks
       auto_approve_permissions: false
mcode must be on the Gateway process's PATH; installing it only on the Docker host does not make it available inside the Gateway container. DeerFlow invokes it through invoke_acp_agent in a per-thread ACP workspace and forwards enabled MCP servers. Keep auto_approve_permissions: false for untrusted tasks; enable it only when mcode must edit files or run commands and you trust the task.
eval "$(python3 scripts/export_claude_code_oauth.py --print-export)"
The exporter rejects malformed credential containers and non-string or blank access tokens before printing a token, emitting a shell export, or writing a credentials file. Valid tokens are exported unchanged, and file exports preserve the full credential container.
API keys can also be set manually in .env (recommended) or exported in your shell:
   OPENAI_API_KEY=your-openai-api-key
   TAVILY_API_KEY=your-tavily-api-key
For an explicit backend dotenv file, export DEER_FLOW_ENV_FILE before startup,
alongside DEER_FLOW_CONFIG_PATH if needed. For example, from backend/:
DEER_FLOW_ENV_FILE=/srv/deer-flow/stage.env DEER_FLOW_CONFIG_PATH=/srv/deer-flow/stage.yaml make gateway
Relative dotenv paths use the backend process working directory; absolute paths
work regardless of that directory. Existing process variables win. An unset
selector preserves default dotenv discovery; a specified empty, missing,
non-file or unreadable path fails startup. Explicit selection also fails when
PYTHON_DOTENV_DISABLED disables dotenv loading. Restart after changing the file.
This selects backend dotenv input only: shell launchers, Docker Compose and the
frontend retain their own environment loading. Values they already export win.
It does not select ENV profiles or isolate databases, storage or tenants.
See backend dotenv selection.
Use the table below as a practical starting point when choosing how to run DeerFlow:
| Deployment target | Starting point | Recommended | Notes |
|---------|-----------|------------|-------|
| Local evaluation / make dev | 4 vCPU, 8 GB RAM, 20 GB free SSD | 8 vCPU, 16 GB RAM | Good for one developer or one light session with hosted model APIs. 2 vCPU / 4 GB is usually not enough. |
| Docker development / make docker-start | 4 vCPU, 8 GB RAM, 25 GB free SSD | 8 vCPU, 16 GB RAM | Image builds, bind mounts, and sandbox containers need more headroom than pure local dev. |
| Long-running server / make up | 8 vCPU, 16 GB RAM, 40 GB free SSD | 16 vCPU, 32 GB RAM | Preferred fo
→ →
 →
 →
 →
 →
 →
 →