1
 →
Local-first code intelligence graph for MCP and CLI. Builds a persistent map of your codebase so AI coding tools read only what matters, with benchmarked context reductions on reviews and large-repo workflows.

Stop burning tokens. Start reviewing smarter.
English | 简体中文 | 日本語 | 한국어 | हिन्दी




Usage · Commands · FAQ · Troubleshooting · GitHub Action · Reproducing the benchmarks · Roadmap
AI coding tools can end up re-reading large parts of your codebase on review tasks. code-review-graph fixes that. It builds a structural map of your code with Tree-sitter, tracks changes incrementally, and gives your AI assistant precise context via MCP so it reads only what matters.
---
pip install code-review-graph                     # or: pipx install code-review-graph
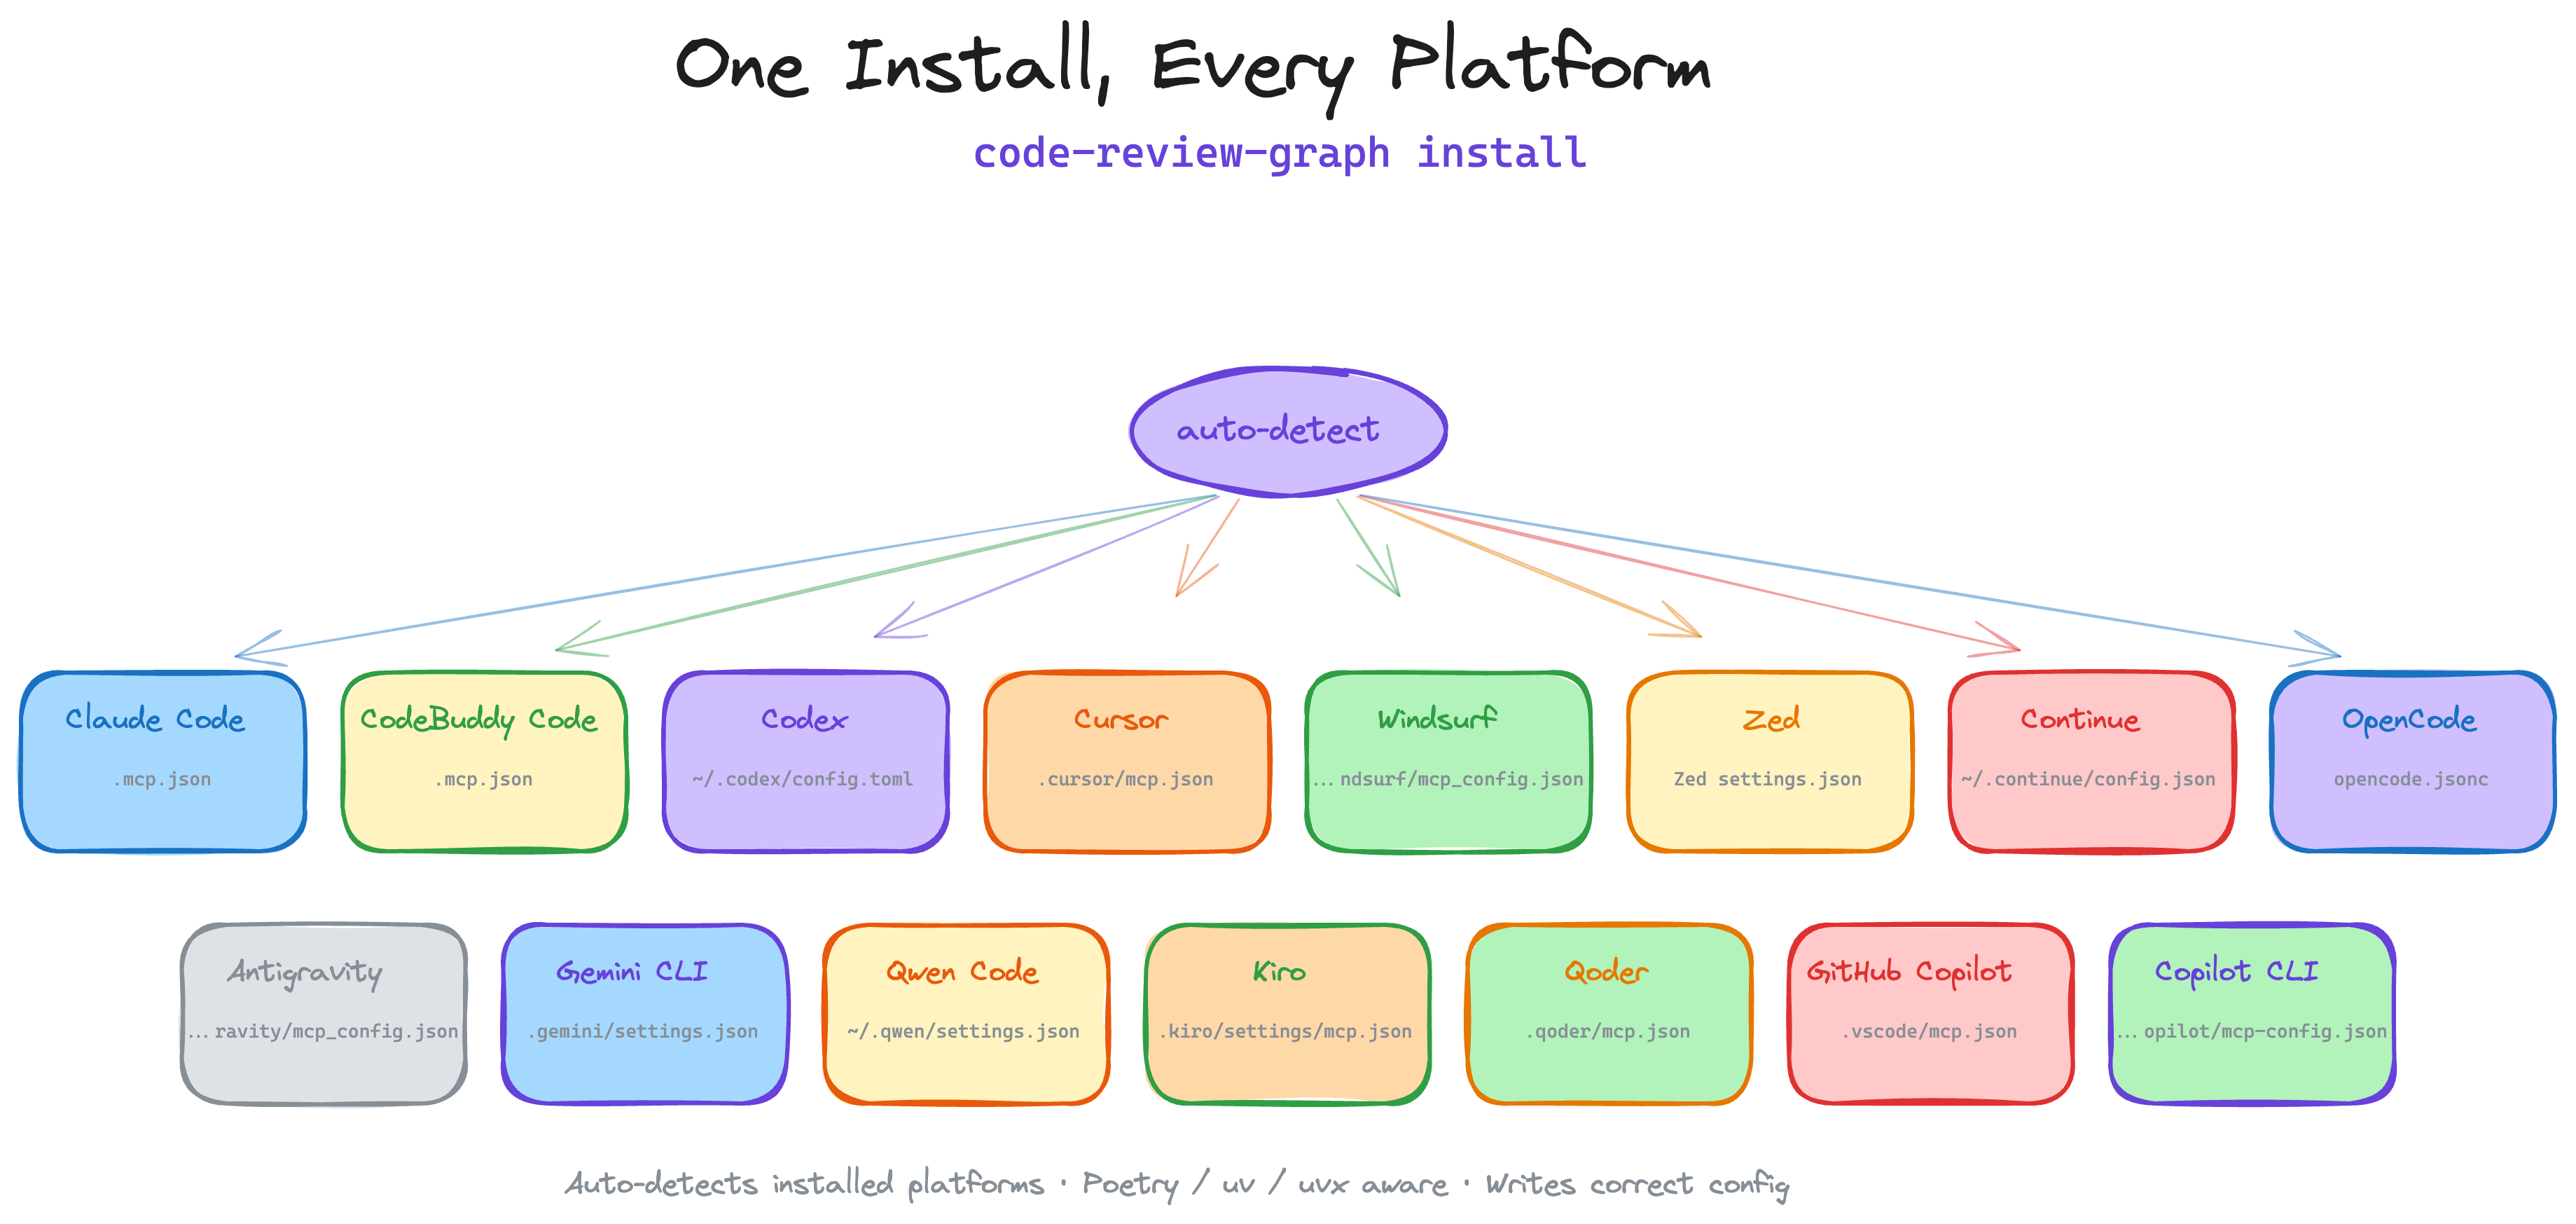
code-review-graph install          # auto-detects and configures all supported platforms
code-review-graph build            # parse your codebase
One command sets up everything. install detects which AI coding tools you have, writes the correct MCP configuration for each one, installs platform-native hooks/skills where supported, and injects graph-aware instructions into your platform rules. It auto-detects whether you installed via uvx or pip/pipx and generates the right config. Restart your editor/tool after installing.
To target a specific platform:
code-review-graph install --platform codex       # configure only Codex
code-review-graph install --platform cursor      # configure only Cursor
code-review-graph install --platform claude-code  # configure only Claude Code
code-review-graph install --platform gemini-cli   # configure only Gemini CLI
code-review-graph install --platform antigravity   # configure only Antigravity
code-review-graph install --platform windsurf     # configure only Windsurf
code-review-graph install --platform zed          # configure only Zed
code-review-graph install --platform continue     # configure only Continue
code-review-graph install --platform opencode     # configure only OpenCode
code-review-graph install --platform qwen         # configure only Qwen
code-review-graph install --platform qoder        # configure only Qoder
code-review-graph install --platform kiro         # configure only Kiro
code-review-graph install --platform copilot      # configure only GitHub Copilot (VS Code)
code-review-graph install --platform copilot-cli  # configure only GitHub Copilot CLI
code-review-graph install --platform codebuddy    # configure only CodeBuddy Code
code-review-graph install --platform hermes       # configure only Hermes Agent
Requires Python 3.10+. For the best experience, install uv (the MCP config will use uvx if available, otherwise falls back to the code-review-graph command directly).
To remove CRG from a Git or SVN project, use the symmetric uninstall command from anywhere inside its working tree. The target is normalized to the working tree root, and non-repository directories are refused. It removes only CRG-owned files and entries; unrelated MCP servers, hooks, skills, and JSONC comments remain untouched. Shared configuration changes use atomic replacement so a failed write leaves the original file intact.
code-review-graph uninstall --dry-run    # preview every action; write nothing
code-review-graph uninstall              # preview, ask for confirmation, then apply
code-review-graph uninstall --yes        # apply without prompting
code-review-graph uninstall --all-repos  # also clean every registered repository
code-review-graph uninstall --keep-data  # remove integrations but keep graph databases
code-review-graph uninstall --keep-user-configs --repo .  # clean this project only
Then open your project and ask your AI assistant:
Build the code review graph for this project
The initial build takes ~10 seconds for a 500-file project. After that, watch mode and supported hooks can keep the graph updated automatically.
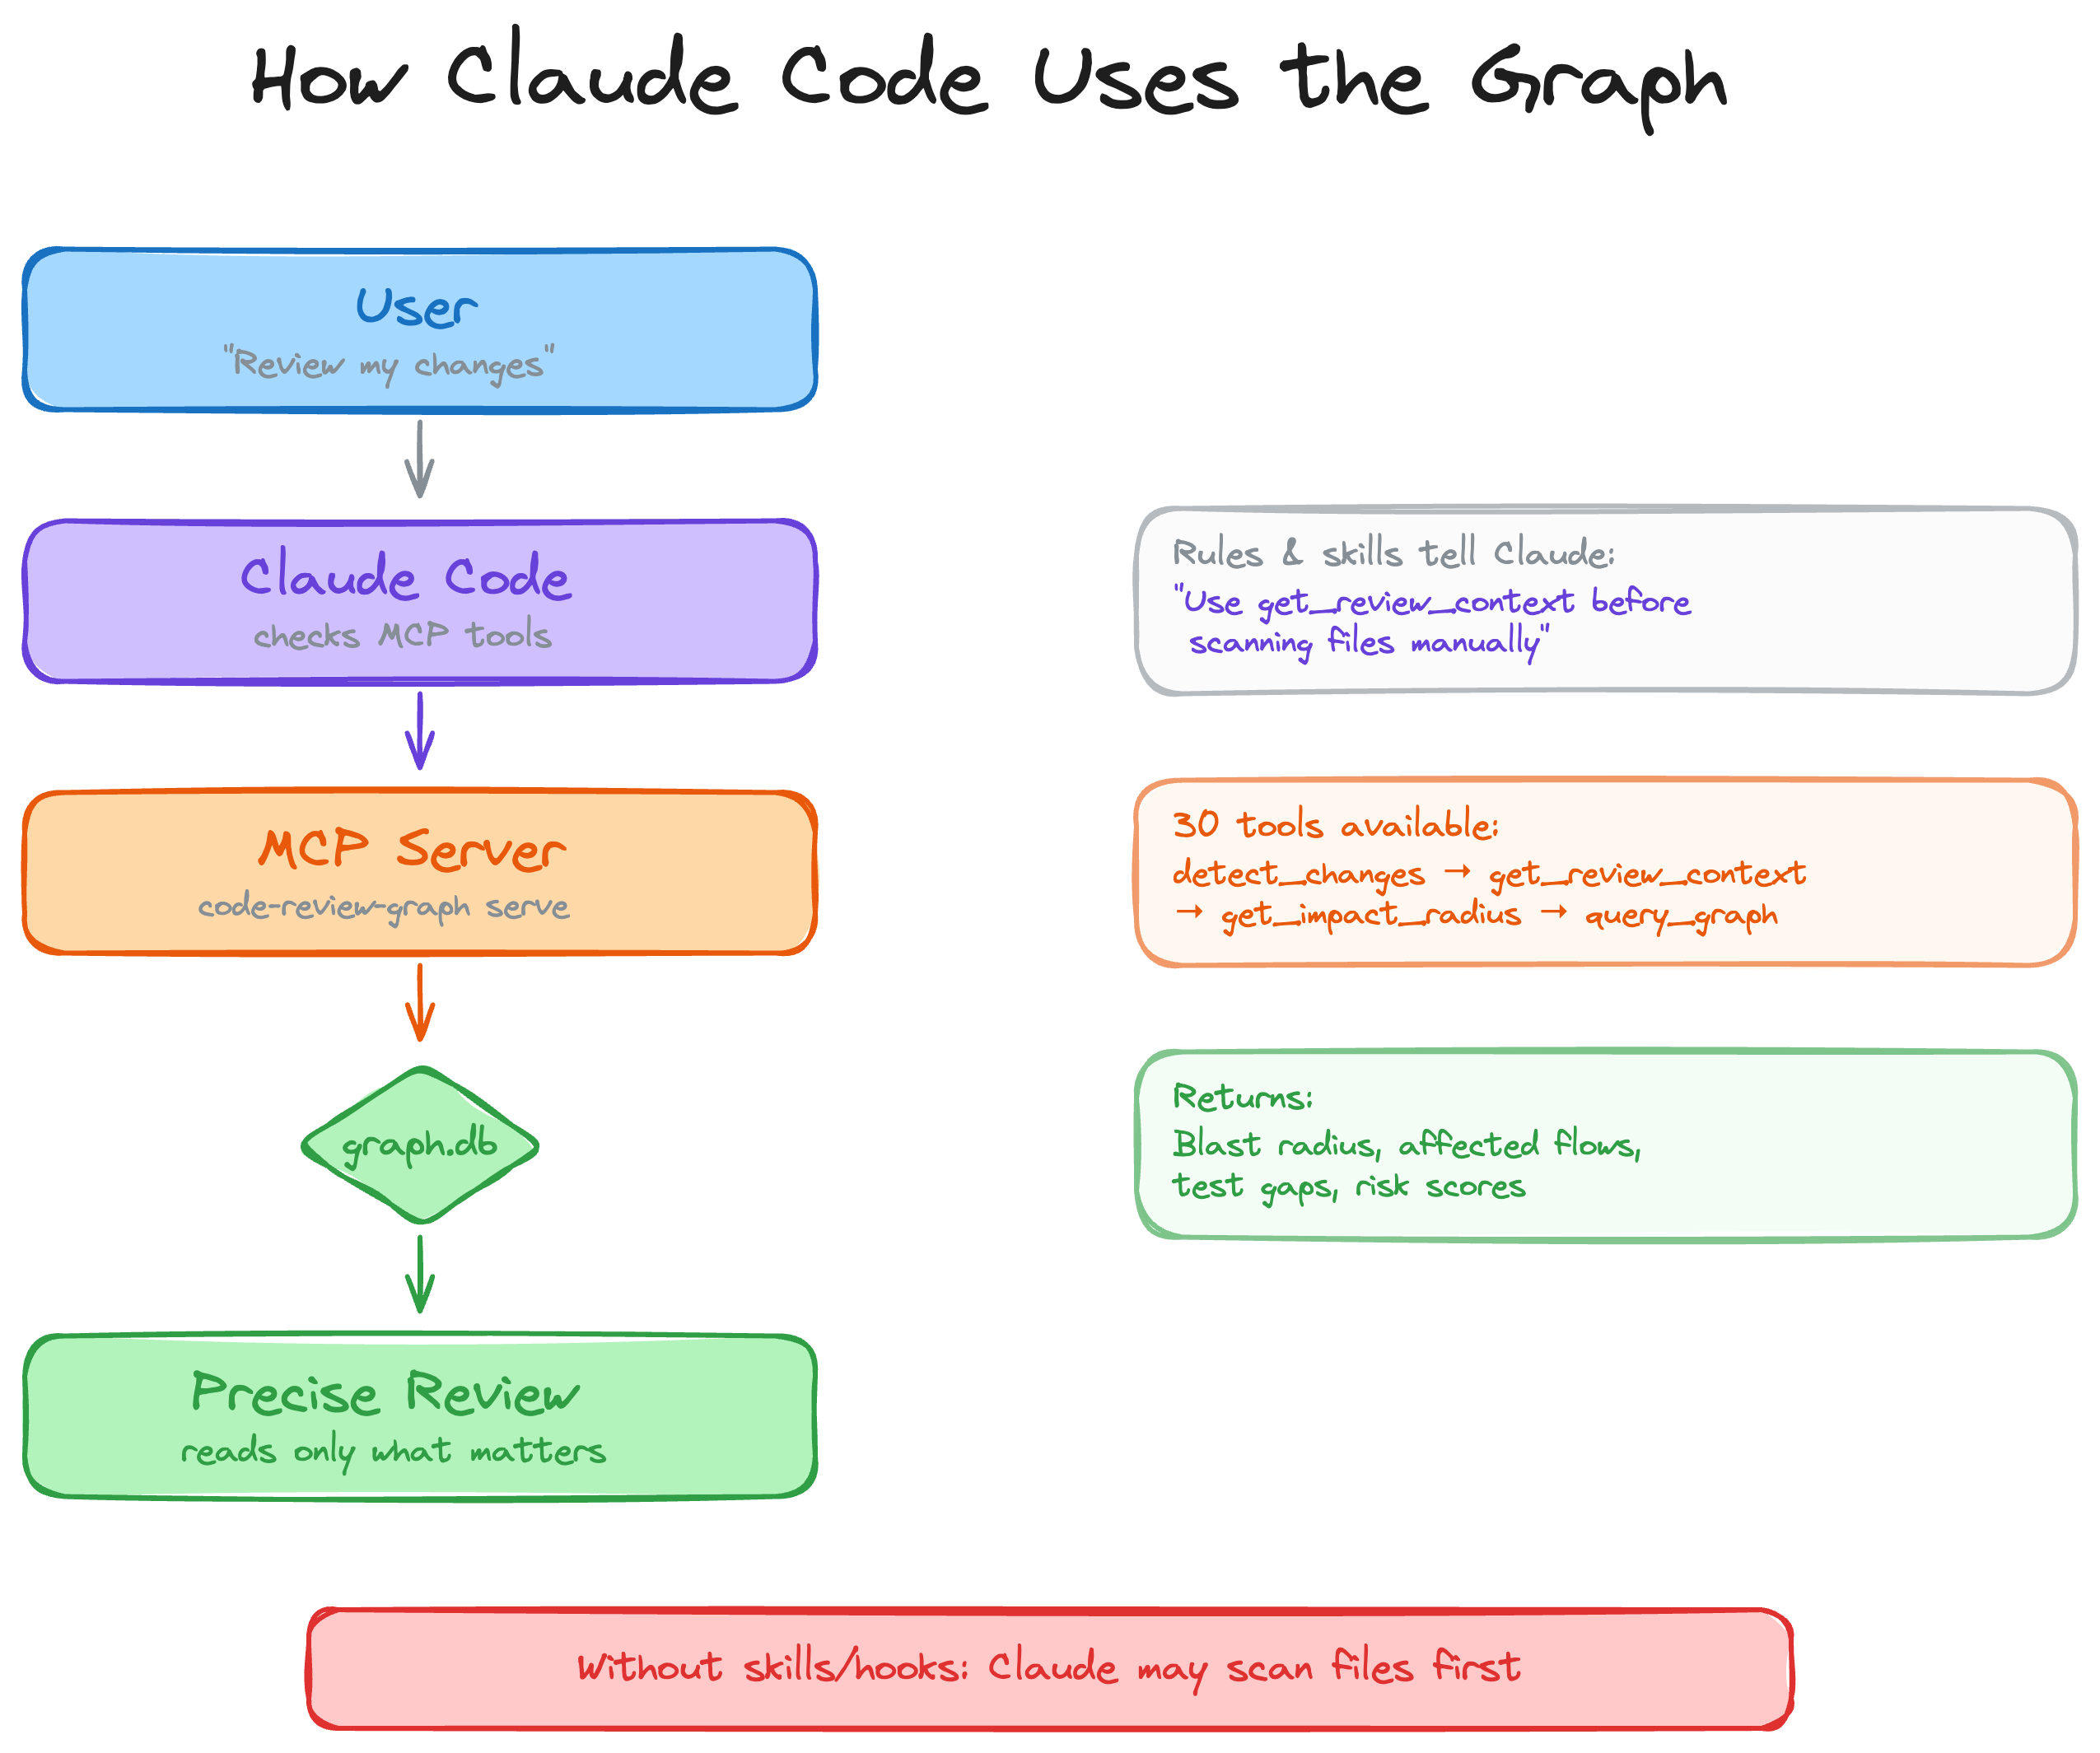
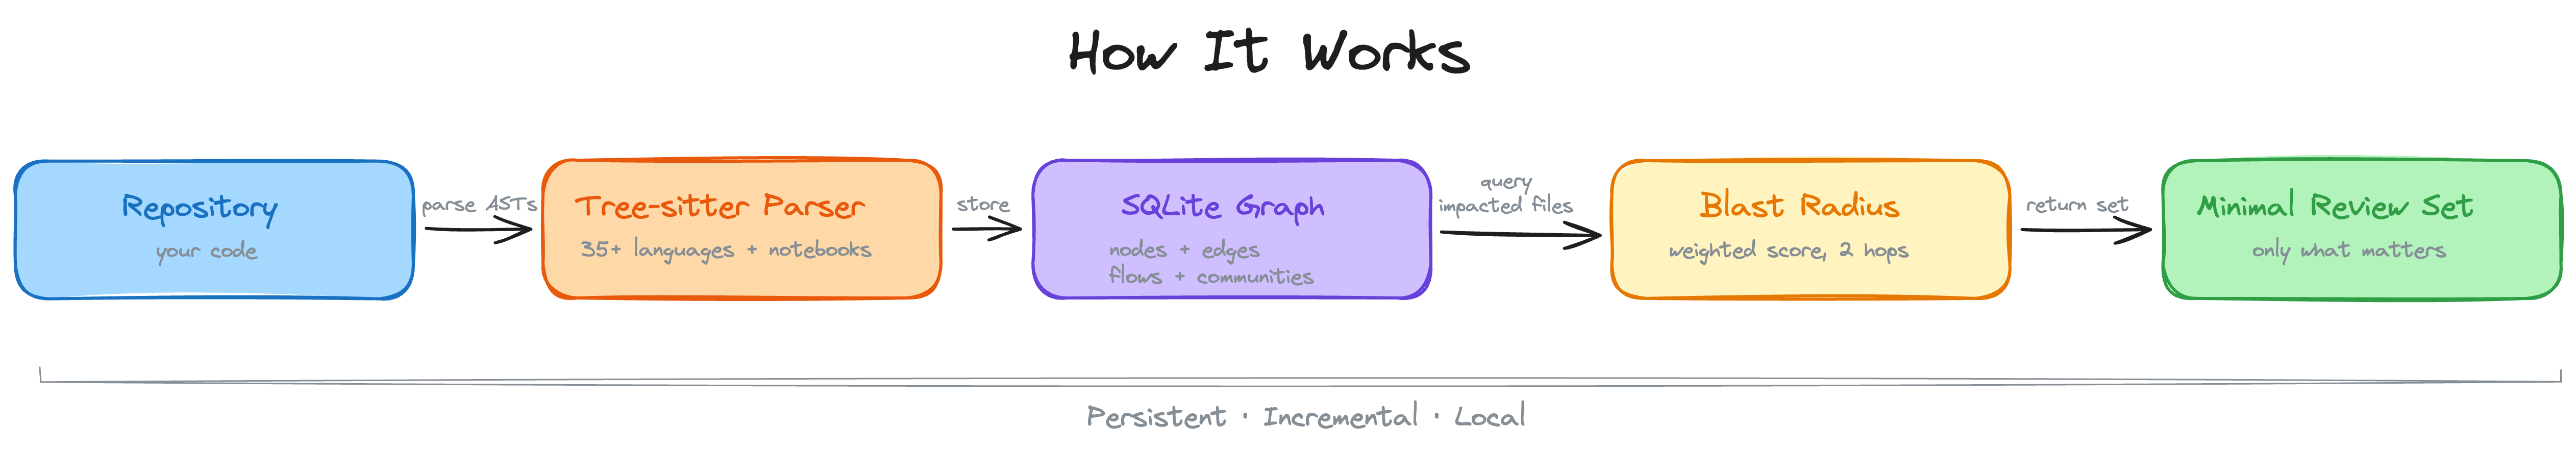
Your repository is parsed into an AST with Tree-sitter, stored as a graph of nodes (functions, classes, imports) and edges (calls, inheritance, test coverage), then queried at review time to compute the minimal set of files your AI assistant needs to read.
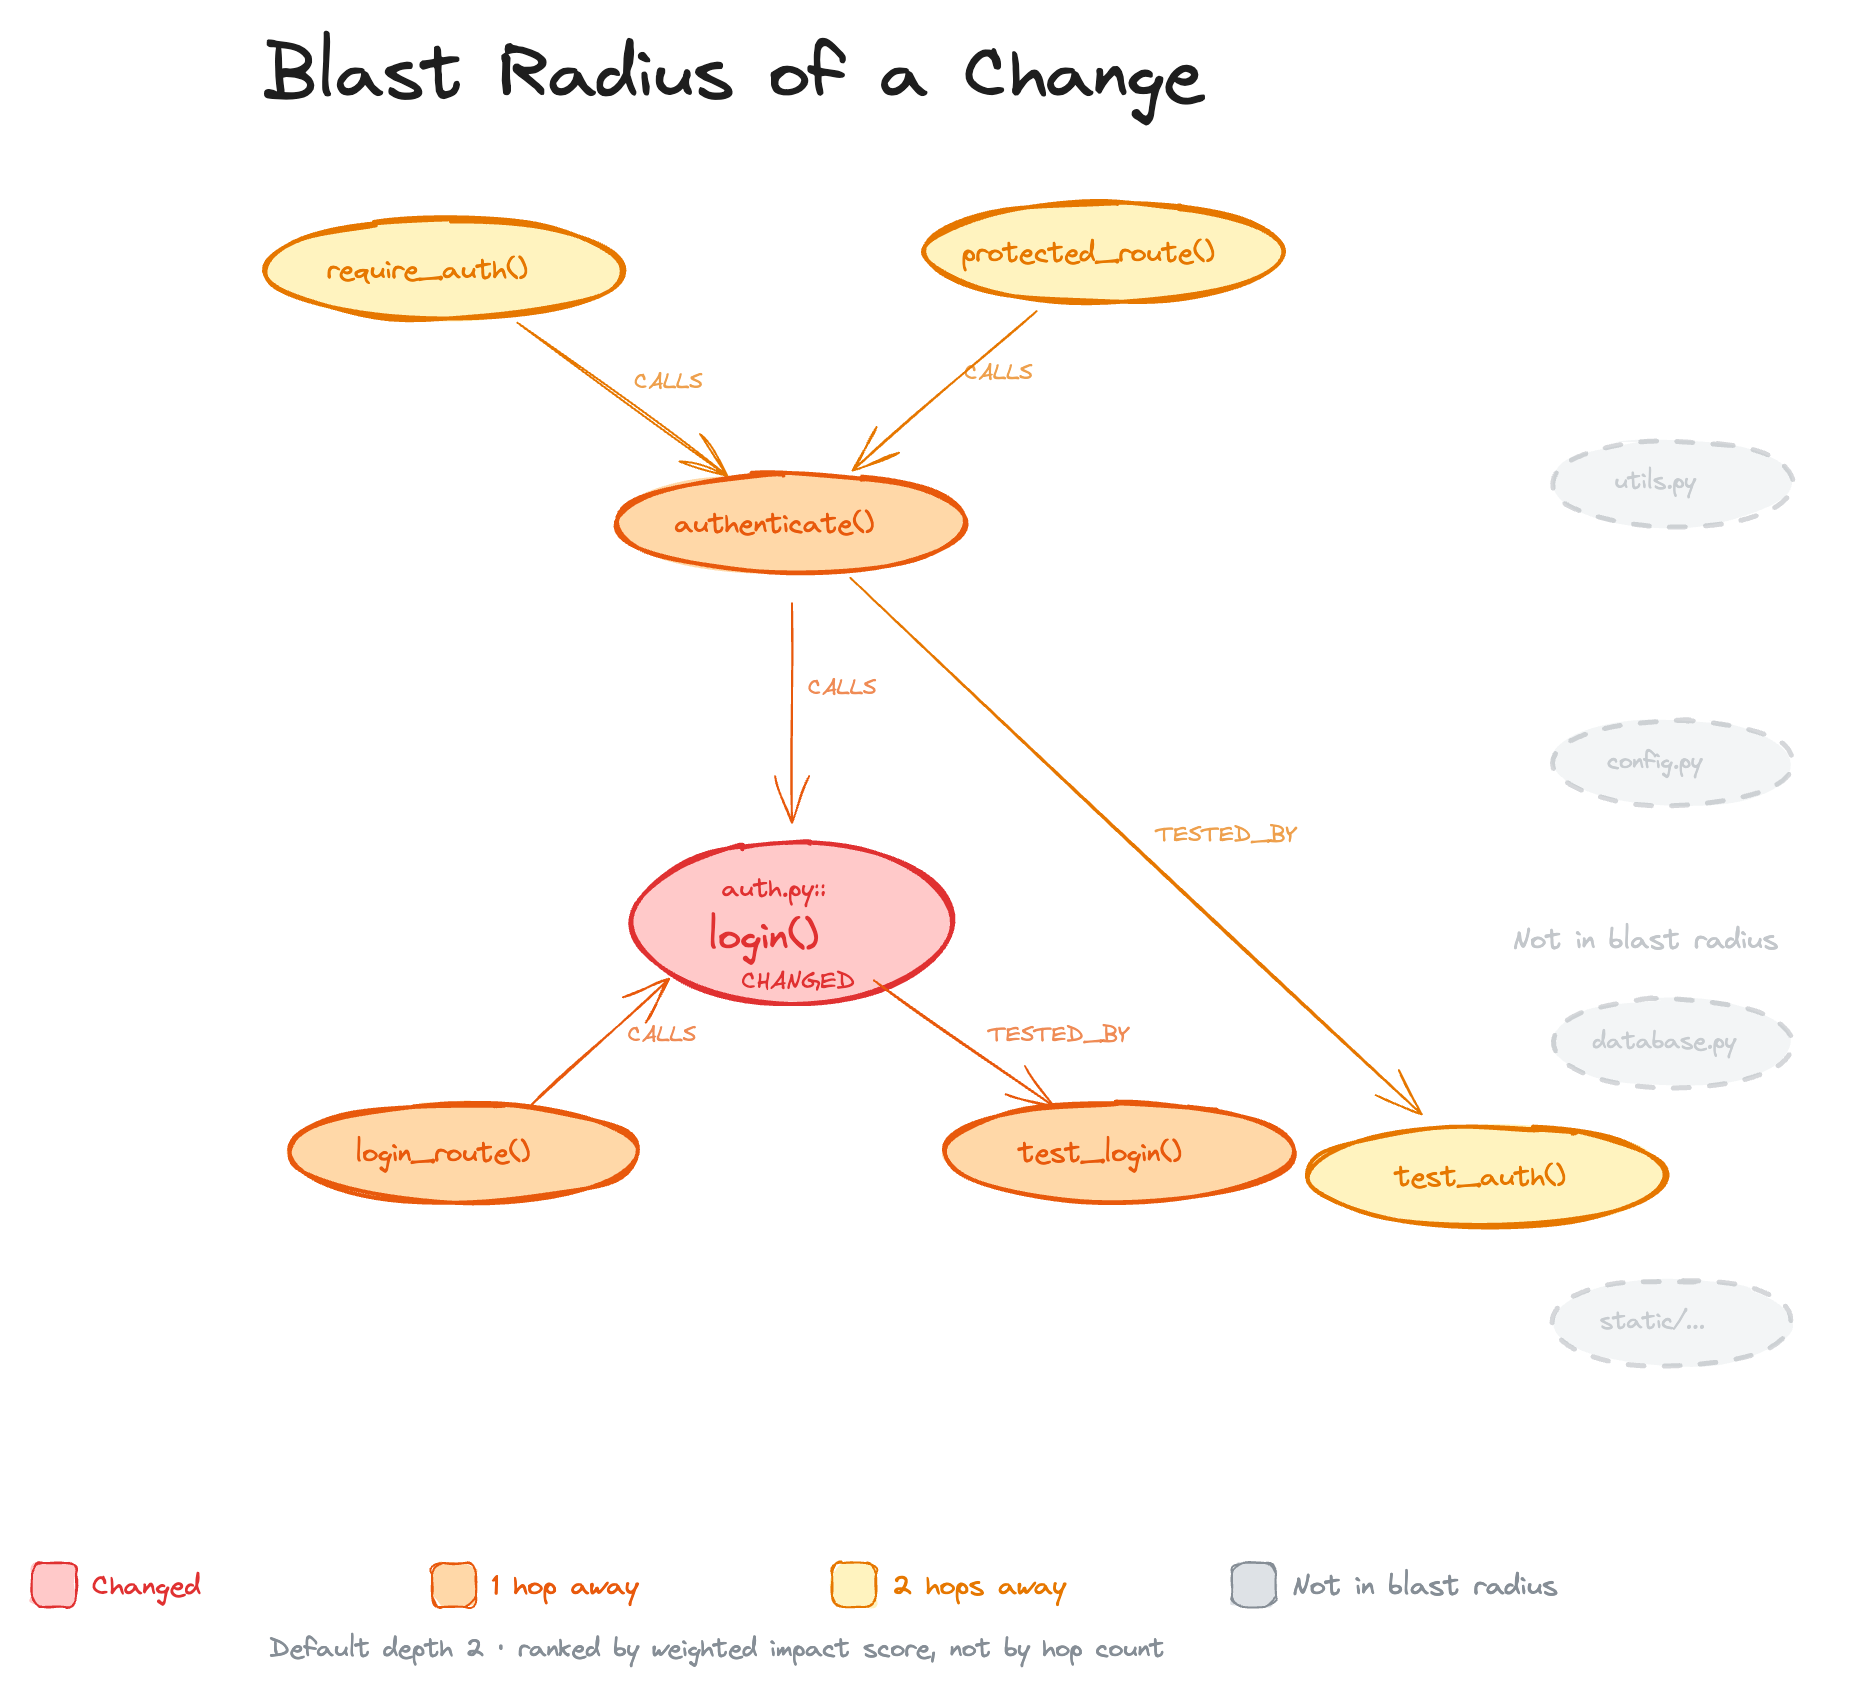
When a file changes, the graph traces every caller, dependent, and test that could be affected. This is the "blast radius" of the change. Your AI reads only these files instead of scanning the whole project.
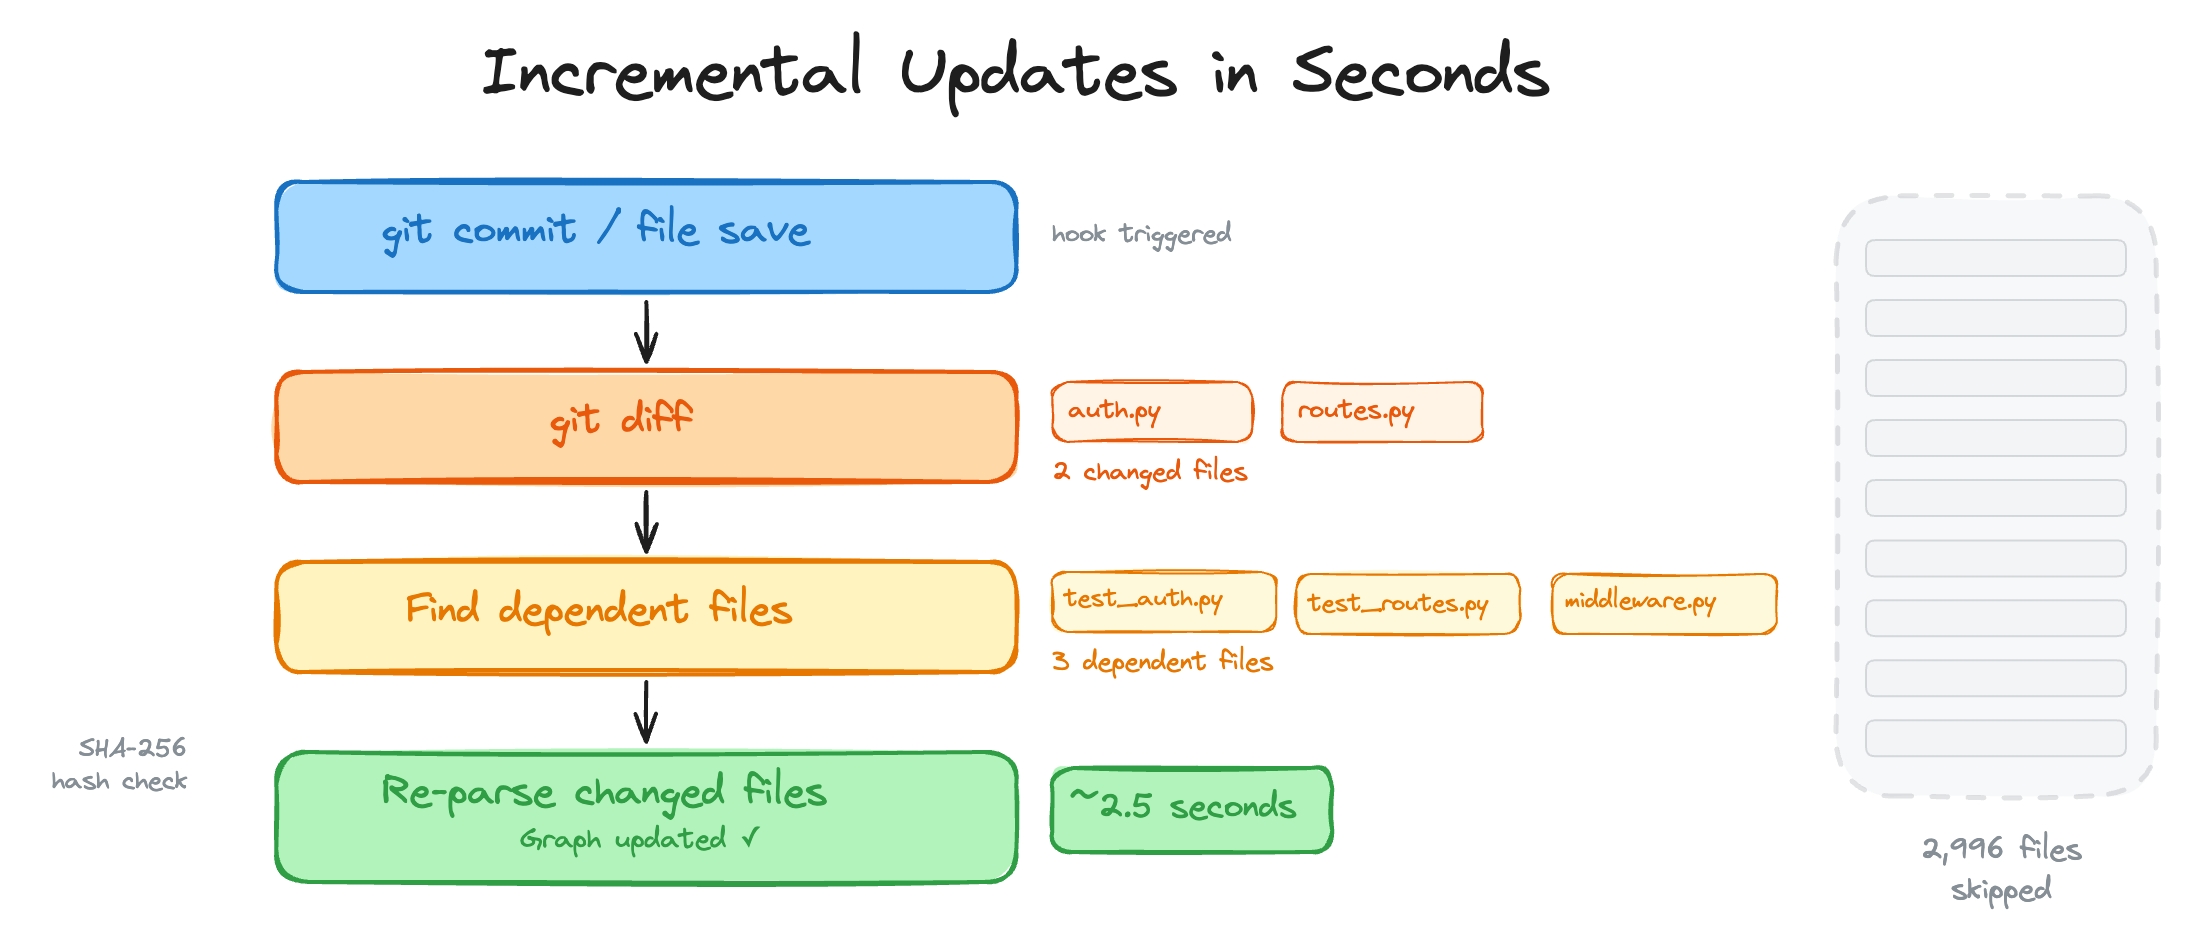
When hooks or watch mode are enabled, file saves and supported commit hooks trigger incremental updates. The graph diffs changed files, finds their dependents through the graph's own import and call edges, and re-parses only the files whose SHA-256 hash actually changed. On a ~3,000-file project (django) a two-file edit re-indexes in about 2.5 seconds on the path the hooks use, of which ~1.4 s is process start-up; a no-op update costs only that start-up. See Incremental update latency for the full measurement.
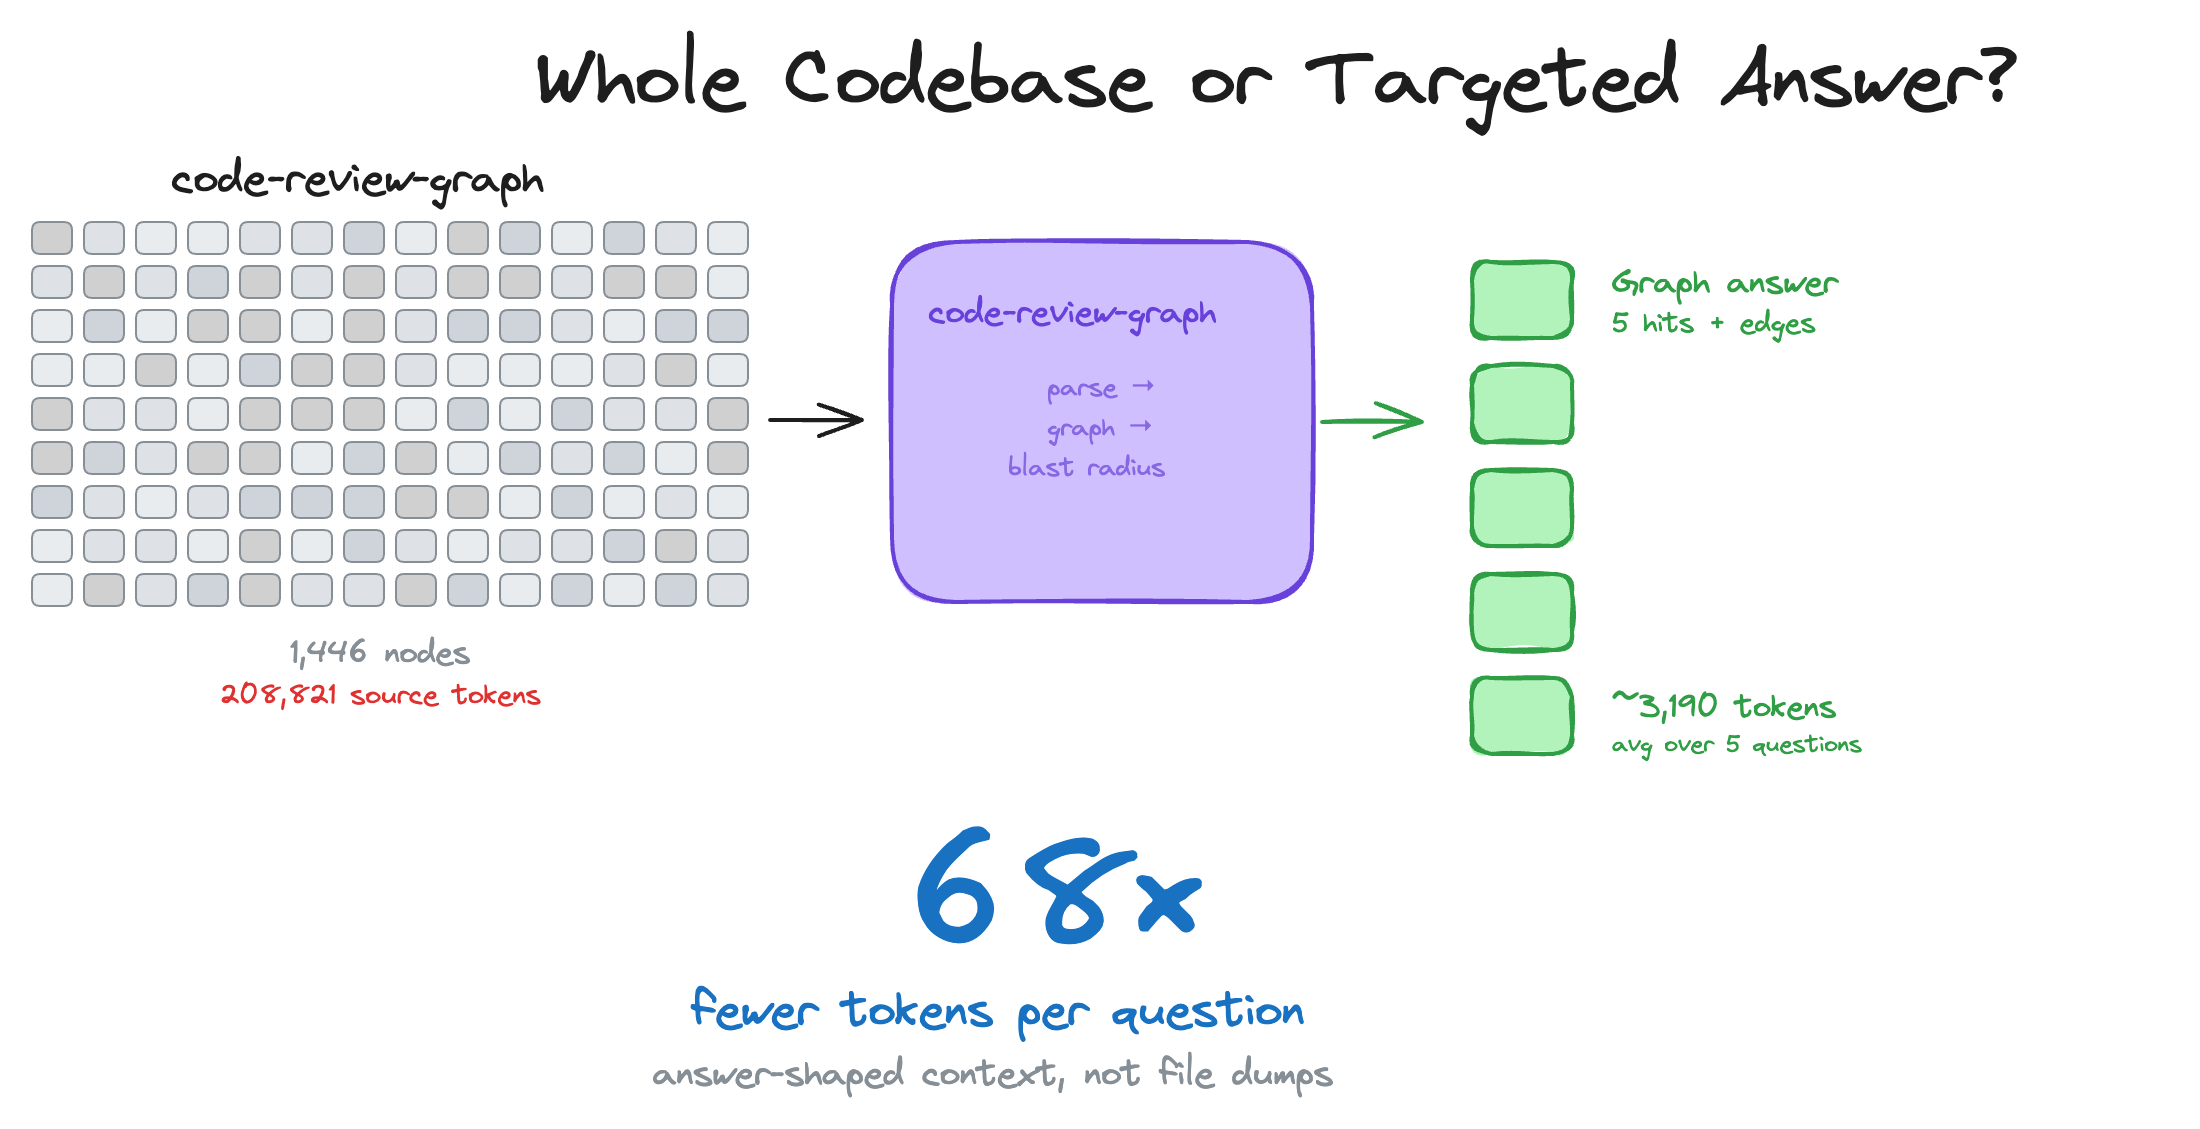
The bigger the repository, the more token waste hurts. Instead of feeding a whole corpus to the model, the graph returns an answer-shaped slice of it: on this repository, 208,821 source tokens become ~3,190 tokens per question.
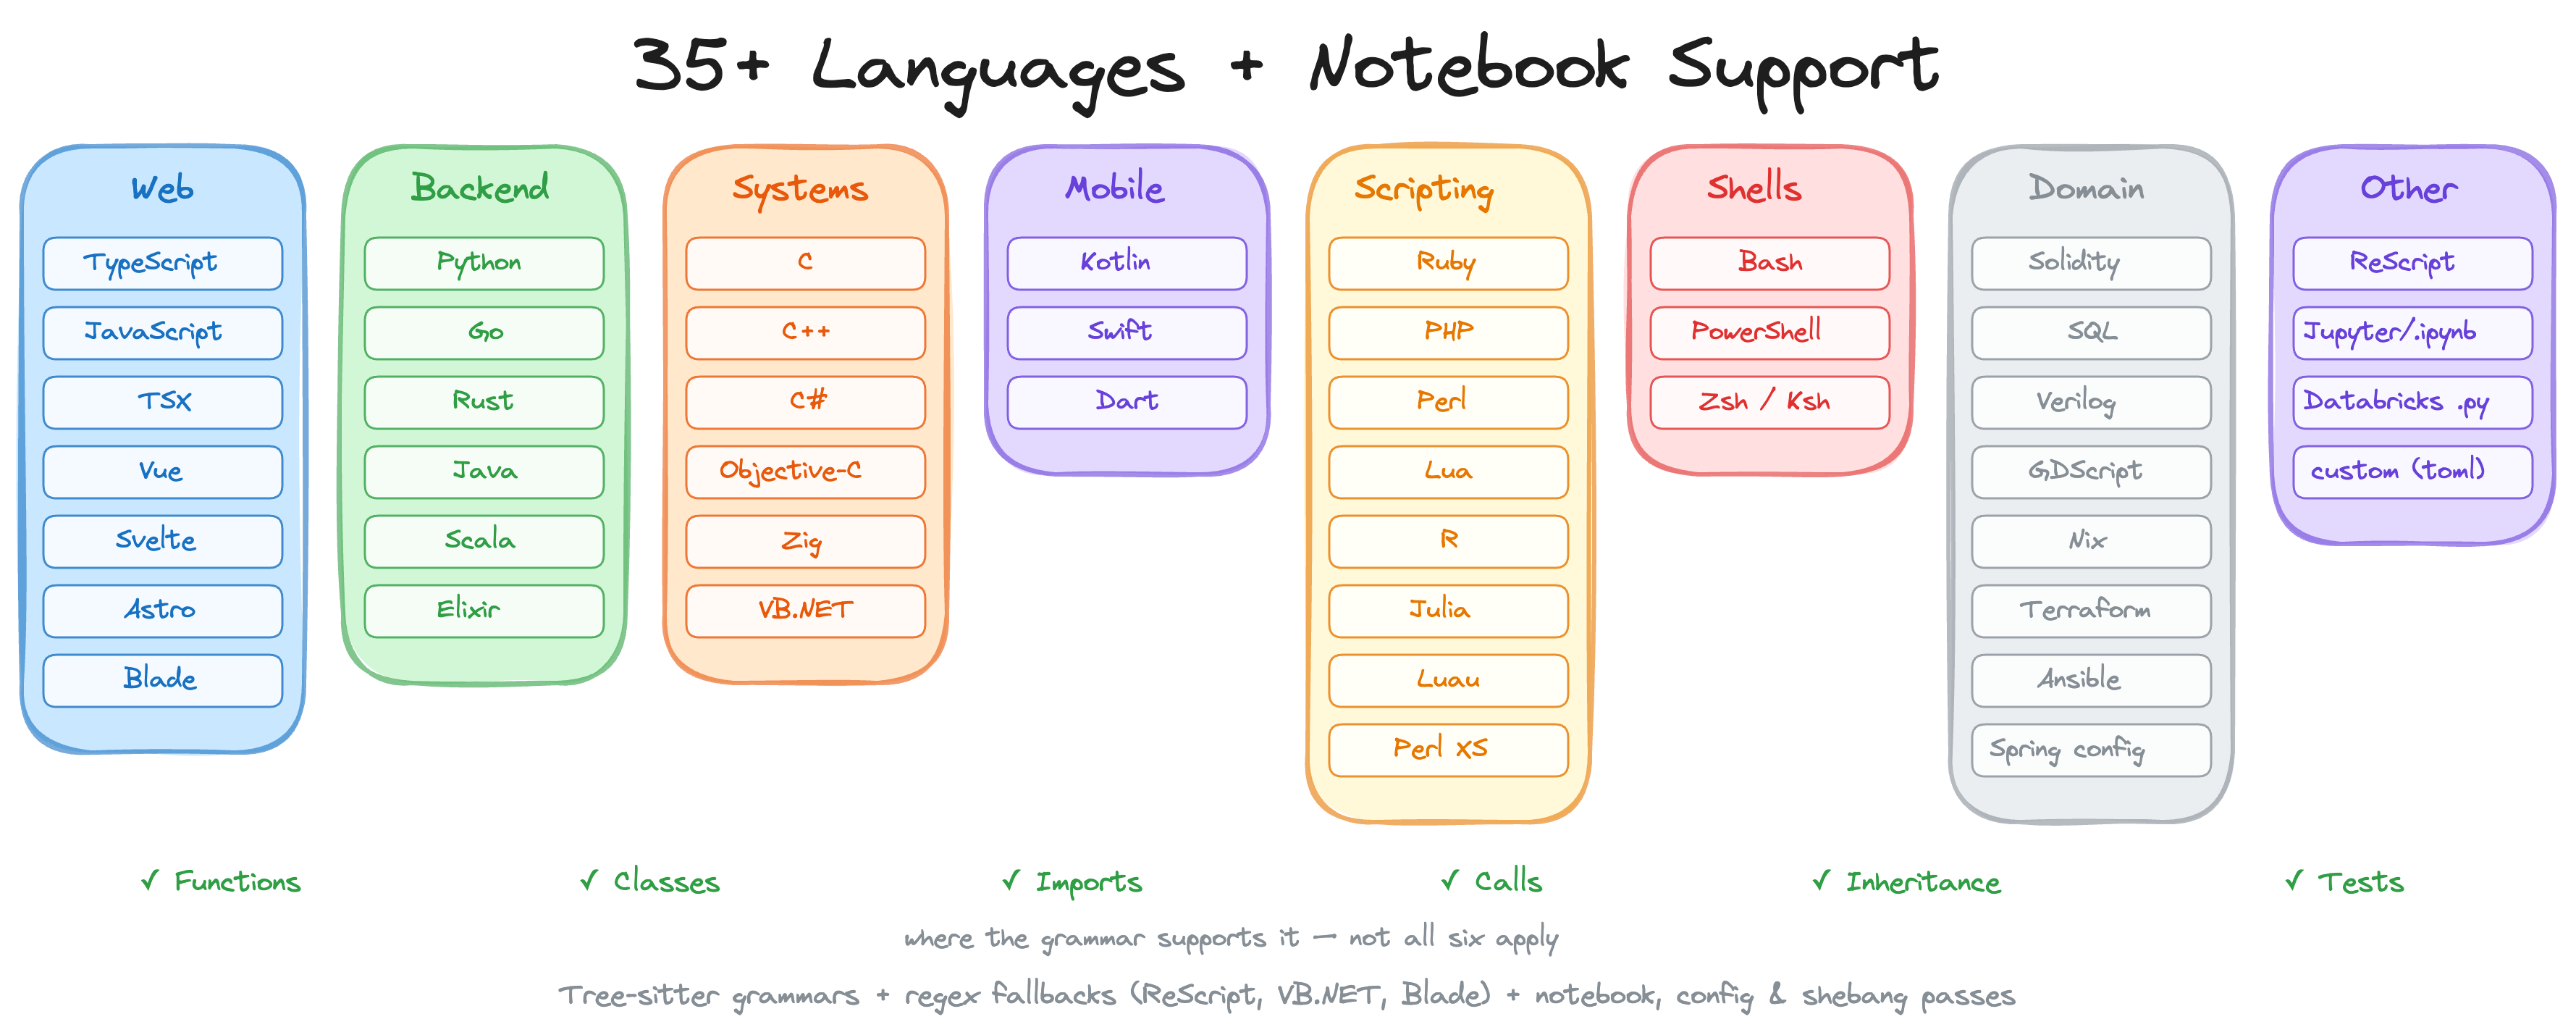
Parser support covers functions, classes, imports, call sites, inheritance, and test detection across the current parser surface, using Tree-sitter where available and targeted fallbacks where needed. Current support includes Python, JavaScript/TypeScript/TSX, Go, Rust, Java, C/C++, C#, VB.NET, Ruby, Kotlin, Swift, PHP, Scala, Solidity, Dart, R, Perl, Lua/Luau, Objective-C, shell scripts, Elixir, Zig, PowerShell, Julia, ReScript, GDScript, Nix, Verilog/SystemVerilog, SQL, Terraform/OpenTofu structure (.tf; generic .hcl files are recognized as file nodes), Ansible playbooks/roles/tasks, Vue/Svelte SFCs, Astro files parsed through the TypeScript parser, Jupyter/Databricks notebooks (.ipynb), and Perl XS files (.xs). Generic YAML is not treated as source code.
PHP projects additionally get repository-bounded Composer PSR-4 resolution, Blade template references, and Laravel Route/Eloquent semantic edges when the source includes explicit framework imports, model inheritance, and receiver evidence.
If your repo uses a language the parser does not cover yet, drop a languages.toml into .code-review-graph/ mapping file extensions to any grammar bundled in tree_sitter_language_pack, plus the tree-sitter node types for functions, classes, imports, and calls:
[languages.erlang]
extensions = [".erl"]
grammar = "erlang"
function_node_types = ["function_clause"]
class_node_types = ["record_decl"]
import_node_types = ["import_attribute"]
call_node_types = ["call"]
The generic tree-sitter walker handles extraction from there — no code changes, and built-in languages can never be overridden. See docs/CUSTOM_LANGUAGES.md for the schema reference, validation rules, and a worked end-to-end example.
The same analysis runs as a composite GitHub Action — and it stays local-first: the knowledge graph is built and queried entirely on your CI runner, with no source code sent to any external service. On each pull request the action posts a single sticky comment with risk-scored functions, affected execution flows, and test gaps, updated in place on every push. An optional fail-on-risk input turns the review into a merge gate.
# .github/workflows/code-review-graph.yml
on:
pull_request:
permissions:
contents: read
pull-requests: write
jobs:
review:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v7
- uses: tirth8205/[email protected]
with:
github-token: ${{ secrets.GITHUB_TOKEN }}
See docs/GITHUB_ACTION.md for inputs, risk levels, and caching details, or the dogfood workflow this repo runs on itself in .github/workflows/pr-review.yml.
---
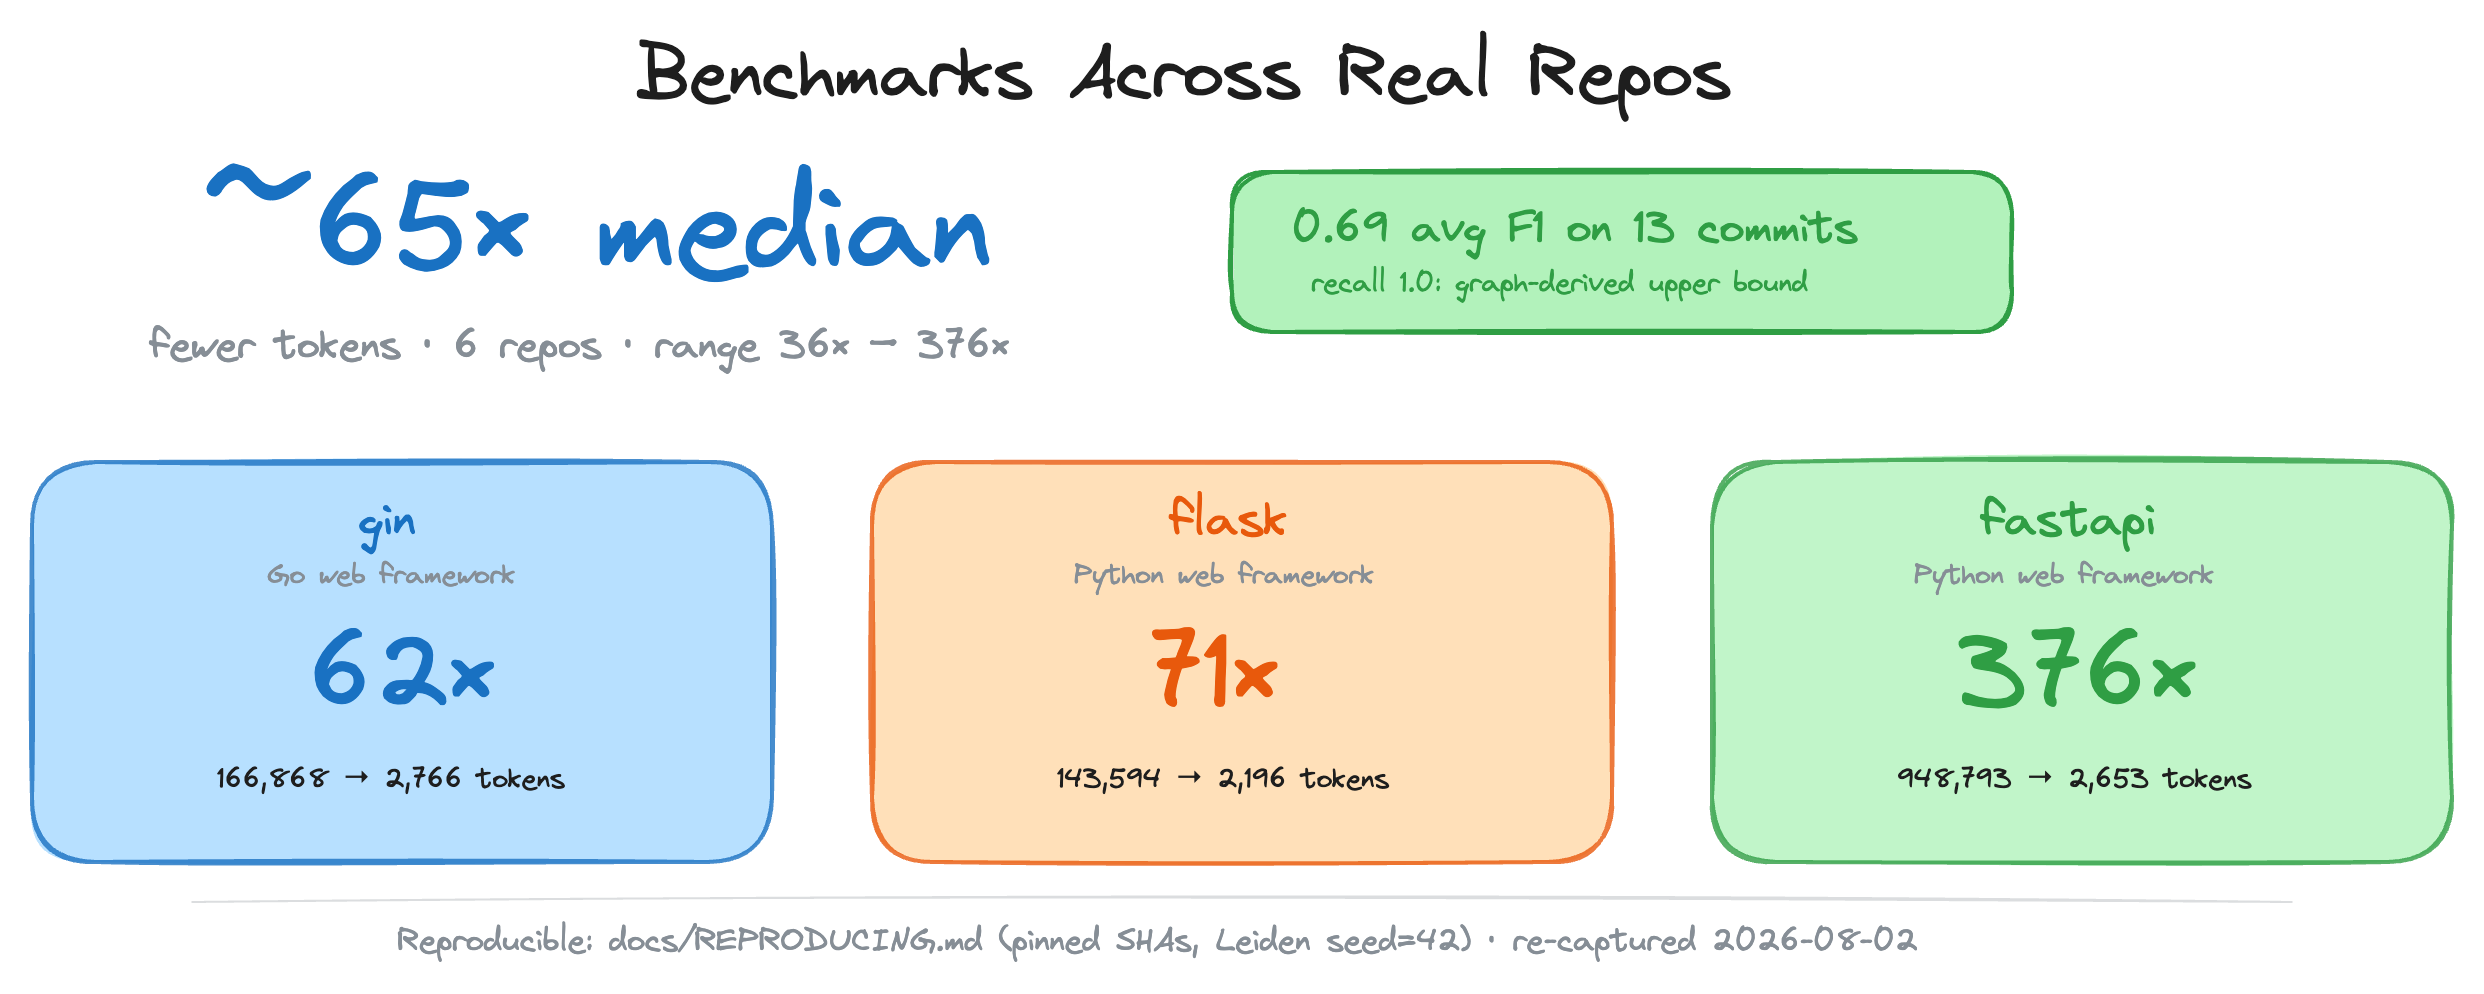
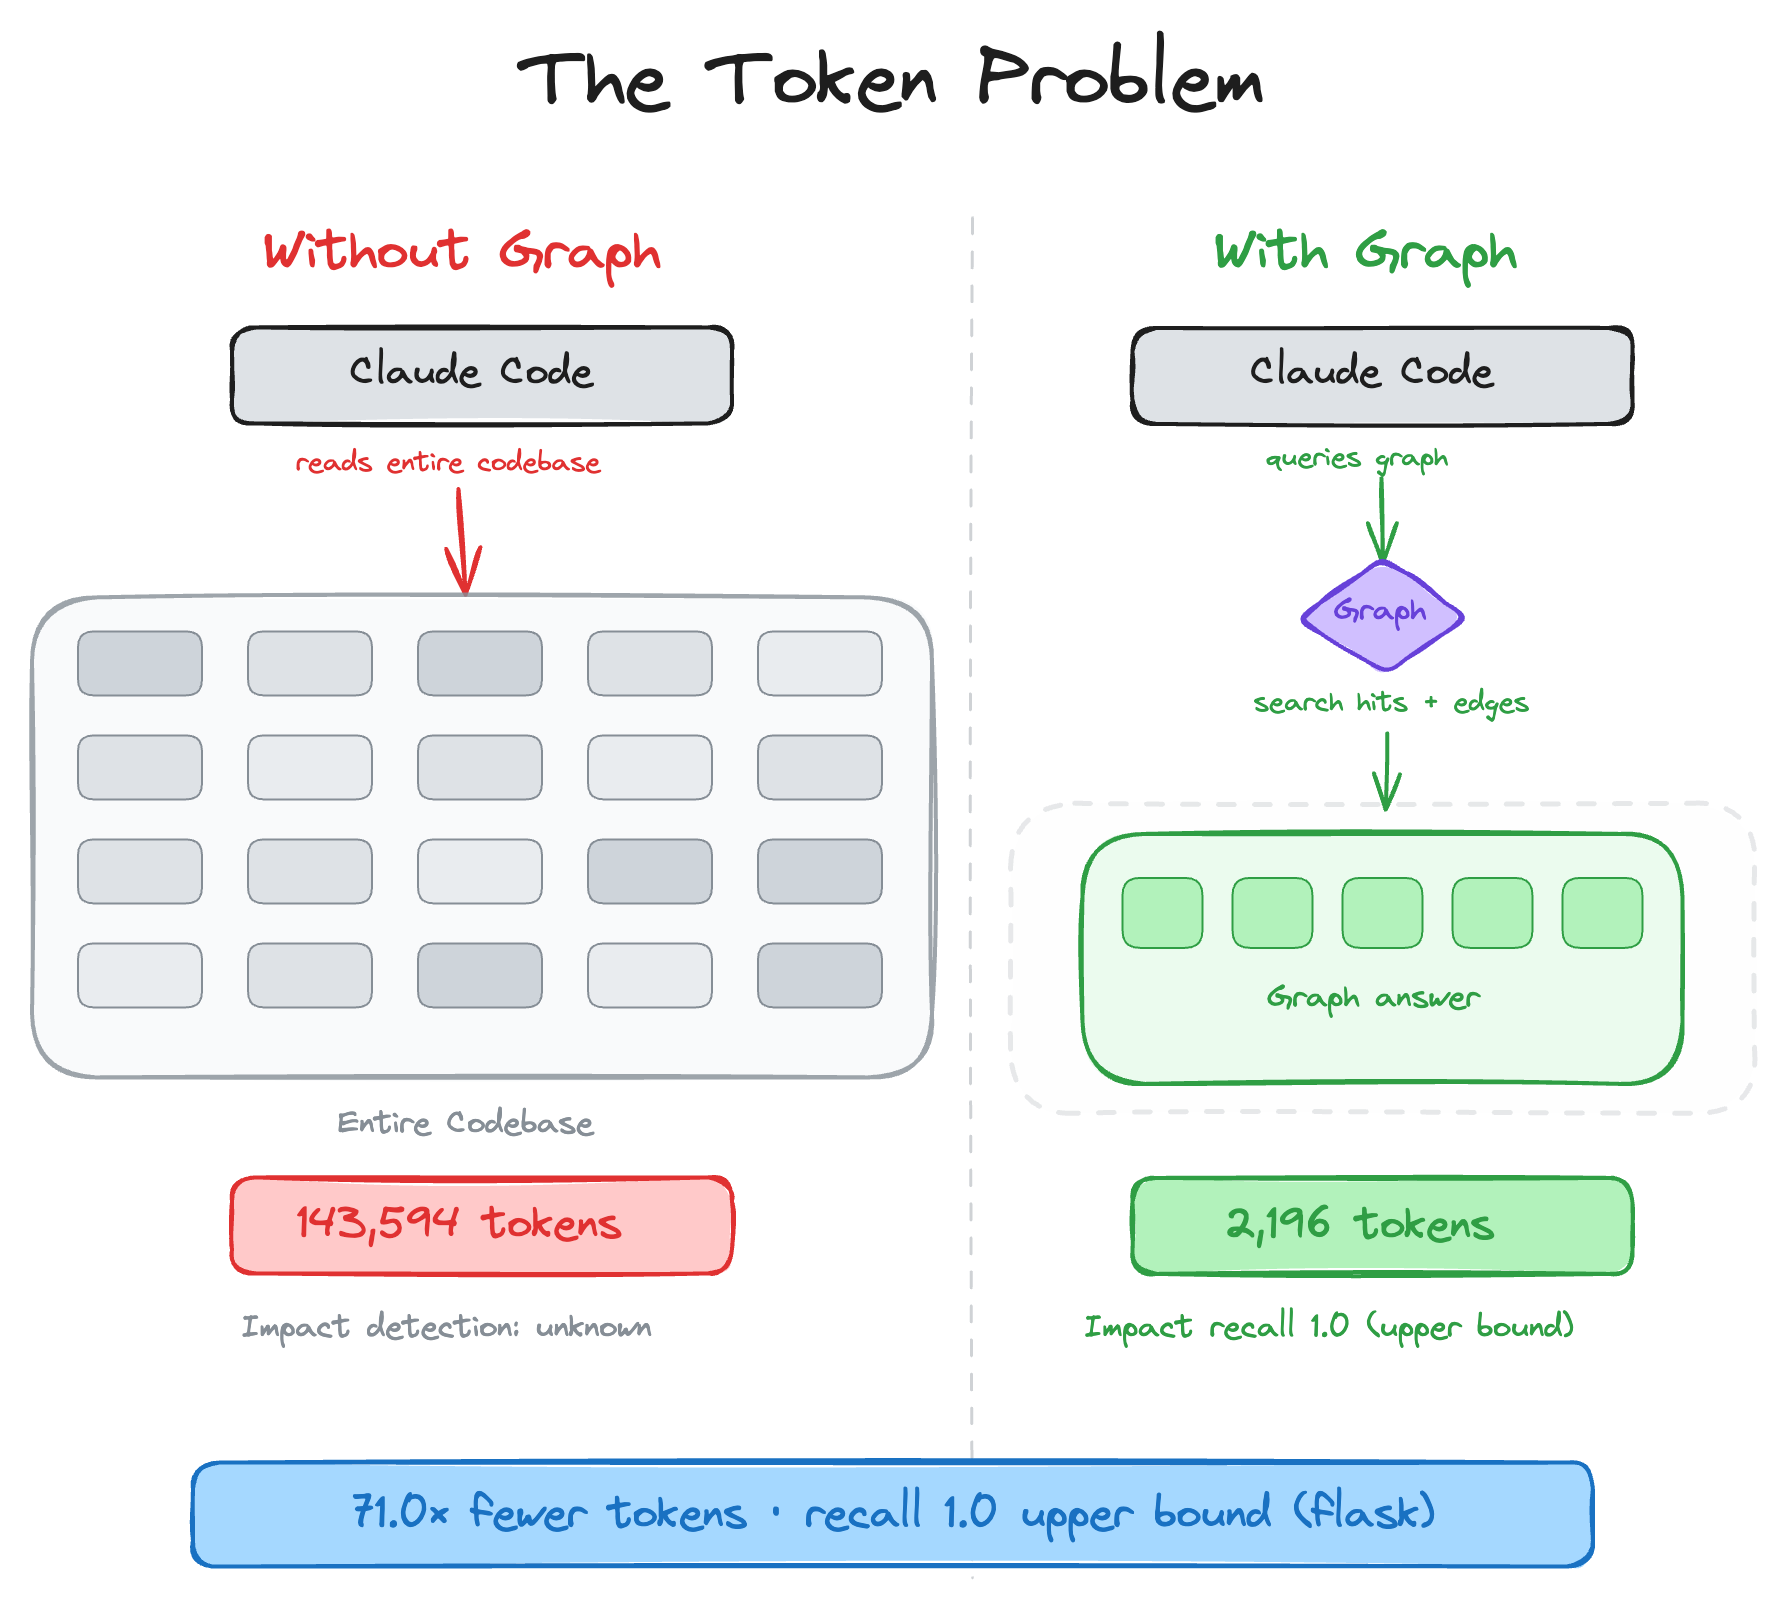
Headline number: the median per-question token reduction across the 6 repos is ~65x (whole-corpus baseline vs graph query). The 376x maximum is a single best-case repo (fastapi, the largest corpus) — not the typical result.
All numbers come from the automated evaluation runner against 6 real open-source repositories (13 commits total). Every config pins an upstream SHA, the Leiden community detector runs with a fixed seed, and embeddings are deterministic on CPU — so two runs on different machines produce identical numbers. The full reproduction recipe with expected outputs is in docs/REPRODUCING.md. A weekly report-only run on the two smallest configs lives in .github/workflows/eval.yml.
For a typical agent question ("how does authentication work", "what is the main entry point", etc.), the graph returns ~2,000–3,500 tokens of targeted search hits + neighbor edges instead of forcing the agent to read every source file. The table below averages over the 5 sample questions defined in code_review_graph/token_benchmark.py.
| Repo | Snapshot SHA | naive_corpus_tokens | avg graph_tokens | Reduction |
|------|---|-----------------:|----------------:|----------:|
| fastapi | 22381558 | 948,793 | 2,653 | 375.6x |
| flask | a29f88ce | 143,594 | 2,196 | 71.0x |
| code-review-graph | 84bde354 | 208,821 | 3,190 | 68.1x |
| gin | 5c00df8a | 166,868 | 2,766 | 61.9x |
| httpx | b55d4635 | 142,356 | 2,661 | 60.6x |
| express | b4ab7d65 | 136,052 | 3,936 | 36.0x |
Median per-question reduction across the 6 repos: ~65x. The range is 36x – 376x, where 376x is the best case (fastapi, the largest corpus), not the headline.
Re-captured 2026-08-02 from clean clones at the pinned SHAs (crg 2.3.7, localall-MiniLM-L6-v2embeddings). These numbers are lower than the 2026-05-25 capture they replace: the graph response grew as node embedding text became richer, soavg graph_tokensrose across every repo. fastapi is now measured at its current pin22381558rather than the retired0227991a.
The whole-corpus baseline above is an upper bound no real agent pays: a competent agent greps for identifiers and reads only the best-matching files. The agent_baseline eval benchmark measures that realistic baseline — a pure-python grep over the corpus, top-3 files by match count, token-counted and compared to the graph query cost (evaluate/results/_agent_baseline_*.csv).
The formal eval/benchmarks/token_efficiency.py benchmark measures a different scenario — full get_review_context() JSON versus just the changed-file content of a commit — and reports ratios below 1 for small commits, because the review-context response carries impact-radius edges plus source snippets that exceed a tiny single-file diff. That is not a bug; the two benchmarks answer different questions. See docs/REPRODUCING.md for the full methodology.
Since v2.3.4, review and impact tools attach a compact context_savings estimate so MCP clients can see the approximate context saved per call. In v2.3.5 the CLI surfaces this as the boxed Token Savings panel shown above (see "Token Savings panel" in the Usage section) and adds --verify to cross-check against OpenAI's cl100k_base tokenizer. Calibration data in docs/REPRODUCING.md shows the estimate is within ~1% of real GPT-4 tokens in aggregate across 222 sample files.
Blast-radius analysis recovers every file in the ground truth on all 13 evaluation commits — but read that as an upper bound, not as "100% recall": in this mode the ground truth (changed files + files with call/import edges into them) is derived from the same graph the predictor traverses, so it is circular by construction. The over-prediction visible in the precision column is a deliberate trade-off: better to flag too many files than miss a broken dependency.
| Repo | Commits | Avg F1 | Avg Precision | Recall (graph-derived upper bound) | |------|--------:|-------:|--------------:|-------:| | httpx | 2 | 0.863 | 0.785 | 1.0 | | code-review-graph | 2 | 0.734 | 0.584 | 1.0 | | fastapi | 2 | 0.697 | 0.539 | 1.0 | | express | 2 | 0.667 | 0.500 | 1.0 | | flask | 2 | 0.633 | 0.485 | 1.0 | | gin | 3 | 0.609 | 0.439 | 1.0 | | Average | 13 | 0.693 | 0.546 | 1.000 |
The benchmark also runs an honest co-change mode: the predictor is seeded with a single changed file and graded against the other files the author actually touched in the same commit — independent-ish evidence from git history, not from the graph. Both modes appear side by side in the result CSVs (ground_truth_mode column). As of the 2026-08-02 capture that mode returns predicted_files = 0 on every graded commit, so it is not yet a usable measurement and no co-change number is quoted here — the harness needs fixing before the mode says anything about accuracy.
| Repo | Files | Nodes | Edges | Flow Detection | Search Latency | |------|------:|------:|------:|---------------:|---------------:| | express | 141 | 1,910 | 17,553 | 106ms | 0.7ms | | fastapi | 1,122 | 6,285 | 27,117 | 128ms | 1.5ms | | flask | 83 | 1,446 | 7,974 | 95ms | 0.7ms | | gin | 99 | 1,286 | 16,762 | 111ms | 0.5ms | | httpx | 60 | 1,253 | 7,896 | 96ms | 0.4ms |
| Feature | Details |
|---------|---------|
| Incremental updates | Re-parses only the files whose hash changed. On a ~3,000-file repo a two-file edit takes ~2.5s on the hook path (measured). |
| Broad language + notebook support | Python, JavaScript/TypeScript/TSX, Go, Rust, Java, C/C++, C#, VB.NET, Ruby, Kotlin, Swift, PHP, Scala, Solidity, Dart, R, Perl, Lua/Luau, Objective-C, shell scripts, Elixir, Zig, PowerShell, Julia, ReScript, GDScript, Nix, Verilog/SystemVerilog, SQL, Terraform/OpenTofu structure (.tf; generic .hcl files are file-only), Ansible playbooks/roles/tasks, Vue/Svelte SFCs, Astro files parsed through the TypeScript parser, Jupyter/Databricks (.ipynb), and Perl XS (.xs) |
| Framework-aware PHP parsing | Repository-bounded Composer PSR-4 imports, Blade template references, and evidence-gated Laravel Route-to-controller and Eloquent relationship edges |
| Blast-radius analysis | Shows which functions, classes, and files are likely affected by a change |
| Auto-update hooks | Hooks and watch mode can update the graph on file saves and supported commit hooks |
| Semantic search | Optional vector embeddings via sentence-transformers, Google Gemini, MiniMax, Voyage AI, or any OpenAI-compatible endpoint (real OpenAI, Azure, new-api, LiteLLM, vLLM, LocalAI) |
| Interactive visualisation | D3.js force-directed graph with search, community legend toggles, and degree-scaled nodes |
| Hub & bridge detection | Find most-connected nodes and architectural chokepoints via betweenness centrality |
| Surprise scoring | Detect unexpected coupling: cross-community, cross-language, peripheral-to-hub edges |
| Knowledge gap analysis | Identify isolated nodes, untested hotspots, thin communities, and structural weaknesses |
| Suggested questions | Auto-generated review questions from graph analysis (bridges, hubs, surprises) |
| Edge confidence | Three-tier confidence scoring (EXTRACTED/INFERRED/AMBIGUOUS) with float scores on edges |
| Graph traversal | Free-form BFS/DFS exploration from any node with configurable depth and token budget |
| Export formats | GraphML (Gephi/yEd), Neo4j Cypher, Obsidian vault with wikilinks, SVG static graph |
| Graph diff | Compare graph snapshots over time: new/removed nodes, edges, community changes |
| Token benchmarking | Measure naive full-corpus tokens vs graph query tokens with per-question ratios |
| Estimated context savings | Compact context_savings metadata on relevant MCP/CLI review outputs, labelled as estimated and kept to three small fields |
| Memory loop | Persist Q&A results as markdown for re-ingestion, so the graph grows from queries |
| Community auto-split | Oversized communities (>25% of graph) are recursively split via Leiden |
| Execution flows | Trace call chains from entry points, sorted by weighted criticality |
| Community detection | Cluster related code via Leiden algorithm with resolution scaling for large graphs |
| Architecture overview | Auto-generated architecture map with coupling warnings |
| Risk-scored reviews | detect_changes maps diffs to affected functions, flows, and test gaps |
| Custom languages | Add new languages via .code-review-graph/languages.toml — no fork or code changes needed |
| GitHub Action | Sticky risk-scored PR review comments in CI, with an optional fail-on-risk merge gate |
| Refactoring tools | Rename preview, framework-aware dead code detection, community-driven suggestions |
| Wiki generation | Auto-generate markdown wiki from community structure |
| Multi-repo registry | Register multiple repos, search across all of them |
| Multi-repo daemon | crg-daemon watches multiple repos as child processes, with health checks and auto-restart |
| MCP prompts | 5 workflow templates: review, architecture, debug, onboard, pre-merge |
| Full-text search | FTS5-powered hybrid search combining keyword and vector similarity |
| Local storage | SQLite file in .code-review-graph/. Core graph storage needs no external database or cloud service. |
| Watch mode | Continuous graph updates as you work |
---
→ →
 →
 →
 →
 →