1
 →
HunyuanImage-3.0: A Powerful Native Multimodal Model for Image Generation
Tencent-Hunyuan/HunyuanImage-3.0 is an open-source project on GitHub, mainly written in Python. HunyuanImage-3.0: A Powerful Native Multimodal Model for Image Generation It currently holds 3,294 stars and 0 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
Git Homed tracks it on the Image Trending board and on the AI Image Trending list.
👏 Join our WeChat and Discord | 💻 Official website(官网) Try our model!  
If you develop/use HunyuanImage-3.0 in your projects, welcome to let us know.
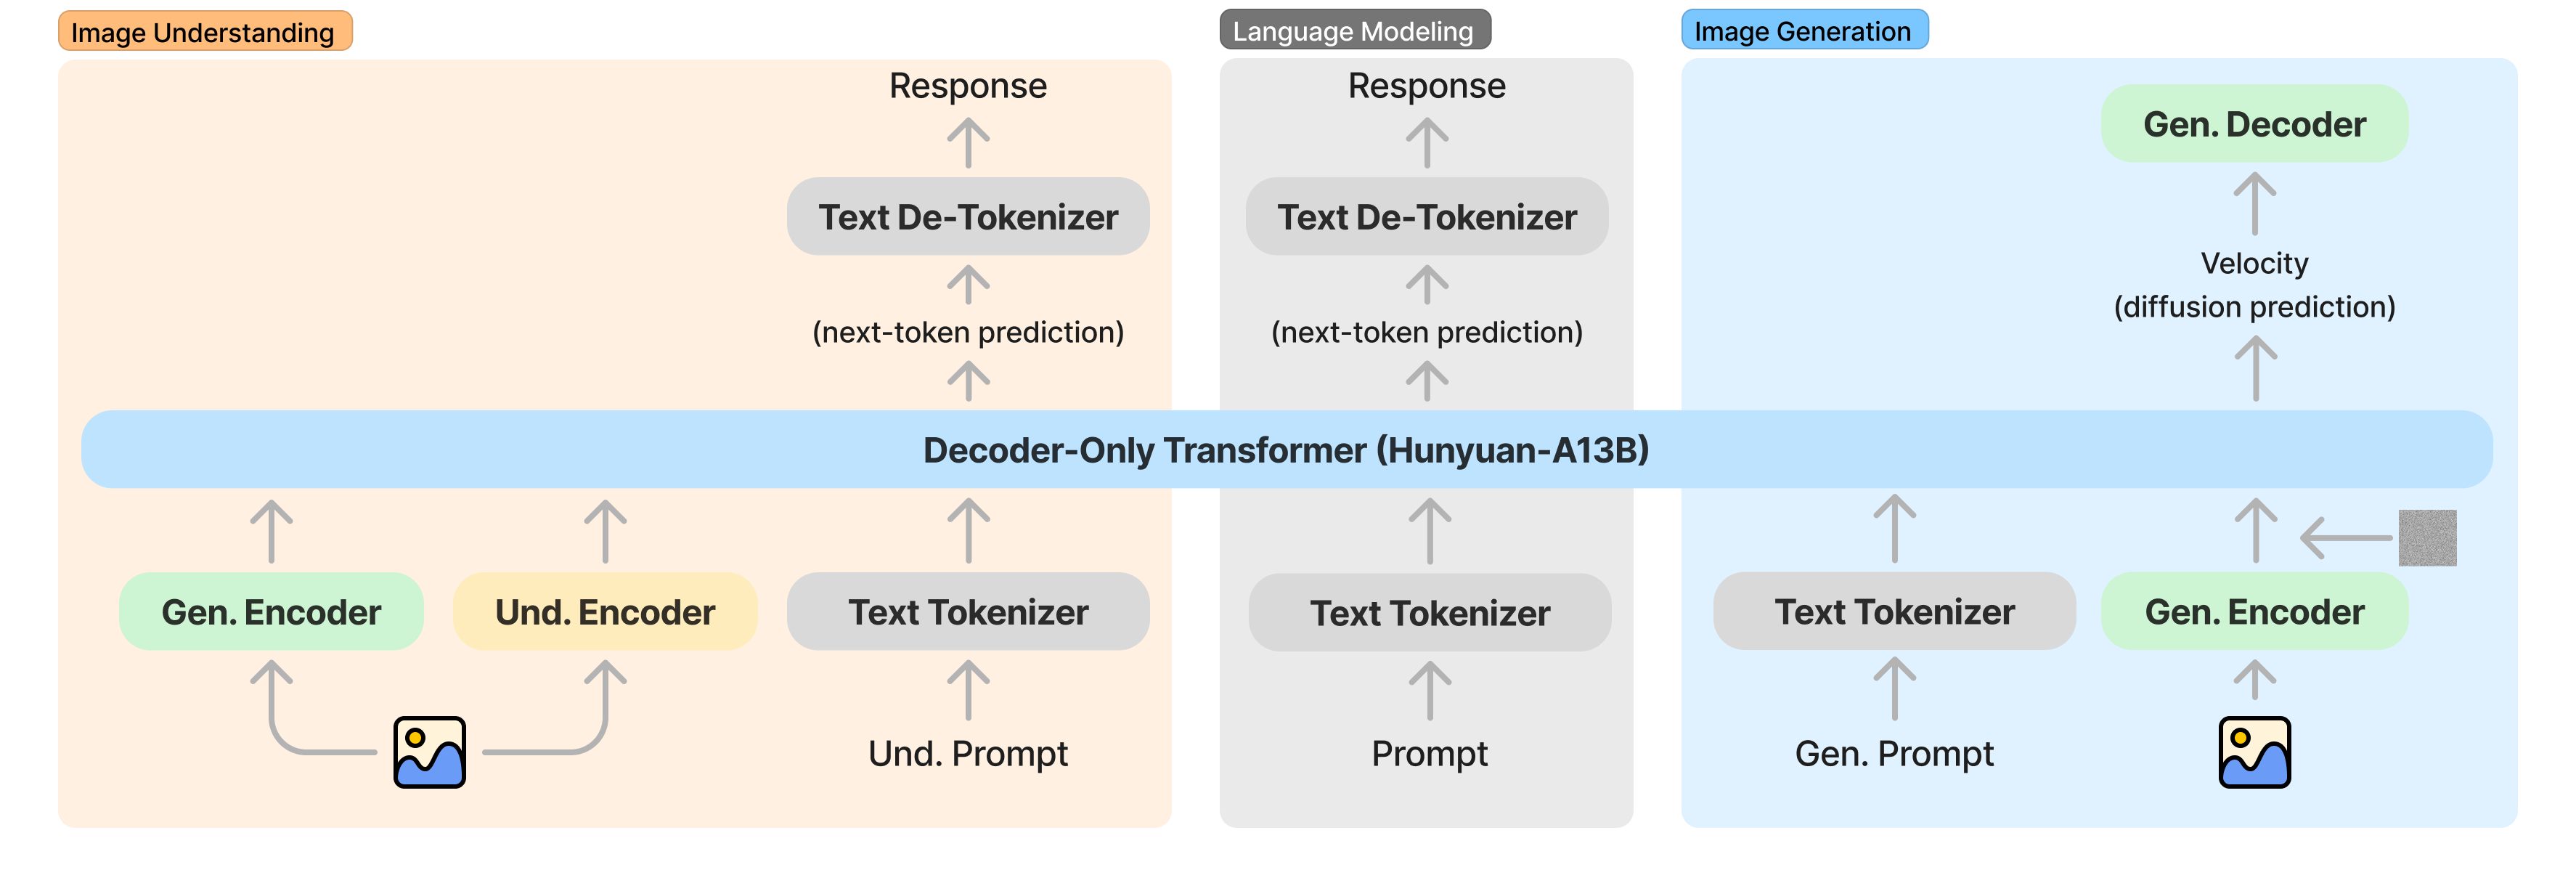
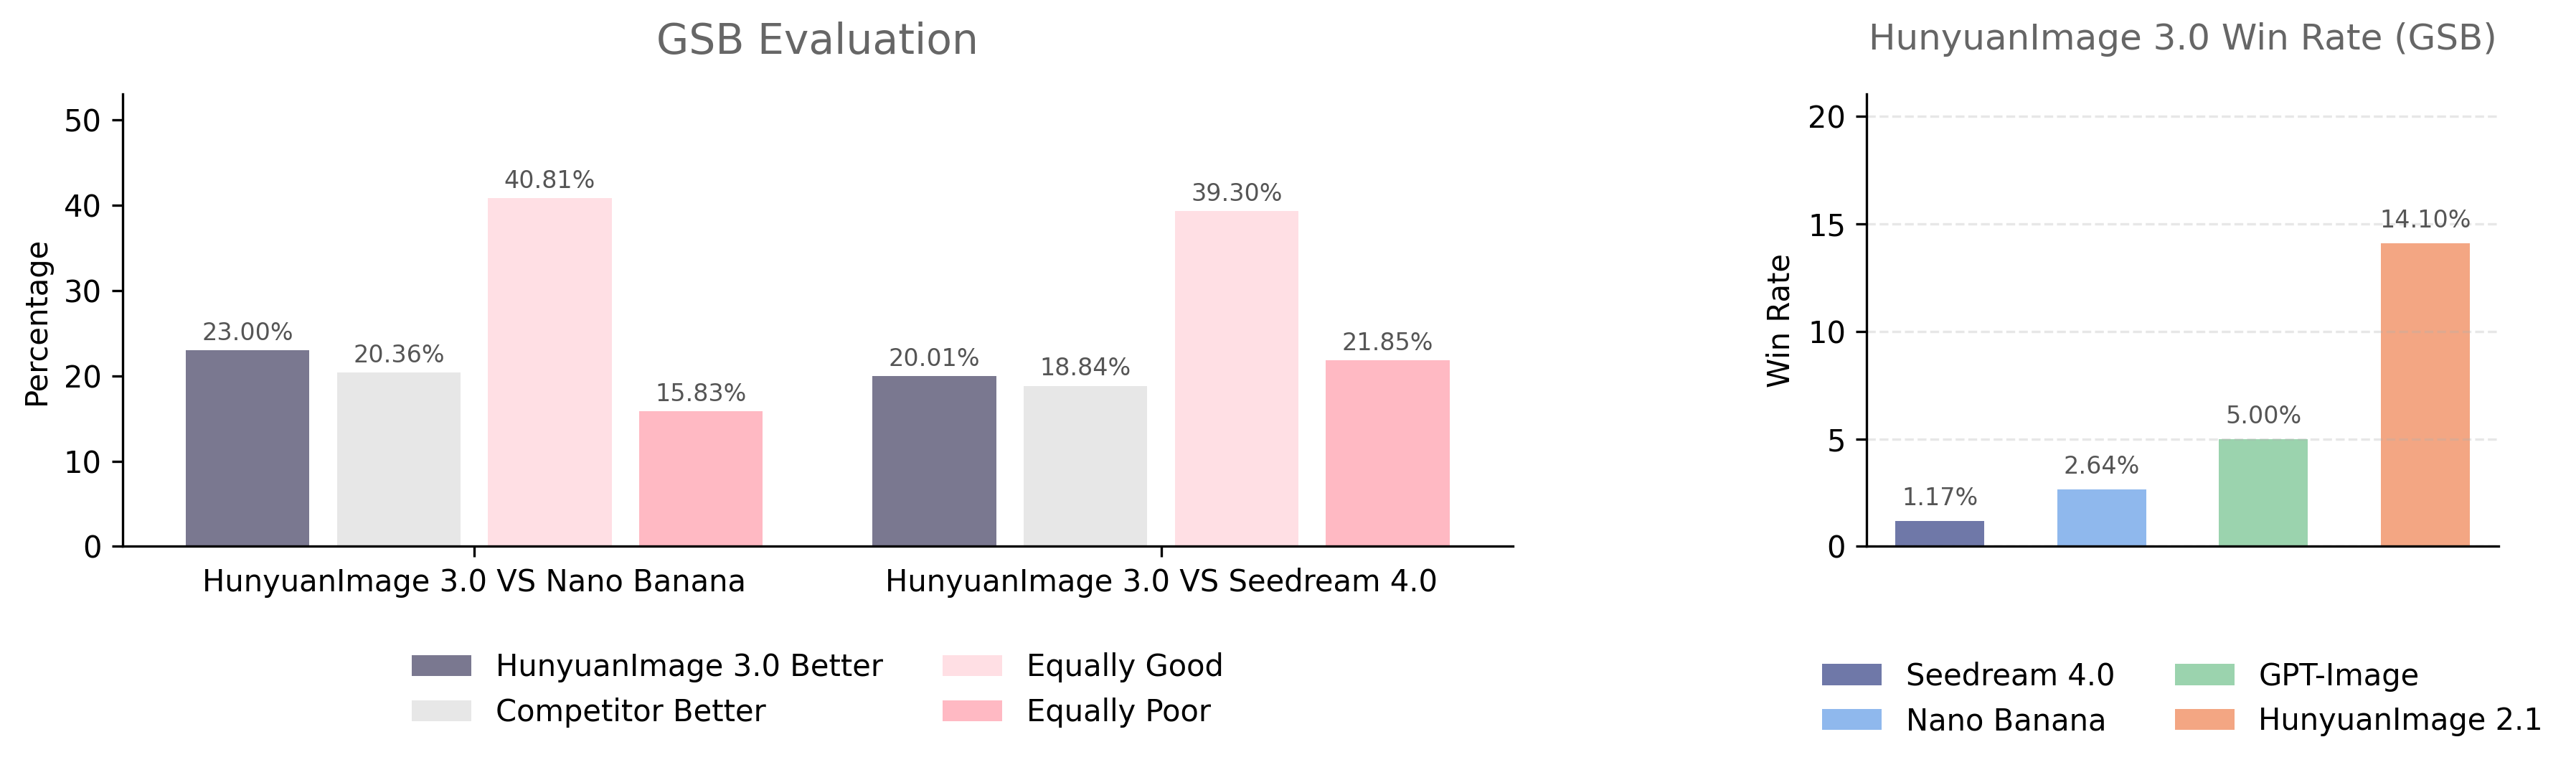
HunyuanImage-3.0 is a groundbreaking native multimodal model that unifies multimodal understanding and generation within an autoregressive framework. Our text-to-image and image-to-image model achieves performance comparable to or surpassing leading closed-source models.
# 1. First install PyTorch (CUDA 12.8 Version)
pip install torch==2.8.0 torchvision==0.23.0 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128
2. Install tencentcloud-sdk for Prompt Enhancement (PE) only for HunyuanImage-3.0 not HunyuanImage-3.0-Instruct
pip install -i https://mirrors.tencent.com/pypi/simple/ --upgrade tencentcloud-sdk-python
3. Then install other dependencies
pip install -r requirements.txt
For up to 3x faster inference, install these optimizations:
# FlashInfer for optimized moe inference. v0.5.0 is tested.
pip install flashinfer-python==0.5.0
💡Installation Tips: It is critical that the CUDA version used by PyTorch matches the system's CUDA version.
FlashInfer relies on this compatibility when compiling kernels at runtime.
GCC version >=9 is recommended for compiling FlashAttention and FlashInfer.
⚡ Performance Tips: These optimizations can significantly speed up your inference!
💡Notation: When FlashInfer is enabled, the first inference may be slower (about 10 minutes) due to kernel compilation. Subsequent inferences on the same machine will be much faster.
# Download from HuggingFace and rename the directory.
Notice that the directory name should not contain dots, which may cause issues when loading using Transformers.
hf download tencent/HunyuanImage-3.0-Instruct --local-dir ./HunyuanImage-3-Instruct
from transformers import AutoModelForCausalLM
Load the model
model_id = "./HunyuanImage-3-Instruct"
Currently we can not load the model using HF model_id tencent/HunyuanImage-3.0-Instruct directly
due to the dot in the name.
kwargs = dict(
    attn_implementation="sdpa",
    trust_remote_code=True,
    torch_dtype="auto",
    device_map="auto",
    moe_impl="eager",   # Use "flashinfer" if FlashInfer is installed
    moe_drop_tokens=True,
)
model = AutoModelForCausalLM.from_pretrained(model_id, kwargs)
model.load_tokenizer(model_id)
Image-to-Image generation (TI2I)
prompt = "基于图一的logo,参考图二中冰箱贴的材质,制作一个新的冰箱贴"
input_img1 = "./assets/demo_instruct_imgs/input_1_0.png"
input_img2 = "./assets/demo_instruct_imgs/input_1_1.png"
imgs_input = [input_img1, input_img2]
cot_text, samples = model.generate_image(
    prompt=prompt,
    image=imgs_input,
    seed=42,
    image_size="auto",
    use_system_prompt="en_unified",
    bot_task="think_recaption",  # Use "think_recaption" for reasoning and enhancement
    infer_align_image_size=True,  # Align output image size to input image size
    diff_infer_steps=50,
    verbose=2
)
Save the generated image
samples[0].save("image_edit.png")
git clone https://github.com/Tencent-Hunyuan/HunyuanImage-3.0.git
cd HunyuanImage-3.0/
# Download from HuggingFace
hf download tencent/HunyuanImage-3.0-Instruct --local-dir ./HunyuanImage-3-Instruct
More demos in run_demo_instruct.sh.
export MODEL_PATH="./HunyuanImage-3-Instruct"
bash run_demo_instruct.sh
| Arguments | Description | Recommended |
| ----------------------- | ------------------------------------------------------------ | ----------- |
| --prompt | Input prompt | (Required) |
| --image | Image to run. For multiple images, use comma-separated paths (e.g., 'img1.png,img2.png') | (Required) |
| --model-id | Model path | (Required) |
| --attn-impl | Attention implementation. Now only support 'sdpa' | sdpa |
| --moe-impl | MoE implementation. Either eager or flashinfer | flashinfer |
| --seed | Random seed for image generation. Use None for random seed | None |
| --diff-infer-steps | Number of inference steps | 50 |
| --image-size | Image resolution. Can be auto, like 1280x768 or 16:9 | auto |
| --use-system-prompt | System prompt type. Options: None, dynamic, en_vanilla, en_recaption, en_think_recaption, en_unified, custom | en_unified |
| --system-prompt | Custom system prompt. Used when --use-system-prompt is custom | None |
| --bot-task | Task type. image for direct generation; auto for text; recaption for re-write->image; think_recaption for think->re-write->image | think_recaption |
| --save | Image save path | image.png |
| --verbose | Verbose level | 2 |
| --reproduce | Whether to reproduce the results | True |
| --infer-align-image-size | Whether to align the target image size to the src image size | True |
| --max_new_tokens | Maximum number of new tokens to generate | 2048 |
| --use-taylor-cache | Use Taylor Cache when sampling | False |
We recommend using the model HunyuanImage-3.0-Instruct-Distil with --diff-infer-steps 8, while keeping all other recommended parameter values unchanged.
# Download HunyuanImage-3.0-Instruct-Distil from HuggingFace
hf download tencent/HunyuanImage-3.0-Instruct-Distil --local-dir ./HunyuanImage-3-Instruct-Distil
Run the demo with 8 steps to samples
export MODEL_PATH="./HunyuanImage-3-Instruct-Distil"
bash run_demo_instruct_Distil.sh
# Download from HuggingFace and rename the directory.
Notice that the directory name should not contain dots, which may cause issues when loading using Transformers.
hf download tencent/HunyuanImage-3.0 --local-dir ./HunyuanImage-3
from transformers import AutoModelForCausalLM
Load the model
model_id = "./HunyuanImage-3"
Currently we can not load the model using HF model_id tencent/HunyuanImage-3.0 directly
due to the dot in the name.
kwargs = dict(
    attn_implementation="sdpa",     # Use "flash_attention_2" if FlashAttention is installed
    trust_remote_code=True,
    torch_dtype="auto",
    device_map="auto",
    moe_impl="eager",   # Use "flashinfer" if FlashInfer is installed
)
model = AutoModelForCausalLM.from_pretrained(model_id, kwargs)
model.load_tokenizer(model_id)
generate the image
prompt = "A brown and white dog is running on the grass"
image = model.generate_image(prompt=prompt, stream=True)
image.save("image.png")
git clone https://github.com/Tencent-Hunyuan/HunyuanImage-3.0.git
cd HunyuanImage-3.0/
# Download from HuggingFace
hf download tencent/HunyuanImage-3.0 --local-dir ./HunyuanImage-3
# Without PE
export MODEL_PATH="./HunyuanImage-3"
python3 run_image_gen.py \
    --model-id $MODEL_PATH \
    --verbose 1 \
    --prompt "A brown and white dog is running on the grass" \
    --bot-task image \
    --image-size "1024x1024" \
    --save ./image.png \
    --moe-impl flashinfer
With PE
export DEEPSEEK_KEY_ID="your_deepseek_key_id"
export DEEPSEEK_KEY_SECRET="your_deepseek_key_secret"
export MODEL_PATH="./HunyuanImage-3"
python3 run_image_gen.py \
    --model-id $MODEL_PATH \
    --verbose 1 \
    --prompt "A brown and white dog is running on the grass" \
    --bot-task image \
    --image-size "1024x1024" \
    --save ./image.png \
    --moe-impl flashinfer \
    --rewrite 1
| Arguments | Description | Recommended |
| ----------------------- | ------------------------------------------------------------ | ----------- |
| --prompt | Input prompt | (Required) |
| --model-id | Model path | (Required) |
| --attn-impl | Attention implementation. Either sdpa or flash_attention_2. | sdpa |
| --moe-impl | MoE implementation. Either eager or flashinfer | flashinfer |
| --seed | Random seed for image generation | None |
| --diff-infer-steps | Diffusion infer steps | 50 |
| --image-size | Image resolution. Can be auto, like 1280x768 or 16:9 | auto |
| --save | Image save path. | image.png |
| --verbose | Verbose level. 0: No log; 1: log inference information. | 0 |
| --rewrite | Whether to enable rewriting | 1 |
Launch an interactive web interface for easy text-to-image generation.
pip install gradio>=4.21.0
# Set your model path
export MODEL_ID="path/to/your/model"
Optional: Configure GPU usage (default: 0,1,2,3)
export GPUS="0,1,2,3"
Optional: Configure host and port (default: 0.0.0.0:443)
export HOST="0.0.0.0"
export PORT="443"
Basic Launch:
sh run_app.sh
With Performance Optimizations:
# Use both optimizations for maximum performance
sh run_app.sh --moe-impl flashinfer --attn-impl flash_attention_2
🌐 Web Interface: Open your browser and navigate to http://localhost:443 (or your configured port)
| Model | Params | Download | Recommended VRAM | Supported |
|---------------------------| --- | --- | --- | --- |
| HunyuanImage-3.0 | 80B total (13B active) | HuggingFace | ≥ 3 × 80 GB | ✅ Text-to-Image
| HunyuanImage-3.0-Instruct | 80B total (13B active) | HuggingFace | ≥ 8 × 80 GB | ✅ Text-to-Image
✅ Text-Image-to-Image
✅ Prompt Self-Rewrite
✅ CoT Think
| HunyuanImage-3.0-Instruct-Distil | 80B total (13B active) | HuggingFace | ≥ 8 × 80 GB |✅ Text-to-Image
✅ Text-Image-to-Image
✅ Prompt Self-Rewrite
✅ CoT Think
✅ Fewer sampling steps (8 steps recommended)
Notes:
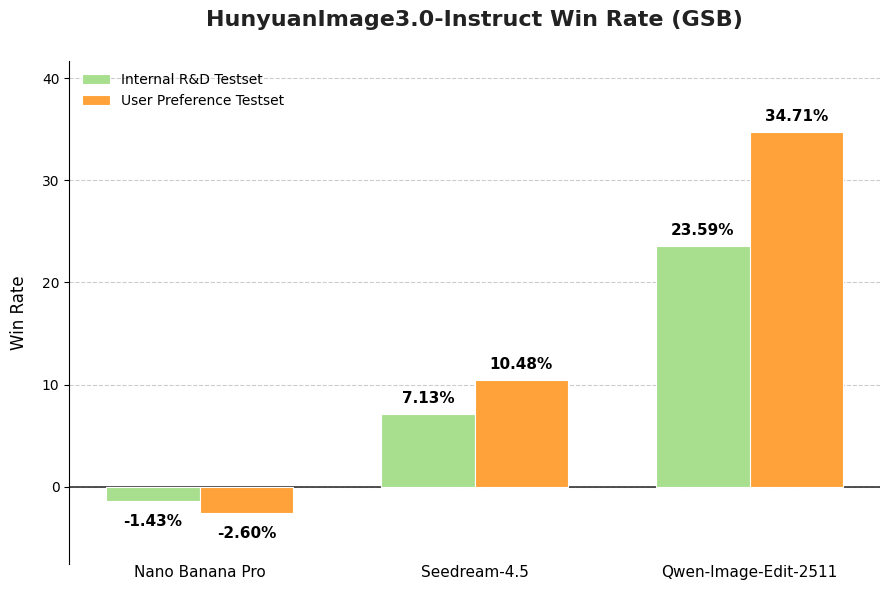
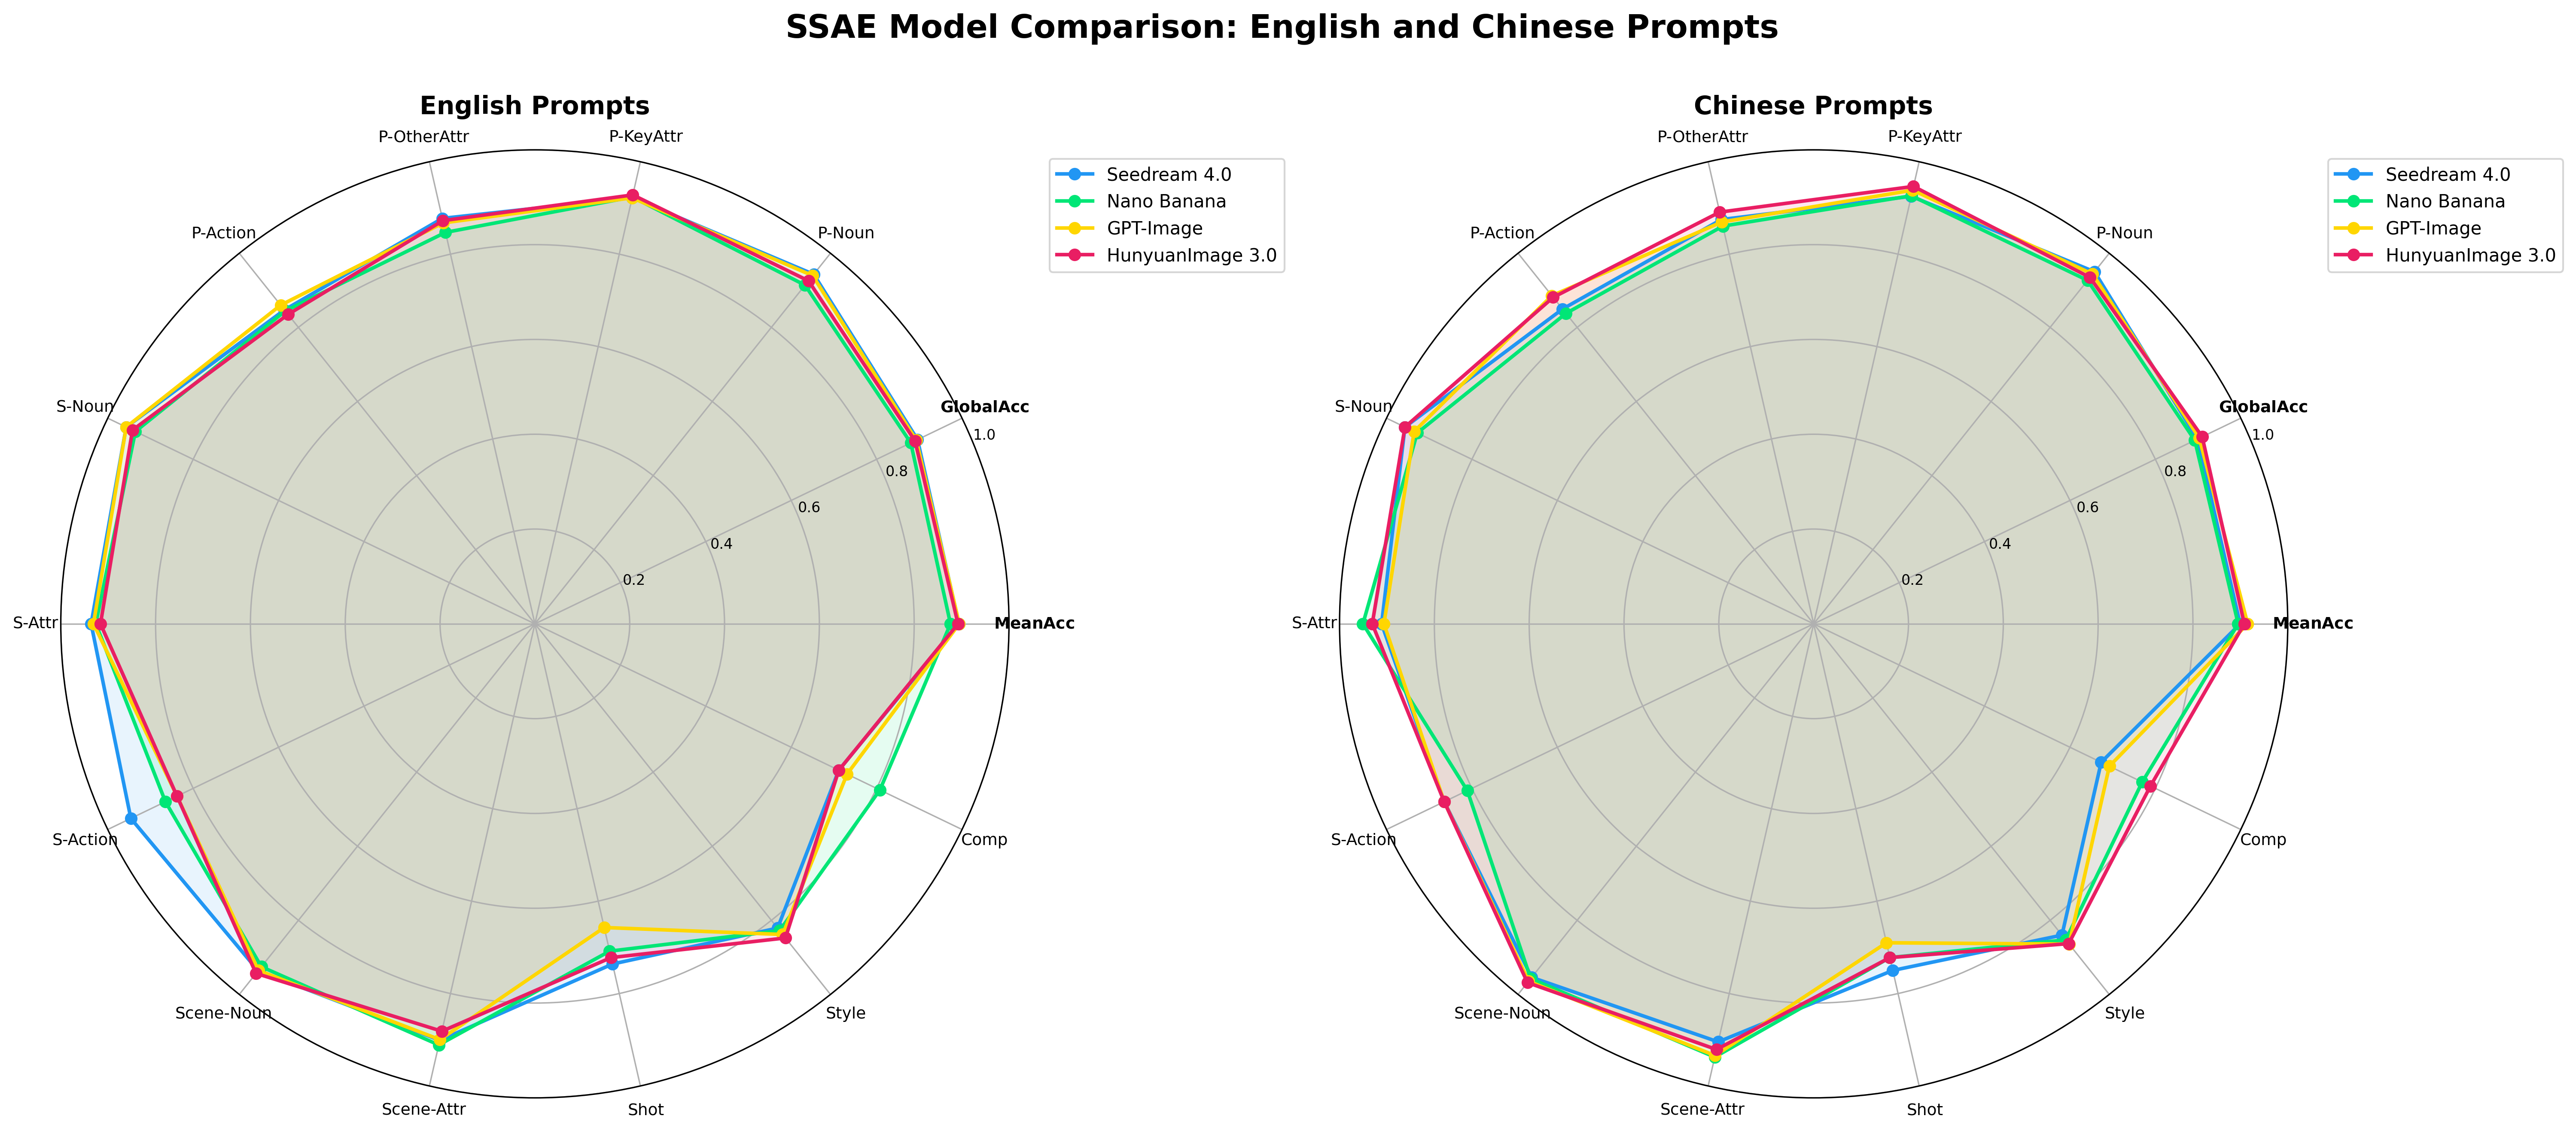
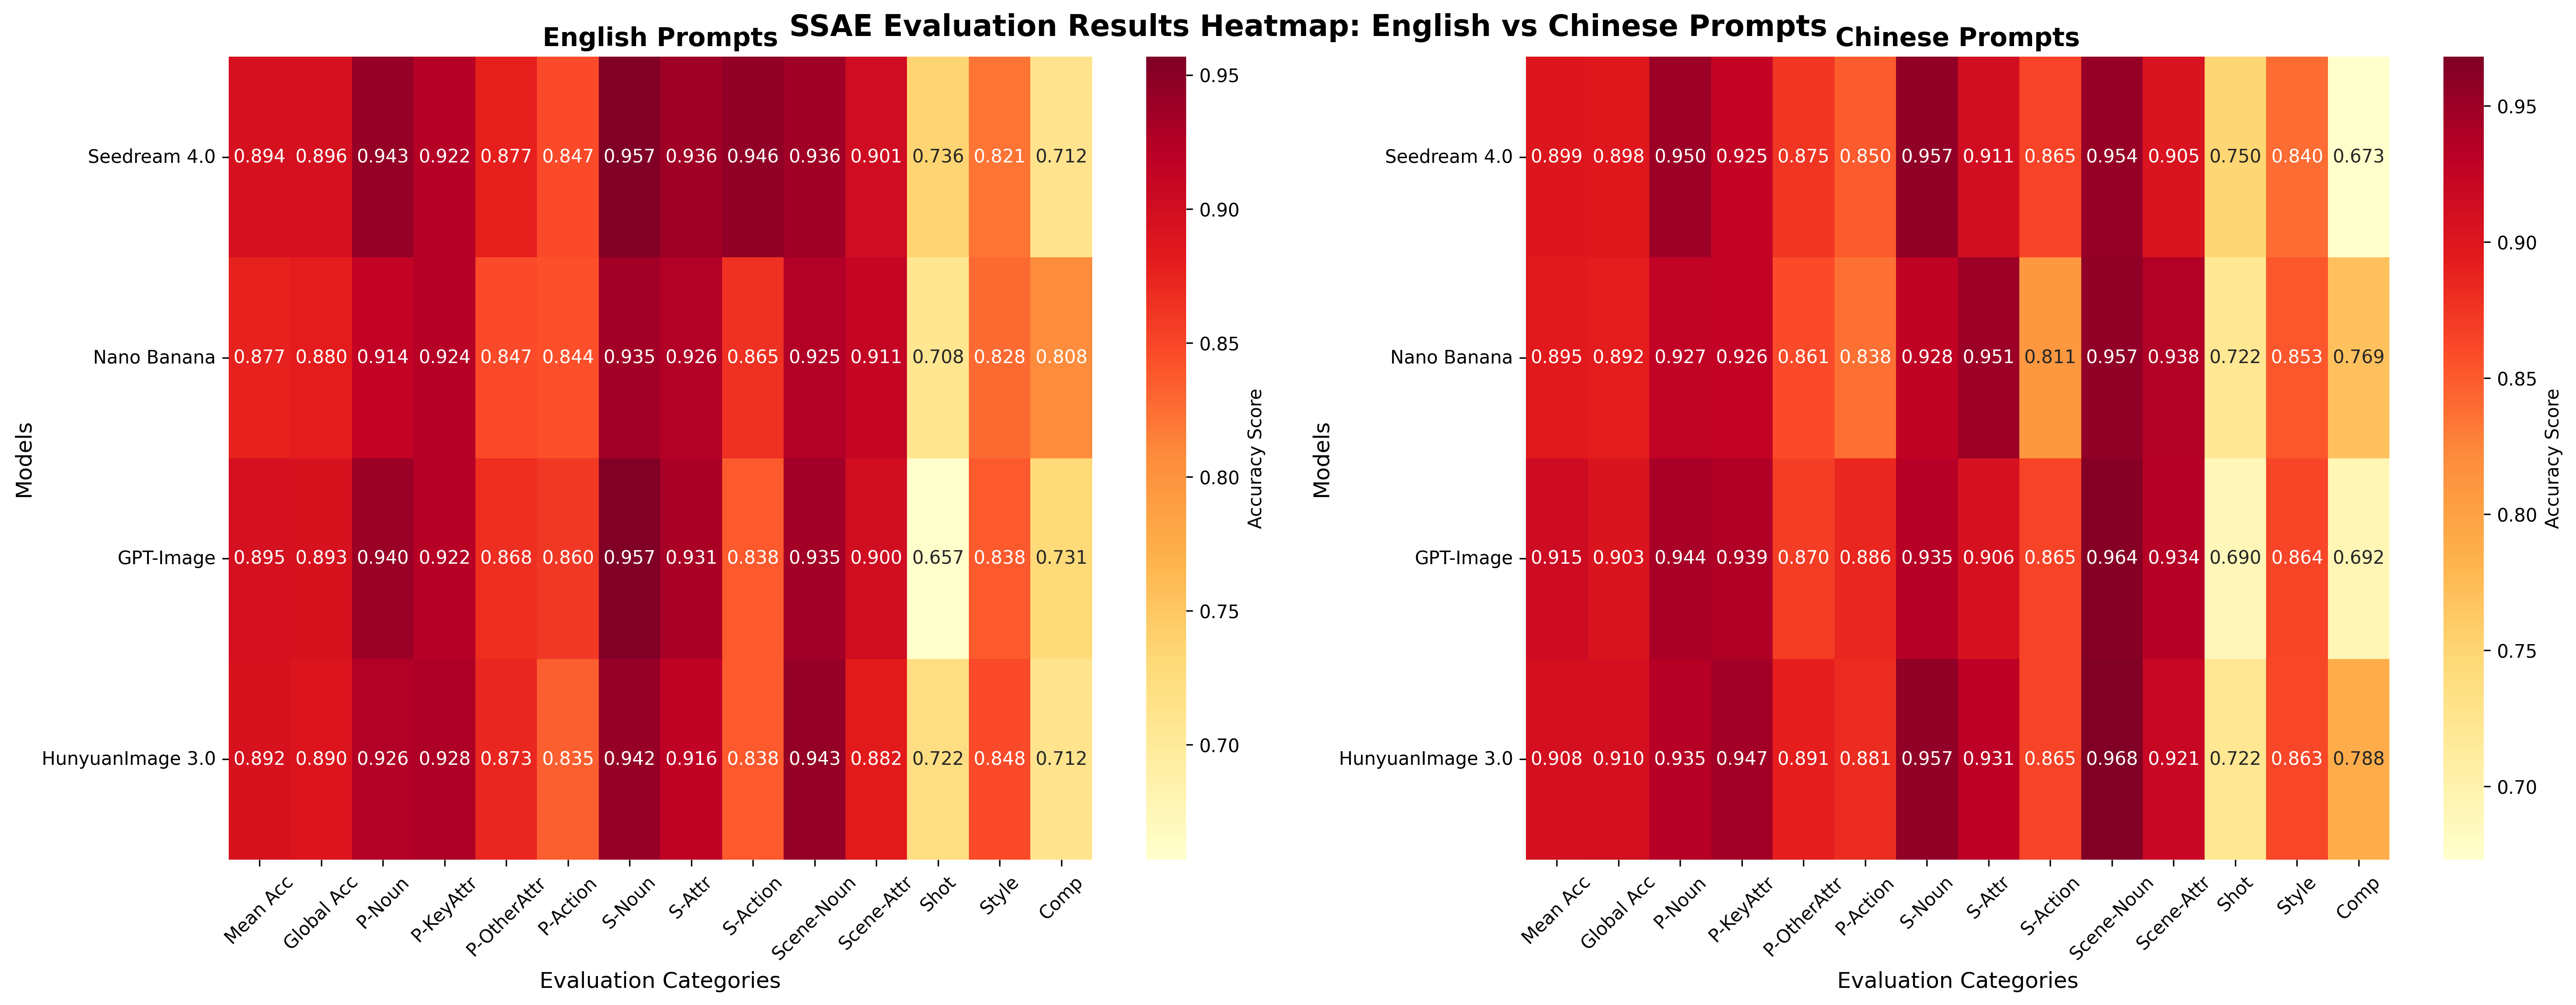
Our model can follow complex instructions to generate high‑quality, creative images.
For text-to-image showcases in HunyuanImage-3.0, click the following links:
HunyuanImage-3.0-Instruct demonstrates powerful capabilities in intelligent image generation and editing. The following showcases highlight its core features:
Showcase 1: Detailed Thought and Reasoning Process
Showcase 2: Creative T2I Generation with Complex Scene Understanding
Prompt: 3D 毛绒质感拟人化马,暖棕浅
→ →
 →
 →→
 →
 →
 →