1
 →
A vector index built on TurboQuant, written in Rust with Python bindings
RyanCodrai/turbovec is an open-source project on GitHub, mainly written in Rust. A vector index built on TurboQuant, written in Rust with Python bindings It currently holds 17,335 stars and 1,483 forks with 22 open issues, and was last pushed on 2026-10-06 (repository created 2026-03-26).
Git Homed tracks it on the Today's Trending board, currently at rank #97 with 26 new stars today.



Python · Rust · How it compares · When to use something else · API reference · Benchmarks
---
Ten million 768-dimensional embeddings take 31 GB of RAM as float32. turbovec holds them in 4 GB and searches them 4.4× faster than FAISS, at matching recall.
turbovec is an in-process vector index for Python and Rust. It stores each vector at 2 or 4 bits per dimension using Google Research's TurboQuant and searches that compressed form directly with agent-optimised SIMD kernels.
sync(path) writes only what changed since the last call — one fsync, crash-safe at any byte, milliseconds however large the index.k results from the allowed set.pip install turbovec
import numpy as np
from turbovec import TurboQuantIndex
vectors = np.load("embeddings.npy").astype(np.float32)   # shape (n, 1536)
index = TurboQuantIndex(dim=1536, bit_width=4)
index.add(vectors)
scores, indices = index.search(vectors[:1], k=5)
print(indices)         # [[    0 86544  3385 84492 24967]]   int64 slot positions
print(scores.shape)    # (1, 5)                             float32 inner products
index.sync("index.tv")                  # first sync writes the file
index.add(more_vectors)
index.sync("index.tv")                  # later syncs write just the change, durably
index = TurboQuantIndex.load("index.tv")   # loads either a sync'd or a write() file
Inputs are 2-D float32 arrays of shape (n, dim); other dtypes raise rather than silently convert. Scores are inner products, so normalise your vectors if you want cosine similarity.
Need ids that survive deletes? IdMapIndex keys everything by your own uint64 ids:
from turbovec import IdMapIndex
index = IdMapIndex(dim=1536, bit_width=4)
index.add_with_ids(vectors, ids)               # ids: uint64 array, one per row
scores, ids = index.search(query, k=10)        # your ids, not slot positions
index.remove(1002)                             # O(1)
Filter: only ids another system approved — a SQL predicate, an ACL, a time window.
allowed = np.array([1001, 1003, 1042], dtype=np.uint64)
scores, ids = index.search(query, k=10, allowlist=allowed)   # shape (1, min(k, 3))
Framework integrations are drop-in replacements for each framework's in-memory store — same public surface, same persistence, same retriever wiring:
LangChain (pip install turbovec[langchain]) ·
LlamaIndex (turbovec[llama-index]) ·
Haystack (turbovec[haystack]) ·
Agno (turbovec[agno]).
cargo add turbovec
use turbovec::{IdMapIndex, TurboQuantIndex};
let mut index = TurboQuantIndex::new(1536, 4)?;
index.add(&vectors);                          // &[f32], row-major, n × 1536
let results = index.search(&queries, 10);     // scores and slot indices, nq × 10
index.write("index.tv")?;
let index = TurboQuantIndex::load("index.tv")?;
let mut ids = IdMapIndex::new(1536, 4)?;
ids.add_with_ids(&vectors, &[1001, 1002, 1003])?;
let (scores, found) = ids.search(&queries, 10);
ids.remove(1002);
The Rust API mirrors the Python one; docs/api.md covers both, including the file formats, sync(), calibration and the staged search.
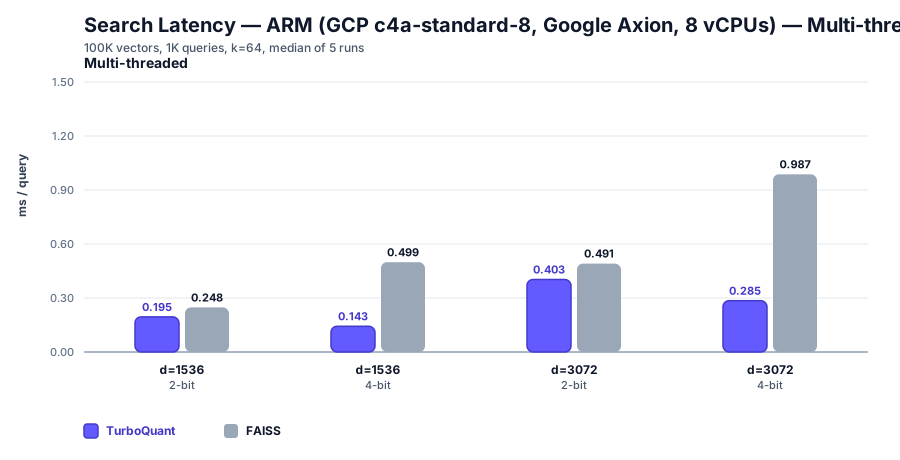
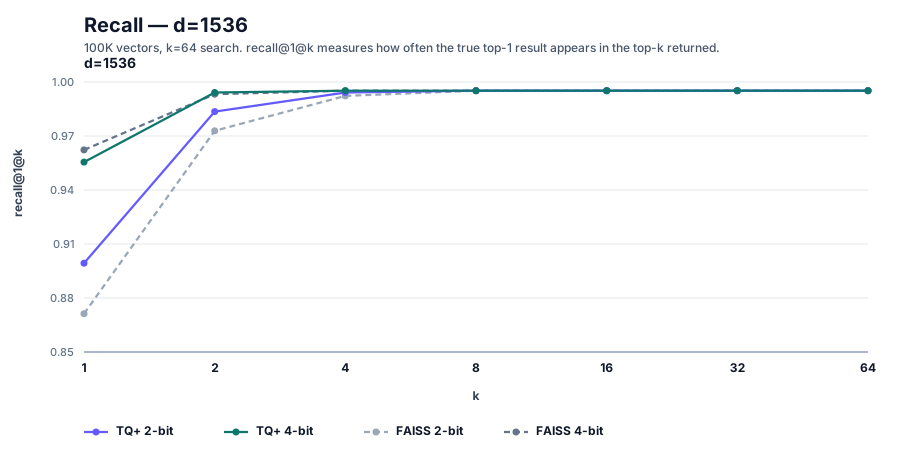
All figures: 100K OpenAI embeddings (d=1536 and d=3072) and GloVe (d=200), k=64, 1K queries, median of 5 runs, on a GCP c4a-standard-8 (ARM) and c3-standard-8 (x86), against FAISS at a matched bit rate. Scripts, raw JSON and every chart are in docs/benchmarks.md.
| | turbovec | FAISS | |
|---|---|---|---|
| Search, 4-bit | 3.8–5.1× faster across the eight cells (ARM 4.0×, x86 4.9×) | IndexPQFastScan | every cell |
| Search, 2-bit | 1.8–2.5× faster (ARM 2.05×, x86 2.35×) | IndexPQFastScan | every cell |
| Recall@1, OpenAI | 0.959 / 0.981 at 4-bit, 0.901 / 0.931 at 2-bit (d=1536 / d=3072) | 0.966 / 0.971, 0.876 / 0.911 | IndexPQ, m matched to bit rate |
| Recall@1, GloVe d=200 | 0.860 at 4-bit, 0.572 at 2-bit | 0.842, 0.565 | IndexPQ, m matched to bit rate |
| Memory, d=1536 | 75 MB at 4-bit, 38 MB at 2-bit | 586 MB float32 | 7.8× / 15.5× |
| Single add() | 7.9–21.7 µs | 6.3–12.6× slower | into a trained, populated index |
| remove(id) | 1.4–5.8 µs | 0.19–1.03 s | FAISS repacks all codes per call |
| Whole-file save | 1.0–1.4× slower than FAISS | write_index | turbovec fsyncs and renames atomically |
| Load → first search | 1.0–1.5× slower than FAISS | read_index | 40 vs 31 ms at d=1536 4-bit on x86 |
Both always return the true nearest neighbour within the first 8 results on the OpenAI corpora. The full suite — every chart, the raw JSON and the scripts to re-run it — is in docs/benchmarks.md.
Normalise each vector and store its length. Rotate every vector by one shared random orthogonal matrix, after which each coordinate follows a known distribution whatever the input. Quantise each coordinate with a Lloyd-Max codebook computed for that distribution — 4 levels at 2-bit, 16 at 4-bit — and bit-pack. At search time the query is rotated once and scored against the codebook with SIMD lookup tables; a per-vector scalar fixed at encode time removes the inner-product bias quantization introduces. An optional one-shot calibrate(sample) fits two scalars per coordinate for data that drifts from the asymptotic distribution (low-dimensional and word-vector embeddings gain most).
The full walk-through, with the maths and the references, is in docs/how-it-works.md.
pip install maturin
cd turbovec-python && maturin build --release && pip install target/wheels/*.whl
cargo build --release
x86_64 builds target x86-64-v2 (SSE4.2, Nehalem 2008+) via .cargo/config.toml; the AVX-512 and AVX2 kernels are #[target_feature]-gated and chosen at runtime with is_x86_feature_detected!, so one binary runs everywhere and uses what the CPU has. Running the benchmark suite is described in docs/benchmarks.md.
→ →
 →
 →
 →
 →
 →
 →