1
 →
Open source observability platform for logs, metrics, traces, RUM, Session replay, pipelines, SLO and LLM observability.
openobserve/openobserve is an open-source project on GitHub, mainly written in TypeScript. Open source observability platform for logs, metrics, traces, RUM, Session replay, pipelines, SLO and LLM observability. It currently holds 21,958 stars and 1,090 forks with 569 open issues, and was last pushed on 2026-09-16 (repository created 2023-02-02).
Git Homed tracks it on the Today's Trending board, currently at rank #64 with 100 new stars today.

Open source Datadog alternative for logs, metrics, traces, and frontend monitoring. Modern observability platform: 10x easier, 140x lower storage cost, high performance, petabyte scale.
Cloud · Documentation · Slack · Quickstart
---
OpenObserve (O2) is a cloud-native observability platform for logs, metrics, traces, analytics, Real User Monitoring (RUM), and AI/LLM observability. It's a cost-effective alternative to Datadog, Splunk, and Elasticsearch for teams that need full observability without the complexity or cost — with Parquet columnar storage and an S3-native design that cuts storage costs by up to 140x.
A single platform for all of your observability signals. Here's why teams choose OpenObserve:
| Benefit | Description | | --- | --- | | 140x lower storage cost | Parquet columnar storage + S3-native architecture dramatically reduce costs vs Elasticsearch | | Single binary deployment | Up and running in under 2 minutes — no complex cluster setup required | | OpenTelemetry native | Built on the OpenTelemetry standard — no vendor lock-in | | Unified platform | Logs, metrics, traces, RUM, dashboards, alerts, and incidents in one tool | | High performance | Better query performance than Elasticsearch on a quarter of the hardware | | SQL + PromQL | Query logs and traces with SQL, metrics with SQL or PromQL — no proprietary query language | | Built in Rust | Memory-safe, high-performance, single binary |
Cost comparison: OpenObserve vs Elasticsearch

Get started in minutes without managing infrastructure. The free tier includes up to 50 GB/day of ingestion.
docker run -d \
      --name openobserve \
      -v $PWD/data:/data \
      -p 5080:5080 \
      -e ZO_ROOT_USER_EMAIL="[email protected]" \
      -e ZO_ROOT_USER_PASSWORD="Complexpass#123" \
      public.ecr.aws/zinclabs/openobserve:latest
Then open http://localhost:5080 and log in with the credentials above.
For other installation methods, see the quickstart documentation. For clustered deployments, see the High Availability deployment guide.
OpenObserve ships with a powerful, unified web UI for every signal — logs, traces, metrics, dashboards, RUM, alerts, incidents, pipelines, and AI observability.
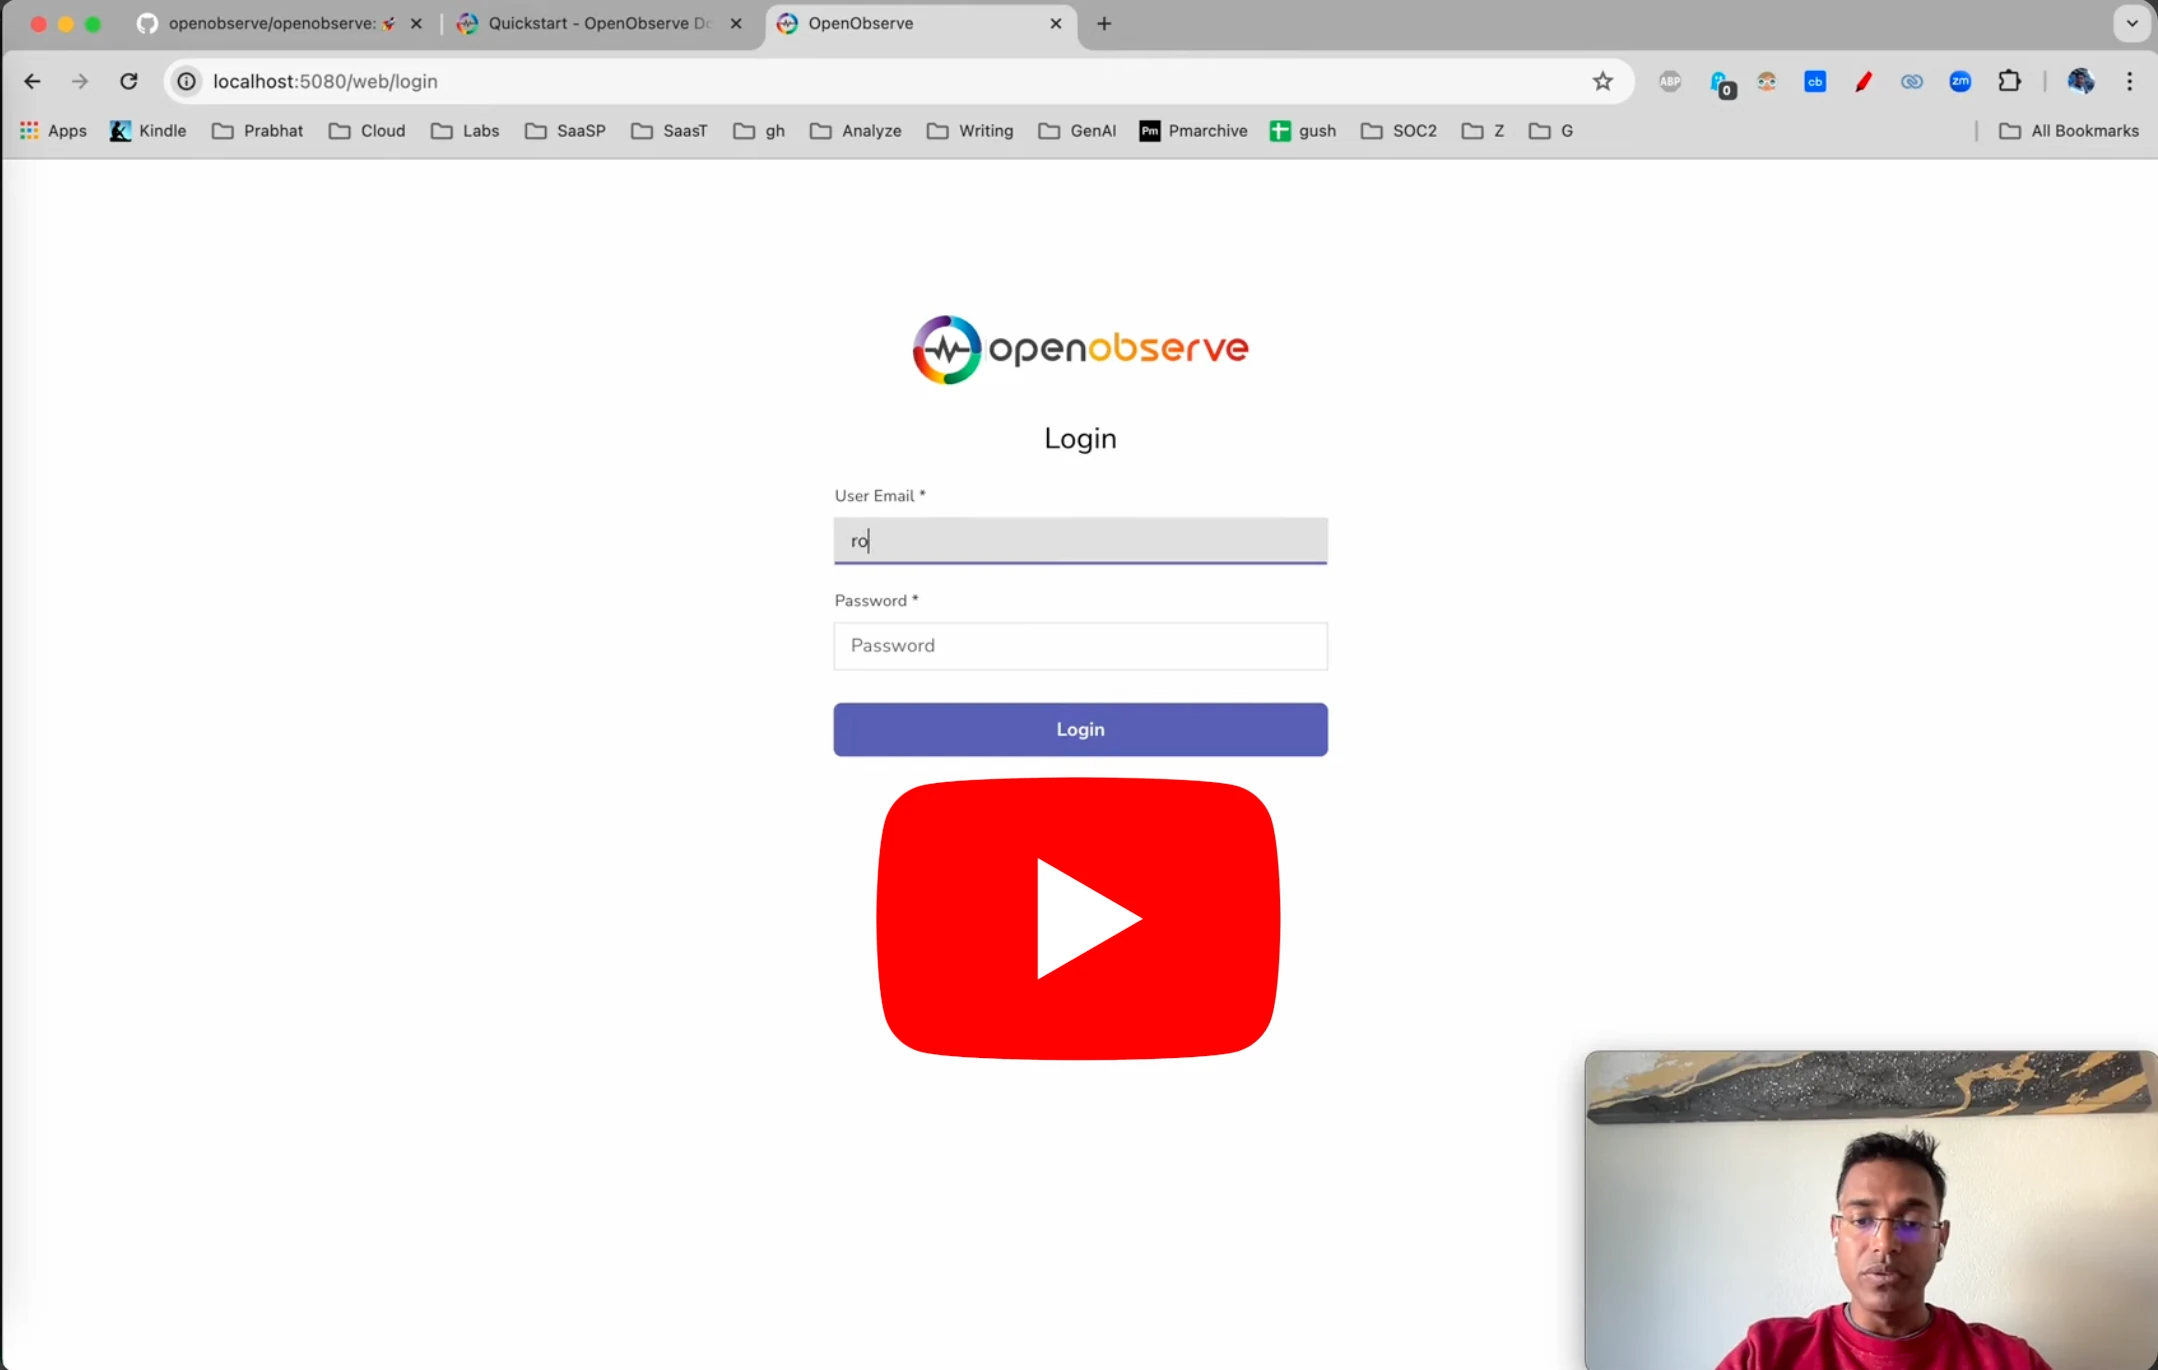
A single home for your workspace — active incidents, service health (error rate, latency, requests), anomalies, and recent events at a glance.
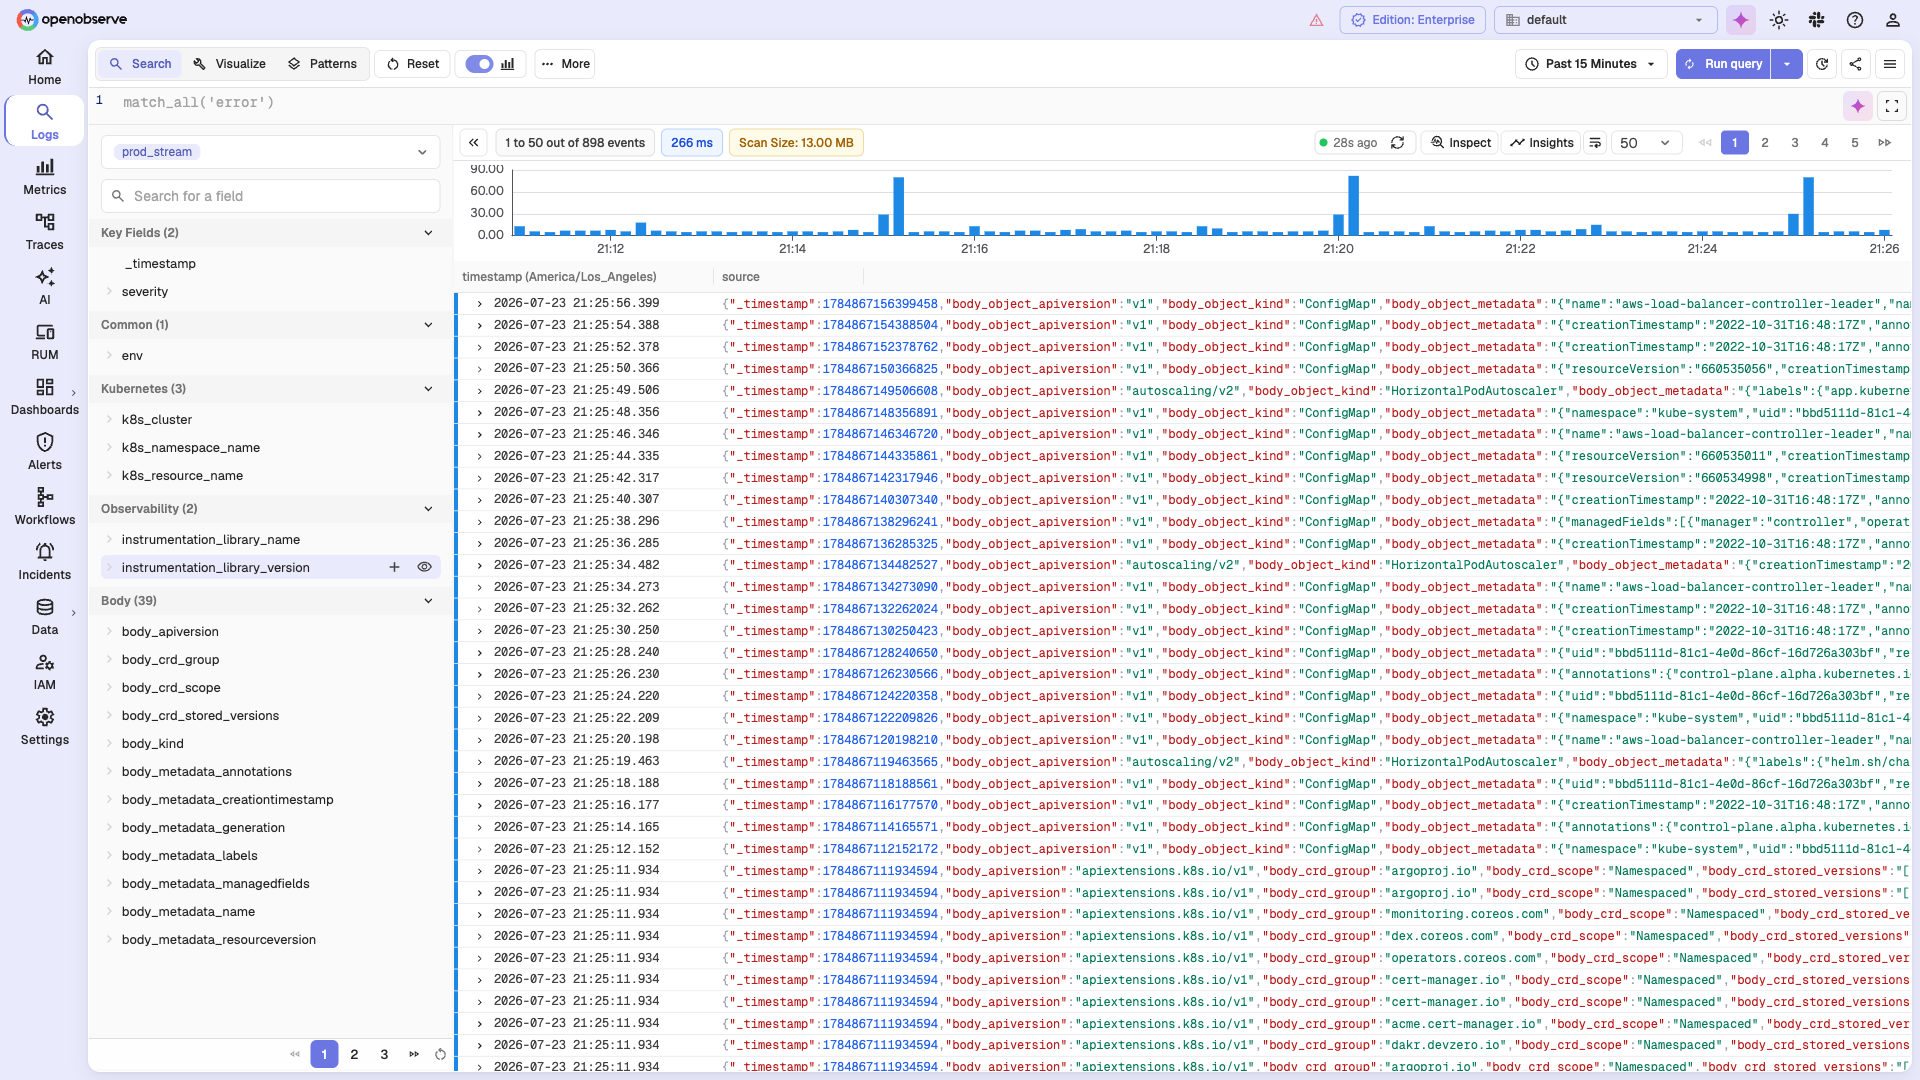
Centralized log management with full-text search, SQL queries, quick filters, and a visual query builder. Instantly search across all your logs, build dashboards from log data, and set up alerts — all on Parquet columnar storage for 140x lower storage cost than Elasticsearch. Read more →
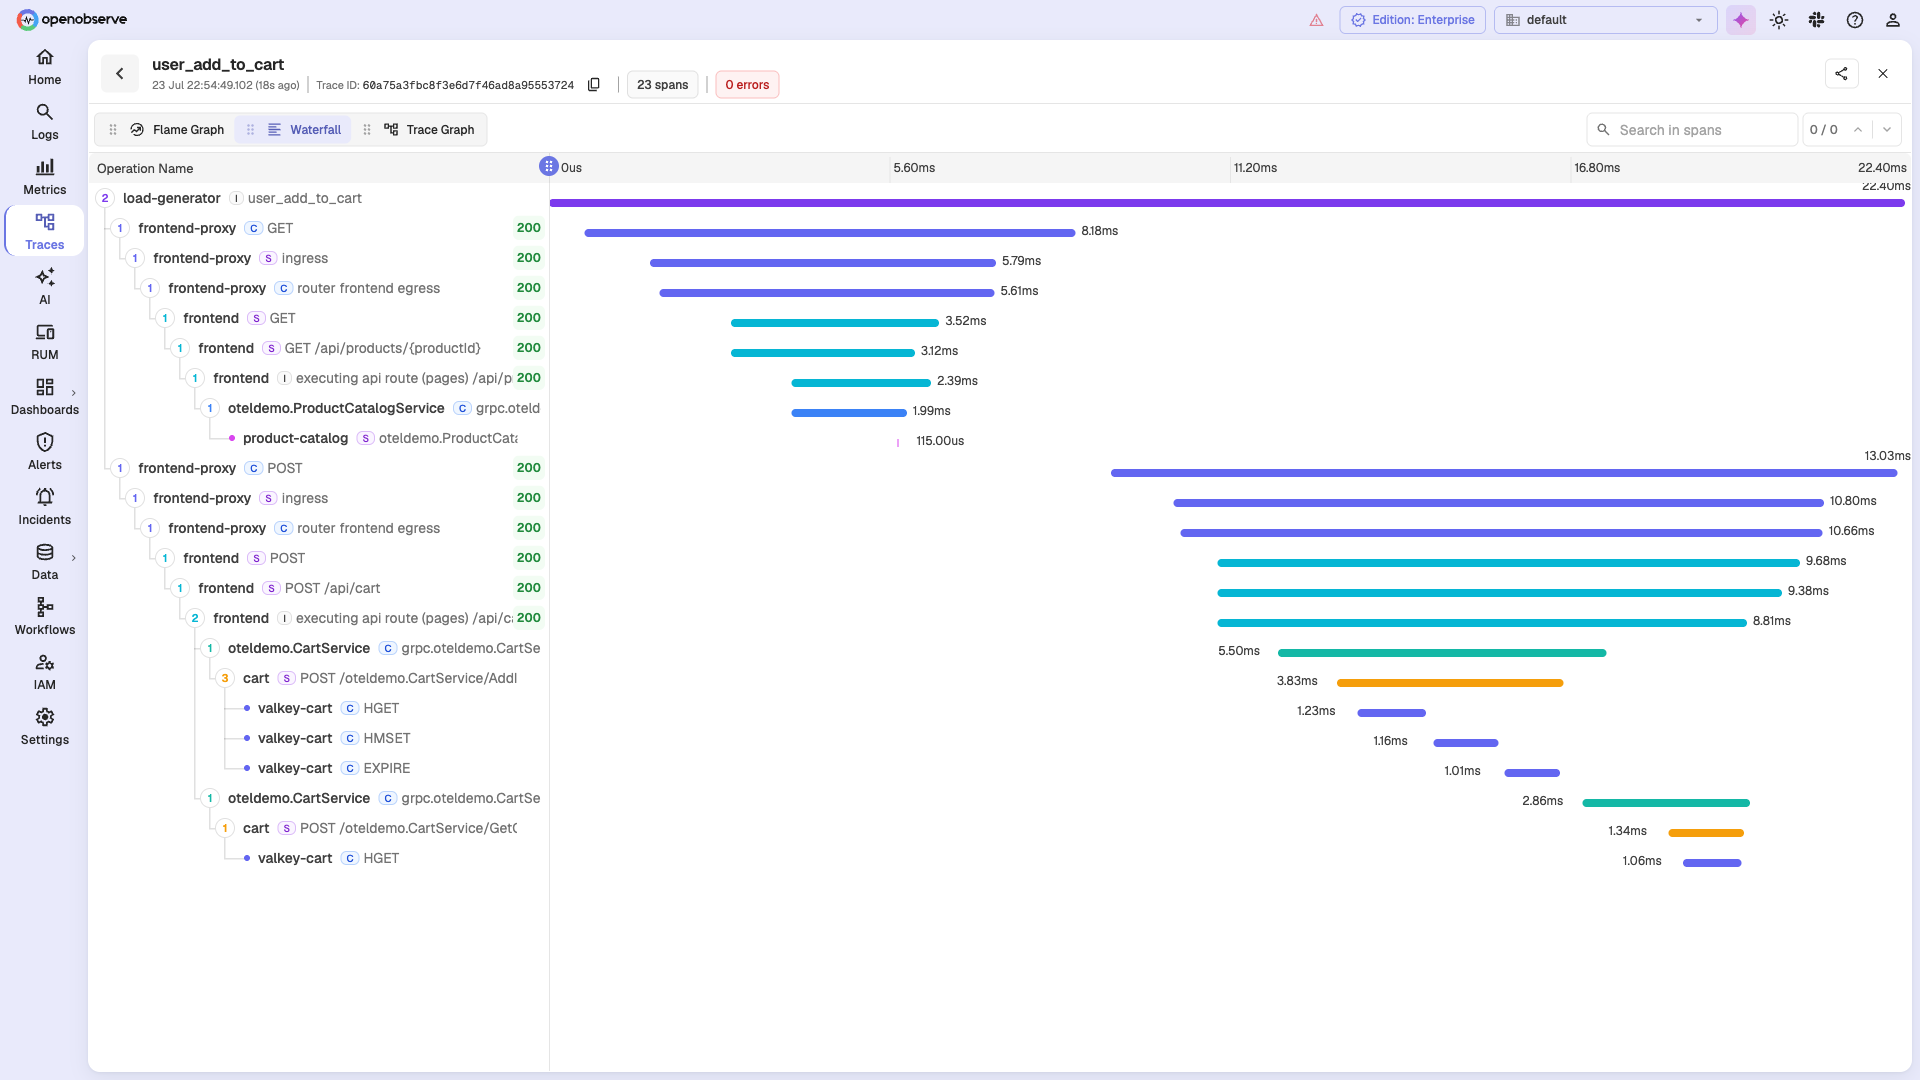
Powered by OpenTelemetry, tracing helps you follow requests across services and pinpoint performance bottlenecks. Explore the full request flow with waterfalls, flame graphs, and Gantt charts; click any span to drill into the trace. Read more →
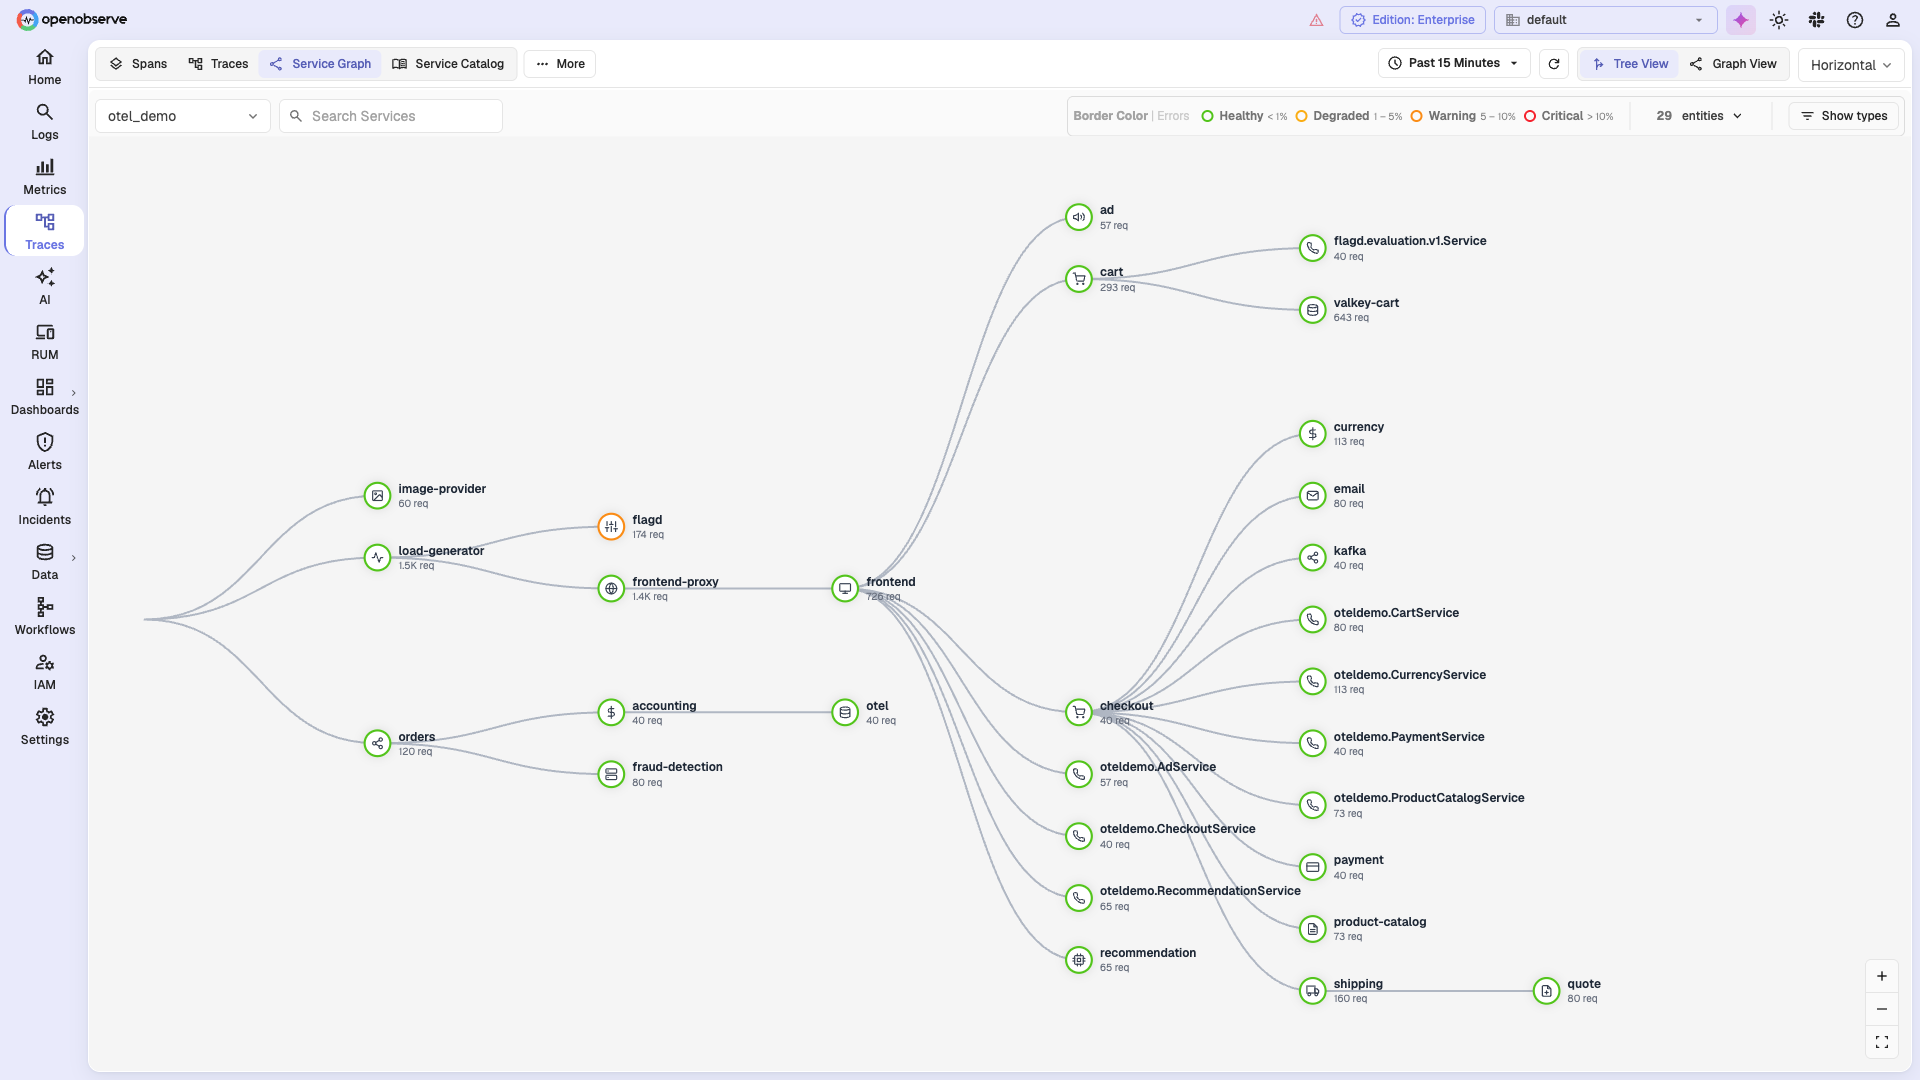
Visualize service-to-service dependencies and request flow across your system, with per-edge request counts and health-based coloring (healthy, degraded, warning, critical) to spot problem hotspots at a glance.
Explore metrics from your infrastructure and applications, then query them with SQL or PromQL. Browse thousands of metrics with faceted filters, preview them inline, combine multiple queries with formulae, and visualize the results with 19+ chart types. Read more →

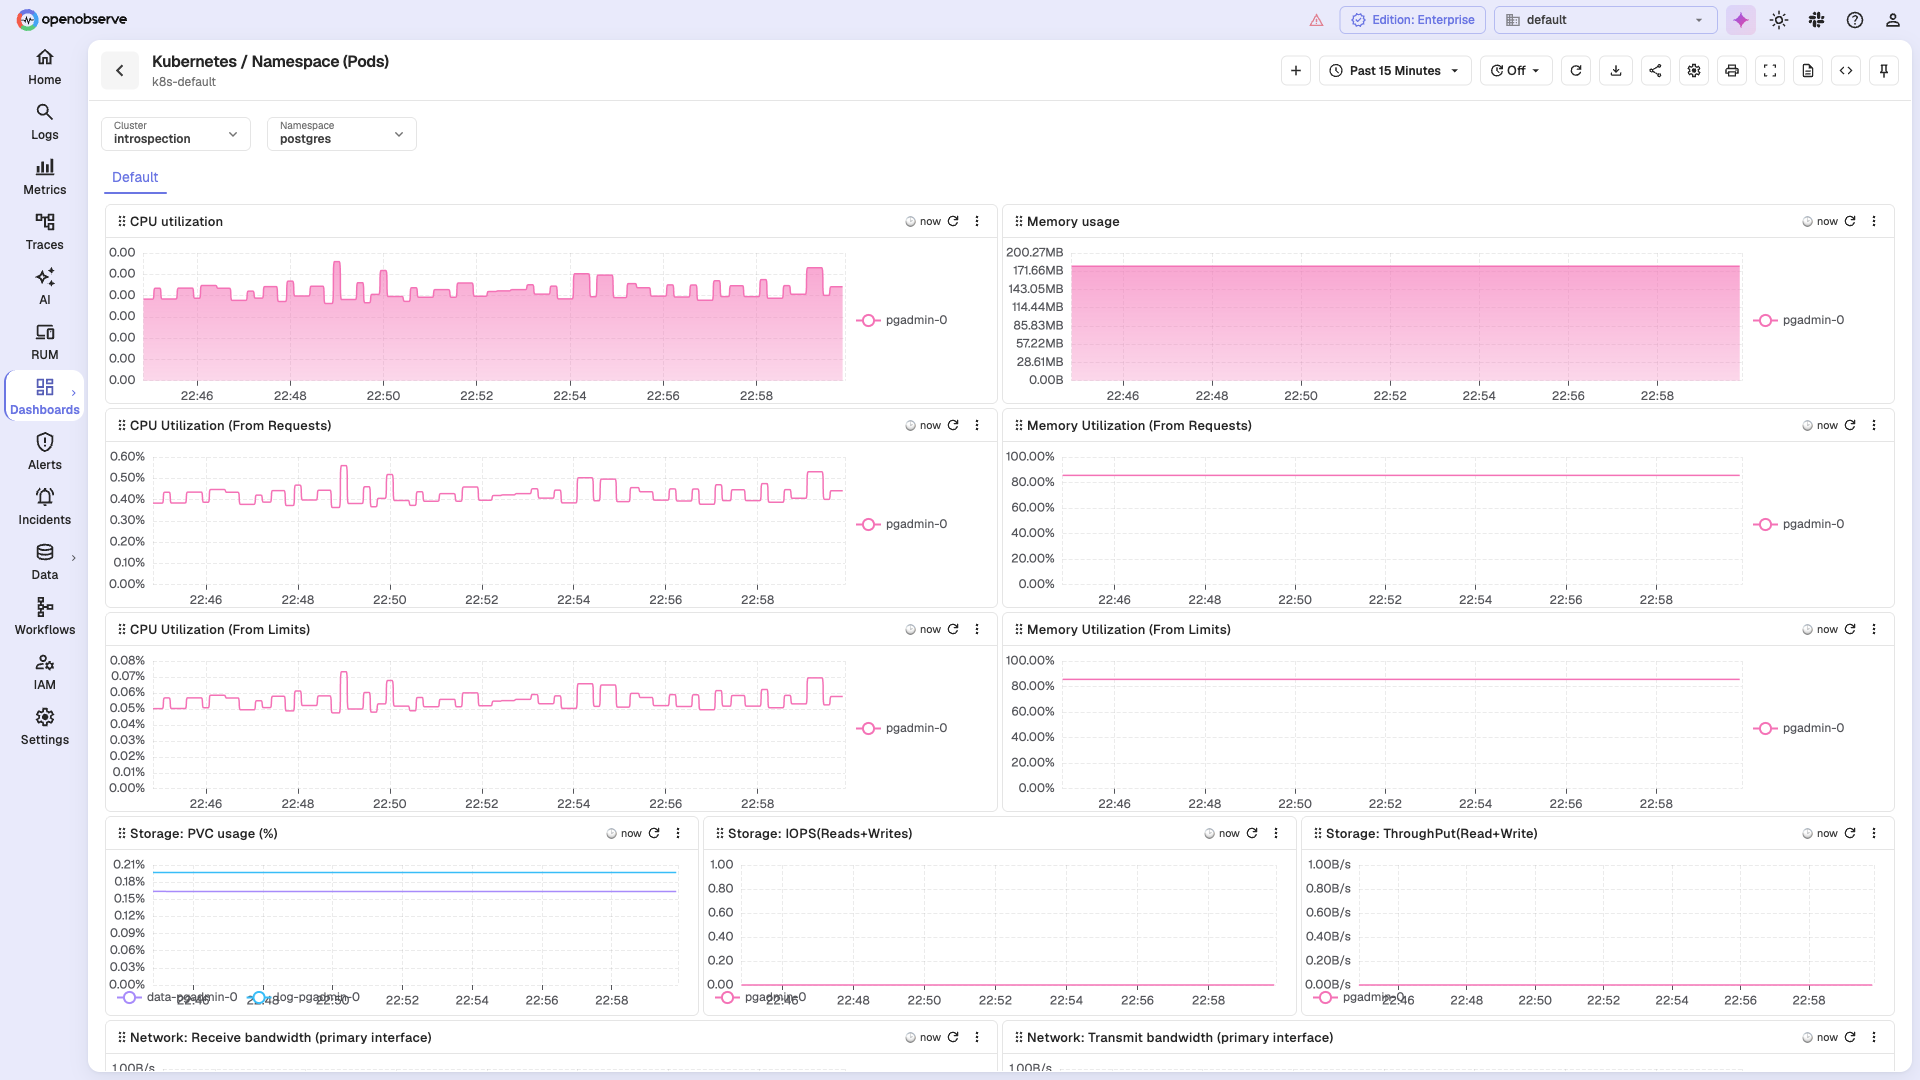
Build custom dashboards from any signal with 19+ built-in chart types and 200+ visualization variations, a drag-and-drop panel builder, template variables, and geo maps. Read more →
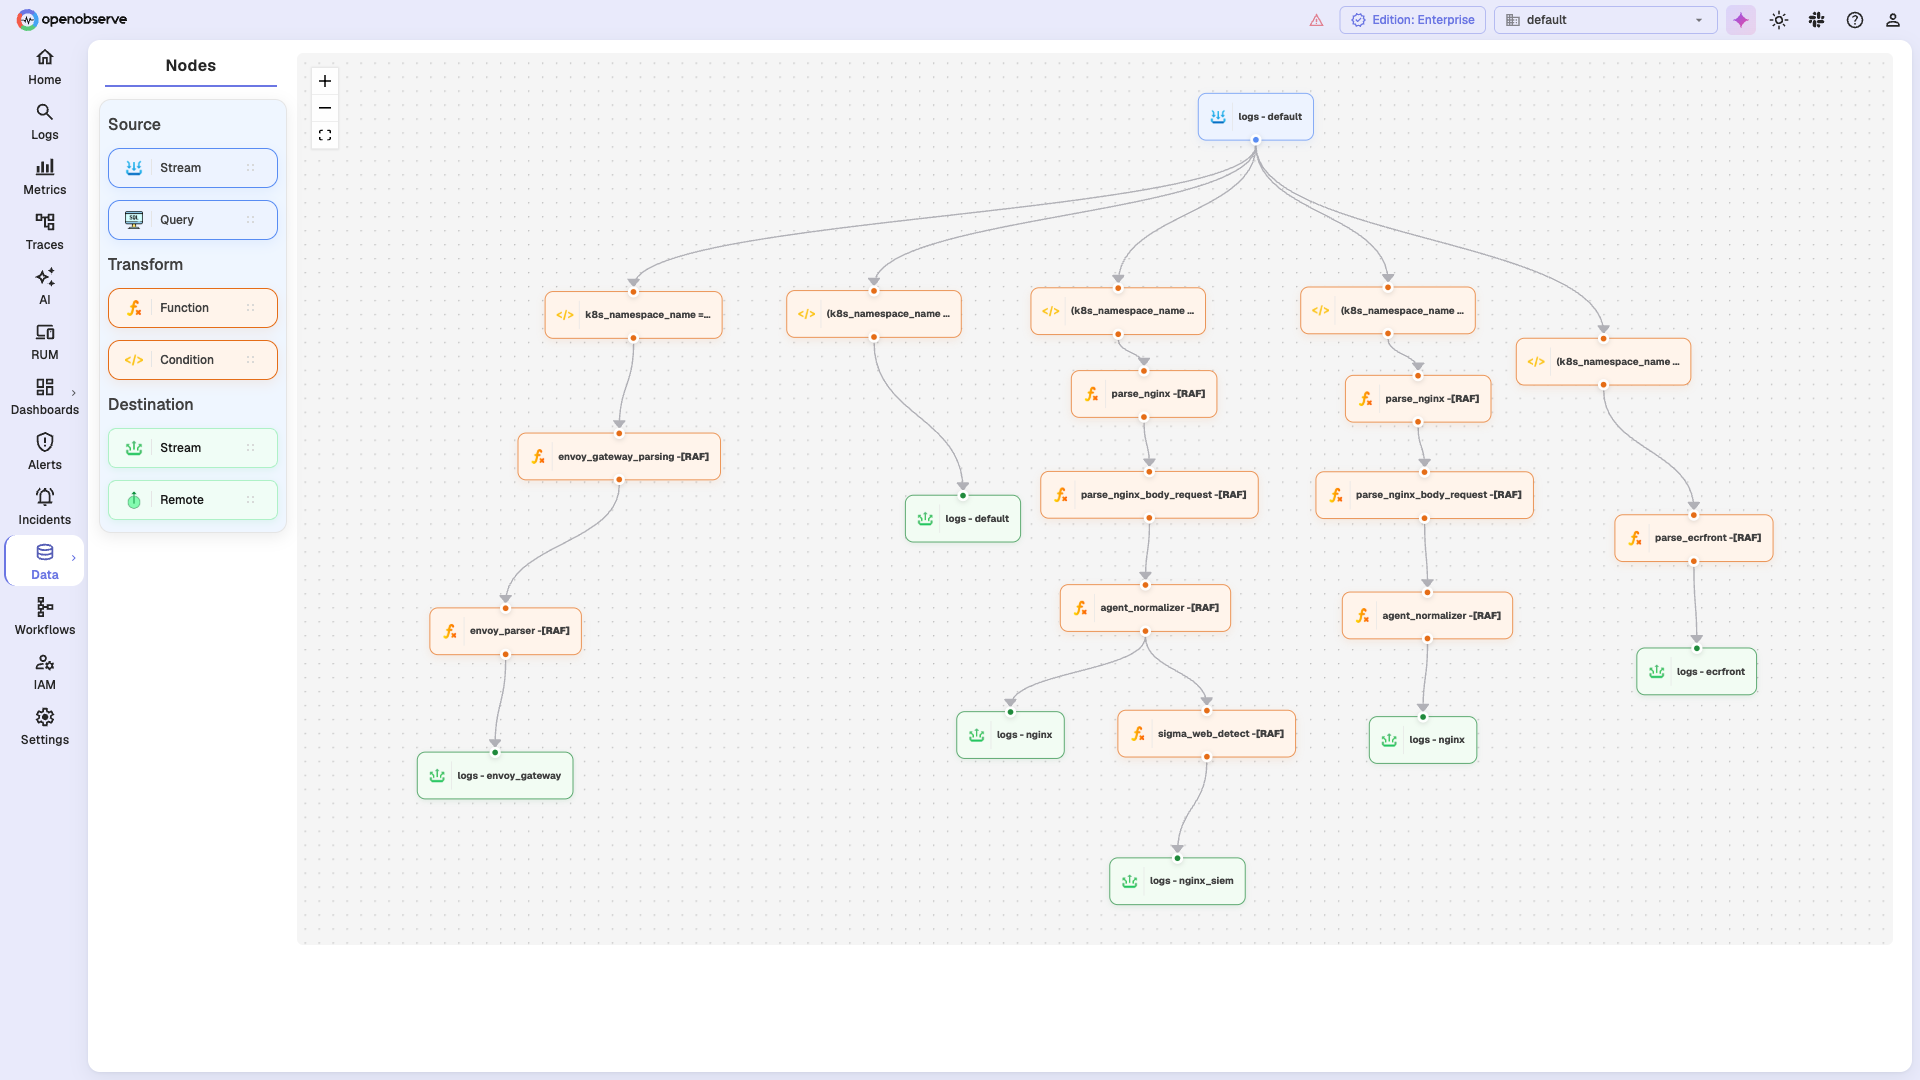
Real User Monitoring with Core Web Vitals, error tracking, performance analytics, and full session replay — so you can see exactly what your users experience. Read more →
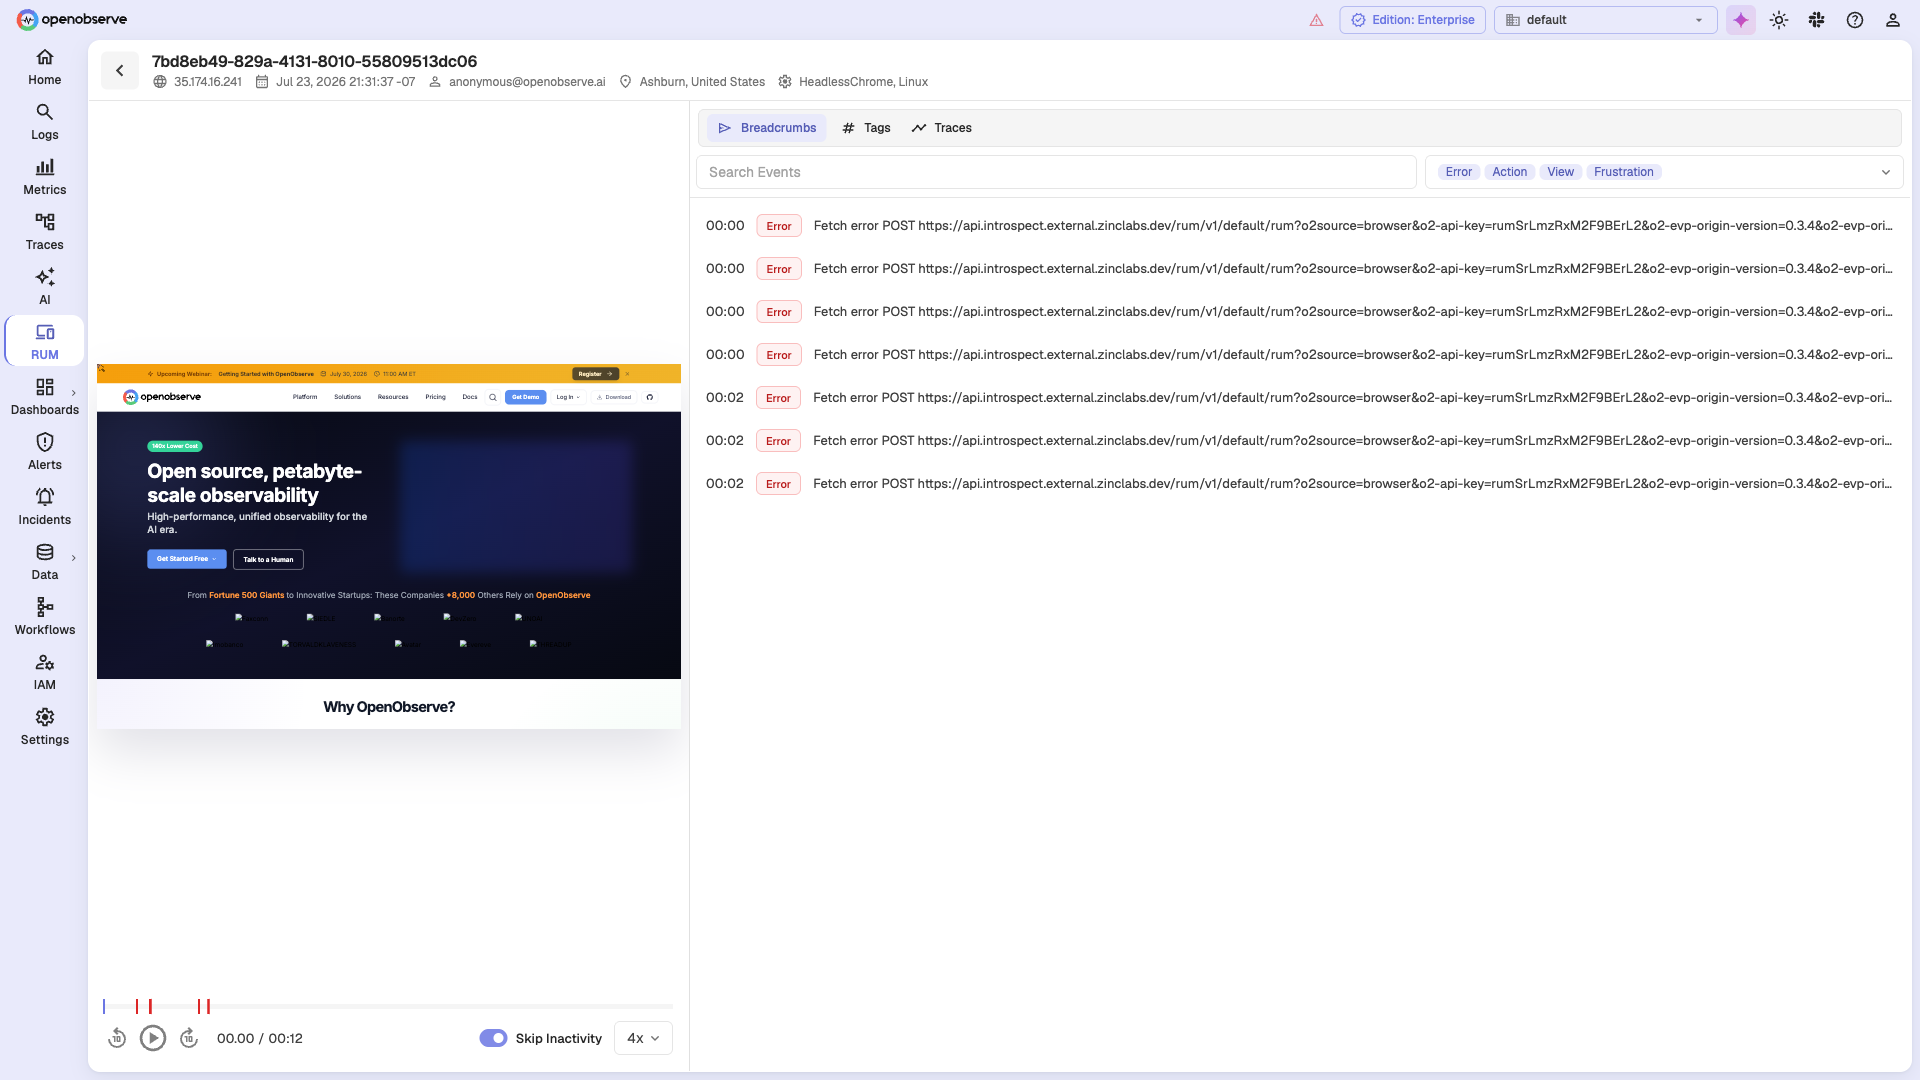
Get notified when something unusual happens on any signal — logs, metrics, or traces. Define thresholds, scheduled or real-time alerts, and notification channels, with alert history and anomaly detection to catch issues early. Read more →
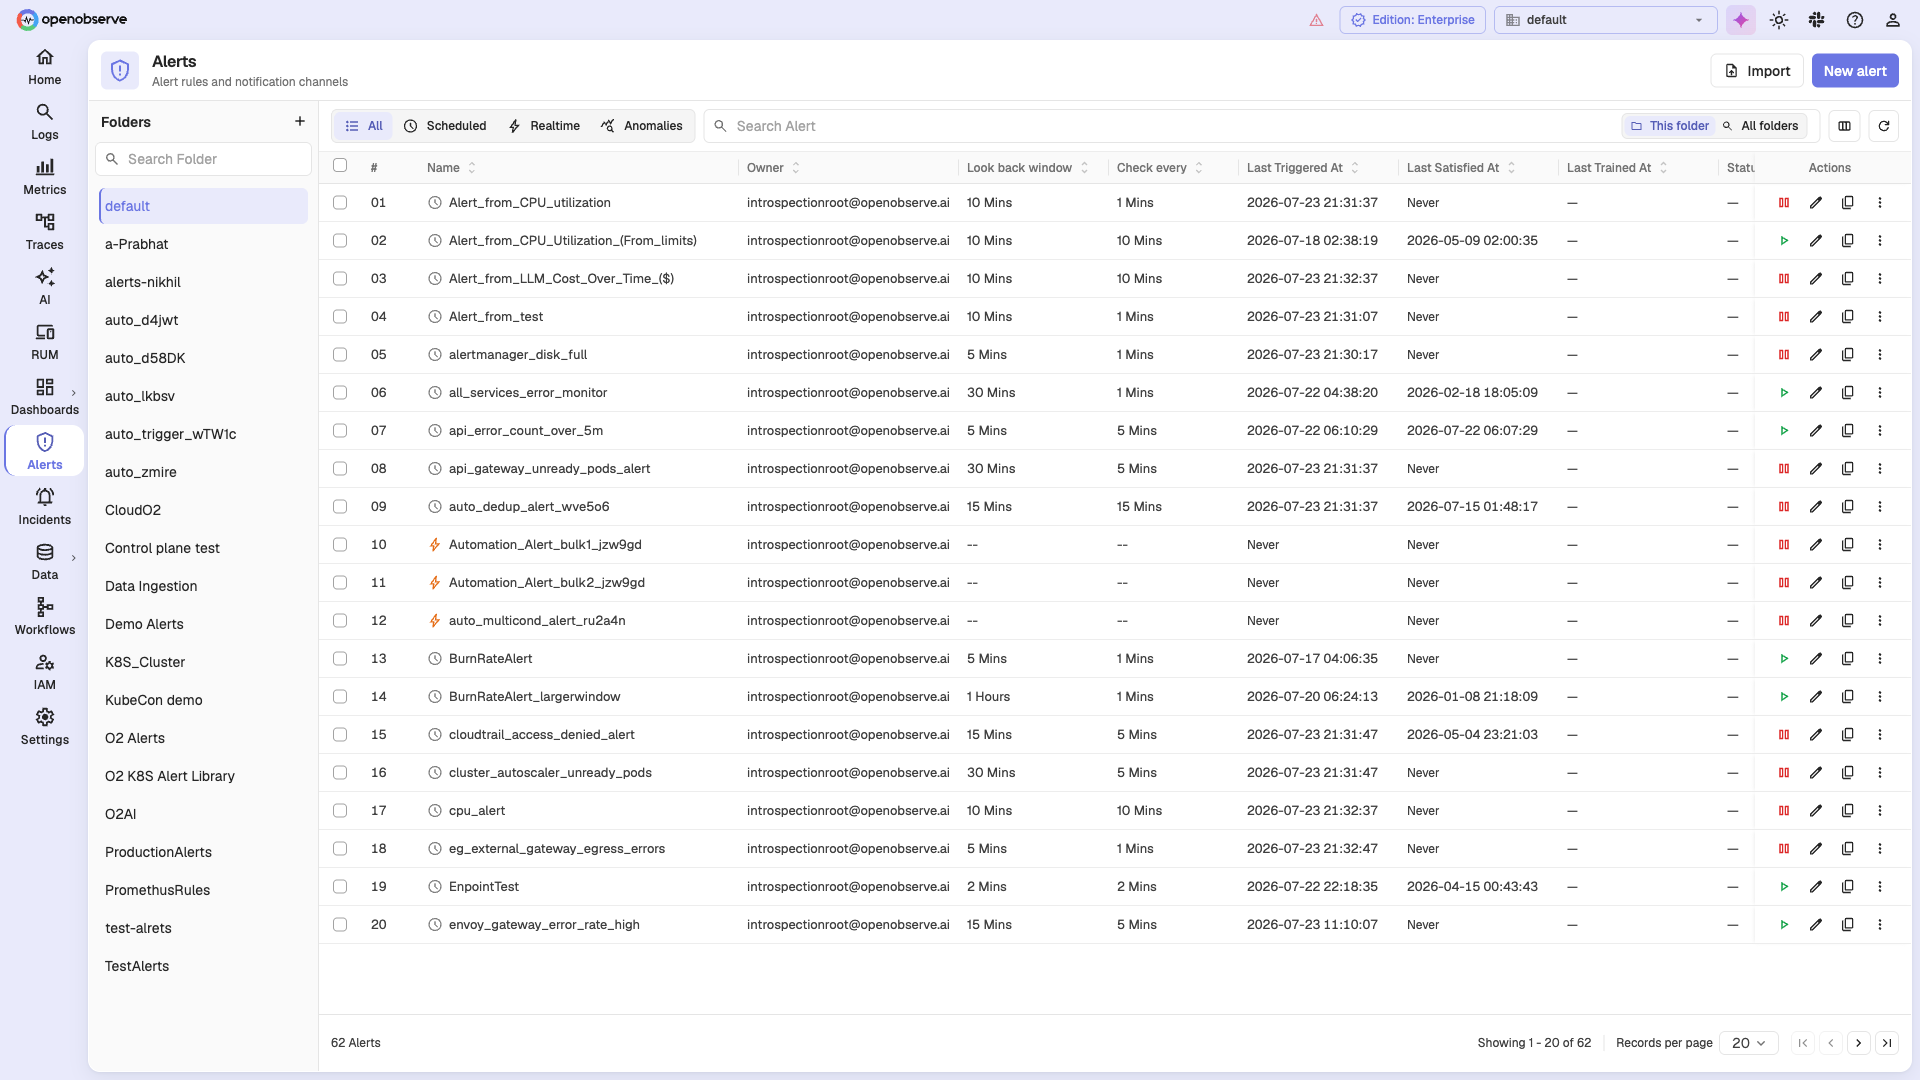
Correlate related alerts into incidents and track them through their lifecycle — open, acknowledged, and resolved — with severity and dimension context for faster response.
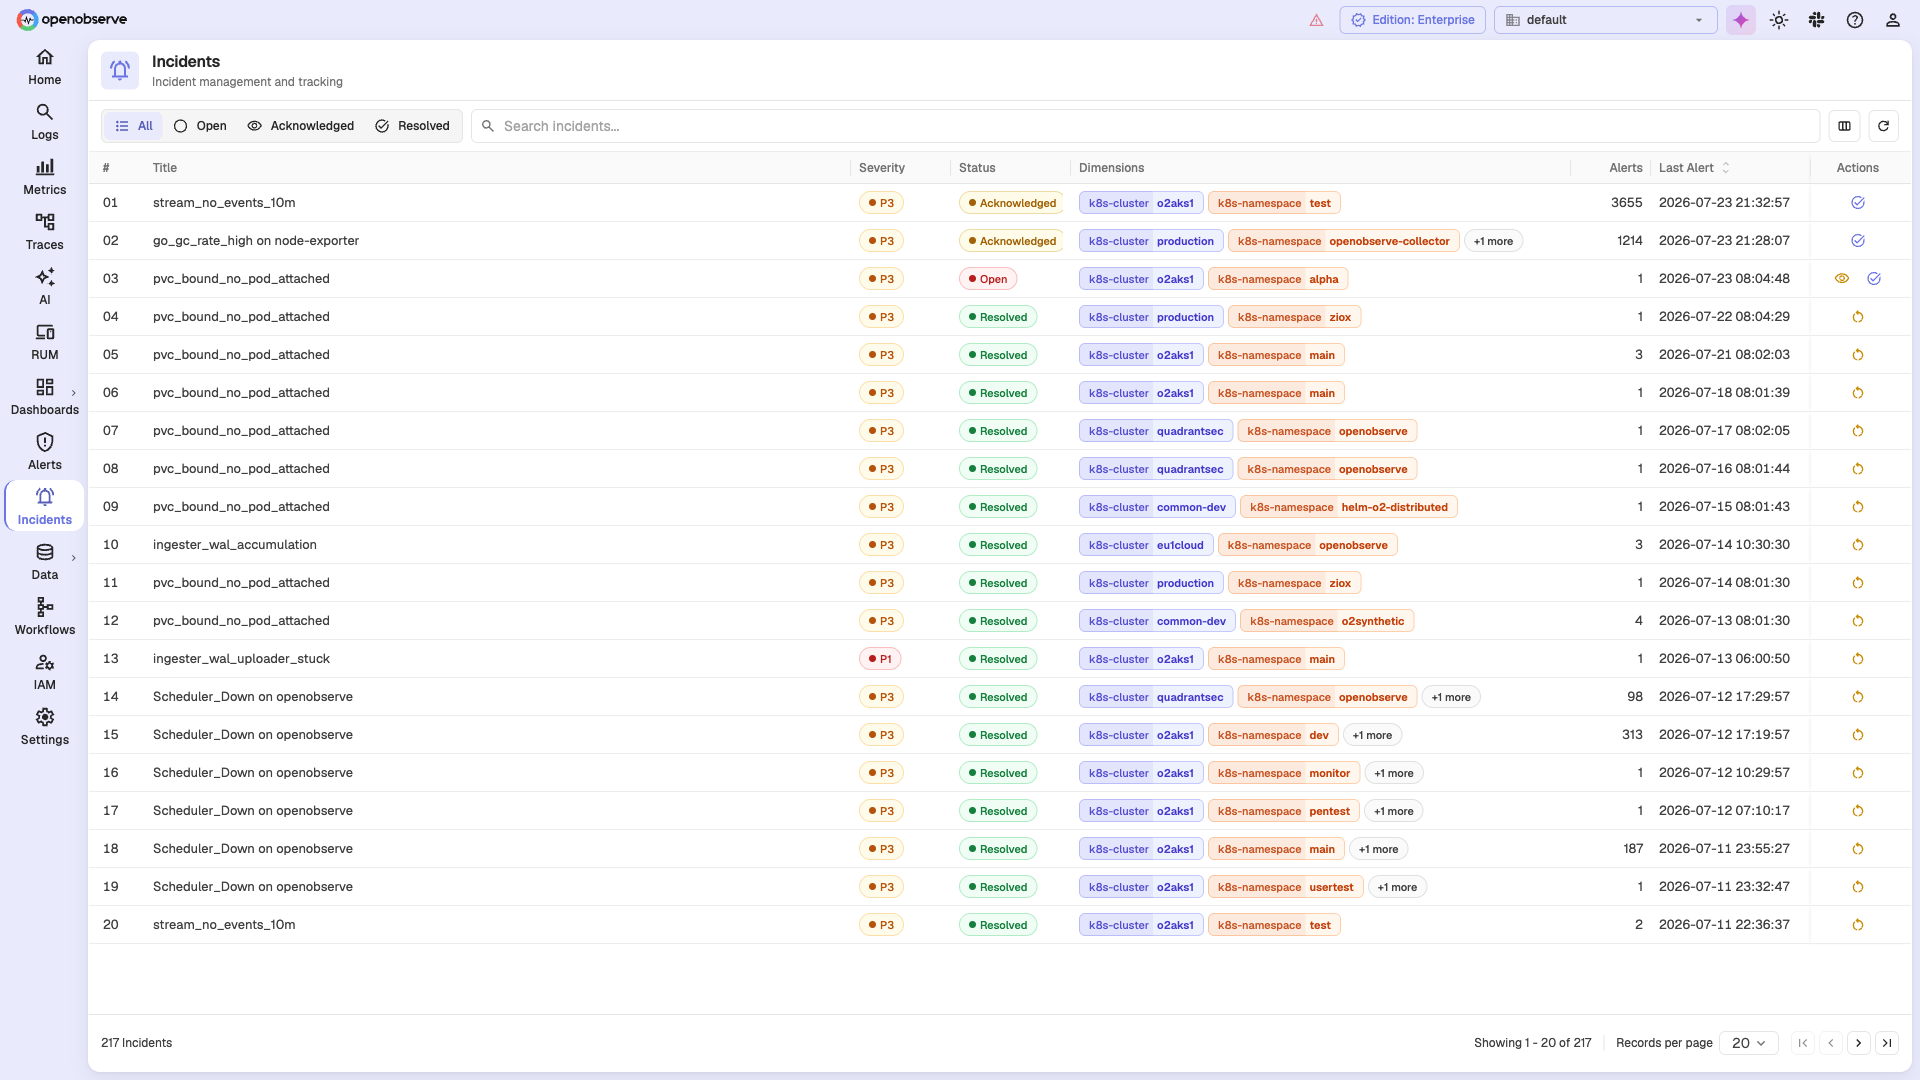
Enrich, redact, reduce, or normalize data at ingest time with a visual editor. Build stream-processing flows — including logs-to-metrics conversion — from source, transform (VRL functions and conditions), and destination nodes. No external tools required. Read more →
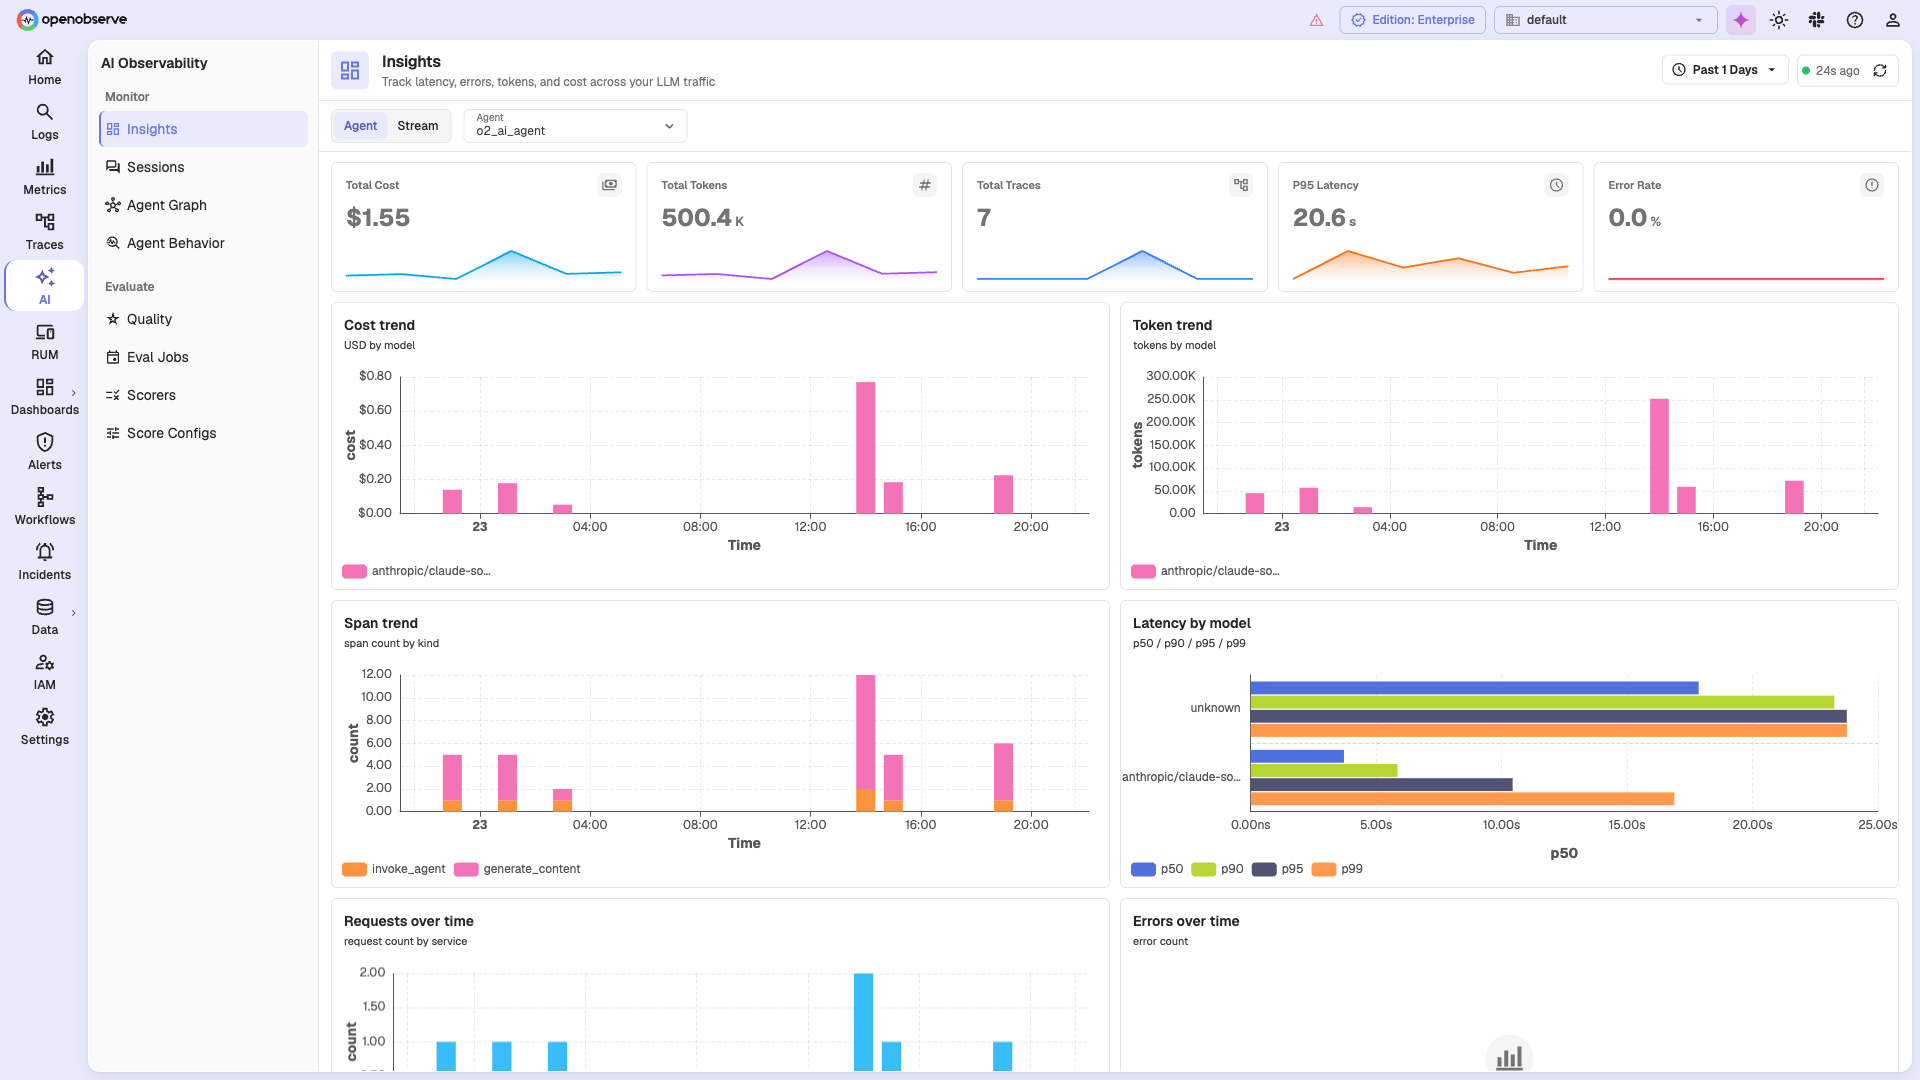
Monitor your GenAI and LLM applications: track cost, tokens, latency percentiles, and error rates across models, with agent graphs, session traces, and evaluation/quality scoring.
An in-product assistant that writes your SQL, VRL, and PromQL and walks you through logs, traces, metrics, and incidents — turning natural-language questions into queries, dashboards, and alerts.

For the full feature list, see the documentation.
OpenObserve achieves 140x lower storage costs and high performance through a modern, cloud-native architecture:
Deploy in High Availability mode with clustering for mission-critical workloads requiring maximum uptime. OpenObserve's stateless architecture with S3-backed storage enables very low Recovery Point Objective (RPO) and Recovery Time Objective (RTO): stateless nodes restart rapidly, and durability is guaranteed by S3's 99.999999999% (11 nines).
Read the architecture documentation → · Read the enterprise deployment guide →
| Aspect | OpenObserve | Datadog | | --- | --- | --- | | Deployment | Self-hosted or Cloud | SaaS only | | Pricing model | Per-GB (free up to 50 GB/day) | Per-host + per-GB | | Open source | Yes (AGPL-3.0) | No | | OpenTelemetry | Native OTLP | Supported | | Query language | SQL + PromQL | Proprietary | | Vendor lock-in | None | High |
| Aspect | OpenObserve | Elasticsearch | | --- | --- | --- | | Storage cost | 140x lower | High (hot/warm/cold tiers) | | Setup complexity | Single binary | Complex cluster management | | Query language | SQL | Lucene/KQL | | Hardware requirements | ~1/4 the resources | High memory/CPU |
| Aspect | OpenObserve | Splunk | | --- | --- | --- | | Licensing | Open source | Expensive enterprise licensing | | Deployment | Single binary or HA cluster | Complex | | Query language | SQL + PromQL | SPL (proprietary) | | Cost | Predictable, low | Unpredictable, high |
| Aspect | OpenObserve | Grafana Stack | | --- | --- | --- | | Components | Single platform | Multiple tools (Grafana + Loki + Prometheus + Tempo) | | Management | One binary | Multiple deployments | | High cardinality | Full support | Loki struggles with high cardinality | | Query performance | Fast on large volumes | Loki slow on large data |
OpenObserve is battle-tested in production environments worldwide:
OpenObserve is a true open source project. The open source edition is feature-complete and production-ready — logs, metrics, traces, dashboards, alerts, pipelines, and everything you need to run observability at scale. It will always remain actively maintained and free to use without restrictions.
For organizations that need enterprise-grade features and support, an Enterprise edition adds:
Enterprise features
The best way to get help, share ideas, and connect with other OpenObserve users is through our community channels.
Our Slack community is the most active place for installation and configuration help, sharing best practices, discussing the roadmap, and connecting with the core team.
We welcome contributions from the community! Whether you're fixing bugs, adding features, improving documentation, or sharing feedback, your help makes OpenObserve better for everyone.
To get started, read our Contributing Guide, which covers setting up your development environment, code standards, submitting pull requests, and reporting issues.
Through a combination of Parquet columnar storage (efficient compression) and an S3-native architecture (inexpensive object storage). See the cost comparison chart in the Why OpenObserve? section.
All data in OpenObserve is immutable — once ingested, it cannot be modified or deleted (only entire retention periods can be dropped). This is by design and is a feature for logs and compliance use cases, ensuring data integrity and audit trails.
Yes. OpenObserve runs in production across thousands of deployments worldwide, including environments processing in excess of 2 PB/day. See our customer stories for real-world examples.
OpenObserve delivers better performance than Elasticsearch for most workloads, with faster search and significantly faster analytics — while using about a quarter of the hardware. The columnar Parquet format is particularly effective for complex aggregations and analytics.
No. OpenObserve is designed to be intuitive from day one:
Open Source Edition — licensed under AGPL-3.0. We chose AGPL to ensure that improvements to OpenObserve remain open source and benefit the entire community, while still allowing free commercial use. Why AGPL, and why it's good for the community →
Enterprise Edition — licensed under a commercial Enterprise License Agreement (not AGPL), which provides additional flexibility for enterprise deployments.
Software Bill of Materials for OpenObserve. You can analyze either SBOM with Dependency-Track.
The SBOM is available here. To regenerate it:
cargo install cargo-cyclonedx
cargo-cyclonedx cyclonedx
The SBOM is available here. To regenerate it:
npm install --global @cyclonedx/cyclonedx-npm
cd web
cyclonedx-npm > sbom.json
 →
 →
 →
 →
 →
 →
 →