1
 →
PDF Parser for AI-ready data. Automate PDF accessibility. Open-source.
opendataloader-project/opendataloader-pdf is an open-source project on GitHub, mainly written in Java. PDF Parser for AI-ready data. Automate PDF accessibility. Open-source. It currently holds 29,654 stars and 2,818 forks with 95 open issues, and was last pushed on 2026-10-12 (repository created 2025-05-13).
Git Homed tracks it on the Today's Trending board, currently at rank #58 with 87 new stars today.
PDF Parser for AI-ready data. Automate PDF accessibility. Open-source.



🔍 PDF parser for AI data extraction — Extract Markdown, JSON (with bounding boxes), and HTML from any PDF. #1 in benchmarks (0.907 overall). Deterministic local mode + AI hybrid mode for complex pages.
pip install opendataloader-pdf, convert in 3 lines. Outputs structured Markdown for chunking, JSON with bounding boxes for source citations, and HTML. LangChain integration available. Python, Node.js, Java SDKs (quick start | LangChain)Requires: Java 11+ and Python 3.10+ (Node.js | Java also available)
Before you start: run java -version. If not found, install JDK 11+ from Adoptium.
pip install -U opendataloader-pdf
import opendataloader_pdf
Batch all files in one call — each convert() spawns a JVM process, so repeated calls are slow
opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    format="markdown,json"
)
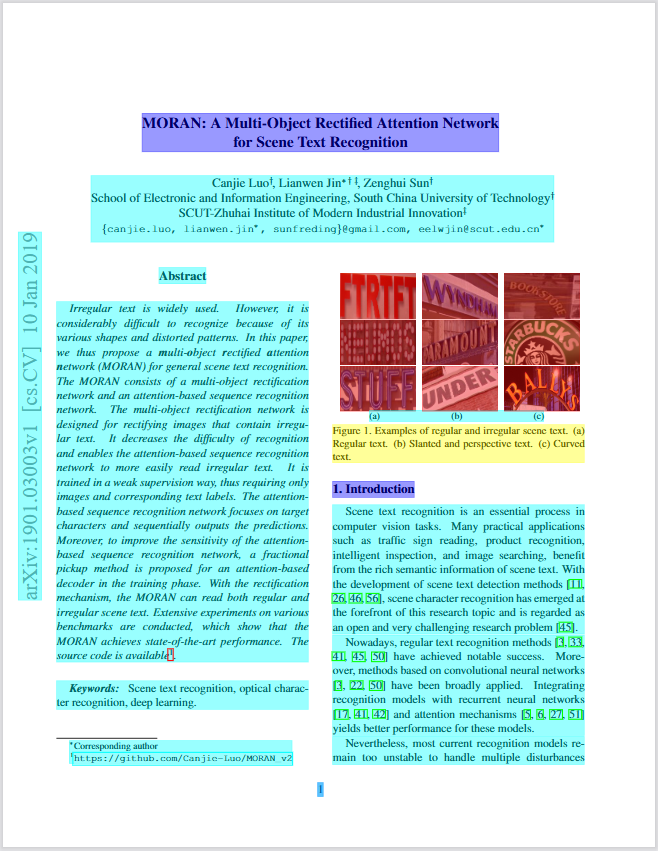
Annotated PDF output — each element (heading, paragraph, table, image) detected with bounding boxes and semantic type.
| Problem | Solution | Status | |---------|----------|--------| | PDF structure lost during parsing — wrong reading order, broken tables, no element coordinates | Deterministic local PDF to Markdown/JSON with bounding boxes, XY-Cut++ reading order | Shipped | | Complex tables, scanned PDFs, formulas, charts need AI-level understanding | Hybrid mode routes complex pages to AI backend (#1 in benchmarks) | Shipped | | Manual PDF remediation cost — Accessibility regulations (EAA, ADA, Section 508) demand Tagged PDFs. Manual remediation costs $50–200/doc | Auto-tag untagged PDFs into Tagged PDFs (free, Apache 2.0). Foundation for PDF/UA workflows; full PDF/UA-1/2 export is an enterprise add-on | Auto-tag: Shipped. PDF/UA export: Enterprise |
| Capability | Supported | Tier | |------------|-----------|------| | Data extraction | | | | Extract text with correct reading order | Yes | Free | | Bounding boxes for every element | Yes | Free | | Table extraction (simple borders) | Yes | Free | | Table extraction (complex/borderless) | Yes | Free (Hybrid) | | Heading hierarchy detection | Yes | Free | | List detection (numbered, bulleted, nested) | Yes | Free | | Image extraction with coordinates | Yes | Free | | AI chart/image description | Yes | Free (Hybrid) | | OCR for scanned PDFs | Yes | Free (Hybrid) | | Formula extraction (LaTeX) | Yes | Free (Hybrid) | | Tagged PDF structure extraction | Yes | Free | | AI safety (prompt injection filtering) | Yes | Free | | Header/footer/watermark filtering | Yes | Free | | Accessibility | | | | Auto-tagging → Tagged PDF for untagged PDFs | Yes | Free (Apache 2.0) | | PDF/UA-1, PDF/UA-2 export | 💼 Available | Enterprise | | Accessibility studio (visual editor) | 💼 Available | Enterprise | | Limitations | | | | Process Word/Excel/PPT | No | — | | GPU required | No | — |
opendataloader-pdf [hybrid] ranks #1 overall (0.907) across reading order, table, and heading extraction accuracy.
| Engine | Overall | Reading Order | Table | Heading | Speed (s/page) | License | |--------|---------|---------------|-------|---------|----------------|---------| | opendataloader [hybrid] | 0.907 | 0.934 | 0.928 | 0.821 | 0.463 | Apache-2.0 | | nutrient | 0.885 | 0.925 | 0.708 | 0.819 | 0.008 | Commercial | | docling | 0.882 | 0.898 | 0.887 | 0.824 | 0.762 | MIT | | marker | 0.861 | 0.890 | 0.808 | 0.796 | 53.932 | GPL-3.0 | | unstructured [hi_res] | 0.841 | 0.904 | 0.588 | 0.749 | 3.008 | Apache-2.0 | | edgeparse | 0.837 | 0.894 | 0.717 | 0.706 | 0.036 | Apache-2.0 | | opendataloader | 0.831 | 0.902 | 0.489 | 0.739 | 0.015 | Apache-2.0 | | mineru | 0.831 | 0.857 | 0.873 | 0.743 | 5.962 | AGPL-3.0 | | pymupdf4llm | 0.732 | 0.885 | 0.401 | 0.412 | 0.091 | AGPL-3.0 | | unstructured | 0.686 | 0.882 | 0.000 | 0.388 | 0.077 | Apache-2.0 | | markitdown | 0.589 | 0.844 | 0.273 | 0.000 | 0.114 | MIT | | liteparse | 0.576 | 0.866 | 0.000 | 0.000 | 1.061 | Apache-2.0 |
Scores normalized to [0, 1]. Higher is better for accuracy; lower is better for speed. Bold = best. Full benchmark details


| Your Document | Mode | Install | Server Command | Client Command |
|---------------|------|---------|----------------|----------------|
| Standard digital PDF | Fast (default) | pip install opendataloader-pdf | None needed | opendataloader-pdf file1.pdf file2.pdf folder/ |
| Complex or nested tables | Hybrid | pip install "opendataloader-pdf[hybrid]" | opendataloader-pdf-hybrid --port 5002 | opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/ |
| Scanned / image-based PDF | Hybrid + OCR | pip install "opendataloader-pdf[hybrid]" | opendataloader-pdf-hybrid --port 5002 --force-ocr | opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/ |
| Non-English scanned PDF | Hybrid + OCR | pip install "opendataloader-pdf[hybrid]" | opendataloader-pdf-hybrid --port 5002 --force-ocr --ocr-engine --ocr-lang — see Choosing an OCR Engine | opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/ |
| Mathematical formulas | Hybrid + formula | pip install "opendataloader-pdf[hybrid]" | opendataloader-pdf-hybrid --enrich-formula | opendataloader-pdf --hybrid docling-fast --hybrid-mode full file1.pdf file2.pdf folder/ |
| Charts needing description | Hybrid + picture | pip install "opendataloader-pdf[hybrid]" | opendataloader-pdf-hybrid --enrich-picture-description | opendataloader-pdf --hybrid docling-fast --hybrid-mode full file1.pdf file2.pdf folder/ |
| Nested sections for RAG chunking | Hybrid + heading levels | pip install "opendataloader-pdf[hybrid]" | opendataloader-pdf-hybrid --port 5002 --heading-hierarchy | opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/ |
| Untagged PDFs needing accessibility | Auto-tagging → Tagged PDF | pip install opendataloader-pdf | None needed | opendataloader-pdf --format tagged-pdf file1.pdf file2.pdf folder/ |
pip install -U opendataloader-pdf
import opendataloader_pdf
Batch all files in one call — each convert() spawns a JVM process, so repeated calls are slow
opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    format="markdown,json"
)
npm install @opendataloader/pdf
import { convert } from '@opendataloader/pdf';
await convert(['file1.pdf', 'file2.pdf', 'folder/'], {
  outputDir: 'output/',
  format: 'markdown,json'
});
  org.opendataloader
  opendataloader-pdf-core
Python Quick Start | Node.js Quick Start | Java Quick Start
Hybrid mode combines fast local Java processing with AI backends. Simple pages stay local (0.02s); complex pages route to AI for +90% table accuracy.
Don't combine with--use-struct-treeon tagged PDFs.--use-struct-treetakes precedence, so the hybrid backend is not called (a warning is logged). If you want the hybrid backend, drop--use-struct-tree.
pip install -U "opendataloader-pdf[hybrid]"
Terminal 1 — Start the backend server:
opendataloader-pdf-hybrid --port 5002
Terminal 2 — Process PDFs:
# Batch all files in one call — each invocation spawns a JVM process, so repeated calls are slow
opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/
Python:
# Batch all files in one call — each convert() spawns a JVM process, so repeated calls are slow
opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    hybrid="docling-fast"
)
Start the backend with --force-ocr for image-based PDFs with no selectable text:
opendataloader-pdf-hybrid --port 5002 --force-ocr
For non-English documents, specify the language:
opendataloader-pdf-hybrid --port 5002 --force-ocr --ocr-lang "ko,en"
The language codes above are for the default engine (EasyOCR): en, ko, ja, ch_sim, ch_tra, de, fr, ar, and more.
OCR quality varies with the engine, the language, and the document itself (scan resolution, fonts, layout). No engine is best for every document, so run a few representative pages through several engines and compare the output before processing a whole collection.
Select the engine with --ocr-engine. Each engine uses its own language code system for --ocr-lang:
| Engine | --ocr-engine | --ocr-lang example | Platform / extra install |
|--------|----------------|----------------------|--------------------------|
| EasyOCR (default) | easyocr | ko,en (ISO 639-1) | Included in opendataloader-pdf[hybrid] |
| RapidOCR | rapidocr | korean (RapidOCR codes: en, ch, japan, korean, ...) | pip install rapidocr onnxruntime |
| Tesseract (CLI) | tesseract | kor,eng (ISO 639-2) | Tesseract binary + language data (e.g. tesseract-ocr-kor) |
| Tesseract (Python binding) | tesserocr | kor,eng (ISO 639-2) | pip install tesserocr + libtesseract |
| Apple Vision | ocrmac | ko-KR,en-US (BCP-47) | macOS only, pip install ocrmac |
| NVIDIA Nemotron OCR | nemotron-ocr | multilingual or english | Linux x86_64 + CUDA, pip install "docling[feat-ocr-nemotron]" |
| Automatic | auto | Not configurable | Docling picks an available engine |
To compare engines on a sample, start one server per engine and send the same file to each.
Terminal 1 — EasyOCR server:
opendataloader-pdf-hybrid --port 5002 --force-ocr --ocr-engine easyocr --ocr-lang "ko,en"
Terminal 2 — Tesseract server:
opendataloader-pdf-hybrid --port 5003 --force-ocr --ocr-engine tesseract --ocr-lang "kor,eng"
Terminal 3 — Send the same sample to both:
opendataloader-pdf sample.pdf --hybrid docling-fast --hybrid-mode full --hybrid-url http://localhost:5002 -o out-easyocr
opendataloader-pdf sample.pdf --hybrid docling-fast --hybrid-mode full --hybrid-url http://localhost:5003 -o out-tesseract
Extract mathematical formulas as LaTeX from scientific PDFs:
# Server: enable formula enrichment
opendataloader-pdf-hybrid --enrich-formula
Batch all files in one call — each invocation spawns a JVM process, so repeated calls are slow
opendataloader-pdf --hybrid docling-fast --hybrid-mode full file1.pdf file2.pdf folder/
Output in JSON:
{
  "type": "formula",
  "page number": 1,
  "bounding box": [226.2, 144.7, 377.1, 168.7],
  "content": "\\frac{f(x+h) - f(x)}{h}"
}
Note: Formula and picture description enrichments require --hybrid-mode full on the client side.
Generate AI descriptions for charts and images — useful for RAG search and accessibility alt text:
# Server
opendataloader-pdf-hybrid --enrich-picture-description
Batch all files in one call — each invocation spawns a JVM process, so repeated calls are slow
opendataloader-pdf --hybrid docling-fast --hybrid-mode full file1.pdf file2.pdf folder/
Output in JSON:
{
  "type": "image",
  "pdfua_tag": "Figure",
  "id": 285,
  "page number": 1,
  "bounding box": [72.0, 400.0, 540.0, 650.0],
  "alt": "A bar chart showing waste generation by region from 2016 to 2030...",
  "alt_source": "ai-generated"
}
alt_source says where the text came from: original (the PDF's own /Alt), ai-generated,
or missing — and when it is missing, there is no alt field at all.
With --enrich-picture-description, every picture goes to the model whatever its size. The
server reports the tally per request, so a picture that came back without a description shows
up in the log rather than only in the output:
picture_description pictures=4 described=4
Cost follows the number of pictures, not their size: a 40×20 pt logo costs about what a
full-page chart does, and on CPU one picture can take over a minute. A document full of icons
is therefore minutes of work per page, and conversions are serialized, so other requests wait.
--picture-area-threshold 0.05 spends the model only on pictures covering at least 5% of
their page:
picture_description pictures=4 described=1 skipped=3 threshold=0.05
Skips are logged at INFO when you set a threshold, and at WARNING when you did not — in that case nothing was asked to drop them, so the cause is worth a look.
Uses SmolVLM (256M), a lightweight vision model. Custom prompts supported via --picture-description-prompt.
Since the picture count comes from the uploaded file, a server reachable by untrusted callers
should set--picture-area-threshold, and--max-file-sizeto cap the conversion work one
file can ask for. That limit is applied once the request body has been received, so it bounds
conversion cost rather than upload bandwidth or temporary disk.
The layout model labels a region as a section header without a depth, so by default every heading comes back at level 1 and subsections sit at the same depth as the document title. Flat headings make it hard to tell a section title from a document title when chunking for RAG.
--heading-hierarchy infers the depth — from the PDF outline first, then section numbering
(1. → 1.1 → 1.1.1), then visual style:
# Server
opendataloader-pdf-hybrid --port 5002 --heading-hierarchy
Client — no extra flag needed
opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/
# 3. Methodology
- # 3.1. Multi-Object Rectification Network
+ ## 3.1. Multi-Object Rectification Network
- # Abstract
+ ## Abstract
Numbering covers numbered sections; style is what pulls an unnumbered Abstract or
References out from under the document title.
Off by default, so existing output is unchanged. Levels are capped at H6.
Enterprise-grade AI document analysis via Hancom Data Loader — customer-customized models trained on your domain-specific documents. 30+ element types (tables, charts, formulas, captions, footnotes, etc.), VLM-based image/chart understanding, complex table extraction (merged cells, nested tables), SLA-backed OCR for scanned documents, and native HWP/HWPX support. Supports PDF, DOCX, XLSX, PPTX, HWP, PNG, JPG. Live demo
| Format | Use Case | |--------|----------| | JSON | Structured data with bounding boxes, semantic types | | Markdown | Clean text for LLM context, RAG chunks | | HTML | Web display with styling | | Annotated PDF | Visual debugging — see detected structures (sample) | | Text | Plain text extraction |
Combine formats: format="json,markdown"
{
  "type": "heading",
  "id": 42,
  "level": "Title",
  "page number": 1,
  "bounding box": [72.0, 700.0, 540.0, 730.0],
  "heading level": 1,
  "font": "Helvetica-Bold",
  "font size": 24.0,
  "text color": "[0.0]",
  "content": "Introduction"
}
| Field | Description |
|-------|-------------|
| type | Element type: heading, paragraph, table, list, image, caption, formula |
| id | Unique identifier for cross-referencing |
| page number | 1-indexed page reference |
| bounding box | [left, bottom, right, top] in PDF points (72pt = 1 inch) |
| heading level | Heading depth (1+) |
| content | Extracted text |
When a PDF has structure tags, OpenDataLoader extracts the exact layout the author intended — no guessing, no heuristics. Headings, lists, tables, and reading order are preserved from the source.
Output quality depends on tag quality. Not all tagged PDFs are well-tagged. For PDFs with sparse or incorrect tags, the default heuristic mode or --hybrid docling-fast often produces better results.
--use-struct-treetakes precedence over--hybrid. If both are set on a tagged PDF, the structure tree is used and the hybrid backend is not called (a well-tagged PDF already carries reading order and structure). Drop--use-struct-treeif you want the hybrid backend instead.
# Batch all files in one call — each convert() spawns a JVM process, so repeated calls are slow
opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    use_struct_tree=True           # Use native PDF structure tags
)
Most PDF parsers ignore structure tags entirely. Learn more
PDFs can contain hidden prompt injection attacks. OpenDataLoader automatically filters:
# Batch all files in one call — each invocation spawns a JVM process, so repeated calls are slow
opendataloader-pdf file1.pdf file2.pdf folder/ --sanitize
pip install -U langchain-opendataloader-pdf
from langchain_opendataloader_pdf import OpenDataLoaderPDFLoader
loader = OpenDataLoaderPDFLoader(
    file_path=["file1.pdf", "file2.pdf", "folder/"],
    format="text"
)
documents = loader.load()
LangChain Docs | GitHub | PyPI
```python
→ →
 →
 →
 →
 →
 →
 →