1
 →
scrape data from Google Maps. Extracts data such as the name, address, phone number, website URL, rating, reviews number, latitude and longitude, reviews,email and more for each place
gosom/google-maps-scraper is an open-source project on GitHub, mainly written in Go. scrape data from Google Maps. Extracts data such as the name, address, phone number, website URL, rating, reviews number, latitude and longitude It currently holds 7,826 stars and 1,221 forks with 66 open issues, and was last pushed on 2026-11-08 (repository created 2023-04-22).
Git Homed tracks it on the Today's Trending board, currently at rank #43 with 121 new stars today.


Extract Google Maps business leads, emails, reviews, phone numbers, websites, ratings, coordinates, and more with a free open-source CLI, Web UI, REST API, and optional self-hosted platform.
Use it for lead generation, local business research, sales prospecting, data enrichment, or developer automation.
The easiest way to use Google Maps Scraper is with an AI coding agent such as Claude Code, Codex, Cursor, GitHub Copilot, or any Agent Skills-compatible tool. You describe the leads you want; the agent plans the searches, runs a small validation, starts the full local scrape, monitors it, and helps you work with the results.
Install the skill:
npx skills add gosom/google-maps-scraper
Then ask your agent in plain language:
Find dentists in Berlin and include their websites and email addresses.
The agent automatically checks for the latest skill and Docker image, then asks only for details it still needs. For larger crawls, you can provide your own proxy, continue without one, or review three randomly selected proxy sponsors. Proxy credentials are entered through a masked local terminal prompt and are never pasted into the agent chat.
Requires Docker and Node.js on macOS, Linux, or Windows through WSL. See how the agent workflow works.
| Goal | Start here | |---|---| | Get leads into CSV/JSON | Command Line | | Ask an AI coding agent to run a scrape | AI Agent Skill | | Run a browser UI locally | Web UI | | Automate scraping from your app | REST API | | Run a multi-user scraping platform | SaaS Edition | | Follow common workflows | Recipes |
If this project is useful to you, a GitHub star helps others discover it. Sponsorships help fund maintenance and new work.
---
These sponsors help support development and maintenance of Google Maps Scraper.
 Coreclaw |
 Evomi |
 G Maps Extractor |
 HasData |
 NodeMaven |
 RapidProxy |
 Scrap.io |
 SearchApi |
 SerpApi |
 TalorData |
 Webshare |
Become a sponsor |
View all sponsors and offers · Become a sponsor
---
| | | |---|---| | Completely Free & Open Source | MIT licensed, no hidden costs or usage limits | | Multiple Interfaces | CLI, Web UI, REST API - use what fits your workflow | | High Performance | ~120 places/minute with optimized concurrency | | 33+ Data Points | Business details, reviews, emails, coordinates, and more | | Production Ready | Scale from a single machine to Kubernetes clusters | | Flexible Output | CSV, JSON, PostgreSQL, S3, or custom plugins | | Proxy Support | Built-in SOCKS5/HTTP/HTTPS proxy rotation |
---
mkdir -p gmaps-output
docker run \
  -v gmaps-playwright-cache:/opt \
  -v "$PWD/example-queries.txt:/queries.txt:ro" \
  -v "$PWD/gmaps-output:/out" \
  gosom/google-maps-scraper \
  -input /queries.txt \
  -results /out/results.csv \
  -depth 1 \
  -exit-on-inactivity 3m
Useful options:
| Need | Flag |
|---|---|
| Extract emails from business websites | -email |
| Write JSON instead of CSV | -json -results /out/results.json |
| Collect extra reviews | -extra-reviews -json -results /out/results.json |
| Resume an interrupted file scrape | -resume -results /out/results.csv |
| Increase concurrency | -c 4, -c 8, or -c 16 |
| Run multiple pages per browser | -pages-per-browser 4 |
| Limit browser processes | -browser-pool-size 2 |
| Use proxies | -proxies "http://user:pass@host:port,socks5://host:port" |
| Read proxies from a credentials file | -proxies-file /path/to/proxies.txt |
-c controls how many scrape jobs run in parallel. Higher concurrency can finish large input files faster, but it also uses more CPU/RAM and can increase blocking or failures, especially without proxies. Start with the default for a first run. For larger jobs on a capable machine, try -c 4, -c 8, or -c 16 and measure the result.
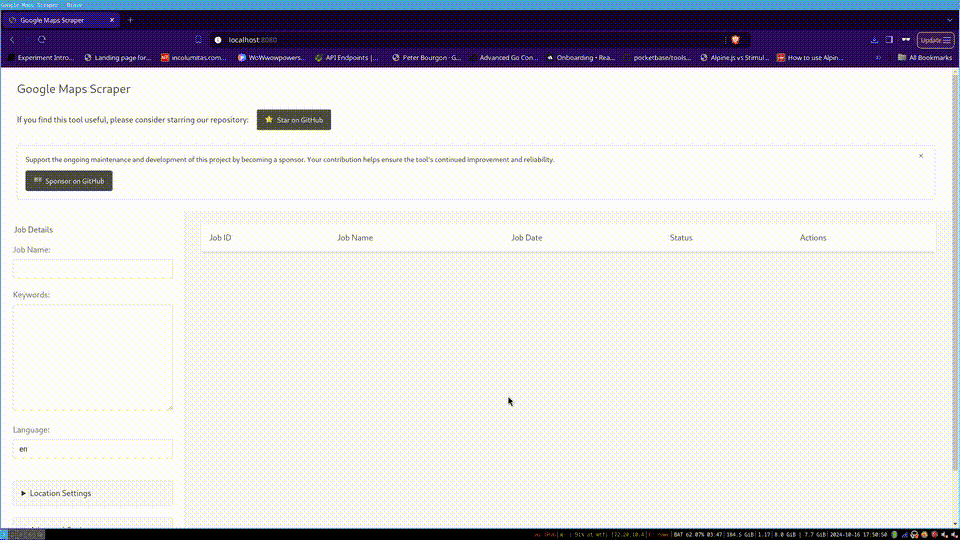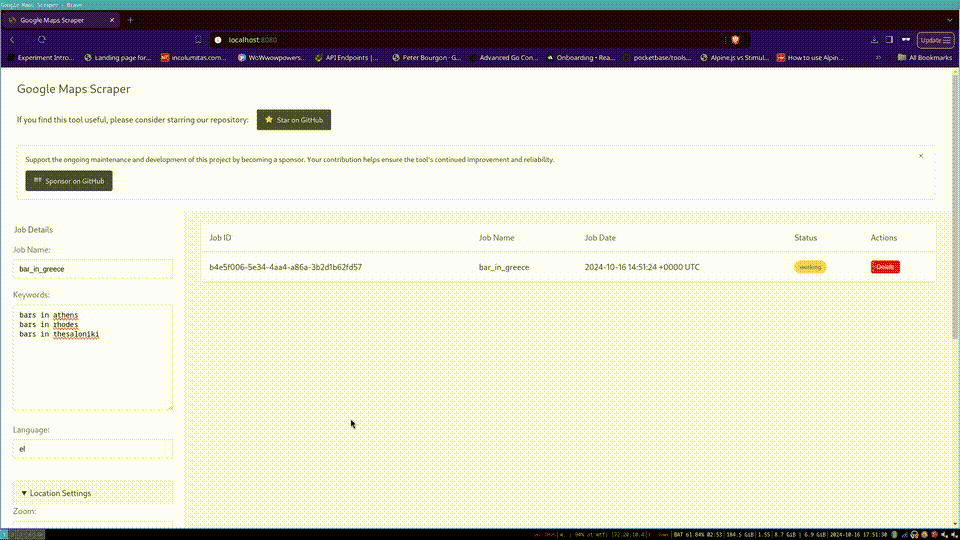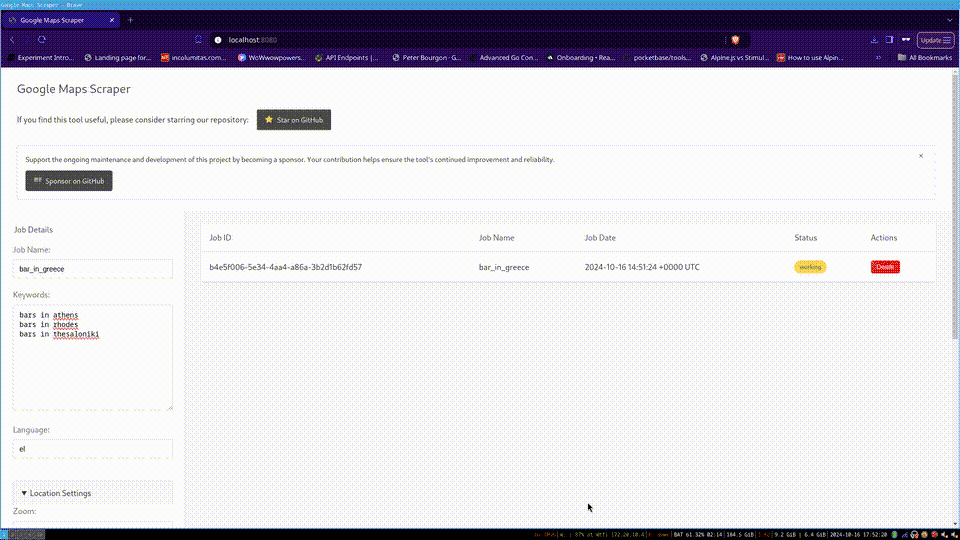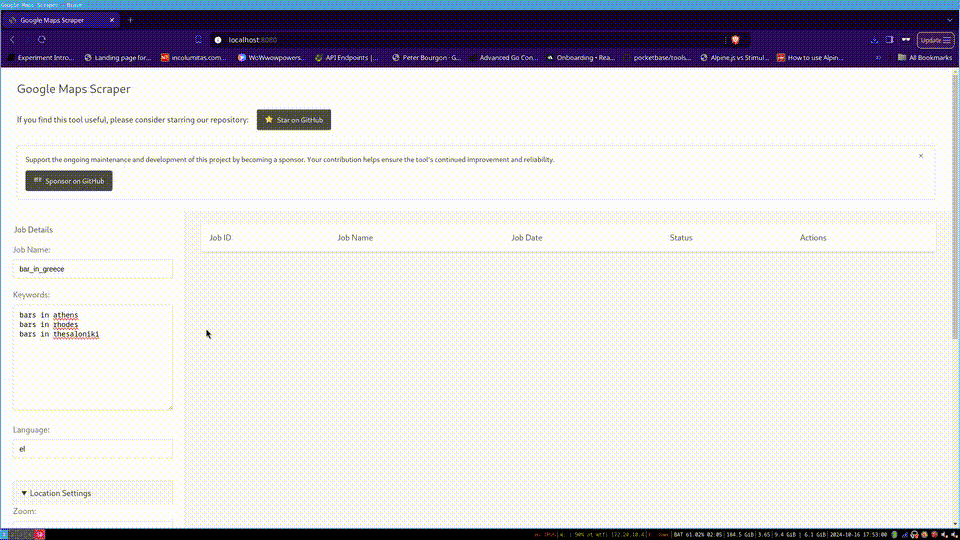
Start the web interface with a single command:
mkdir -p gmapsdata
docker run \
  -v "$PWD/gmapsdata:/gmapsdata" \
  -p 8080:8080 \
  gosom/google-maps-scraper \
  -data-folder /gmapsdata
Then open http://localhost:8080 in your browser.
Or download the binary release for your platform.
Note: Results take at least 3 minutes to appear (minimum configured runtime).
macOS Users: Docker command may not work. See MacOS Instructions.
When running the web server, a full REST API is available:
| Endpoint | Method | Description |
|----------|--------|-------------|
| /api/v1/jobs | POST | Create a new scraping job |
| /api/v1/jobs | GET | List all jobs |
| /api/v1/jobs/{id} | GET | Get job details |
| /api/v1/jobs/{id} | DELETE | Delete a job |
| /api/v1/jobs/{id}/download | GET | Download results as CSV |
Full OpenAPI 3.0.3 documentation available at http://localhost:8080/api/docs
Need a multi-user platform with API keys, admin UI, job queue, workers, and cloud provisioning? Use the optional self-hosted SaaS edition:
curl -fsSL https://raw.githubusercontent.com/gosom/google-maps-scraper/main/PROVISION | sh
See SaaS documentation for deployment and operations details. There is also a 5-minute deployment walkthrough and a YouTube video walkthrough.
More examples are available in Recipes. If you need proxies for larger jobs, see Proxy Sponsors.
---
The AI Agent Skill turns a natural-language lead request into a guided local scraping workflow. It is designed for nontechnical users as well as developers and keeps you in control of the search scope, proxy choice, and output.
If you have not installed it yet:
npx skills add gosom/google-maps-scraper
Then just ask your agent:
Find me all dentists in Berlin with their emails
The agent will:
1. Noninteractively check for the latest skill and Docker image. 2. Infer sensible search defaults and ask only for missing essentials. 3. Let you use your own proxy, continue without one, or choose from three randomly selected proxy sponsors. 4. Collect proxy credentials through a masked local terminal prompt instead of chat. 5. Run a small validation scrape before the full job. 6. Start and monitor the Docker crawl in the background. 7. Present the results with options to save, filter, analyze, or export.
Proxy sponsor recommendations are clearly disclosed and shown with equal placement. Any discount or offer is displayed only when it is configured in the skill's active sponsor registry. You can always use another provider or no proxy.
Requires Docker and Node.js on macOS, Linux, or Windows through WSL. See the skill definition for details.
---
The published Docker image uses Playwright:
docker pull gosom/google-maps-scraper
Requirements: Go 1.27.3+
git clone https://github.com/gosom/google-maps-scraper.git
cd google-maps-scraper
go mod download
go build
./google-maps-scraper -input example-queries.txt -results results.csv -exit-on-inactivity 3m
First run downloads required browser libraries for Playwright.
---
| Feature | Description | |---------|-------------| | 33+ Data Points | Business name, address, phone, website, reviews, coordinates, and more | | Email Extraction | Optional crawling of business websites for email addresses | | Multiple Output Formats | CSV, JSON, PostgreSQL, S3, or custom plugins | | Proxy Support | SOCKS5, HTTP, HTTPS with authentication | | Scalable Architecture | Single machine to Kubernetes cluster | | REST API | Programmatic control for automation | | Web UI | User-friendly browser interface | | Fast Mode (Beta) | Quick extraction of up to 21 results per query | | AWS Lambda | Serverless execution support (experimental) |
---
| # | Field | Description |
|---|-------|-------------|
| 1 | input_id | Internal identifier for the input query |
| 2 | link | Direct URL to the Google Maps listing |
| 3 | title | Business name |
| 4 | category | Business type (e.g., Restaurant, Hotel) |
| 5 | address | Street address |
| 6 | open_hours | Operating hours |
| 7 | popular_times | Visitor traffic patterns |
| 8 | website | Official business website |
| 9 | phone | Contact phone number |
| 10 | plus_code | Location shortcode |
| 11 | review_count | Total number of reviews |
| 12 | review_rating | Average star rating |
| 13 | reviews_per_rating | Breakdown by star rating |
| 14 | latitude | GPS latitude |
| 15 | longitude | GPS longitude |
| 16 | cid | Google's unique Customer ID |
| 17 | status | Business status (open/closed/temporary) |
| 18 | descriptions | Business description |
| 19 | reviews_link | Direct link to reviews |
| 20 | thumbnail | Thumbnail image URL |
| 21 | timezone | Business timezone |
| 22 | price_range | Price level ($, $$, $$$) |
| 23 | data_id | Internal Google Maps identifier |
| 24 | street_view_url | Street View URL |
| 25 | place_id | Google's unique place id |
| 26 | images | Associated image URLs |
| 27 | reservations | Reservation booking link |
| 28 | order_online | Online ordering link |
| 29 | menu | Menu link |
| 30 | owner | Owner-claimed status |
| 31 | complete_address | Full formatted address |
| 32 | credit_cards_accepted | Accepted credit card networks |
| 33 | about | Additional business info |
| 34 | user_reviews | Customer reviews (text, rating, timestamp) |
| 35 | user_reviews_extended | Extended reviews up to ~300 (requires -extra-reviews) |
| 36 | emails | Extracted email addresses (requires -email flag) |
Custom Input IDs: Define your own IDs in the input file:
Matsuhisa Athens #!#MyCustomID
Direct Google Maps URLs: Input lines can be regular search queries or direct Google Maps URLs. Supported URL formats include:
https://www.google.com/maps/search/pizza
https://www.google.com/maps/place/Empire+State+Building/@40.7484405,-73.9856632
https://maps.google.com/maps?z=16&q=Empire+State+Building
maps.app.goo.gl/abc123
URLs on google.com subdomains must include a scheme (http:// or https://) and a /maps path. Short maps.app.goo.gl links are also supported without a scheme.
---
Usage: google-maps-scraper [options]
Core Options:
  -input string       Path to input file with queries (one per line)
  -results string     Output file path (default: stdout)
  -json              Output JSON instead of CSV
  -resume            Resume a CLI file scrape by appending missing places
  -depth int         Max scroll depth in results (default: 10)
  -c int             Concurrency level (default: half of CPU cores)
Email & Reviews:
  -email             Extract emails from business websites
  -extra-reviews     Collect extended reviews (up to ~300)
Location Settings:
  -lang string       Language code, e.g., 'de' for German (default: "en")
  -geo string        Coordinates for search, e.g., '37.7749,-122.4194'
  -zoom int          Zoom level 0-21 (default: 15)
  -radius float      Search radius in meters (default: 10000)
  -grid-bbox string  Bounding box for grid scraping, format: "minLat,minLon,maxLat,maxLon"
  -grid-cell float   Grid cell size in km (default: 1.0, used with -grid-bbox)
Web Server:
  -web               Run web server mode
  -addr string       Server address (default: ":8080")
  -data-folder       Data folder for web runner (default: "webdata")
Database:
  -dsn string        PostgreSQL connection string
  -produce           Produce seed jobs only (requires -dsn)
Proxy:
  -proxies string    Comma-separated proxy list
                     Format: protocol://user:pass@host:port
  -proxies-file      Path to a file containing one proxy URL per line
Export:
Advanced:
  -exit-on-inactivity duration    Exit after inactivity (e.g., '5m')
  -fast-mode                      Quick mode with reduced data
  -debug                          Show browser window
  -writer string                  Custom writer plugin (format: 'dir:pluginName')
  -browser-pool-size int          Number of browser processes to launch (default: 0, derived from -c and -pages-per-browser)
  -pages-per-browser int          Max concurrent pages per browser process (default: 1)
Notes:
  -grid-bbox requires a valid zoom level (1-21)
  -fast-mode cannot be used together with -grid-bbox
Run ./google-maps-scraper -h for the complete list.
Use -resume to continue a CLI file scrape after a crash or manual stop:
./google-maps-scraper \
  -resume \
  -input queries.txt \
  -results results.csv \
  -depth 10
Resume mode reads the existing CSV or JSONL results file, appends new results, and skips places that were already written. It also writes completed input queries to .resume.json; future resume runs use that sidecar file to skip fully completed queries.
-resume is only supported with regular file output. It requires -results to be a file path and does not support stdout, -writer, or -fast-mode. Resume runs should use the same input and scrape options as the original run.
For larger scraping jobs, proxies help avoid rate limiting. Here's how to configure them:
./google-maps-scraper \
  -input queries.txt \
  -results results.csv \
  -proxies 'socks5://user:pass@host:port,http://host2:port2' \
  -depth 1 -c 2
Supported protocols: socks5, socks5h, http, https
Current proxy sponsors are listed in Proxy Sponsors. Using those links helps fund project maintenance.
Email extraction is disabled by default. When enabled, the scraper visits each business website to find email addresses.
./google-maps-scraper -input queries.txt -results results.csv -email
Note: Email extraction increases processing time significantly.
Fast mode returns up to 21 results per query, ordered by distance. Useful for quick data collection with basic fields.
./google-maps-scraper \
  -input queries.txt \
  -results results.csv \
  -fast-mode \
  -zoom 15 \
  -radius 5000 \
  -geo '37.7749,-122.4194'
Warning: Fast mode is in Beta. You may experience blocking.
Grid mode splits a bounding box into cells and runs one search per cell. This is useful when a single search does not return enough places.
queries.txt example:
cafes in Peristeri, Greece
Command example:
./google-maps-scraper \
  -input queries.txt \
  -results peristeri-cafes.csv \
  -grid-bbox "38.0077,23.6719,38.0257,23.6947" \
  -grid-cell 0.5 \
  -zoom 16 \
  -depth 1 \
  -c 4
Notes:
-grid-bbox guides where searches are launched from, but results are not strictly clipped to the box.-fast-mode with -geo + -radius (or post-filter by latitude/longitude).With the default -pages-per-browser 1, each concurrent job (-c) effectively uses its own browser process with a single page tab. This can be inefficient because browser pages can be CPU- and memory-heavy, and each browser process adds overhead.
The -pages-per-browser flag lets you run multiple page tabs inside the same browser process, reducing overhead. Leave -browser-pool-size at 0 to derive the browser count from concurrency and pages per browser, or set it explicitly to cap the number of browser processes independently of concurrency.
How the flags interact:
| Flag | What it controls |
|------|------------------|
| -c | Total number of concurrent scrape jobs |
| -browser-pool-size | Number of browser processes to launch (default: 0, derived from -c and -pages-per-browser) |
| -pages-per-browser | Number of page tabs per browser process (default: 1) |
When -pages-per-browser is greater than 1, the scraper opens multiple tabs within each browser process and routes jobs through a shared page pool. This can significantly increase job throughput on the same hardware.
Example — 8 concurrent jobs across 2 browsers with 4 tabs each:
./google-maps-scraper \
  -c 8 \
  -browser-pool-size 2 \
  -pages-per-browser 4 \
  -input queries.txt \
  -results results.csv \
  -depth 1
Tuning guidance:
-c 4 -browser-pool-size 1 -pages-per-browser 4 for a 4:1 page-to-browser ratio.htop or docker stats; browser resource use varies significantly by workload, Chromium version, and page count.-browser-pool-size low and reduce -c or -pages-per-browser.-c or -pages-per-browser.-browser-pool-size × -pages-per-browser should roughly equal or exceed -c to keep all jobs busy.-browser-pool-size is most useful in containerized environments (Docker, Kubernetes) where you want predictable resource usage.For distributed scraping across multiple machines:
1. Start PostgreSQL:
docker-compose -f docker-compose.dev.yaml up -d
2. Seed the jobs: ```bash ./google-maps-scraper \ -dsn "postgres://postgres:postgres@lo
→ →
 →
 →
 →
 →
 →
 →