1
 →
Unlimited FREE AI coding. Connect Claude Code, Codex, Cursor, Cline, Copilot, Antigravity to FREE Claude/GPT/Gemini via 40+ providers. Auto-fallback, RTK -40% tokens, never hit limits.
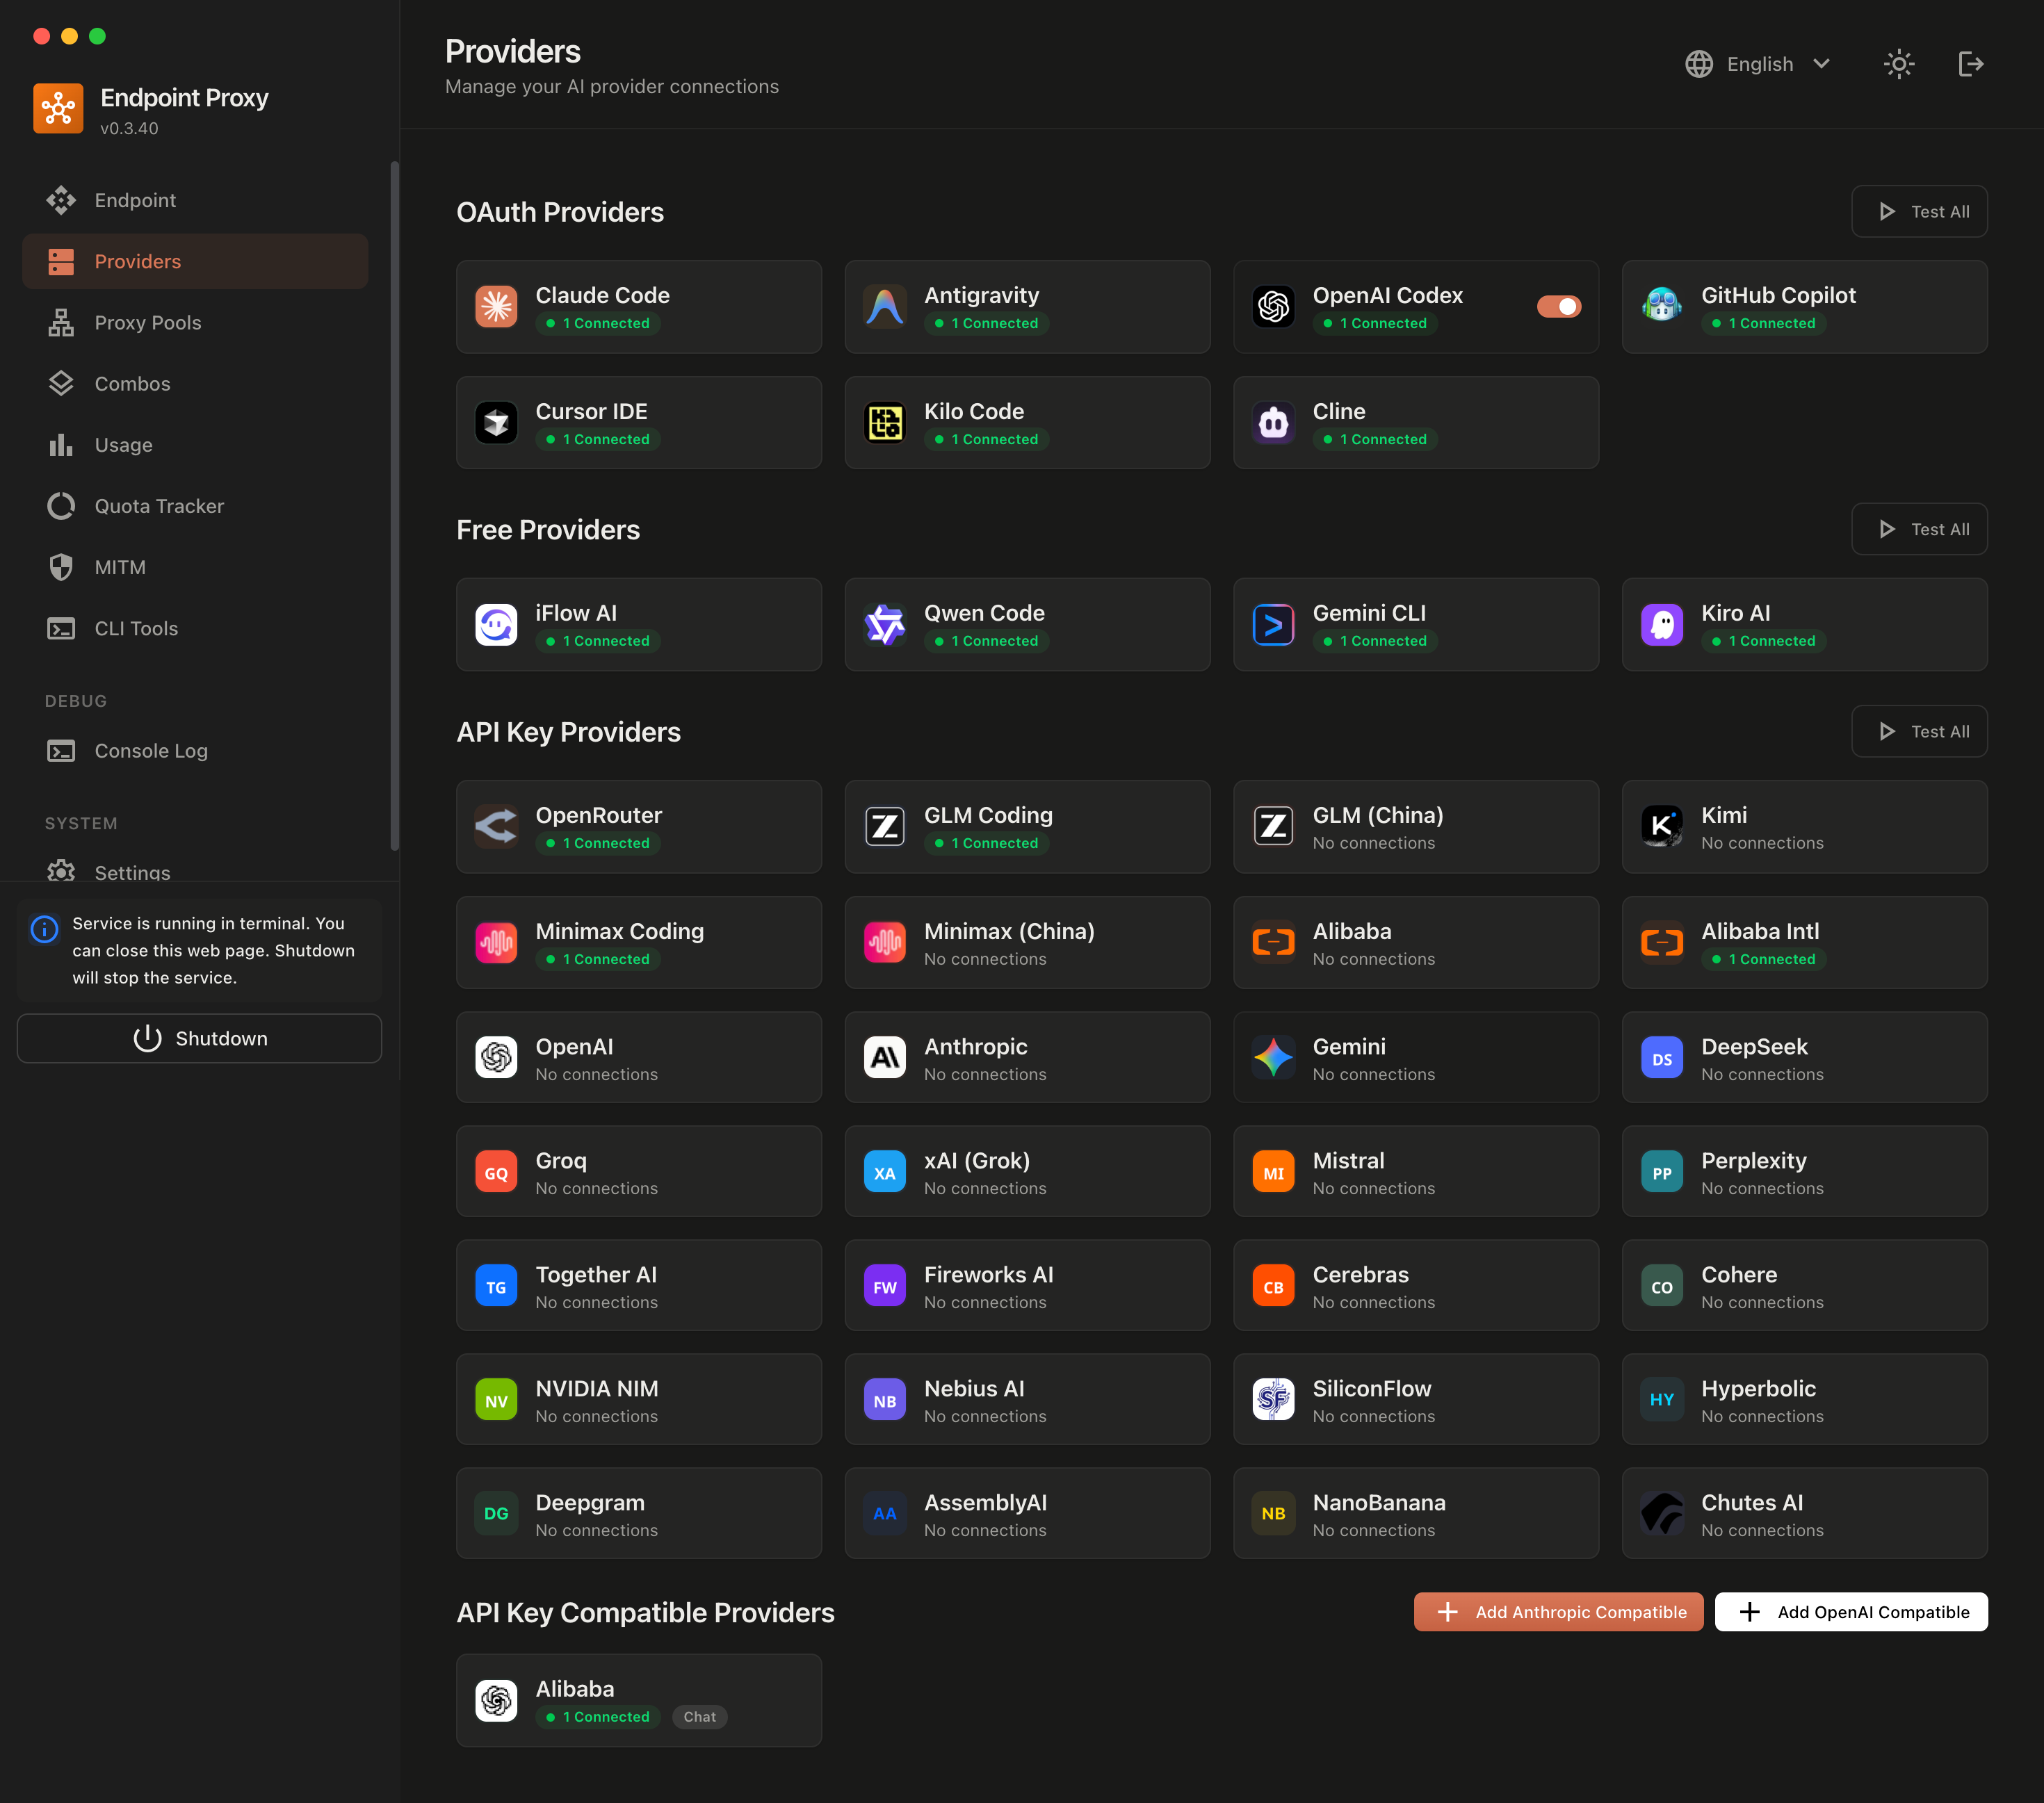 # 9Router - FREE AI Router & Token Saver
Never stop coding. Save 20-40% tokens with RTK + auto-fallback to FREE & cheap AI models.
Connect All AI Code Tools (Claude Code, Cursor, Antigravity, Copilot, Codex, Gemini, OpenCode, Cline, OpenClaw...) to 40+ AI Providers & 100+ Models.



🚀 Quick Start • 💡 Features • 📖 Setup • 🌐 Website
🇧🇷 Português (Brasil) • 🇻🇳 Tiếng Việt • 🇨🇳 中文 • 🇯🇵 日本語 • 🇷🇺 Русский • 🇹🇭 ไทย • 🇮🇷 فارسی • 🇮🇩 Indonesia • 🇪🇸 Español • 🇫🇷 Français
---
Stop wasting money, tokens and hitting limits:
┌─────────────┐
│  Your CLI   │  (Claude Code, Codex, OpenClaw, Cursor, Cline...)
│   Tool      │
└──────┬──────┘
       │ http://localhost:20128/v1
       ↓
┌─────────────────────────────────────────────┐
│           9Router (Smart Router)            │
│  • RTK Token Saver (cut tool_result tokens) │
│  • Format translation (OpenAI ↔ Claude)     │
│  • Quota tracking                           │
│  • Auto token refresh                       │
└──────┬──────────────────────────────────────┘
       │
       ├─→ [Tier 1: SUBSCRIPTION] Claude Code, Codex, GitHub Copilot
       │   ↓ quota exhausted
       ├─→ [Tier 2: CHEAP] GLM ($0.6/1M), MiniMax ($0.2/1M)
       │   ↓ budget limit
       └─→ [Tier 3: FREE] Kiro, OpenCode Free, Vertex ($300 credits)
Result: Never stop coding, minimal cost + 20-40% token savings via RTK
---
1. Install globally:
npm install -g 9router
9router
🎉 Dashboard opens at http://localhost:20128
2. Connect a FREE provider (no signup needed):
Dashboard → Providers → Connect Kiro AI (~50 credits/month free: Claude 4.5 + GLM-5 + MiniMax) or OpenCode Free (no auth) → Done!
3. Use in your CLI tool:
Claude Code/Codex/OpenClaw/Cursor/Cline Settings:
  Endpoint: http://localhost:20128/v1
  API Key: [copy from dashboard]
  Model: kr/claude-sonnet-4.5
That's it! Start coding with FREE AI models.
Alternative: run from source (this repository):
This repository package is private (9router-app), so source/Docker execution is the expected local development path.
cp .env.example .env
npm install
PORT=20128 NEXT_PUBLIC_BASE_URL=http://localhost:20128 npm run dev
Production mode:
npm run build
PORT=20128 HOSTNAME=0.0.0.0 NEXT_PUBLIC_BASE_URL=http://localhost:20128 npm run start
Default URLs:
http://localhost:20128/dashboardhttp://localhost:20128/v1
🇻🇳 Tiếng Việt Tiết kiệm chi phí LLM cho OpenClaw với 9Router by Mì AI |
🇵🇰 اردو / हिन्दी 9Router + Claude Code FREE Unlimited Setup by Build AI With Hamid |
🇺🇸 English 9Router + Claude Code FREE Setup by Build AI With Hamid |
🇺🇸 English 9Router + Claude Code FREE Setup by Build AI With Hamid |
🇺🇸 English Claude Code FREE Forever — Unlimited Models by Build AI With Hamid |
🇺🇸 English Claude CLI Free Setup with 9Router 🚀 by CodeVerse Soban |
🇻🇳 Tiếng Việt Cài Đặt OpenClaw Free Từ A-Z + 9Router by Mai Gia |
🇺🇸 English FREE OpenClaw + Claude Opus 4.6 by Build AI With Hamid |
🇮🇩 Indonesia Koding 24 Jam Anti Rate Limit! Hemat Token AI 65% | Tutorial Quick Setup 9Router 🚀 by Krisswuh |
🇮🇩 Indonesia Cara Deploy 9Router di Hugging Face GRATIS Non-Stop! | Alternatif VPS RAM 16GB by Krisswuh |
🇮🇷 Persian-فارسی این شکلی از هر API ای استفاده کن برای هوش مصنوعی by Matin SenPai |
🇻🇳 Tiếng Việt Hướng Dẫn Setup OpenClaw + 9Router: Tạo Bot Zalo AI Tự Động Từ A-Z by tuanminhhole |
🎬 Made a video about 9Router? Submit a Pull Request adding your video to this section — we'll merge it!
---
9Router works seamlessly with all major AI coding tools:
 Claude-Code |
 OpenClaw |
 Codex |
 OpenCode |
 Cursor |
 Antigravity |
 Cline |
 Continue |
 Droid |
 Roo |
 Copilot |
 Kilo Code |
 OpenDesign |
 jcode |
 Grok Build |
 Devin CLI |
 DeepSeek TUI |
 Qwen Code |
---
|
Claude-Code |
Antigravity |
Codex |
 GitHub |
Cursor |
 Kimchi |
 Kiro AI Claude 4.5 + GLM-5 + MiniMax 50 credits/month free |
OpenCode Free No auth • Auto-fetch models Free (model list varies) |
 Vertex AI Gemini 3 Pro + GLM-5 + DeepSeek $300 credits free |
Note: iFlow, Qwen Code and Gemini CLI free tiers were discontinued in 2026. Use Kiro / OpenCode Free / Vertex instead.
> Kiro AI moved to a paid model in Sep 2025 — the free tier is now capped at 50 credits/month (plus 500 trial credits for new accounts in the first 30 days). Paid tiers: Pro $20/mo (1,000 credits), Pro+ $40/mo (2,000), Pro Max $100/mo (5,000), Power $200/mo (10,000).
OpenCode Free model list fluctuates over time (some models free only for limited promos) — subject to change without notice.
Vertex AI: the $300 free credit for new GCP accounts is still valid, but since Mar 2026 the Gemini API endpoint no longer consumes these credits — call the Vertex AI Studio endpoint instead.
 OpenRouter |
 GLM |
 Kimi |
 MiniMax |
 OpenAI |
 Anthropic |
|
Gemini |
 DeepSeek |
 Groq |
 xAI |
 Mistral |
 Perplexity |
 Together AI |
 Fireworks |
 Cerebras |
 Cohere |
 NVIDIA |
 SiliconFlow |
...and 20+ more providers including Nebius, Chutes, Hyperbolic, and custom OpenAI/Anthropic compatible endpoints
For speech and embeddings served from your own machine — whisper.cpp, faster-whisper, Speaches, Kokoro-FastAPI, openedai-speech, llama.cpp/llama-server, vLLM, Infinity, text-embeddings-inference, or anything else that speaks the OpenAI shape.
| Provider | Endpoint used | Typical server |
| --- | --- | --- |
| Self-hosted STT | /v1/audio/transcriptions | whisper.cpp, faster-whisper |
| Self-hosted TTS | /v1/audio/speech | Kokoro-FastAPI, openedai-speech |
| Self-hosted Embedding | /v1/embeddings | llama-server, vLLM, Infinity |
Every other speech provider is a named cloud service with a fixed endpoint. These three read their address from each connection, so one provider can front several machines and load-balance across them like any other.
Set it on the connection as providerSpecificData.baseUrl:
| Provider | Give it | Result |
| --- | --- | --- |
| Self-hosted STT | the full URL — http://host:8080/v1/audio/transcriptions | used as-is |
| Self-hosted TTS | the server root — http://host:8880 | + /v1/audio/speech |
| Self-hosted Embedding | the OpenAI base, /v1 included — http://host:8080/v1 | + /embeddings |
Mind the/v1on embeddings. The adapter appends/embeddings, so
http://host:8080resolves tohttp://host:8080/embeddingsand misses the
OpenAI route — llama-server answers 501. Give it the same base URL an OpenAI
client would use. A full .../v1/embeddings is also accepted, so a value pasted
from a curl example works too.
The API key is not checked by most local servers, but the field must be non-empty:
it is what gives the connection a credentials record, and baseUrl lives there.
Any placeholder works.
Self-hosted Embedding has no cloud fallback by design — a connection saved
without a baseUrl is reported as a configuration error rather than quietly
falling back to api.openai.com, which would send your input text and API key to
a third party under a provider named "Self-hosted".
---
| Feature | What It Does | Why It Matters |
| --------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------- | ------------------------------------------------- |
| 🚀 RTK Token Saver (RTK ⭐40K) | Compress tool outputs (git diff, grep, ls, tree...) before sending to LLM | Save 20-40% input tokens per request |
| 🧠 Headroom Token Saver (Headroom) | Optional external /v1/compress proxy before provider routing | Save more context tokens without changing clients |
| 🪨 Caveman Mode (Caveman ⭐52K) | Inject caveman-speak prompt → LLM replies terse, technical substance preserved | Save up to 65% output tokens |
| 🐴 Ponytail (Ponytail) | Inject "lazy senior dev" prompt → LLM writes minimal, YAGNI-first code (Lite/Full/Ultra) | Fewer output tokens, less refactoring |
| 🎯 Smart 3-Tier Fallback | Auto-route: Subscription → Cheap → Free | Never stop coding, zero downtime |
| 📊 Real-Time Quota Tracking | Live token count + reset countdown | Maximize subscription value |
| 🔄 Format Translation | OpenAI ↔ Claude ↔ Gemini ↔ Cursor ↔ Kiro ↔ Vertex | Works with any CLI tool |
| 👥 Multi-Account Support | Multiple accounts per provider | Load balancing + redundancy |
| 🔄 Auto Token Refresh | OAuth tokens refresh automatically | No manual re-login needed |
| 🎨 Custom Combos | Create unlimited model combinations | Tailor fallback to your needs |
| 📝 Request Logging | Debug mode with full request/response logs | Troubleshoot issues easily |
| 💾 Cloud Sync | Sync config across devices | Same setup everywhere |
| 📊 Usage Analytics |
→ →
 →
 →
 →
 →