1
 →
Provider-neutral Codex Skill for producing verified AI presenter videos from a script and an authorized presenter image.
cclank/lanshu-create-ai-presenter-video is an open-source project on GitHub, mainly written in HTML. Provider-neutral Codex Skill for producing verified AI presenter videos from a script and an authorized presenter image. It currently holds 2,546 stars and 389 forks with 2 open issues, and was last pushed on 2026-10-06 (repository created 2026-08-20).
Git Homed tracks it on the Video Trending board and on the AI Video Trending list.
English | 简体中文



Turn a topic or script into a verified, publish-ready explainer video — presented by a digital human from one authorized portrait, or acted out on screen in one of nine visual styles — driven by the coding agent you already use.
lanshu-create-ai-presenter-video is an Agent Skill that takes an AI agent through the full production of an explainer video. On the presenter route that means script, narration, presenter generation, lip-sync, captions and keyword motion graphics, editing, rendering, and quality assurance. On the styled route the narration is performed scene by scene in one of nine visual styles, from a word-timed story to a rendered film. Every stage is gated by evidence on disk, and nothing is delivered until the output passes decode and loudness checks.
SKILL.md that loads in Claude Code, Codex, Gemini CLI, Cursor, OpenCode, GitHub Copilot, and other Agent Skills clients. Any agent that can read files and run shell commands can follow it directly.intake to verified, computed from artifacts instead of declared by hand.| Route | The video | You provide | Paid generation | Format | |---|---|---|---|---| | Presenter | A digital human presents; captions and keyword graphics support it | Topic or script + authorized portrait | Voice + presenter video | Any; 9:16 by default | | Styled explainer | No presenter: every narrated phrase is acted out on screen in one of nine visual styles | Topic or script (or your own recorded narration) | Voice only (none with your own narration) | 16:9 |
The agent infers the route from your request or asks once, with the style gallery. The nine styles share one contract — word-timed captions, chapter chips, a performed closing line, a one-frame recap — and differ in how ideas are acted out: editorial paper, tech HUD, notebook and pen, paper pop-up book, pop comic, 3D one-take, drafting sheet, chalkboard, and a clay town. Below is the same moment of the bundled KV cache explainer in all nine:
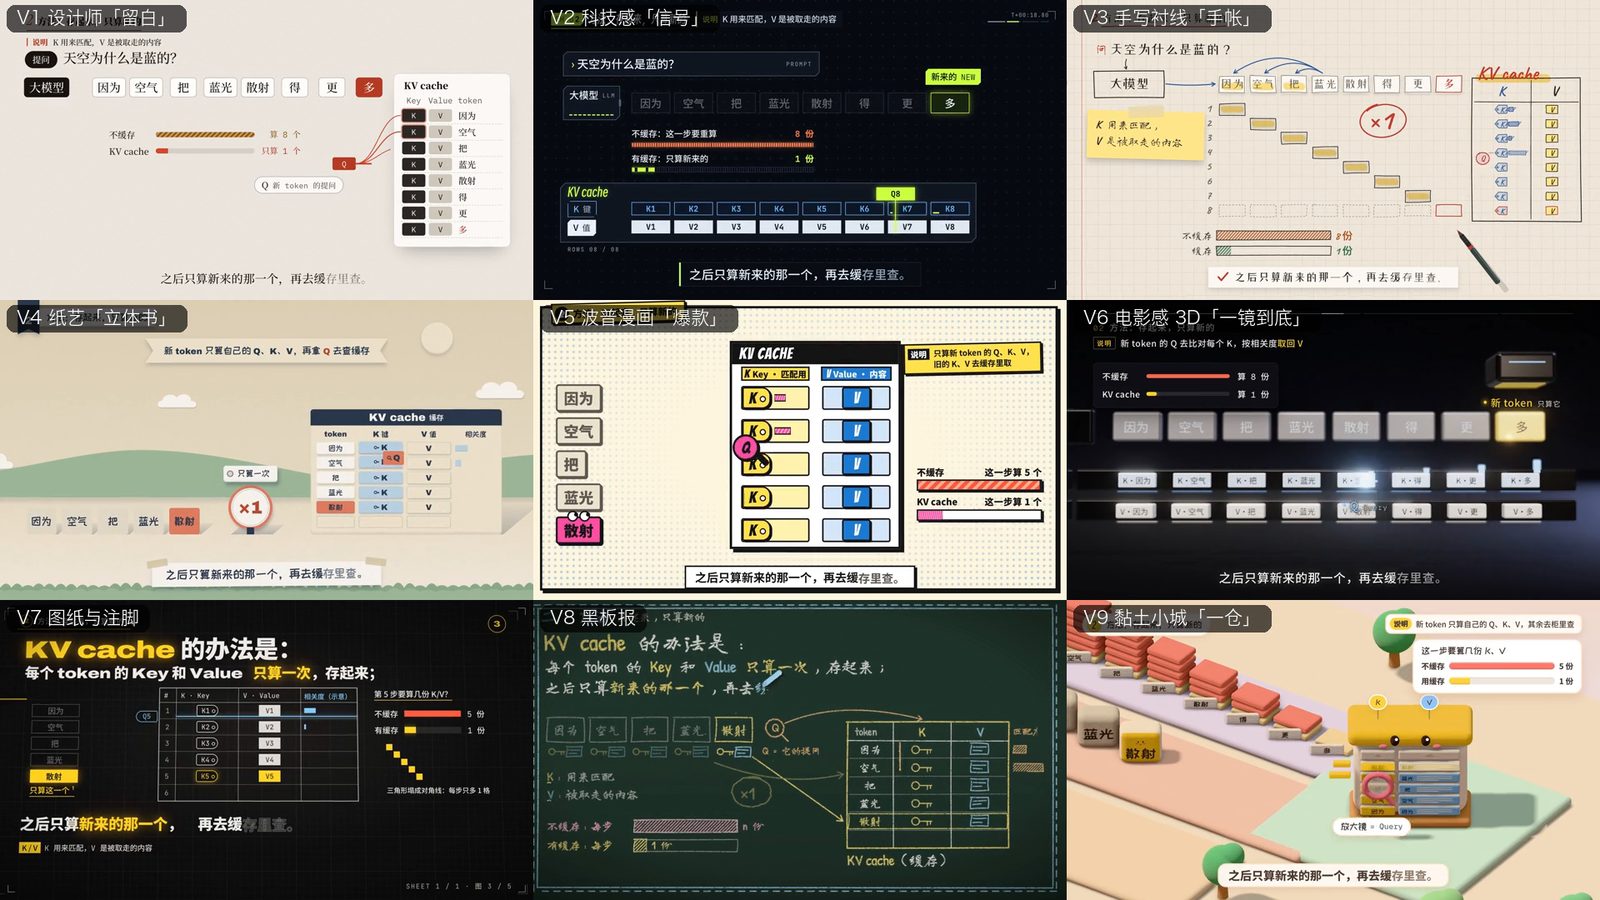
A new topic becomes a playable draft in any style in a few commands — narration, word timing, captions, chapters,
closing line, recap, and sound are generated; the agent then performs each line's scene. See
explainer/STYLES.md to choose a style and
references/styled-explainer.md for the workflow — including an optional method for
bringing your digital human into a styled film.
| Input | Required | Notes | |---|---|---| | Topic or finished script | Yes | A topic becomes a 45–75 second script; a supplied script keeps its natural length. | | Presenter image | Presenter routes | One clear adult presenter, with confirmed rights to use the image. Not needed for the styled explainer. | | Voice sample | No | Used only with explicit cloning authorization; otherwise a stock voice is selected and recorded. | | Supporting media | No | Screen recordings, images, B-roll, or brand assets, used where they prove or clarify a spoken point. | | Delivery preferences | No | Platform, duration, aspect ratio, style, watermark, music, and call to action. |
Presenter route:
Topic or script + authorized portrait
        │
        ▼
Lock script and full narration ──► narration becomes the master clock
        │
        ▼
Low-cost presenter pilot
        │
        ▼
Presenter generation (split at real pauses when a provider caps duration)
        │
        ▼
Audio-driven edit: captions, keyword graphics, cover, close
        │
        ▼
Technical and visual QA
        │
        ▼
Master, share copy, contact sheet, and delivery report
Styled route:
Topic or script ──► choose a style (menu + gallery, or drafts in all nine)
        │
        ▼
Script written for the style ──► voice with word timestamps (or your own narration)
        │
        ▼
Draft film from the style's starter: captions, chapters, closing line, recap, sound
        │
        ▼
Storyboard ──► every line performed on screen, on its words
        │
        ▼
QA (check, stillness, cover) ──► render ──► master, share copy, subtitles, delivery report
Each state requires evidence before a job may advance. check_state.py computes the state from the job's artifacts:
| State | Evidence required |
|---|---|
| intake | Job created |
| content_locked | Passing preflight report, script, beat sheet |
| audio_locked | Decodable final narration, ASR report |
| visual_plan_locked | Timeline, storyboard, approved plan |
| presenter_generated | Recorded presenter capability, selected video, visual review |
| composition_checked | Composition report |
| rendered | Decodable render with video and audio |
| verified | Master, share copy, and a delivery report with passing output loudness |
On the styled route, audio_locked also needs a voiced story.json (a --dry draft never counts), and
presenter_generated is reached by the performed film and its visual review instead of a presenter video.
ffprobe, Bash, jq, awk, and sed.npx), rsync, Python with numpy (sound bed; pointPYTHON at it), and a MiniMax API key (MINIMAX_API_KEY) for the voice and its word timestamps — or your own
recorded narration.
The repository directory is the skill. Clone it into your harness's skills directory and keep the folder name lanshu-create-ai-presenter-video, which the Agent Skills specification requires to match the skill name.
| Harness | Skills directory | Explicit invocation |
|---|---|---|
| Claude Code | ~/.claude/skills/ or project-level .claude/skills/ | /lanshu-create-ai-presenter-video |
| Codex | ~/.codex/skills/ | $lanshu-create-ai-presenter-video |
| Other Agent Skills clients | See the client's documentation, linked from the client list | Client-specific |
For example, with Claude Code:
git clone https://github.com/cclank/lanshu-create-ai-presenter-video.git \
  ~/.claude/skills/lanshu-create-ai-presenter-video
Run git pull in the installed directory to update. If you use several harnesses, clone once into each skills directory.
Agents without Agent Skills support. Clone the repository anywhere, then start the session with:
Read /path/to/lanshu-create-ai-presenter-video/SKILL.md and follow its workflow exactly.
Most harnesses select the skill automatically from its description, so you can describe the video you want:
Turn this script and portrait into a 30-second 16:9 presenter video with live captions.
For a styled explainer you don't need to know the styles yet — ask, and the agent shows the nine with a picture and recommends a few for your topic:
Make a 40-second explainer about RAG, no presenter. Which styles are there?
Use the explicit invocation from the table above to guarantee selection. The skill works in the language of your request.
The agent runs the bundled scripts itself. To set up a job manually, point SKILL_DIR at your installation:
SKILL_DIR=~/.claude/skills/lanshu-create-ai-presenter-video
python3 "$SKILL_DIR/scripts/init_job.py" \
  --job-dir ~/Videos/my-presenter-video \
  --presenter-image ~/Pictures/presenter.png \
  --topic "Context engineering in one minute" \
  --duration 60 \
  --aspect 9:16 \
  --rights-confirmed \
  --adult-presenter-confirmed
Complete the manual review and upload approvals in job.json, then run preflight:
python3 "$SKILL_DIR/scripts/preflight.py" ~/Videos/my-presenter-video/job.json
After each stage, record its artifacts in job.json and let the checker compute the state:
python3 "$SKILL_DIR/scripts/check_state.py" ~/Videos/my-presenter-video/job.json --write
A styled explainer by hand, from a job directory (X=$SKILL_DIR/explainer):
python3 "$SKILL_DIR/scripts/init_job.py" --job-dir . --route styled --explainer-style v8-chalkboard --topic "RAG in 40 seconds"
python3 "$X/tools/story.py" story              # story/script.md → voice + word times → story/story.json
bash "$X/tools/new_film.sh" v8-chalkboard story film   # a playable draft; perform each line in film/beats.js
python3 "$X/tools/qa.py" film qa/film          # check, stillness, snapshots, cover
bash "$X/tools/render.sh" film rag outputs     # master, share copy, subtitles
| Script | Purpose |
|---|---|
| init_job.py | Creates a self-contained job directory, copies all inputs into it, and records job-relative paths. |
| preflight.py | Validates inputs, manual review, and approvals; separates local errors from remote-generation blockers. |
| plan_segments.py | Splits the locked narration at real ASR pauses when a provider caps request or reference-audio duration. |
| check_state.py | Computes the evidence-backed production state and exits non-zero when the recorded state overclaims. |
| finalize_delivery.sh | Builds master and share encodes, verifies full decode, delivered loudness, and black or frozen frames, then publishes them with a contact sheet and report. |
Under explainer/tools/, used on the styled route:
| Tool | Purpose |
|---|---|
| story.py | script.md → MiniMax voice per line with the engine's word timestamps → story.json; --audio for your own narration, --dry for a silent draft, --check for the plan and estimated length. |
| new_film.sh / new_topic.sh | A playable film from a style's starter (or drafts in all nine styles at once). |
| docs.py | Script, beat sheet, timeline, and a storyboard table from the story. |
| qa.py | hyperframes check, snapshots at every chapter, stillness pairs, a cover frame, and a composition report. |
| render.sh | Render, finalize with finalize_delivery.sh, write subtitles (SRT); DRAFT=1 makes a 720p review copy for a phone. |
| srt.py, still_grid.py, fonts.py, sync.sh, stamp.py | Subtitles, a 3×3 style comparison still, font subsets, and project plumbing. |
The agent loads each guide only when it reaches the matching stage, which keeps context usage low.
| Guide | Covers |
|---|---|
| generation.md | Intake, script and narration, capability selection, billing gates, segment planning, presenter prompts |
| editing.md | Timeline contract, segment seams, openings and closes, captions, keyword graphics, preview and export |
| qa-recovery.md | Acceptance gates and recovery playbooks for lip-sync, identity, seams, loudness, and remote tasks |
| styled-explainer.md | The styled explainer route: story pipeline, style starters, performing scenes, and an optional method for adding a digital human |
| explainer/STYLES.md | The style menu and gallery, common words → styles, and how to write the narration for each style |
| explainer/KITS.md | The kit contract, the aesthetic baseline, the starters, and the tools |
| explainer/GOTCHAS.md | HyperFrames pitfalls met while building the styles |
lanshu-create-ai-presenter-video/
├── SKILL.md                 # Skill entry point: metadata and workflow
├── README.md
├── README.zh-CN.md
├── agents/
│   └── openai.yaml          # Codex display metadata; other harnesses ignore it
├── assets/
│   └── job.template.json    # Job manifest template
├── references/              # Stage guides loaded on demand
├── scripts/                 # Job setup, gates, segment planning, delivery
├── explainer/               # Styled explainer engine: core runtime, nine style kits + starters, tools, examples
│   ├── STYLES.md            # Style chooser with the gallery
│   ├── KITS.md              # The kit contract and tools
│   ├── kits//        # One look per style, and starter/ = the film minus the topic
│   ├── stories/             # Example scripts (KV cache) and a draft test story
│   ├── examples/kv-cache/   # The finished KV cache film in each style
│   └── tools/               # story.py, new_film.sh, qa.py, render.sh, srt.py, …
└── tests/
    ├── smoke.sh             # End-to-end test with synthetic media
    └── explainer_smoke.sh   # Styled route: intake, story, starter sync, state
| Setting | Default |
|---|---|
| Format | 9:16, 1080×1920, 30 fps (styled explainer: 16:9, 1920×1080, 30 fps) |
| Duration | 45–75 seconds from a topic; natural length for a supplied script |
| Voice | Stock voice unless an authorized sample is provided; styled route: MiniMax Chinese (Mandarin)_Reliable_Executive, speed set per style |
| Structure | Hook, 2–4 content beats, concise close |
| Music and call to action | Off unless requested |
| Loudness | −16 LUFS ±0.5 LU, true peak ≤ −1 dBTP; override with PROGRAM_LUFS |
--describe false, so frames stay local.
The smoke test drives a synthetic job from intake to verified without calling any remote service. It requires FFmpeg, jq, and Python 3.9+:
bash tests/smoke.sh
bash tests/explainer_smoke.sh   # styled explainer; also needs Node.js and rsync
CI runs metadata validation, a portability check, syntax checks for the explainer engine, and both smoke tests on every push and pull request.
Issues and pull requests are welcome. Reports from different harnesses and providers are especially valuable, as are improvements to the workflow, compatibility, and quality checks. To add a tenth explainer style, follow the kit contract in explainer/KITS.md and the starter brief in explainer/STARTER-BRIEF.md.
Created and maintained by 岚叔 (Lanshu). Follow on X for updates and new AI video workflows:
Released under the MIT License. Fonts, libraries, and services the explainer engine uses are listed in explainer/THIRD_PARTY.md.
→ →
 →
 →
 →
 →
 →
 →