1
 →
The fastest, litest AI Gateway. Rust core with Python SDK. Call 100+ LLM APIs in OpenAI (or native) format with cost tracking, guardrails, load balancing, and logging [Bedrock, Azure, OpenAI
BerriAI/litellm is an open-source project on GitHub, mainly written in Python. The fastest, litest AI Gateway. Rust core with Python SDK. Call 100+ LLM APIs in OpenAI (or native) format with cost tracking, guardrails, load balancing It currently holds 60,575 stars and 12,178 forks with 5,423 open issues, and was last pushed on 2026-10-09 (repository created 2023-07-27).
Git Homed tracks it on the Today's Trending board.
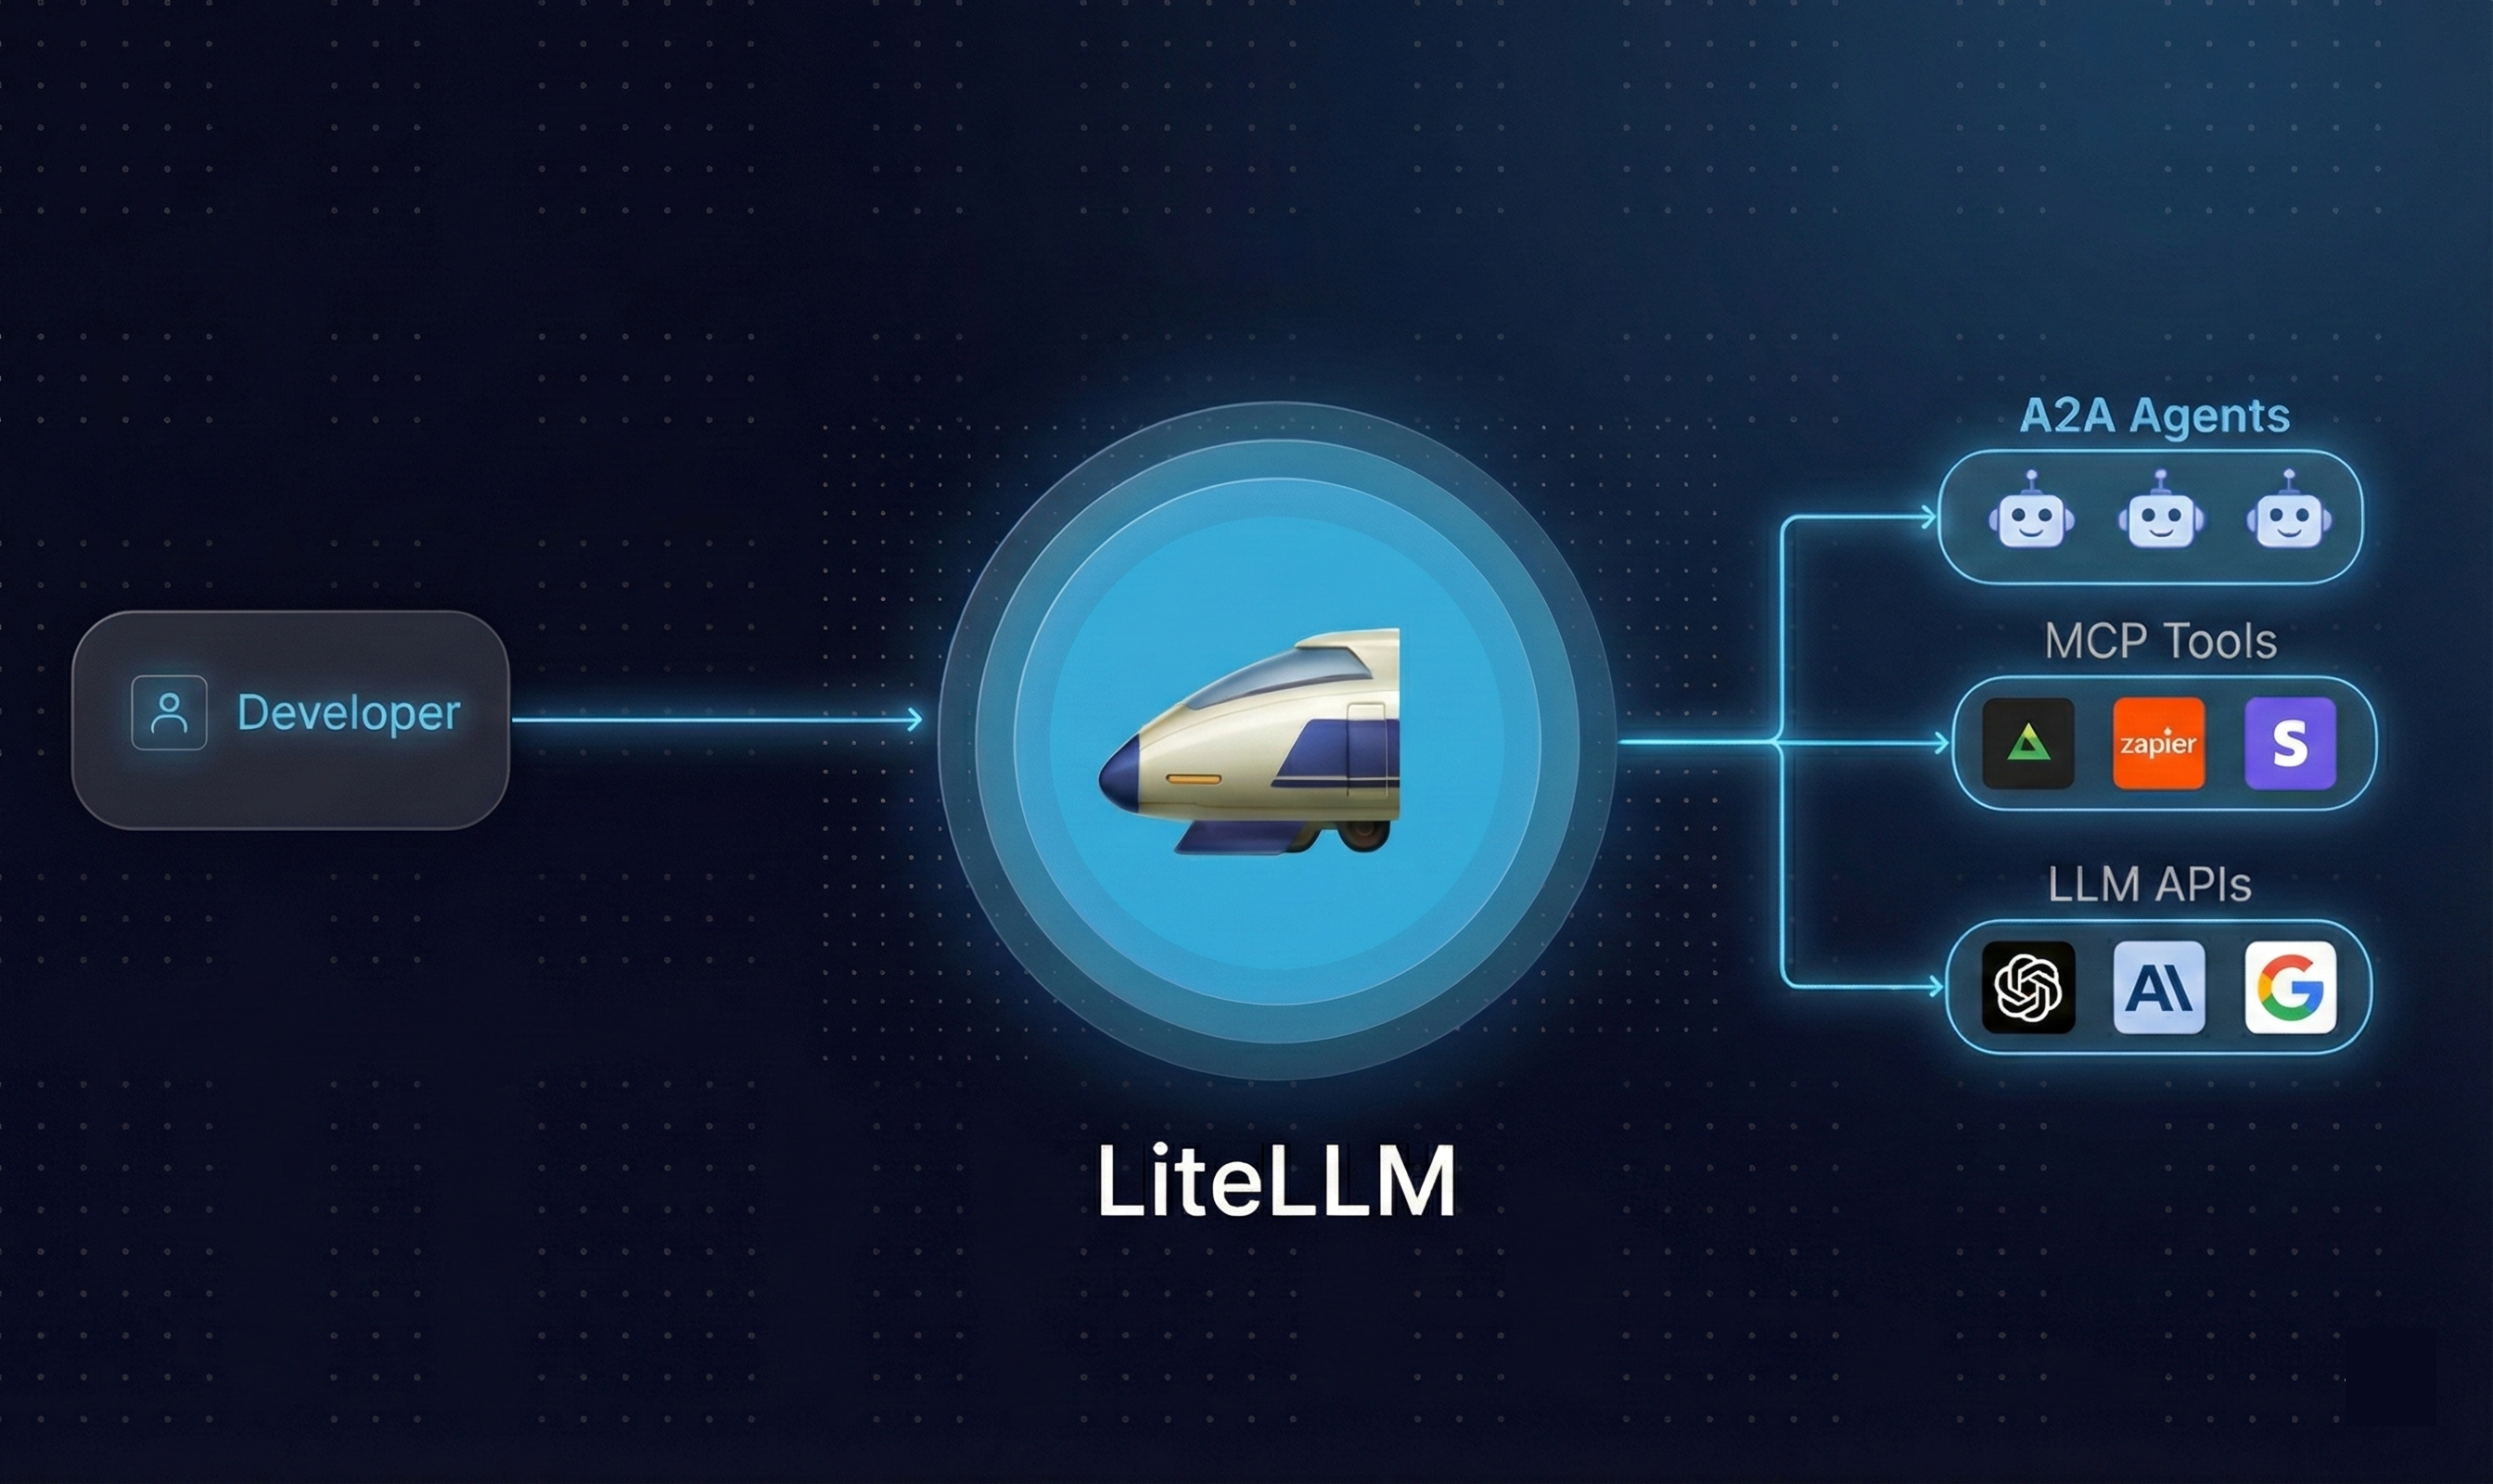
LiteLLM AI Gateway
Open Source AI Gateway for 100+ LLMs. Self-hosted. Enterprise-ready. Call any LLM in OpenAI format.




---
LiteLLM is an open source AI Gateway that gives you a single, unified interface to call 100+ LLM providers — OpenAI, Anthropic, Gemini, Bedrock, Azure, and more — using the OpenAI format.
Use it as a Python SDK for direct library integration, or deploy the AI Gateway (Proxy Server) as a centralized service for your team or organization.
Jump to LiteLLM Proxy (LLM Gateway) Docs
Jump to Supported LLM Providers
---
Managing LLM calls across providers gets complicated fast — different SDKs, auth patterns, request formats, and error types for every model. LiteLLM removes that friction:
 |
 |
 |
 |
 |
Netflix |
 |
---
All Supported Endpoints - /chat/completions, /responses, /embeddings, /images, /audio, /batches, /rerank, /a2a, /messages and more.
uv add litellm
An independent litellm-core distribution provides the Python SDK with the same
import litellm API and runtime dependencies. It has no optional extras, CLI entry
points, or bundled dashboard. Install one SDK distribution per environment because
litellm and litellm-core own overlapping Python files. Use litellm for the
proxy, CLI, and optional extras
Build and install core from this checkout while its release integration is pending:
python scripts/build_core_distribution.py --out-dir dist/core
python -m pip install dist/core/litellm_core-*.whl
The builder requires Git, uv and the Rust build toolchain. It reads the release version
from the root pyproject.toml, leaves source files unchanged, and produces a wheel
and a self-contained sdist in dist/core. Run installation in a fresh environment
without litellm
from litellm import completion
import os
os.environ["OPENAI_API_KEY"] = "your-openai-key"
os.environ["ANTHROPIC_API_KEY"] = "your-anthropic-key"
OpenAI
response = completion(model="openai/gpt-4o", messages=[{"role": "user", "content": "Hello!"}])
Anthropic
response = completion(model="anthropic/claude-sonnet-4-20250514", messages=[{"role": "user", "content": "Hello!"}])
Getting Started - E2E Tutorial - Setup virtual keys, make your first request
uv tool install 'litellm[proxy]'
litellm --model gpt-4o
import openai
client = openai.OpenAI(api_key="anything", base_url="http://0.0.0.0:4000")
response = client.chat.completions.create(
    model="gpt-4o",
    messages=[{"role": "user", "content": "Hello!"}]
)
Supported Providers - LangGraph, Vertex AI Agent Engine, Azure AI Foundry, Bedrock AgentCore, Pydantic AI
from litellm.a2a_protocol import A2AClient
from a2a.types import SendMessageRequest, MessageSendParams
from uuid import uuid4
client = A2AClient(base_url="http://localhost:10001")
request = SendMessageRequest(
    id=str(uuid4()),
    params=MessageSendParams(
        message={
            "role": "user",
            "parts": [{"kind": "text", "text": "Hello!"}],
            "messageId": uuid4().hex,
        }
    )
)
response = await client.send_message(request)
Step 1. Add your Agent to the AI Gateway — set protocolVersion to 1.0 or 0.3 per agent
Step 2. Call Agent via A2A SDK (requires a2a-sdk>=1.1.0)
import httpx
from a2a.client import A2ACardResolver, ClientConfig, ClientFactory
from a2a.types import Message, Part, Role, SendMessageRequest
from a2a.utils.constants import TransportProtocol
from uuid import uuid4
base_url = "http://localhost:4000/a2a/my-agent"  # LiteLLM proxy + agent name
headers = {"Authorization": "Bearer "}    # LiteLLM master key or a virtual key
async with httpx.AsyncClient(headers=headers, timeout=60.0) as http_client:
    resolver = A2ACardResolver(httpx_client=http_client, base_url=base_url)
    agent_card = await resolver.get_agent_card()
    config = ClientConfig(
        httpx_client=http_client,
        streaming=False,
        supported_protocol_bindings=[TransportProtocol.JSONRPC, TransportProtocol.HTTP_JSON],
    )
    client = ClientFactory(config).create(agent_card)
request = SendMessageRequest(
        message=Message(
            message_id=uuid4().hex,
            role=Role.ROLE_USER,
            parts=[Part(text="Hello!")],
        )
    )
    async for event in client.send_message(request):
        populated = event.ListFields()
        if populated and populated[0][0].name in ("message", "msg"):
            print("".join(getattr(p, "text", "") or "" for p in populated[0][1].parts))
from mcp import ClientSession, StdioServerParameters
from mcp.client.stdio import stdio_client
from litellm import experimental_mcp_client
import litellm
server_params = StdioServerParameters(command="python", args=["mcp_server.py"])
async with stdio_client(server_params) as (read, write):
    async with ClientSession(read, write) as session:
        await session.initialize()
# Load MCP tools in OpenAI format
        tools = await experimental_mcp_client.load_mcp_tools(session=session, format="openai")
# Use with any LiteLLM model
        response = await litellm.acompletion(
            model="gpt-4o",
            messages=[{"role": "user", "content": "What's 3 + 5?"}],
            tools=tools
        )
Step 1. Add your MCP Server to the AI Gateway
Step 2. Call MCP tools via /chat/completions
curl -X POST 'http://0.0.0.0:4000/v1/chat/completions' \
  -H 'Authorization: Bearer ' \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "gpt-4o",
    "messages": [{"role": "user", "content": "Summarize the latest open PR"}],
    "tools": [{
      "type": "mcp",
      "server_url": "litellm_proxy/mcp/github",
      "server_label": "github_mcp",
      "require_approval": "never"
    }]
  }'
{
  "mcpServers": {
    "LiteLLM": {
      "url": "http://localhost:4000/mcp/",
      "headers": {
        "x-litellm-api-key": "Bearer "
      }
    }
  }
}
For MCP OAuth, an upstream may advertise dynamic client registration but refuse requests with HTTP 401 or 403. If the provider requires a pre-registered OAuth app, configure its credentials.client_id and, when required, credentials.client_secret on the MCP server. This skips dynamic registration in the gateway sign-in flow. The provider must approve the app for MCP access; reaching its authorization page does not establish that login or tool calls will succeed
import litellm
from litellm import Harness, sandbox
result = litellm.agent(
    Harness.CLAUDE_CODE,  # or Harness.CODEX, Harness.OPENCODE, Harness.DEEPAGENTS
    "Find why tests/test_router.py is flaky and fix it.",
    sandbox=sandbox.local("./repo"),
    model="litellm_proxy/claude-sonnet-4-5",  # a model group on your AI Gateway
)
print(result.text, result.cost, [f.path for f in result.files])
Set LITELLM_PROXY_API_BASE and LITELLM_PROXY_API_KEY and every model call the agent makes goes through your AI Gateway, tagged harness,claude_code. Drop the litellm_proxy/ prefix to call a provider directly. Install starlette uvicorn plus the agent's CLI (claude, codex or opencode), or deepagents langchain-litellm for Deep Agents.
| Provider | /chat/completions | /messages | /responses | /embeddings | /image/generations | /audio/transcriptions | /audio/speech | /moderations | /batches | /rerank |
|-------------------------------------------------------------------------------------|---------------------|-------------|--------------|---------------|----------------------|-------------------------|-----------------|----------------|-----------|-----------|
| Abliteration (abliteration) | ✅ | | | | | | | | | |
| AI/ML API (aiml) | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | |
| AI21 (ai21) | ✅ | ✅ | ✅ | | | | | | | |
| AI21 Chat (ai21_chat) | ✅ | ✅ | ✅ | | | | | | | |
| Aleph Alpha | ✅ | ✅ | ✅ | | | | | | | |
| Amazon Nova | ✅ | ✅ | ✅ | | | | | | | |
| Anthropic (anthropic) | ✅ | ✅ | ✅ | | | | | | ✅ | |
| Anthropic Text (anthropic_text) | ✅ | ✅ | ✅ | | | | | | ✅ | |
| Anyscale | ✅ | ✅ | ✅ | | | | | | | |
| AssemblyAI (assemblyai) | ✅ | ✅ | ✅ | | | ✅ | | | | |
| Auto Router (auto_router) | ✅ | ✅ | ✅ | | | | | | | |
| AWS - Bedrock (bedrock) | ✅ | ✅ | ✅ | ✅ | | | | | | ✅ |
| AWS - Sagemaker (sagemaker) | ✅ | ✅ | ✅ | ✅ | | | | | | |
| Azure (azure) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | |
| Azure AI (azure_ai) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | |
| Azure Text (azure_text) | ✅ | ✅ | ✅ | | | ✅ | ✅ | ✅ | ✅ | |
| Baseten (baseten) | ✅ | ✅ | ✅ | | | | | | | |
| Bytez (bytez) | ✅ | ✅ | ✅ | | | | | | | |
| Cerebras (cerebras) | ✅ | ✅ | ✅ | | | | | | | |
| Clarifai (clarifai) | ✅ | ✅ | ✅ | | | | | | | |
| Cloudflare AI Workers (cloudflare) | ✅ | ✅ | ✅ | | | | | | | |
| Codestral (codestral) | ✅ | ✅ | ✅ | | | | | | | |
| Cognition (cognition) | ✅ | ✅ | ✅ | | | | | | | |
| Cohere (cohere) | ✅ | ✅ | ✅ | ✅ | | | | | | ✅ |
| Cohere Chat (cohere_chat) | ✅ | ✅ | ✅ | | | | | | | |
| CometAPI (cometapi) | ✅ | ✅ | ✅ | ✅ | | | | | | |
| CompactifAI (compactifai) | ✅ | ✅ | ✅ | | | | | | | |
| Custom (custom) | ✅ | ✅ | ✅ | | | | | | | |
| Custom OpenAI (custom_openai) | ✅ | ✅ | ✅ | | | ✅ | ✅ | ✅ | ✅ | |
| Dashscope (dashscope) | ✅ | ✅ | ✅ | ✅ | | | | | | ✅ |
| Databricks (databricks) | ✅ | ✅ | ✅ | | | | | | | |
| DataRobot (datarobot) | ✅ | ✅ | ✅ | | | | | | | |
| Deepgram (deepgram) | ✅ | ✅ | ✅ | | | ✅ | | | | |
| DeepInfra (deepinfra) | ✅ | ✅ | ✅ | | | | | | | |
| Deepseek (deepseek) | ✅ | ✅ | ✅ | | | | | | | |
| Eden AI (edenai) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | | | |
| ElevenLabs (elevenlabs) | ✅ | ✅ | ✅ | | | ✅ | ✅ | | | |
| Empower (empower) | ✅ | ✅ | ✅ | | | | | | | |
| Fal AI (fal_ai) | ✅ | ✅ | ✅ | | ✅ | | | | | |
| Featherless AI (featherless_ai) | ✅ | ✅ | ✅ | | | | | | | |
| Fireworks AI (fireworks_ai) | ✅ | ✅ | ✅ | | | | | | | |
| FriendliAI (friendliai) | ✅ | ✅ | ✅ | | | | | | | |
| Galadriel (galadriel) | ✅ | ✅ | ✅ | | | | | | | |
| GitHub Copilot (github_copilot) | ✅ | ✅ | ✅ | ✅ | | | | | | |
| GitHub Models (github) | ✅ | ✅ | ✅ | | | | | | | |
| Google - PaLM | ✅ | ✅ | ✅ | | | | | | | |
| Google - Vertex AI (vertex_ai) | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | |
| Google AI Studio - Gemini (gemini) | ✅ | ✅ | ✅ | | | | | | | |
| GradientAI (gradient_ai) | ✅ | ✅ | ✅ | | | | | | | |
| Groq AI (groq) | ✅ | ✅ | ✅ | | | | | | | |
| Heroku (heroku) | ✅ | ✅ | ✅ | | | | | | | |
| Hosted VLLM (hosted_vllm) | ✅ | ✅ | ✅ | | | | | | | |
| Huggingface (huggingface) | ✅ | ✅ | ✅ | ✅ | | | | | | ✅ |
| Hyperbolic (hyperbolic) | ✅ | ✅ | ✅ | | | | | | | |
| IBM - Watsonx.ai (watsonx) | ✅ | ✅ | ✅ | ✅ | | | | | | |
| Infinity (infinity) | | | | ✅ | | | | | | |
| Jina AI (jina_ai) | | | | ✅ | | | | | | |
| Lambda AI (lambda_ai) | ✅ | ✅ | ✅ | | | | | | | |
| Lemonade (lemonade) | ✅ | ✅ | ✅ | | | | | | | |
| LiteLLM Proxy (litellm_proxy) | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | |
| Llamafile (llamafile) | ✅ | ✅ | ✅ | | | | | | | |
| LM Studio (lm_studio) | ✅ | ✅ | ✅ | | | | | | | |
| Maritalk (maritalk) | ✅ | ✅ | ✅ | | | | | | | |
| Meta - Llama API (meta_llama) | ✅ | ✅ | ✅ | | | | | | | |
| Mistral AI API (mistral) | ✅ | ✅ | ✅ | ✅ | | | | | | |
| ModelScope (modelscope) | ✅ | ✅ | ✅ | | ✅ | | | | | |
| Moonshot (moonshot) | ✅ | ✅ | ✅ | | | | | | | |
| Morph (morph) | ✅ | ✅ | ✅ | | | | | | | |
| Nebius AI Studio (nebius) | ✅ | ✅ | ✅ | ✅ | | | | | | |
| NLP Cloud (nlp_cloud) | ✅ | ✅ | ✅ | | | | | | | |
| Novita AI (novita) | ✅ | ✅ | ✅ | | | | | | | |
| Nscale (nscale) | ✅ | ✅ | ✅ | | | | | | | |
| Nvidia NIM (nvidia_nim) | ✅ | ✅ | ✅ | | | | | | | |
| OCI (oci) | ✅ | ✅ | ✅ | | | | | | | |
| Ollama (ollama) | ✅ | ✅ | ✅ | ✅ | | | | | | |
| Ollama Chat (ollama_chat) | ✅ | ✅ | ✅ | | | | | | | |
| Oobabooga (oobabooga) | ✅ | ✅ | ✅ | | | ✅ | ✅ | ✅ | ✅ | |
| OpenAI (openai) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | |
| OpenAI-like (openai_like) | | | | ✅ | | | | | | |
| OpenRouter (openrouter) | ✅ | ✅ | ✅ | | | | | | | |
| OVHCloud AI Endpoints (ovhcloud) | ✅ | ✅ | ✅ | | | | | | | |
| Perplexity AI (perplexity) | ✅ | ✅ | ✅ | | | | | | | |
| Petals (petals) | ✅ | ✅ | ✅ | | | | | | | |
| Pinstripes (pinstripes) | ✅ | ✅ | ✅ | | | | | | | |
| Predibase (predibase) | ✅ | ✅ | ✅ | | | | | | | |
| Qianwen AI Platform (qwen_ai_platform) | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | ✅ |
| QwenCloud (qwencloud) | ✅ | ✅ | ✅ | ✅ | ✅ | | | | | ✅ |
| Recraft (recraft) | | | | | ✅ | | | | | |
| Replicate (replicate) | ✅ | ✅ | ✅ | | | | | | | |
| Sagemaker Chat (sagemaker_chat) | ✅ | ✅ | ✅ | | | | | | | |
| Sail (sail) | ✅ | ✅ | ✅ | | | | | | | |
| [Sambanova
→ →
 →
 →
 →
 →
 →
 →