1
 →
apache/datafusion-comet is an open-source project on GitHub, mainly written in Scala. Apache DataFusion Comet Spark Accelerator It currently holds 1,305 stars and 404 forks with 0 open issues, and was last pushed on an unknown date (repository created unknown).
Git Homed tracks it on the Today's Trending board, currently at rank #49 with 1 new stars today.
[![Apache licensed][license-badge]][license-url] [![Discord chat][discord-badge]][discord-url] [![Pending PRs][pending-pr-badge]][pending-pr-url] [![Maven Central][maven-badge]][maven-url]
[license-badge]: https://img.shields.io/badge/license-Apache%20v2-blue.svg [license-url]: https://github.com/apache/datafusion-comet/blob/main/LICENSE.txt [discord-badge]: https://img.shields.io/discord/885562378132000778.svg?logo=discord&style=flat-square [discord-url]: https://discord.gg/3EAr4ZX6JK [pending-pr-badge]: https://img.shields.io/github/issues-search/apache/datafusion-comet?query=is%3Apr+is%3Aopen+draft%3Afalse+review%3Arequired+-status%3Afailure&label=Pending%20PRs&logo=github [pending-pr-url]: https://github.com/apache/datafusion-comet/pulls?q=is%3Apr+is%3Aopen+draft%3Afalse+review%3Arequired+-status%3Afailure+sort%3Aupdated-desc [maven-badge]: https://img.shields.io/maven-central/v/org.apache.datafusion/comet-spark-spark4.0_2.13 [maven-url]: https://search.maven.org/search?q=g:org.apache.datafusion%20AND%20comet-spark
Apache DataFusion Comet is a high-performance accelerator for Apache Spark. Comet keeps Spark queries Arrow-native end-to-end: operators, expressions, shuffle, and broadcast all stay in Apache Arrow columnar format, avoiding the per-row overhead of Spark's row-based engine. Within the Arrow-native pipeline, operators and expressions execute as Rust code (via the [Apache DataFusion] query engine) or as JVM code that operates directly on Arrow batches. Comet integrates with the Spark ecosystem without requiring any code changes.
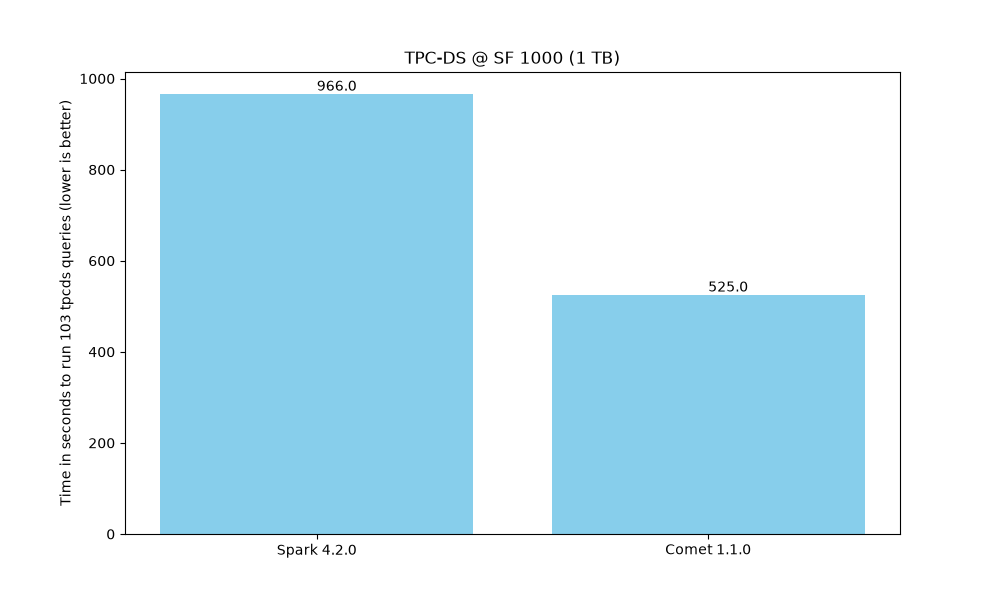
Comet provides a ~1.8x speedup over Spark 4.2 for TPC-DS @ SF 1000 (1TB), resulting in ~45% cost savings.
That speedup gives you a choice: finish the same Spark workload in just over half the time on the cluster you already have, or match your current Spark performance on just over half the resources. Either way, the gain translates directly into lower cloud bills, reduced on-prem capacity, and lower energy usage, with no changes to your existing Spark SQL, DataFrame, or PySpark code. Comet runs on commodity hardware: no GPUs, FPGAs, or other specialized accelerators are required, so the savings come from better utilization of the infrastructure you already run on.
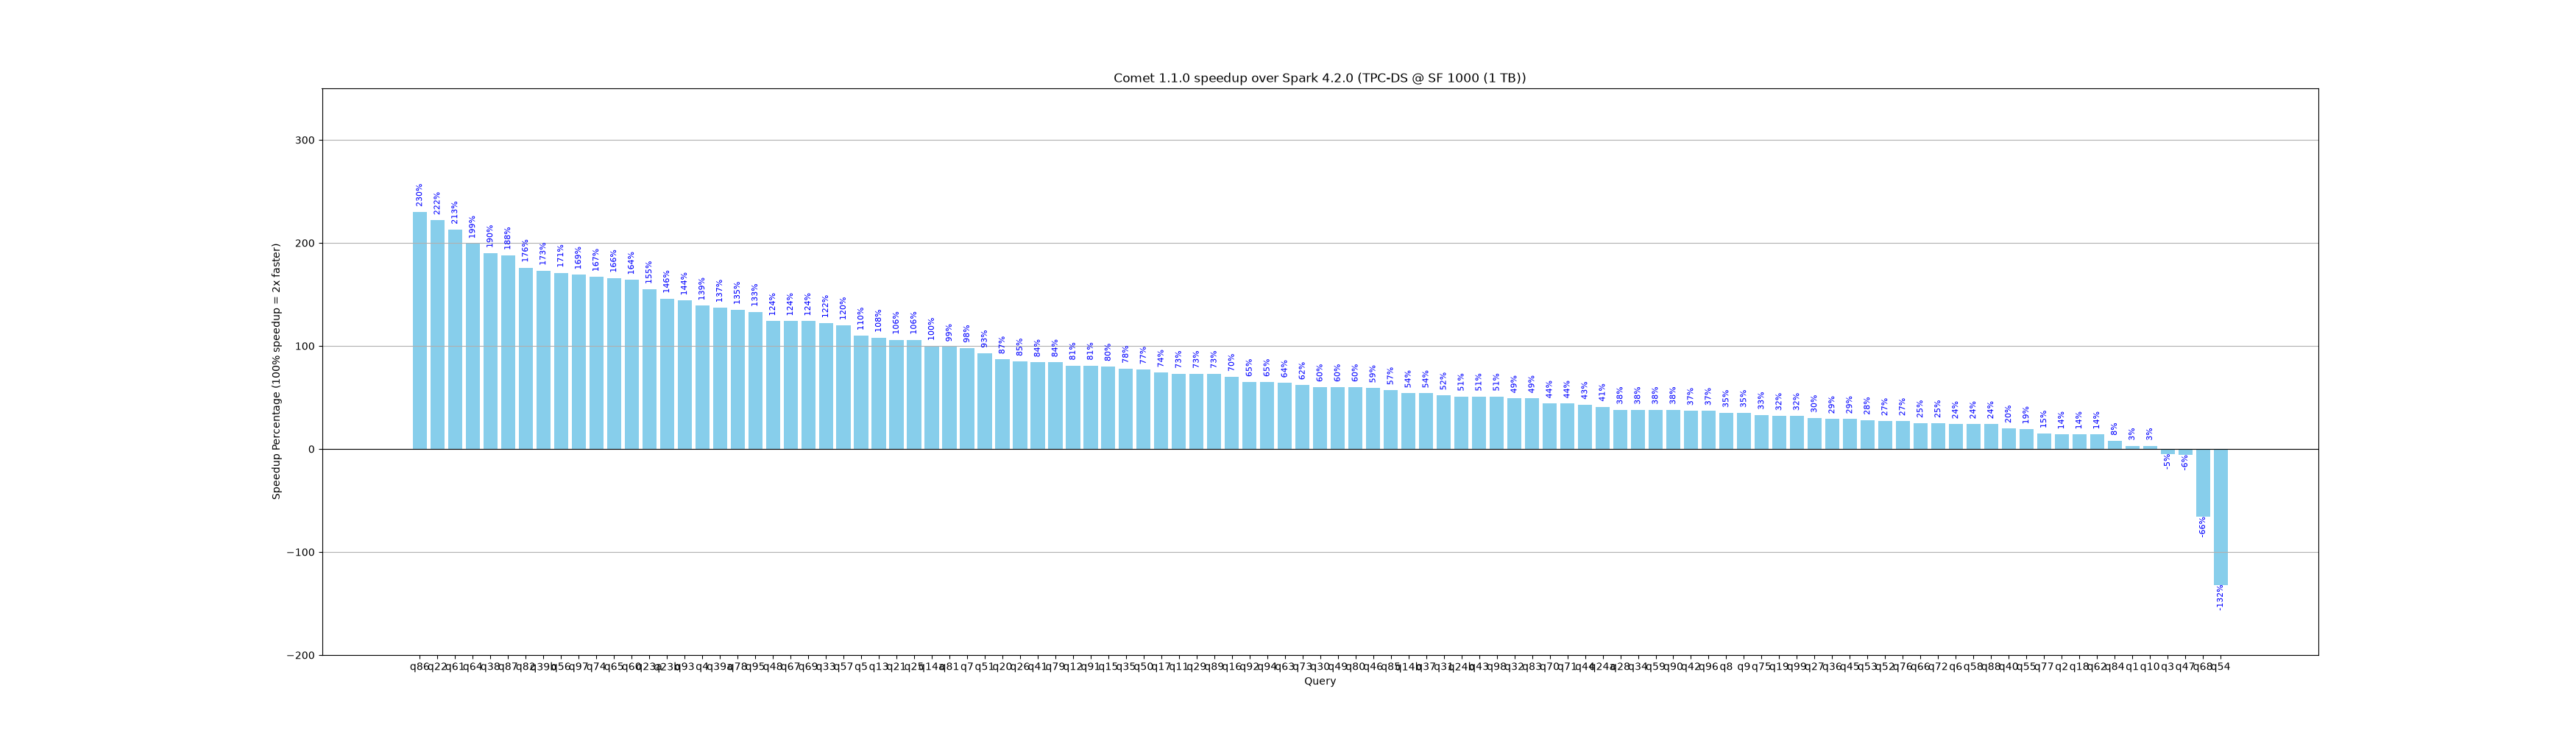
See the Comet Benchmarking Guide for more details.
[Apache DataFusion]: https://datafusion.apache.org
Comet accelerates Spark workloads by replacing Spark operators and expressions with high-performance implementations that process Apache Arrow columnar data directly. Most operators are powered by native Rust execution built on Apache DataFusion, while others run efficiently in the JVM on Arrow batches. This unified columnar execution model keeps processing within the Comet engine end-to-end, reducing overhead and delivering faster, more efficient query execution without reverting to Spark's traditional row-based engine.
FILTER (WHERE ...) clausesFor the authoritative lists, see the supported expressions and supported operators pages.
Comet is designed as a drop-in accelerator for Apache Spark, allowing you to integrate Comet into your existing Spark deployments and workflows seamlessly. With no code changes required, you can immediately harness the benefits of Comet's acceleration capabilities without disrupting your Spark applications.
Comet supports Apache Spark 3.4, 3.5, 4.0, 4.1, and 4.2. See the installation guide for the detailed version, Java, and Scala compatibility matrix.
Install Comet by adding the jar for your Spark and Scala version to the Spark classpath and enabling the plugin. A typical configuration looks like:
export COMET_JAR=/path/to/comet-spark-spark3.5_2.12-.jar
$SPARK_HOME/bin/spark-shell \
    --jars $COMET_JAR \
    --conf spark.driver.extraClassPath=$COMET_JAR \
    --conf spark.executor.extraClassPath=$COMET_JAR \
    --conf spark.plugins=org.apache.spark.CometPlugin \
    --conf spark.shuffle.manager=org.apache.spark.sql.comet.execution.shuffle.CometShuffleManager \
    --conf spark.comet.explain.fallback.enabled=true \
    --conf spark.memory.offHeap.enabled=true \
    --conf spark.memory.offHeap.size=4g \
    --conf spark.executor.memoryOverhead=2g
For full installation instructions, published jar downloads, and configuration reference, see the installation guide and the configuration reference.
Join the DataFusion Slack and Discord channels to connect with other users, ask questions, and share your experiences with Comet.
We welcome contributions from the community to help improve and enhance Apache DataFusion Comet. Whether it's fixing bugs, adding new features, writing documentation, or optimizing performance, your contributions are invaluable in shaping the future of Comet. Check out our contributor guide to get started.
Apache DataFusion Comet is licensed under the Apache License 2.0. See the LICENSE.txt file for details.
→ →
 →
 →
 →
 →
 →→