1
 →
An all-in-one, pure C++ inference engine for audio models, powered by ggml. Supports TTS, STT, VAD, voice conversion, music generation, and more, with highly optimized performance.
0xShug0/audio.cpp is an open-source project on GitHub, mainly written in C++. An all-in-one, pure C++ inference engine for audio models, powered by ggml. Supports TTS, STT, VAD, voice conversion, music generation, and more It currently holds 3,030 stars and 344 forks with 20 open issues, and was last pushed on 2026-09-25 (repository created 2026-06-23).
Git Homed tracks it on the Audio Trending board and on the AI Audio Trending list.

audio.cpp is a high-performance C++ audio inference framework built on top of ggml, designed to make modern local audio models practical, portable, and fast.
Tired of juggling a dozen Conda environments, hundreds of Python packages, and dependency conflicts just to try a few audio models? audio.cpp gives those paths a shared native runtime instead. Runs on Windows, Linux, and macOS, with support for NVIDIA, AMD, Apple Silicon, and CPU-only machines.
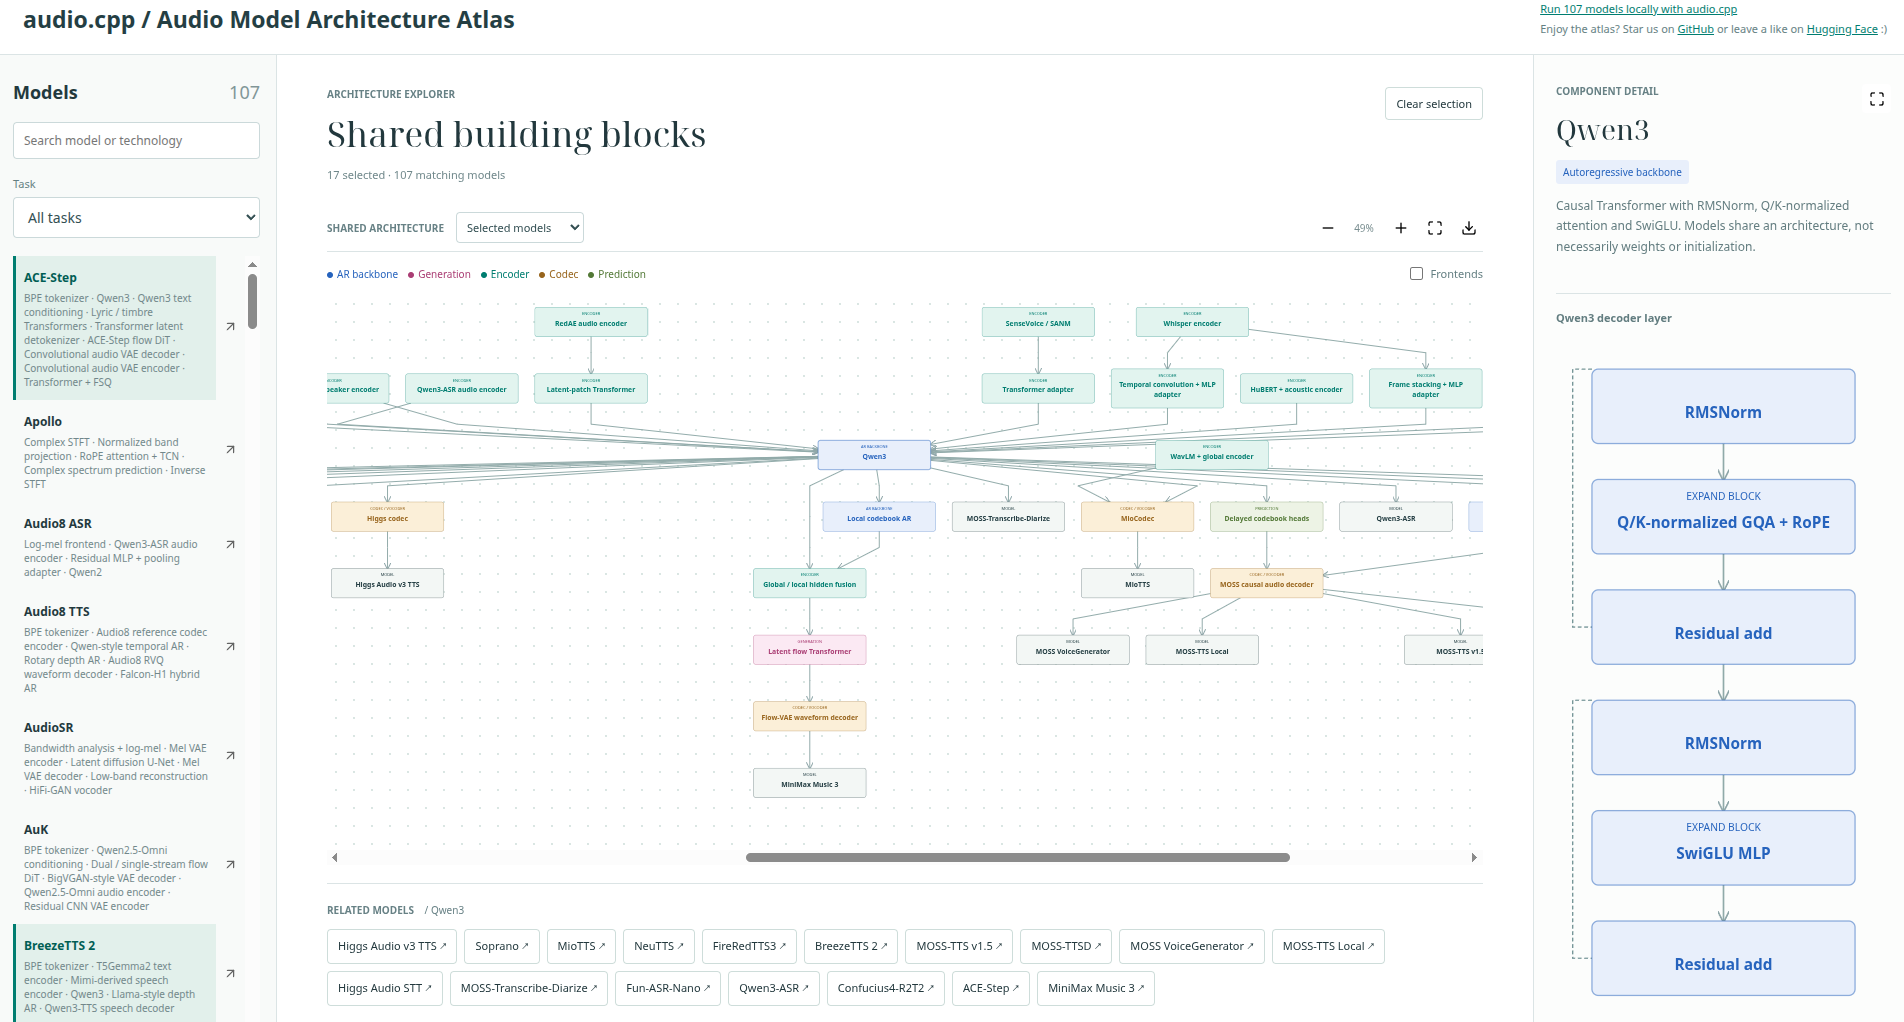
Lost in a sea of audio model names, papers, and codebases? Explore 100+ audio models in the Audio Model Architecture Atlas to see how they're built, what they share, and where they differ, whether you're learning or building your own.


[!IMPORTANT]
> v0.9.1 highlights: LFM2.5-Audio brings speech recognition, speech generation, and speech-to-speech conversations to audio.cpp. Higgs Audio TTS runs faster at around 6 GB VRAM, and the WebUI adds experimental generation history to revisit your results!
>Unsloth integration: audio.cpp now powers speech, music, and speech-to-text in Unsloth Studio!
> 110+ audio model families and 190+ variants, running locally. Explore TTS, ASR, music generation, voice conversion, separation, and more through a shared CLI, server API, and WebUI. Built with contributions from the community.
> Arena UI: The new Arena tab makes it easier to compare local models side by side for TTS, voice conversion, and ASR. Use one shared input, queue multiple models or GGUF variants, then review outputs with metrics!
> Performance: Selected CUDA TTS paths run 1.8-8x faster than Python, while tested Q8 GGUF packages deliver up to 1.53x speedup and 37% lower peak VRAM versus 16-bit weights; see the GGUF guide and Q8 performance report.
> Production deployment example: Try Fun-ASR-Nano and SenseVoice with audio.cpp on the FunASR platform!
> VibeVoice 1.5B: generates a 93.9-minute podcast in 18.2 minutes with 10 diffusion steps and without quantization, running about 5.15x faster than real time.
> Supertonic 3: generates about 10 hours of audio in 3 minutes on RTX5090. Up to 200x+ real-time on CUDA, 6x+ real-time on CPU, and 47 ms TTFT in CUDA streaming mode.
Demo: 10 hours of audio generated in 3 minutes.
> Real-world ASR win: In TranscrIA benchmark on messy French meeting audio, audio.cpp’s Nemotron 3.5 ASR matched the same WER as other implementations while using about 1/4 of the wall time.
It is built for real end-to-end execution rather than one-off model demos: the same runtime powers TTS, voice cloning, voice conversion, ASR, diarization, VAD, source separation, alignment, codec-style models, and higher-level workflows through a common framework surface.
Highlights:
ggml, with CUDA, HIP/ROCm, Vulkan, Metal, and CPU backends behind shared CLI and server entry points instead of Python-only deployment paths.The goal of the framework is to provide highly optimized, reusable building blocks for audio-related models, so new model integrations can be brought up faster, shared components can be improved once and benefit many families, and real end-to-end inference paths can stay efficient, maintainable, and portable.
audio.cpp would not be moving this quickly without generous contributors bringing in real fixes, new capabilities, and careful polish. See CONTRIBUTING.md for how to contribute and for a shout-out to the people already helping shape the project.
[!TIP]
Contribution focus: the most helpful contributions right now are improvements to the UI, API server, and pipeline/workflow subsystems. These areas make the existing model surface easier to use, serve, compose, and validate. See CONTRIBUTING.md for more details.
> New model PRs: before starting a new model port, please check the supported model table because several families are already implemented or under testing and read the New Model PRs section in CONTRIBUTING.md. New ports should start under the community models surface, where review is lighter than core models but still needs reproducible validation.
[!IMPORTANT]
2026-10-07 - Release v0.9.1: New models include LFM2.5-Audio, Audio Flamingo 3/Next, OWSM/OWSM-CTC, Index-Echo translation, CrisperWhisper2, KittenTTS2, KugelAudio, RE-USE, Sidon, and Smart Turn. The WebUI adds more models, elapsed-time tracking, settings import/export, and experimental generation history. This release also improves CPU/GPU performance, memory use, streaming, and cross-platform compatibility. Thanks to everyone contributing code, testing, and feedback!
> 2026-09-30 - Release v0.9.0: 100+ audio models, an enhancement and denoising WebUI tab, speaker-tagged ASR, and performance and memory improvements. Explore the Architecture Atlas. Thanks to our community!
> 2026-09-15 - Release v0.8.0: 80+ model families and 120+ variants, including YuE2 and SheetSage2, plus MP3/HTTPS frontend modules. Thanks to @DrewThomasson for Colab, @christopherthompson81 for the C ABI, and @XsquirrelC for VibeASR and BitNet support!
> 2026-08-26 - Release 0.7: This release adds MiniMax Music 3, MagpieTTS, PersonaPlex, MeanVC2, AudioSR, ControlFoley, FireRedTTS3, FireRedAudio, MiDashengLM-Gen, F5-TTS/Habibi, Granite Speech 5.0 TurboCTC, MMS Forced Aligner, and MOSS-VoiceGenerator, plus DotTTS Edit and ACE-Step 1.5 XL variants, bringing audio.cpp to 62 total model families and 85+ model variants! It also introduces the new Arena UI for side-by-side TTS, voice-conversion, and ASR comparison with shared inputs, queued runs, metrics, and result sorting.
> 2026-08-13 - Release 0.6: This release adds 5 new model families - DotTTS, NeuTTS, MuScriptor, MiniMax-H3, and SenseVoice - bringing audio.cpp to 49 total model families and 70+ model variants, alongside the new native WebUI from @mirek190, expanded GGUF packaging, and more shared framework runtime pieces.
> 2026-07-31 - Release 0.5: audio.cpp reaches 44 model families with 9 new additions, early HIP/ROCm support for AMD GPUs, Nix ROCm/HIP build support, Metal optimizations with tested VoxCPM2 runs up to 2.56x faster on Apple Silicon, and a major GGUF-first WebUI/package-spec usability pass.
2026-06-25 to 2026-07-23 (release 0.1 to 0.4): audio.cpp grew from the first released model wave into broad TTS, ASR, music generation, source separation, VAD, diarization, codec, and voice-conversion coverage, with VibeVoice 1.5B/7B, LoRA adapter loading, initial streaming support, and major CUDA Conv1DTransp speedups.
Task tags: TTS text to speech, Clone voice cloning, VC voice conversion, S2S speech-to-speech, ASR speech recognition, Classify audio classification, Wake wake-word detection, Align forced alignment, VAD voice activity detection, Diar speaker diarization, Codec audio codec, Sep source separation, MIDI audio-to-symbolic MIDI/events, Music music/song generation, SFX sound effects, Video video generation, Edit audio/music editing, Design voice design, Dialogue multi-speaker dialogue TTS, Ctrl TTS/clone voice control such as emotion, style, instruction, caption, or non-verbal tag control.
Runtime tags summarize the supported loading paths. GGUF package precision varies by model and release; check the audio.cpp GGUF repo or docs/gguf.md for the exact package list. Bundled means the tiny runtime asset ships under assets/framework/models and needs no separate model download. Stream means the family exposes a streaming server/session path.
Model weights keep the license of their original release, which is separate from audio.cpp's own license. docs/model_licenses.md lists that license per family, and whether it allows commercial use.
| Family | Task | Lang | Variants | Runtime |
|---|---|---|---|---|
| breeze_tts | TTS, Clone, Design, Ctrl | zh, en | BreezeTTS 2 instruction-conditioned TTS and prompt-audio voice cloning | GGUF BF16/Q8/Q4_0, Stream |
| chatterbox | TTS, Clone, VC| ar, da, de, el, en, es, fi, fr, hi, it, ko, ms, nl, no, pl, pt, sv, sw, tr | Chatterbox with 0.5B backbone | GGUF 16/Q8 |
| confucius4_tts | Clone | zh, en, ja, ko, de, fr, es, id, it, th, pt, ru, ms, vi | Confucius4-TTS multilingual voice cloning | GGUF F32, Stream |
| cosyvoice3 | TTS, Clone | zh, en, ja, ko, de, es, fr, it, ru, yue | Fun-CosyVoice3 zero-shot, cross-lingual, and instruction-conditioned TTS | GGUF F32/Q8 |
| dots_tts | TTS, Clone, Edit, Ctrl | multilingual | DotTTS SOAR
DotTTS MeanFlow
DotTTS Edit | GGUF 16/Q8, Stream |
| dramabox | TTS, Clone | en | DramaBox expressive TTS and voice cloning | GGUF Q8 |
| fish_audio | TTS, Clone, Ctrl | auto, en, zh | Fish Audio S2 Pro | GGUF 16/Q8 |
| firered_audio | ASR, TTS, Clone, Design, Ctrl | zh, en | FireRedAudio multimodal speech/audio model with ASR, understanding, cloning, design, and edit paths | GGUF original/Q8 |
| fireredtts3 | TTS, Clone, Design, Ctrl | 24 langs + 21 zh dialects | FireRedTTS3 Base
FireRedTTS3 Instruct/Voicedesign | GGUF original/Q8 |
| higgs_audio_tts | TTS, Clone, Ctrl | auto | Higgs Audio v3 TTS 4B | GGUF 16/Q8 |
| index_tts2 | TTS, Clone, Ctrl | zh, en, ja, es, ar | IndexTTS-2
IndexTTS-2.5 | GGUF 16/Q8 |
| kokoro_tts | TTS | en-us, en-gb, es, fr, hi, it, ja, pt-br, zh | Kokoro 82M, 54 preset voices | Safetensors, local GGUF BF16/Q8 |
| kugelaudio | TTS, Stream | European multilingual | KugelAudio-0-Open, four preset voices | GGUF BF16 / Q8_0 / Q4_K |
| irodori_tts | TTS, Clone, Design, Ctrl | ja | Irodori-TTS-v4.1-Small
Irodori-TTS-v4.1-Anime
Irodori-TTS-500M-v3
Irodori-TTS-600M-v3-VoiceDesign | GGUF 16/Q8 |
| magpie_tts | TTS | ar-AE, ar-MSA, ar-SA, de, en, es, fr, hi, it, ko, pt-BR, vi, zh | NVIDIA MagpieTTS Multilingual 357M (v2607) with baked speaker prompts and NanoCodec decode | GGUF original/Q8 |
| maya1 | TTS, Design, Ctrl | en | Maya1 expressive TTS with natural-language voice design, inline emotion tags, and SNAC decoding | GGUF original/Q8 |
| miotts | TTS, Clone | en, ja | MioTTS-1.7B | GGUF 16/Q8 |
| moss_tts_local | TTS, Clone, Ctrl | auto, optional language hint | MOSS-TTS-Local-Transformer-v1.5 | GGUF 16/Q8 |
| moss_tts_nano | TTS, Clone | auto | MOSS-TTS-Nano-100M | GGUF 16/Q8 |
| neutts | TTS, Ctrl | en | NeuTTS 2E with built-in speaker prompts and emotion control | GGUF original precision, Stream |
| omnivoice | TTS, Clone, Design, Ctrl | 646+ langs | OmniVoice, Qwen3-0.6B based
VoiceTut-TTS (Egyptian Arabic fine-tune) | GGUF 16/Q8, Stream |
| personaplex | Dialogue, S2S | en | PersonaPlex 7B v1 speech-to-speech conversational model with packaged voice/persona prompts | GGUF Q4/Q8, Stream |
| pocket_tts | TTS, Clone | en, de, it, pt, es | PocketTTS-100M English/German/Italian/Portuguese/Spanish | GGUF 16/Q8, Stream |
| qwen3_tts | TTS, Clone, Design, Ctrl | zh, en, fr, de, it, ja, ko, pt, ru, es | Qwen3-TTS-12Hz-0.6B-Base
Qwen3-TTS-12Hz-1.7B-Base
Qwen3-TTS-12Hz-1.7B-CustomVoice
Qwen3-TTS-12Hz-1.7B-VoiceDesign | GGUF 16/Q8 |
| supertonic | TTS | en, ko, ja, ar, bg, cs, da, de, el, es, et, fi, fr, hi, hr, hu, id, it, lt, lv, nl, pl, pt, ro, ru, sk, sl, sv, tr, uk, vi, na | Supertonic 3 | GGUF F32, Stream |
| vibevoice | TTS, Dialogue | en, zh | VibeVoice-1.5B
VibeVoice-7B | GGUF 16/Q8 |
| voxcpm2 | TTS, Clone, Design, Ctrl | ar, da, de, el, en, es, fi, fr, he, hi, id, it, ja, km, ko, lo, ms, my, nl, no, pl, pt, ru, sv, sw, th, tl, tr, vi, zh | VoxCPM2-2B, 48 kHz | GGUF 16/Q8, Stream |
| Family | Task | Lang | Variants | Runtime |
|---|---|---|---|---|
| ast_audioset | Classify | language agnostic | MIT AST AudioSet, 527 classes | GGUF F32 |
| ced | Classify | language agnostic | CED Tiny, 527 AudioSet classes | GGUF F32 |
| ced | Classify | language agnostic | CED Mini, 527 AudioSet classes | GGUF F32 |
| ced | Classify | language agnostic | CED Small, 527 AudioSet classes | GGUF F32 |
| ced | Classify | language agnostic | CED Base, 527 AudioSet classes | GGUF F32 |
| audio_flamingo | ASR, Audio understanding | en | Audio Flamingo 3
Audio Flamingo Next | GGUF BF16 |
| canary_asr | ASR, Translate | en, de, es, fr | Canary 180M Flash | GGUF F32/Q8 |
| citrinet_asr | ASR | en | Citrinet-256 | GGUF Q8 |
| cohere_asr | ASR | en, fr, de, es, it, pt, nl, pl, el, ar, ja, zh, vi, ko | Cohere Transcribe 03-2026 | GGUF BF16/Q8/Q4_0 |
| crisperwhisper | ASR, Align | 99 language codes | CrisperWhisper 2.0 Large | GGUF BF16/Q8, Stream |
| gigaam_asr | ASR | ru, kk, ky, uz, en | GigaAM v3 CTC
GigaAM v3 RNN-T
GigaAM v3 E2E CTC
GigaAM v3 E2E RNN-T
GigaAM Multilingual CTC
GigaAM Multilingual Large CTC | GGUF F16/F32 |
| fun_asr_nano | ASR | auto, zh, en, ja | Fun-ASR-Nano-2512 | GGUF 16/Q8 |
| higgs_audio_stt | ASR | en | Higgs Audio v3 STT | GGUF 16/Q8, Stream |
| hviske_asr | ASR | da | Hviske v5.3 | GGUF Q8 |
| hviske_asr_v6 | ASR | da | Hviske v6 | GGUF BF16 / Q8 |
| index_echo | ASR, Translate | zh → en, es, ja | Index-Echo-S2TT 2B
Index-Echo-S2TT 9B | GGUF original/Q8_0/Q4_K |
| marblenet_vad | VAD | lang agnostic | MarbleNet VAD | Bundled |
| micro_wake_word | Wake | model dependent | microWakeWord MixedNet TFLite models converted to GGUF | GGUF F32, Stream |
| firered_vad | VAD | lang agnostic | FireRed VAD / Stream-VAD | GGUF F32/F16/Q8, Stream |
| pulsevad | VAD | lang agnostic | PulseVAD 2.1K Student / 81K Teacher | GGUF F32 |
| moonshine_asr | ASR | en | Moonshine Streaming Tiny/Small/Medium | GGUF Q8, Stream |
| moss_transcribe_diarize | ASR | auto, 50+ languages | MOSS-Transcribe-Diarize with speaker labels and timestamps | GGUF BF16/Q8/Q4_K, Stream |
| nemotron_3_diar | Diar | multilingual | NVIDIA Nemotron 3 Diarization with eight-speaker arrival-order diarization | GGUF BF16, Batch, Stream |
| nemotron_asr | ASR | 100+ ASR prompt codes incl. auto | Nemotron 3.5 ASR Streaming 0.6B | GGUF 16/Q8, Stream |
| niagara_asr | ASR | en | Niagara 19M Batch English
Niagara 38M Batch English | GGUF F32 |
| owsm | ASR, Translate | 151 language codes | OWSM v4 Base 102M
OWSM v4 Small 370M
OWSM v4 Medium 1B | GGUF F32 / Q8_0 / Q4_K (Small, Medium) |
| owsm_ctc | ASR, Translate | 151 language codes | OWSM-CTC v4 1B | GGUF F32 / Q8_0 |
| qwen3_asr | ASR | zh, en, yue, ar, de, fr, es, pt, id, it, ko, ru, th, vi, ja, tr, hi, ms, nl, sv, da, fi, pl, cs, fil, fa, el, ro, hu, mk | Qwen3-ASR-0.6B
Qwen3-ASR-1.7B-hf
QwenCleo-ASR (Egyptian Arabic fine-tune) | GGUF 16/Q8, Stream |
| qwen3_forced_aligner | Align | zh, yue, en, de, es, fr, it, pt, ru, ko, ja | Qwen3-ForcedAligner-0.6B | GGUF 16/Q8 |
| samsone | Audio understanding | en | SAMSONE 99M
SAMSONE 134M
SAMSONE 356M | GGUF BF16/Q8 |
| silero_vad | VAD | lang agnostic | Silero VAD | Bundled, Stream |
| sherpa_kws | Wake | model dependent | sherpa-onnx streaming Zipformer keyword spotting | GGUF F32, Stream |
| smart_turn | Turn detection | auto | Smart Turn v3.2 | GGUF F32 |
| sortformer_diar | Diar | en | Sortformer-4spk-v1 | - |
| vibevoice_asr | ASR | auto | VibeVoice ASR | GGUF 16/Q8 |
| vibevoice_asr_streaming | ASR | en, zh, es, pt, de, ja, ko, fr, ru, it | VibeVoice ASR Streaming 7B/1.5B with persistent decoder state and speaker turns | GGUF BF16/Q8/Q4, Stream |
| voxtral_realtime | ASR | auto | Voxtral-Mini-4B-Realtime-2602 | GGUF 16/Q8/Q4, Stream |
| Family | Task | Lang | Variants | Runtime |
|---|---|---|---|---|
| apollo | S2S | lang agnostic | Apollo music restoration | GGUF F32 |
| audiosr | S2S | lang agnostic | AudioSR Basic audio super-resolution package | GGUF F32 |
| bs_roformer | Sep | lang agnostic | BS-RoFormer vocal separation checkpoints | GGUF Q8 |
| builtin_audio_utils | S2S | lang agnostic | RNNoise
DeepFilterNet2
ZipEnhancer
GTCRN Streaming
GTCRN DNS3
GTCRN VCTK
FlashSR | Safetensors |
| controlfoley | SFX | auto | ControlFoley 44 kHz multimodal Foley generation from text, video, and reference audio conditioning | GGUF F32/Q8 |
| htdemucs | Sep | lang agnostic | HTDemucs
HTDemucs_ft
HTDemucs_6stems | GGUF 16/Q8 |
| meanvc2 | VC | lang agnostic | MeanVC2 120 ms/40 ms zero-shot voice conversion | GGUF F32/Q4, Stream |
| mel_band_roformer | Sep | lang agnostic | Mel-Band RoFormer MLX vocal separation variants | GGUF 16/Q8 |
| miocodec | Codec, VC | lang agnostic | MioCodec v2, 25 Hz, 44.1 kHz | GGUF 16/Q8 |
| mossformer2 | Sep | lang agnostic | MossFormer2 SS 16K two-speaker separation | GGUF F32 |
| muscriptor | MIDI | music | MuScriptor Small audio-to-symbolic transcription | GGUF F32, Stream |
| rvc | VC | lang agnostic | RVC F16 GGUF with packaged v1/v2 voices and optional retrieval blending | GGUF 16 |
| sam_audio | S2S | lang agnostic | SAM Audio Small
SAM Audio Base
SAM Audio Large | GGUF F32/BF16/Q8 |
| seed_vc | VC | lang agnostic | SeedVC XLS-R + HiFT
SeedVC Whisper-small + BigVGAN | GGUF 16/Q8 |
| sheetsage2 | MIDI | music | SheetSage2 audio-to-ABC score transcription | GGUF orig |
| sidon | S2S | lang agnostic | Sidon v0.1 single-speaker speech restoration | GGUF F32 |
| tf_gridnet | Sep | lang agnostic | TF-GridNet WSJ0-2mix two-speaker separation | GGUF F32 |
| tone_color_vc | VC | lang agnostic | Tone Color VC | GGUF F32/F16 |
| universr | S2S | lang agnostic | UniverSR Audio and Speech super-resolution | GGUF F32 |
| Family | Task | Lang | Variants | Runtime |
|---|---|---|---|---|
| ace_step | Music, Edit | 50+ langs | ACE-Step 1.5 Turbo
ACE-Step 1.5 Base
ACE-Step 1.5 XL Turbo
ACE-Step 1.5 XL SFT | GGUF 16 |
| heartmula | Music | zh, en, ja, ko, es | HeartMuLa-oss-3B with HeartCodec-oss | GGUF 16/Q8 |
| midashenglm_gen | Music, SFX | auto | MiDashengLM-Gen structured-prompt generation for speech, music, sound effects, and ambience | GGUF F32/Q8 |
| minimax_h3 | Video, Music, TTS/Dialogue | auto | MiniMax-H3 Q4_K with optional INT8 ConvRot DiT | GGUF Q4/INT8 |
| minimax_music3 | Music | auto | MiniMax Music 3 text-to-music generation with lyrics conditioning | GGUF Q4/Q8 |
| stable_audio | Music, SFX, Edit | en | Stable Audio 3 Small Music
Stable Audio 3 Small SFX
Stable Audio 3 Medium | GGUF 16/Q8 |
| vevo2 | TTS, Music, VC, Edit | en, zh | Vevo2 with Qwen2.5-0.5B AR model | GGUF 16 |
| yue2 | Music | en | YuE2-3B lyrics-conditioned song generation with optional ABC score planning and conditioning | GGUF BF16/Q8/Q4 |
Some model families in the supported table started as outside contributions before being promoted into the core release surface. Thanks to Mirek @mirek190 for BS-RoFormer, @justinjohn0306 for MOSS-TTS-Local, and @LauraGPT from the official FunASR team for Fun-ASR-Nano.
Community model ports live under community_models to make the ownership boundary clear while keeping them available through the normal audio.cpp CLI and server paths. Some community-contributed models graduate into the core model tree when they become part of the main release surface. Huge thanks to the contributors who bring these models in, test them, and keep pushing the framework into new territory. See docs/community_models/models.md for community-model expectations and current entries.
| Family | Task | Lang | Runtime | Contributor | What They Added | |---|---|---|---|---|---| | audio8_asr | ASR | en, zh, yue, ja, ko, fr, de | GGUF Q8, Safetensors | @gqf2008 | Audio8-ASR-0.1B compact multilingual autoregressive ASR reusing the Qwen3-ASR encoder with an MLP-tower adapter and an 8-layer Qwen2-style decoder (CC-BY-NC, local conversion only) | | audio8_tts | TTS, Clone | auto, yue, zh, nl, en, fr, de, it, ja, ko, pl, es | GGUF Q8, Stream | @jasonchen31 | Audio8 TTS Preview 0.6B DualAR multilingual TTS and zero-shot voice cloning with a Qwen backbone and neural codec | | auk | TTS, audio editing | auto | GGUF F32/F16/Q8 | [@0xShug0](https:/
→ →
 →
 →
 →
 →
 →
 →