1
 →
Open-source LLM knowledge platform: turn raw documents into a queryable RAG, an autonomous reasoning agent, and a self-maintaining Wiki.



| English | 简体中文 | 日本語 | 한국어 |
Overview • Architecture • Key Features • Getting Started • API Reference • Developer Guide
WeKnora is an open-source, LLM-powered knowledge framework built for enterprise-grade document understanding, semantic retrieval, and autonomous reasoning.
https://github.com/user-attachments/assets/19b28ce2-a62f-4f54-b289-c983576259bc
2:25 · 1080p · English narration & captions.
It is organized around three core capabilities: RAG-based Quick Q&A for everyday lookups, a ReAct Agent that autonomously orchestrates retrieval, MCP tools, a tenant skill catalog, session-persistent Docker / E2B / Cube sandboxes and web search to handle complex multi-step tasks, and a brand-new Wiki Mode in which agents distill raw documents into a self-maintaining, interlinked markdown knowledge base with an interactive knowledge graph, complete with manual editing, revision history and one-click rollback. Cross-session long-term memory remembers who you are and what you keep asking about. Knowledge curation is equally hands-on: a tree-structured folder view preserves the directory layout of uploads, and chunk editing with revision history lets retrieval chunks be edited, diffed and reverted like documents. Combined with multi-source ingestion (Feishu wiki / Feishu Drive / GitLab / Tencent IMA / Notion / Yuque / DingTalk Docs / RSS, and growing), website embed widgets for publishing agents to external sites, scoped API keys with a principal model for programmatic integrations, multi-instance storage backends per workspace for flexible data placement, 20+ LLM provider integrations (including LiteLLM), full Langfuse observability plus a runtime task-queue dashboard with worker-pool governance, enterprise-ready multi-workspace RBAC (4-tier role matrix + per-resource ownership + per-workspace audit log), and a fully self-hostable modular architecture, WeKnora turns scattered documents into a queryable, reasoning-capable, continuously evolving knowledge asset.
The framework supports auto-syncing knowledge from Feishu, GitLab, Tencent IMA, Notion, and Yuque (more data sources coming soon), handles 10+ document formats including PDF, Word, images, Excel and XMind, and can serve Q&A directly through IM channels like WeCom, Feishu, Slack, and Telegram. It is compatible with major LLM providers including OpenAI, DeepSeek, Qwen (Alibaba Cloud), Zhipu, Hunyuan, Gemini, MiniMax, NVIDIA, LiteLLM, and Ollama. Office files can be parsed in-process with anydoc. Its fully modular design allows swapping LLMs, vector databases, and storage backends, with support for local and private cloud deployment ensuring complete data sovereignty. WeKnora also integrates with Langfuse for comprehensive observability into agent reasoning, token usage, and pipeline tracing.
search_memory); in-process anydoc office parser; official DeepSeek Harness plugin @wxg-prc-cpg/dsh-weknora; GitLab and Tencent IMA data sources; LiteLLM; Exa and Metaso web search; XMind parsing; chat artifacts, question outline and timestamps; context compaction and provider prompt-cache markers. Plus OIDC JWKS verification, optional complex passwords, document auto-tagging, and broad sandbox/security hardening. See CHANGELOG.md.resource_urls=public / RESOURCE_URL_MODE (third-party apps render images and files without a second authenticated proxy call); Feishu Drive data source and docx sync through the blocks API; batch document tagging; MCP Server 1.1.x (migrated to the mcp 2.x high-level API, official PyPI package tencent-weknora-mcp, new create_knowledge_from_text and list_shared_knowledge_bases for 29 tools total); AWS S3 default credential chain (IAM Role / IRSA); local HTML upload parsing; QQBot markdown replies; new PR CI checks for app / frontend / docreader / mcp-server. Plus large-scale router and modelcontext refactors, rerank and chunking quality work, and broad stability fixes. See CHANGELOG.md.CHANGELOG.md.@Skill / @MCP mentions with scoped agent runtime; mid-conversation MCP OAuth; QQBot & Lark (Feishu International) IM integration; Redis TLS; Requesty model provider + Keenable web search; tenantless provisioning & gated self-service workspaces; admin password reset; knowledge base duplicate flow; weknora CLI v0.10. Plus broad security hardening (SSRF, secret redaction, SQL validation, IDOR). See CHANGELOG.md.CHANGELOG.md.process_config; weknora CLI v0.9 (bundled Agent Skills, session stop, auth/profile harmonization); KB marquee multi-select; HNSW index for 1024-dim pgvector embeddings; chat resources store refactor; Langfuse-only tracing (Jaeger removed). See CHANGELOG.md.weknora CLI v0.7 / v0.8 (agent-first wire contract, NDJSON, --dry-run); OpenDataLoader + PaddleOCR-VL parsers; MCP server multi-transport (stdio / SSE / HTTP); per-model thinking-mode config; Tencent LKEAP rerank + native Gemini embeddings + MiniMax-M3. See CHANGELOG.md.Owner / Admin / Contributor / Viewer + per-KB ownership + per-workspace audit log), workspace member management & multi-workspace UX, self-service workspaces; weknora CLI v0.4 GA with mcp serve; KB retrieval fan-out across vector stores; AES-256-GCM credential encryption + docreader gRPC TLS + Token; Zhipu embedder + Huawei OBS; server-side user preferences; Go 1.26.0. See docs/RBAC说明.md and CHANGELOG.md.weknora CLI preview.final_answer tool.🛠️ Skill Sandbox Chat · generate and preview a Word file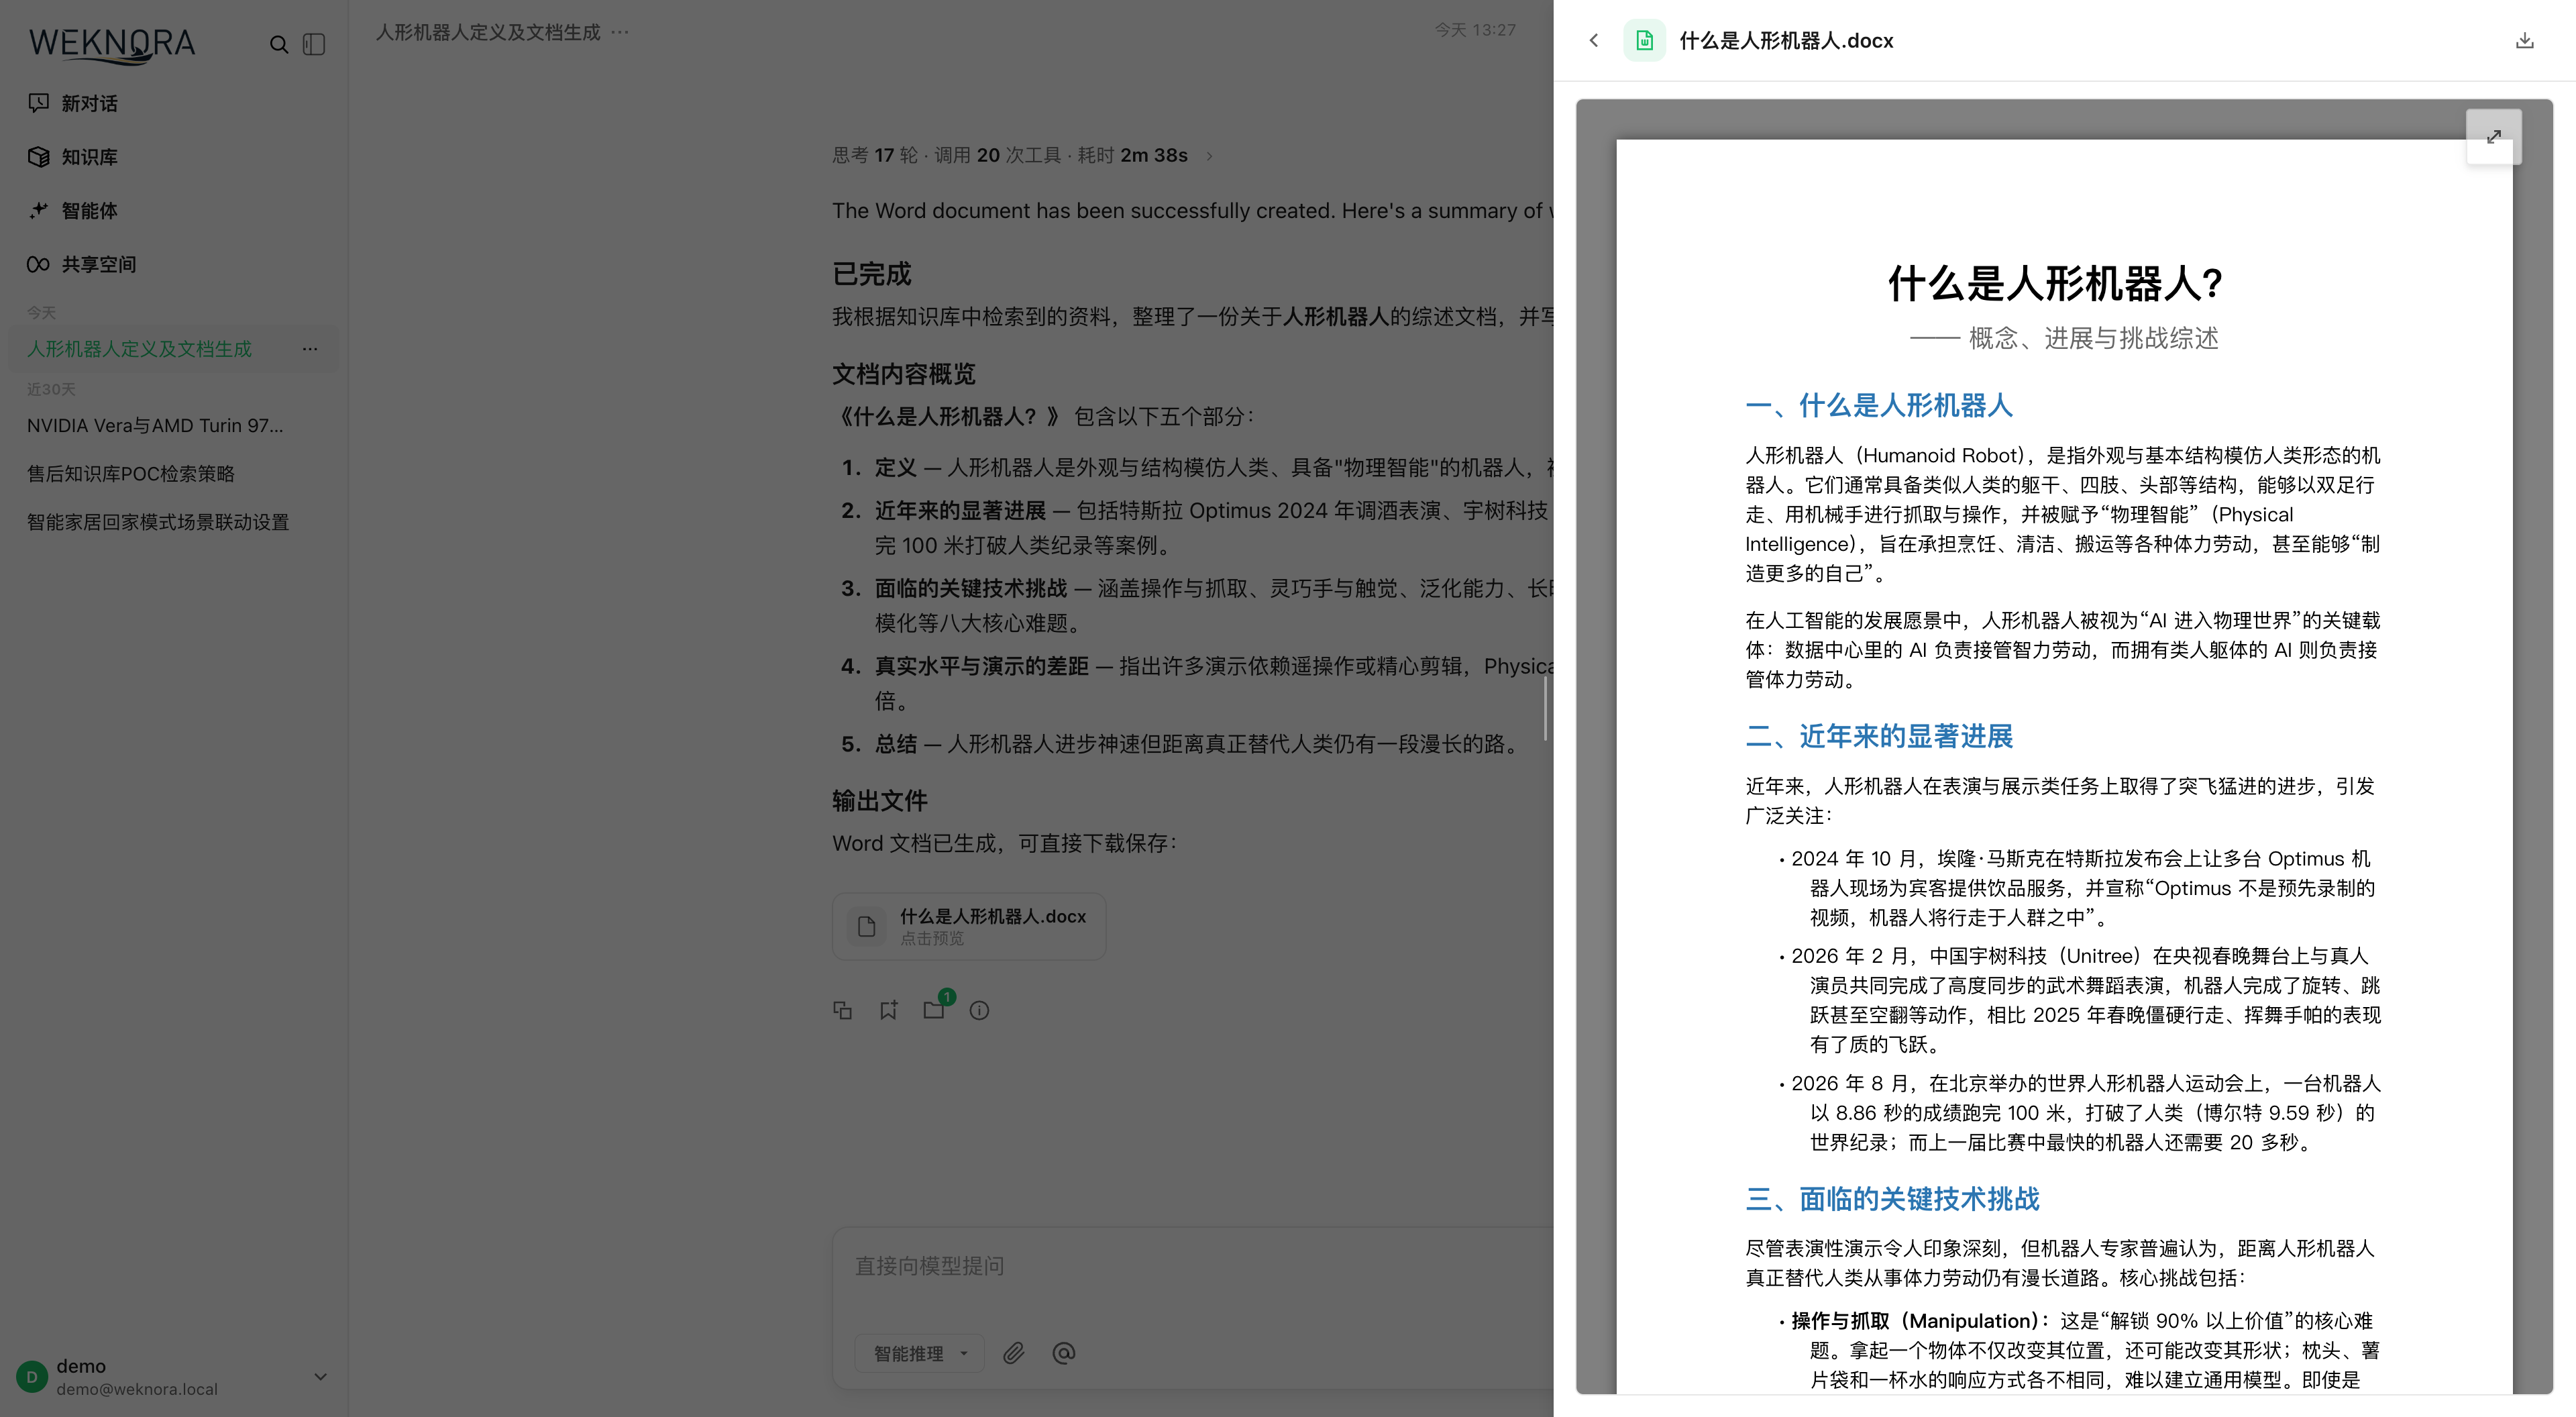 |
|
📦 Skill Catalog · install onto an E2B sandbox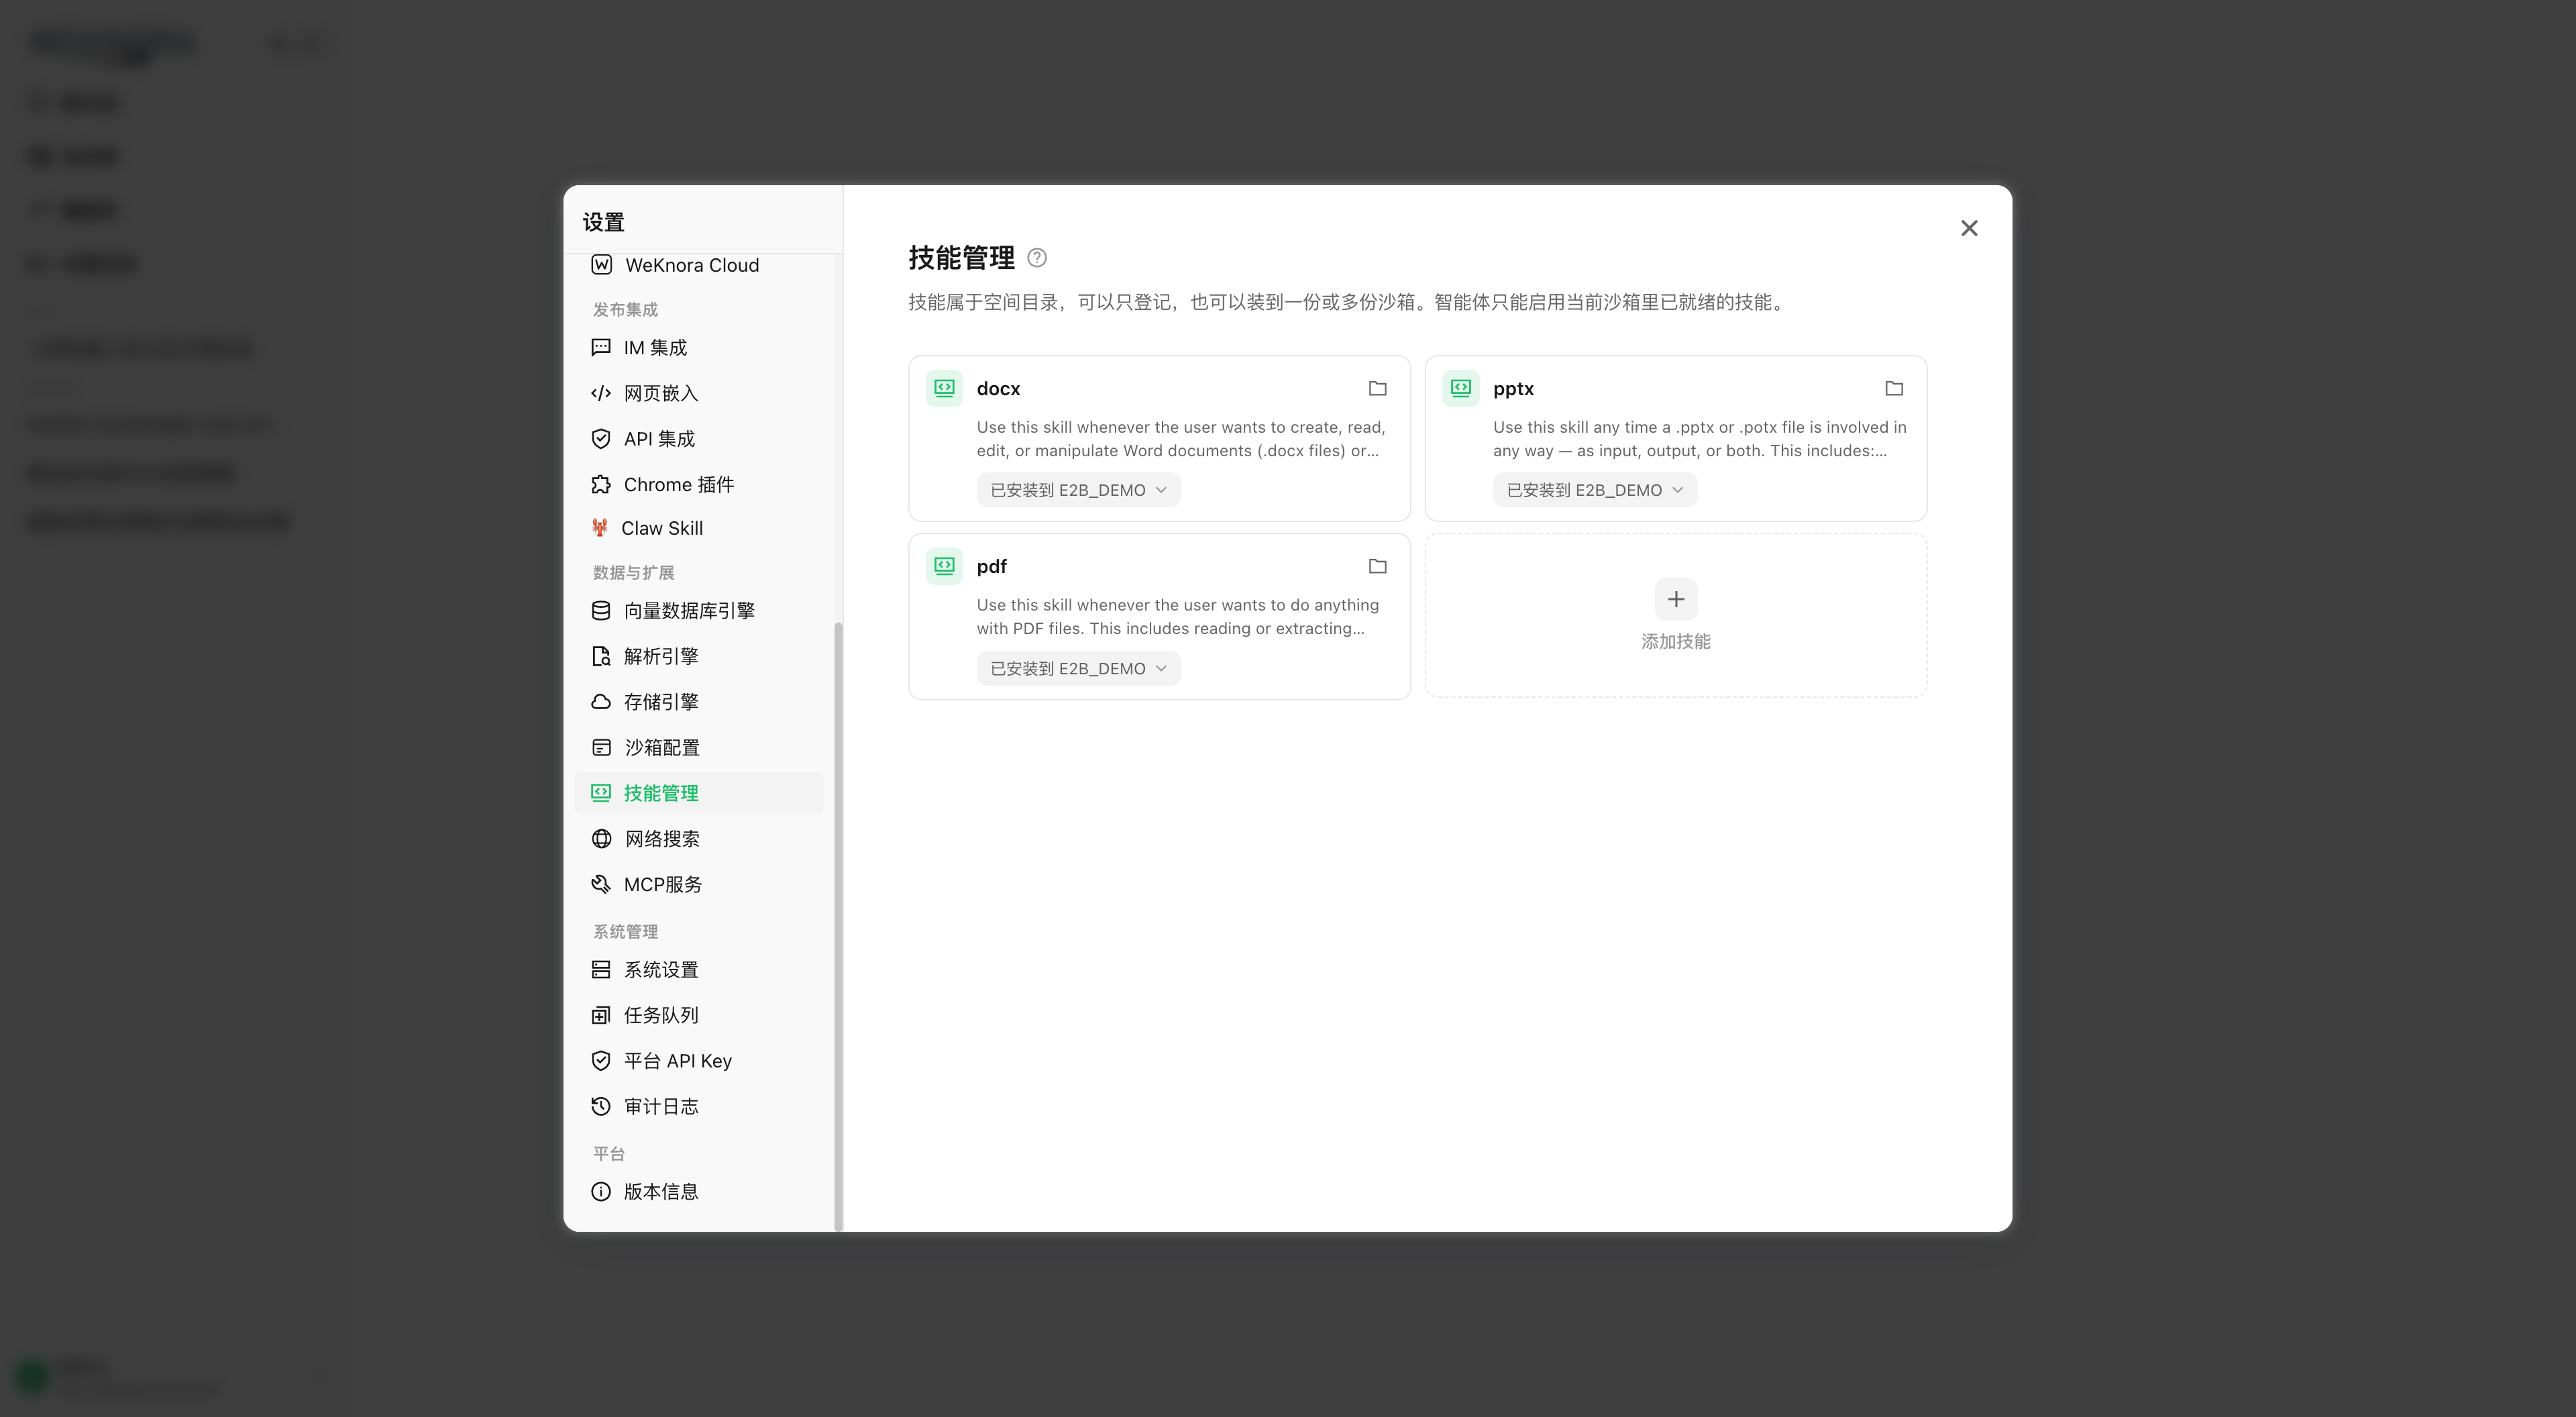 |
🤖 Agent Mode · search, read a skill, write sandbox files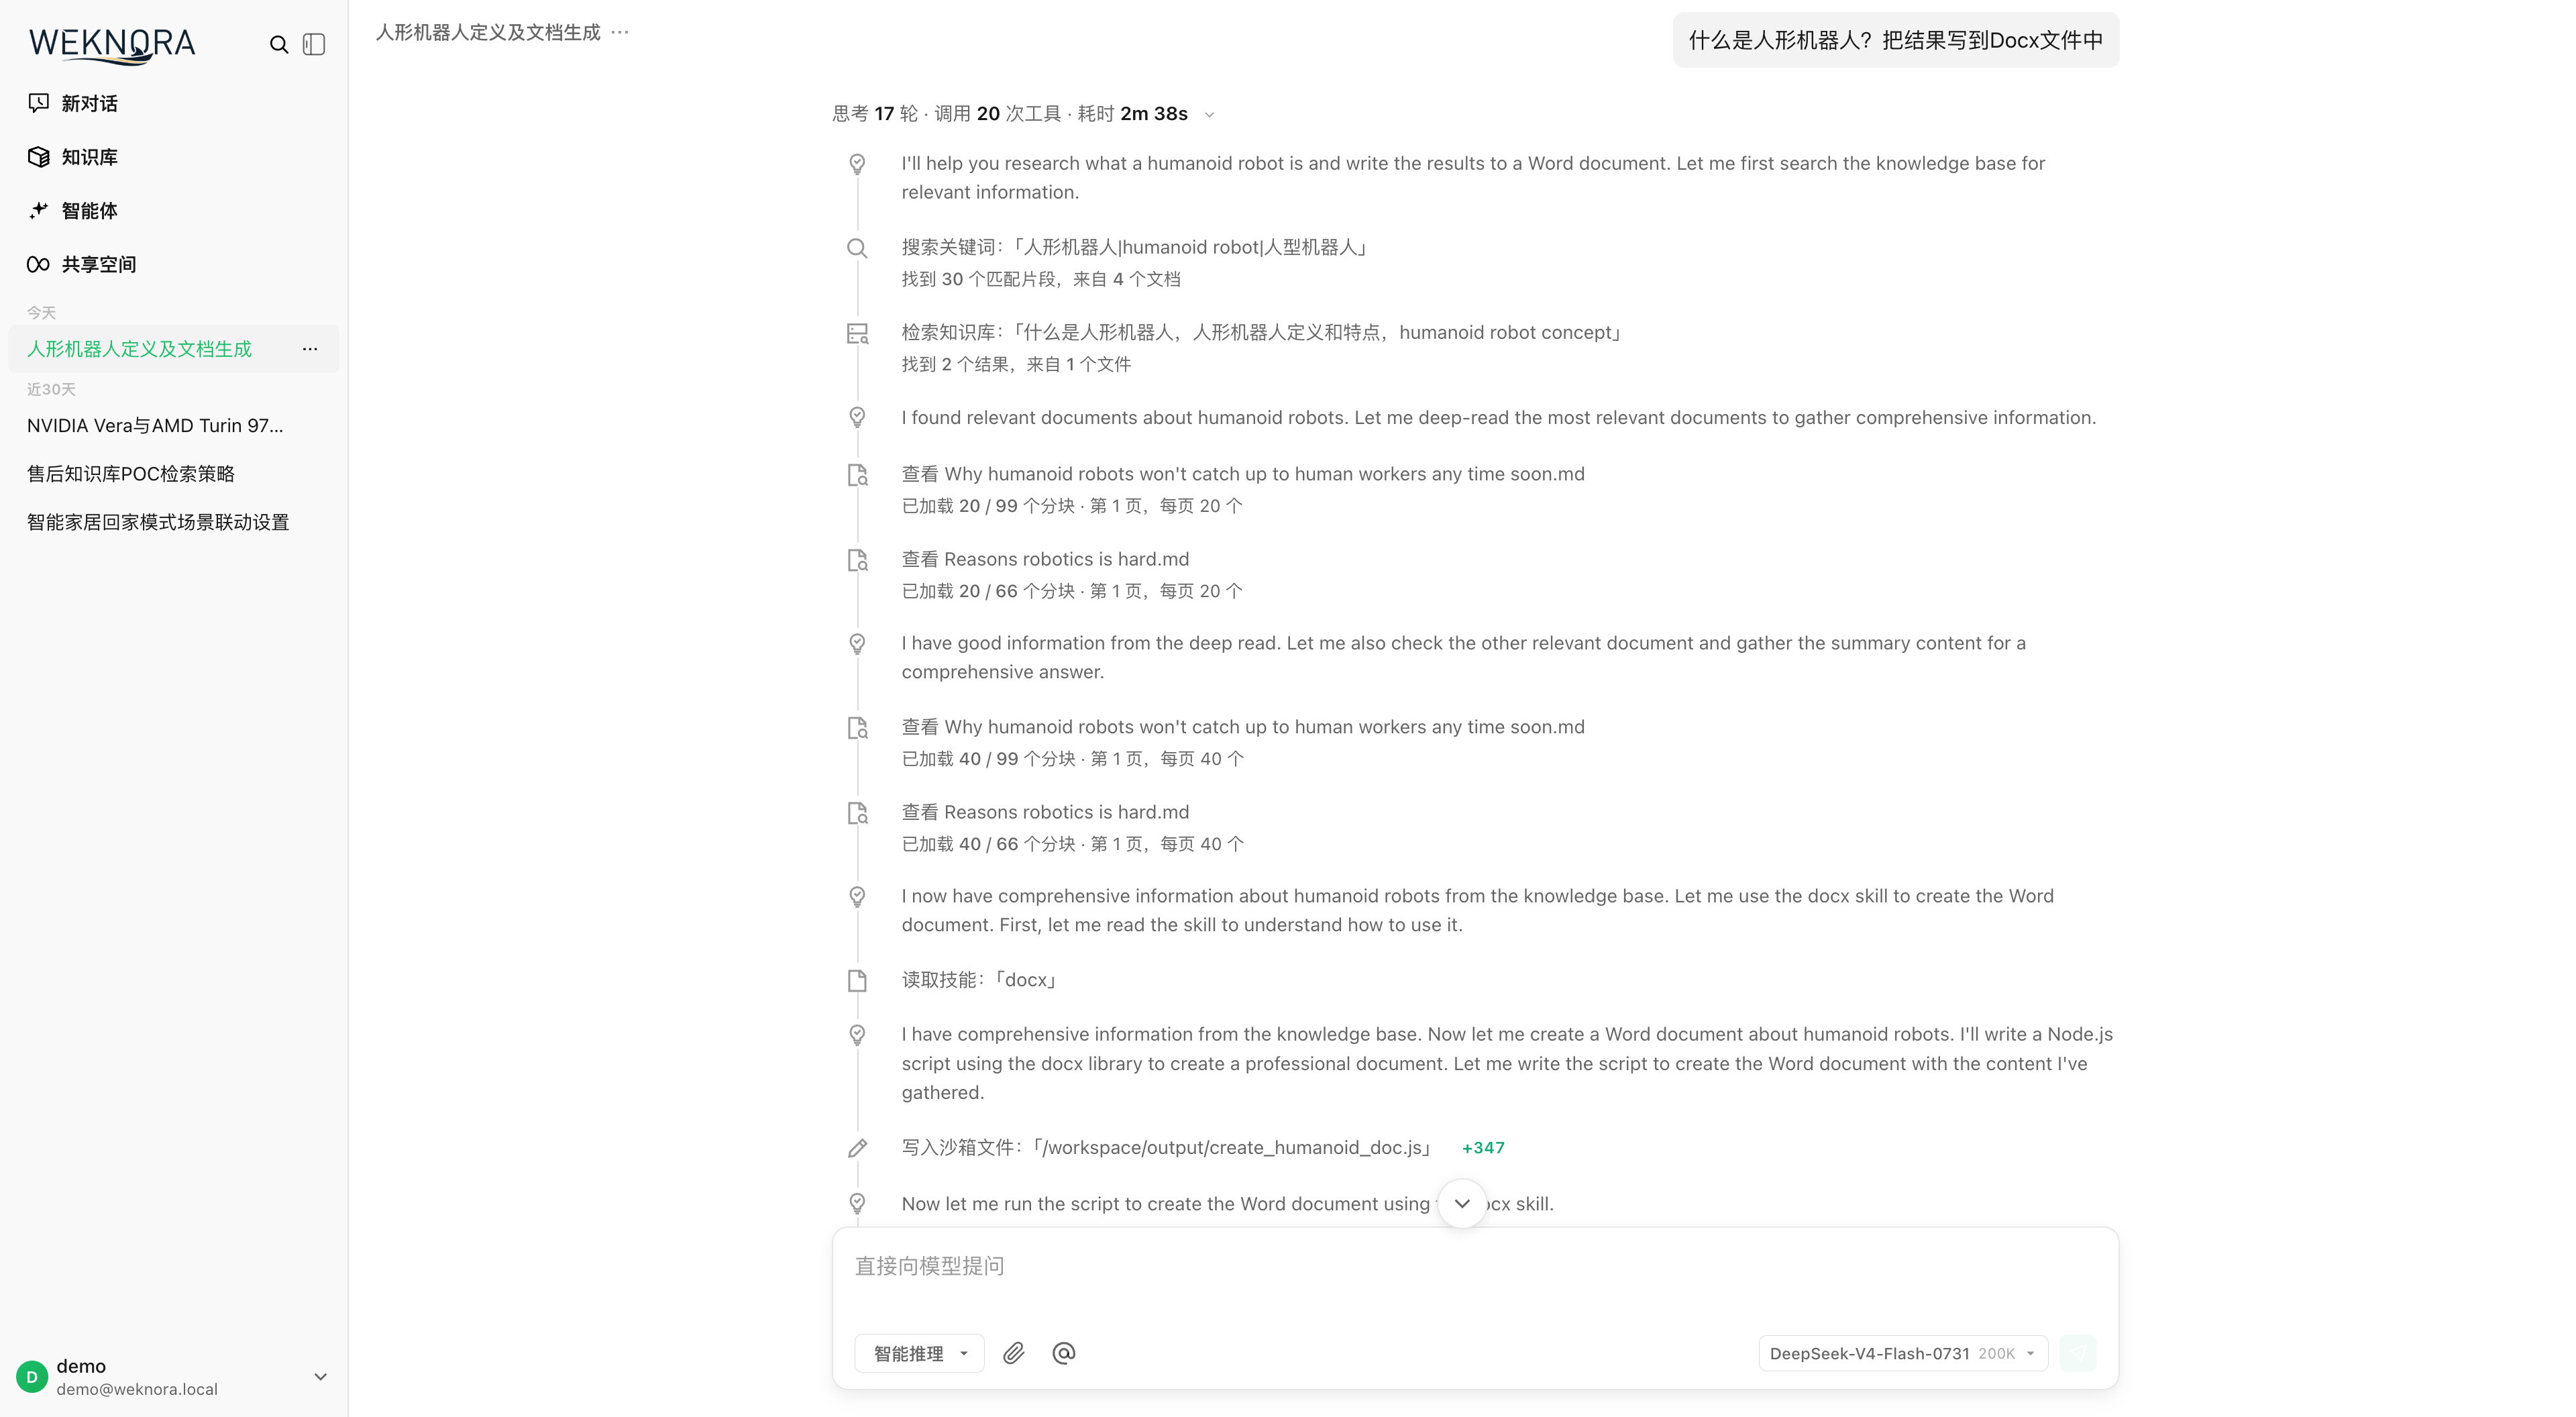 |
💬 Intelligent Q&A Conversation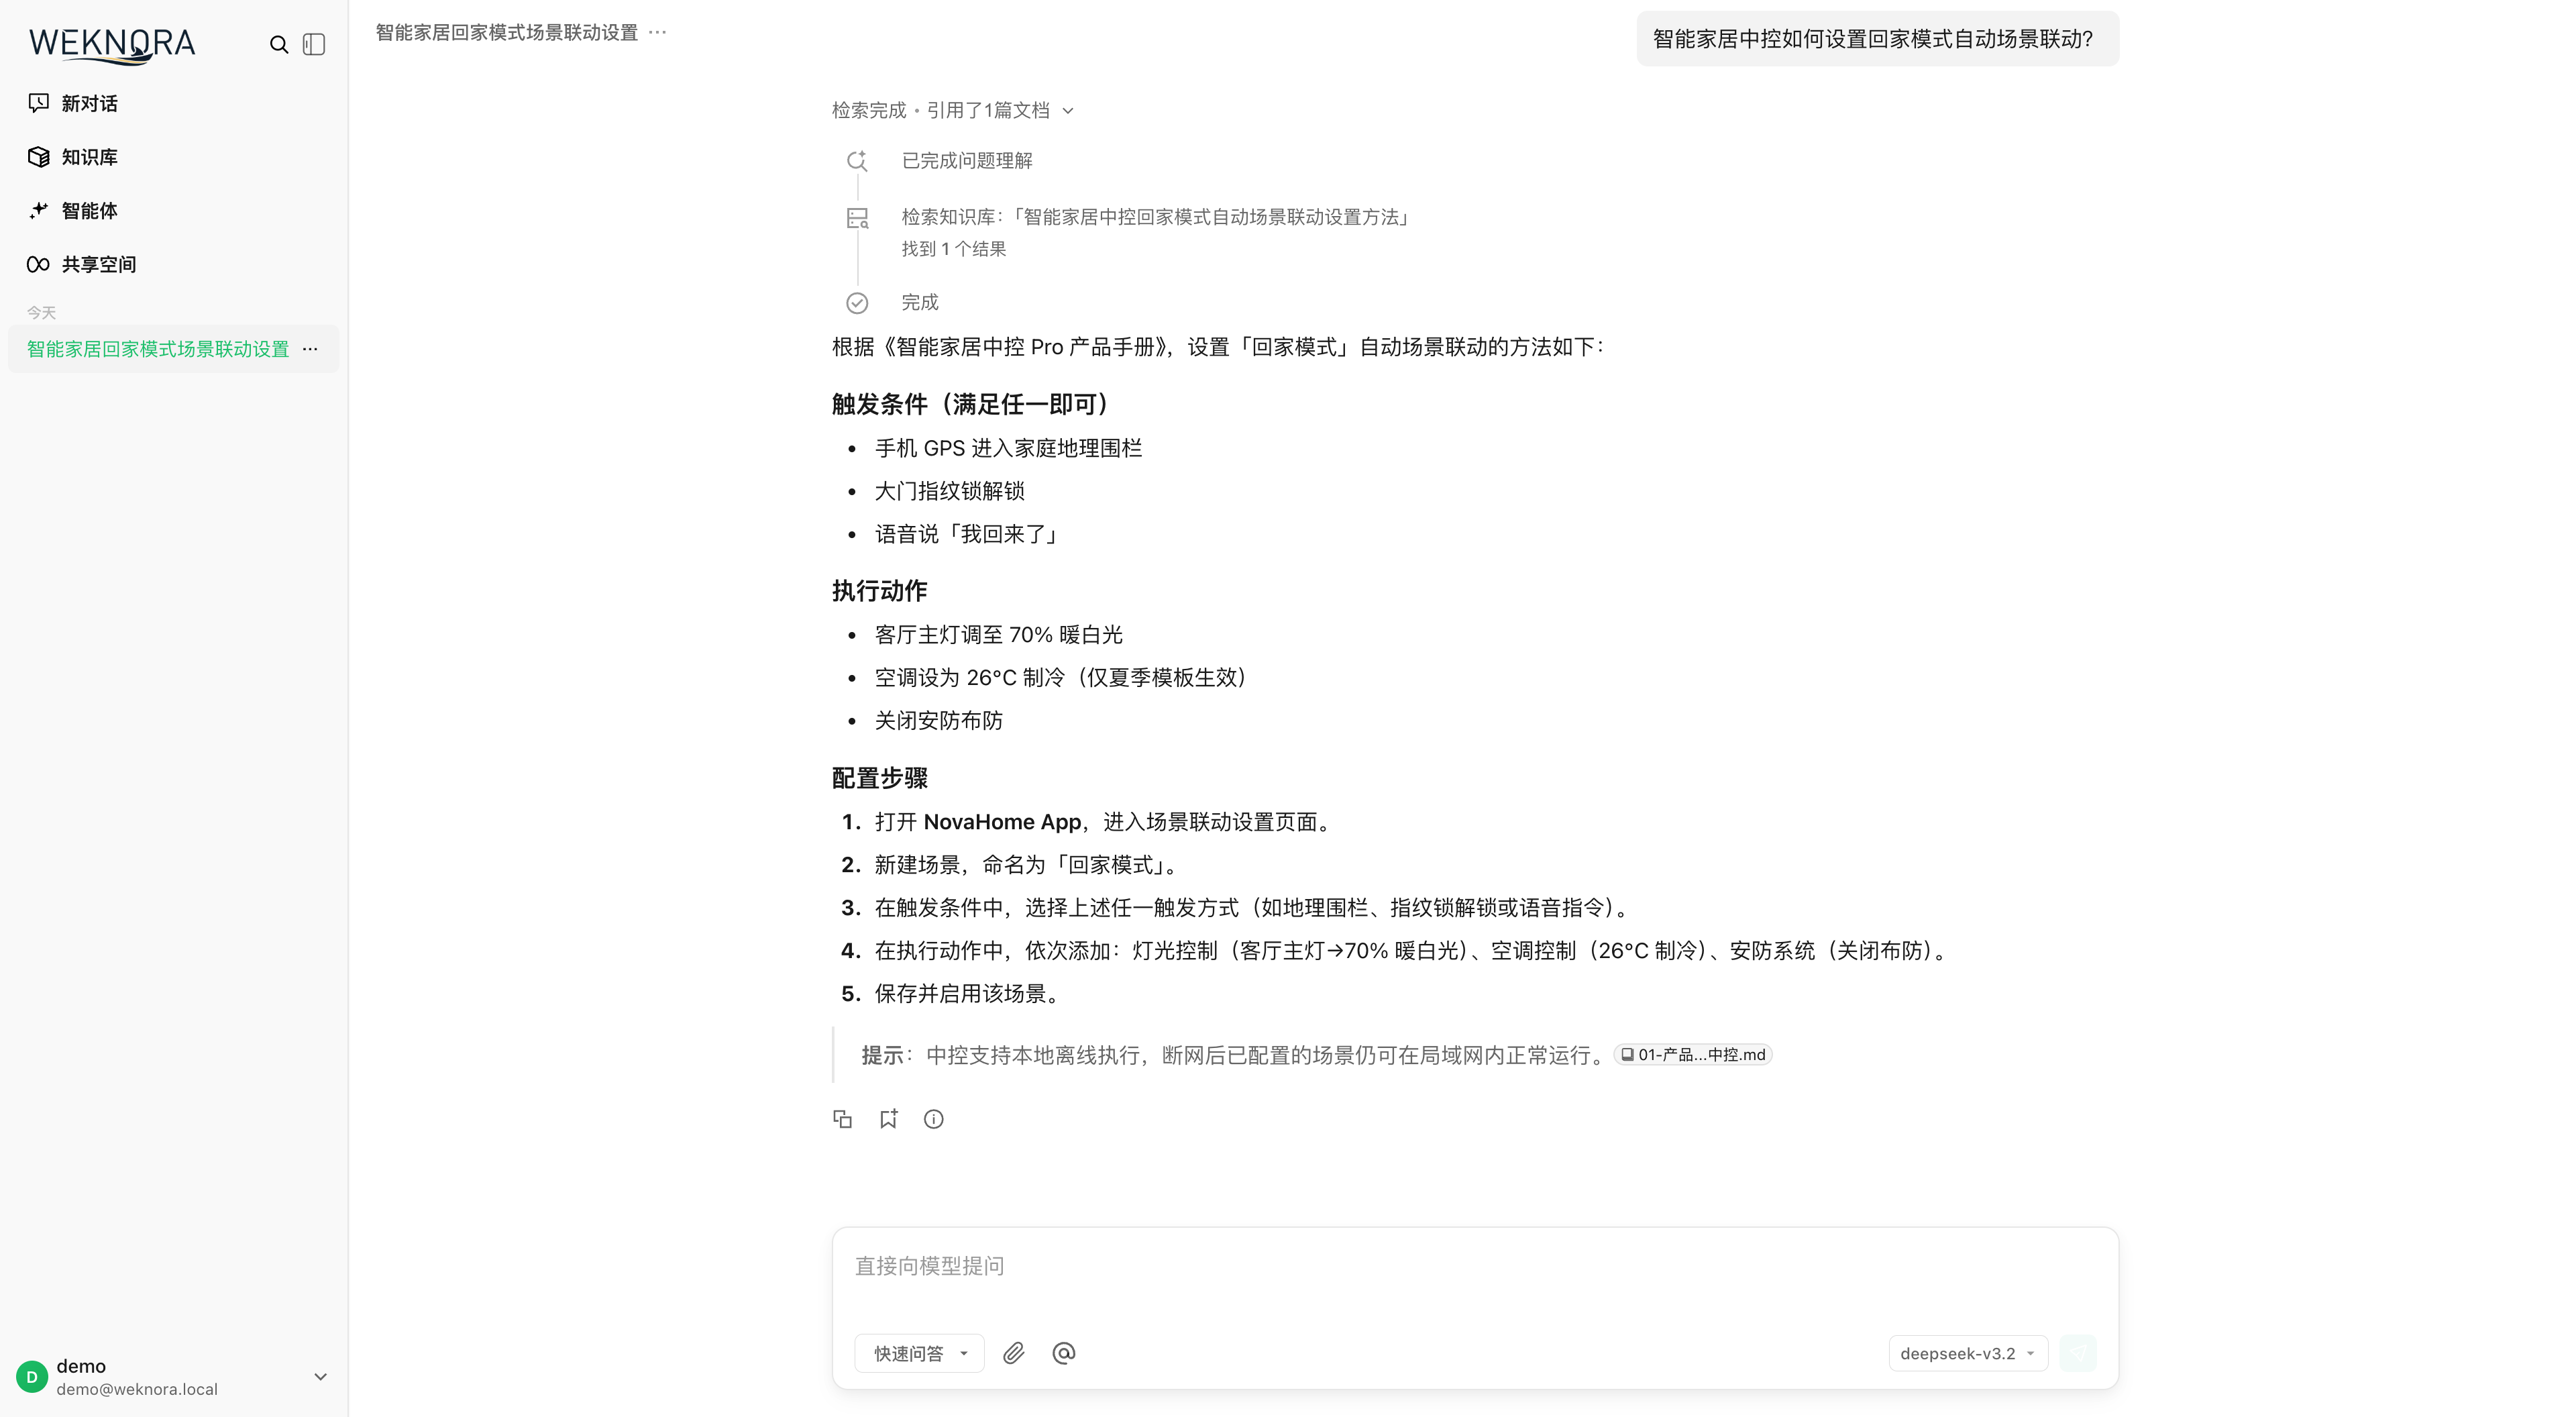 |
|
📖 Wiki Browser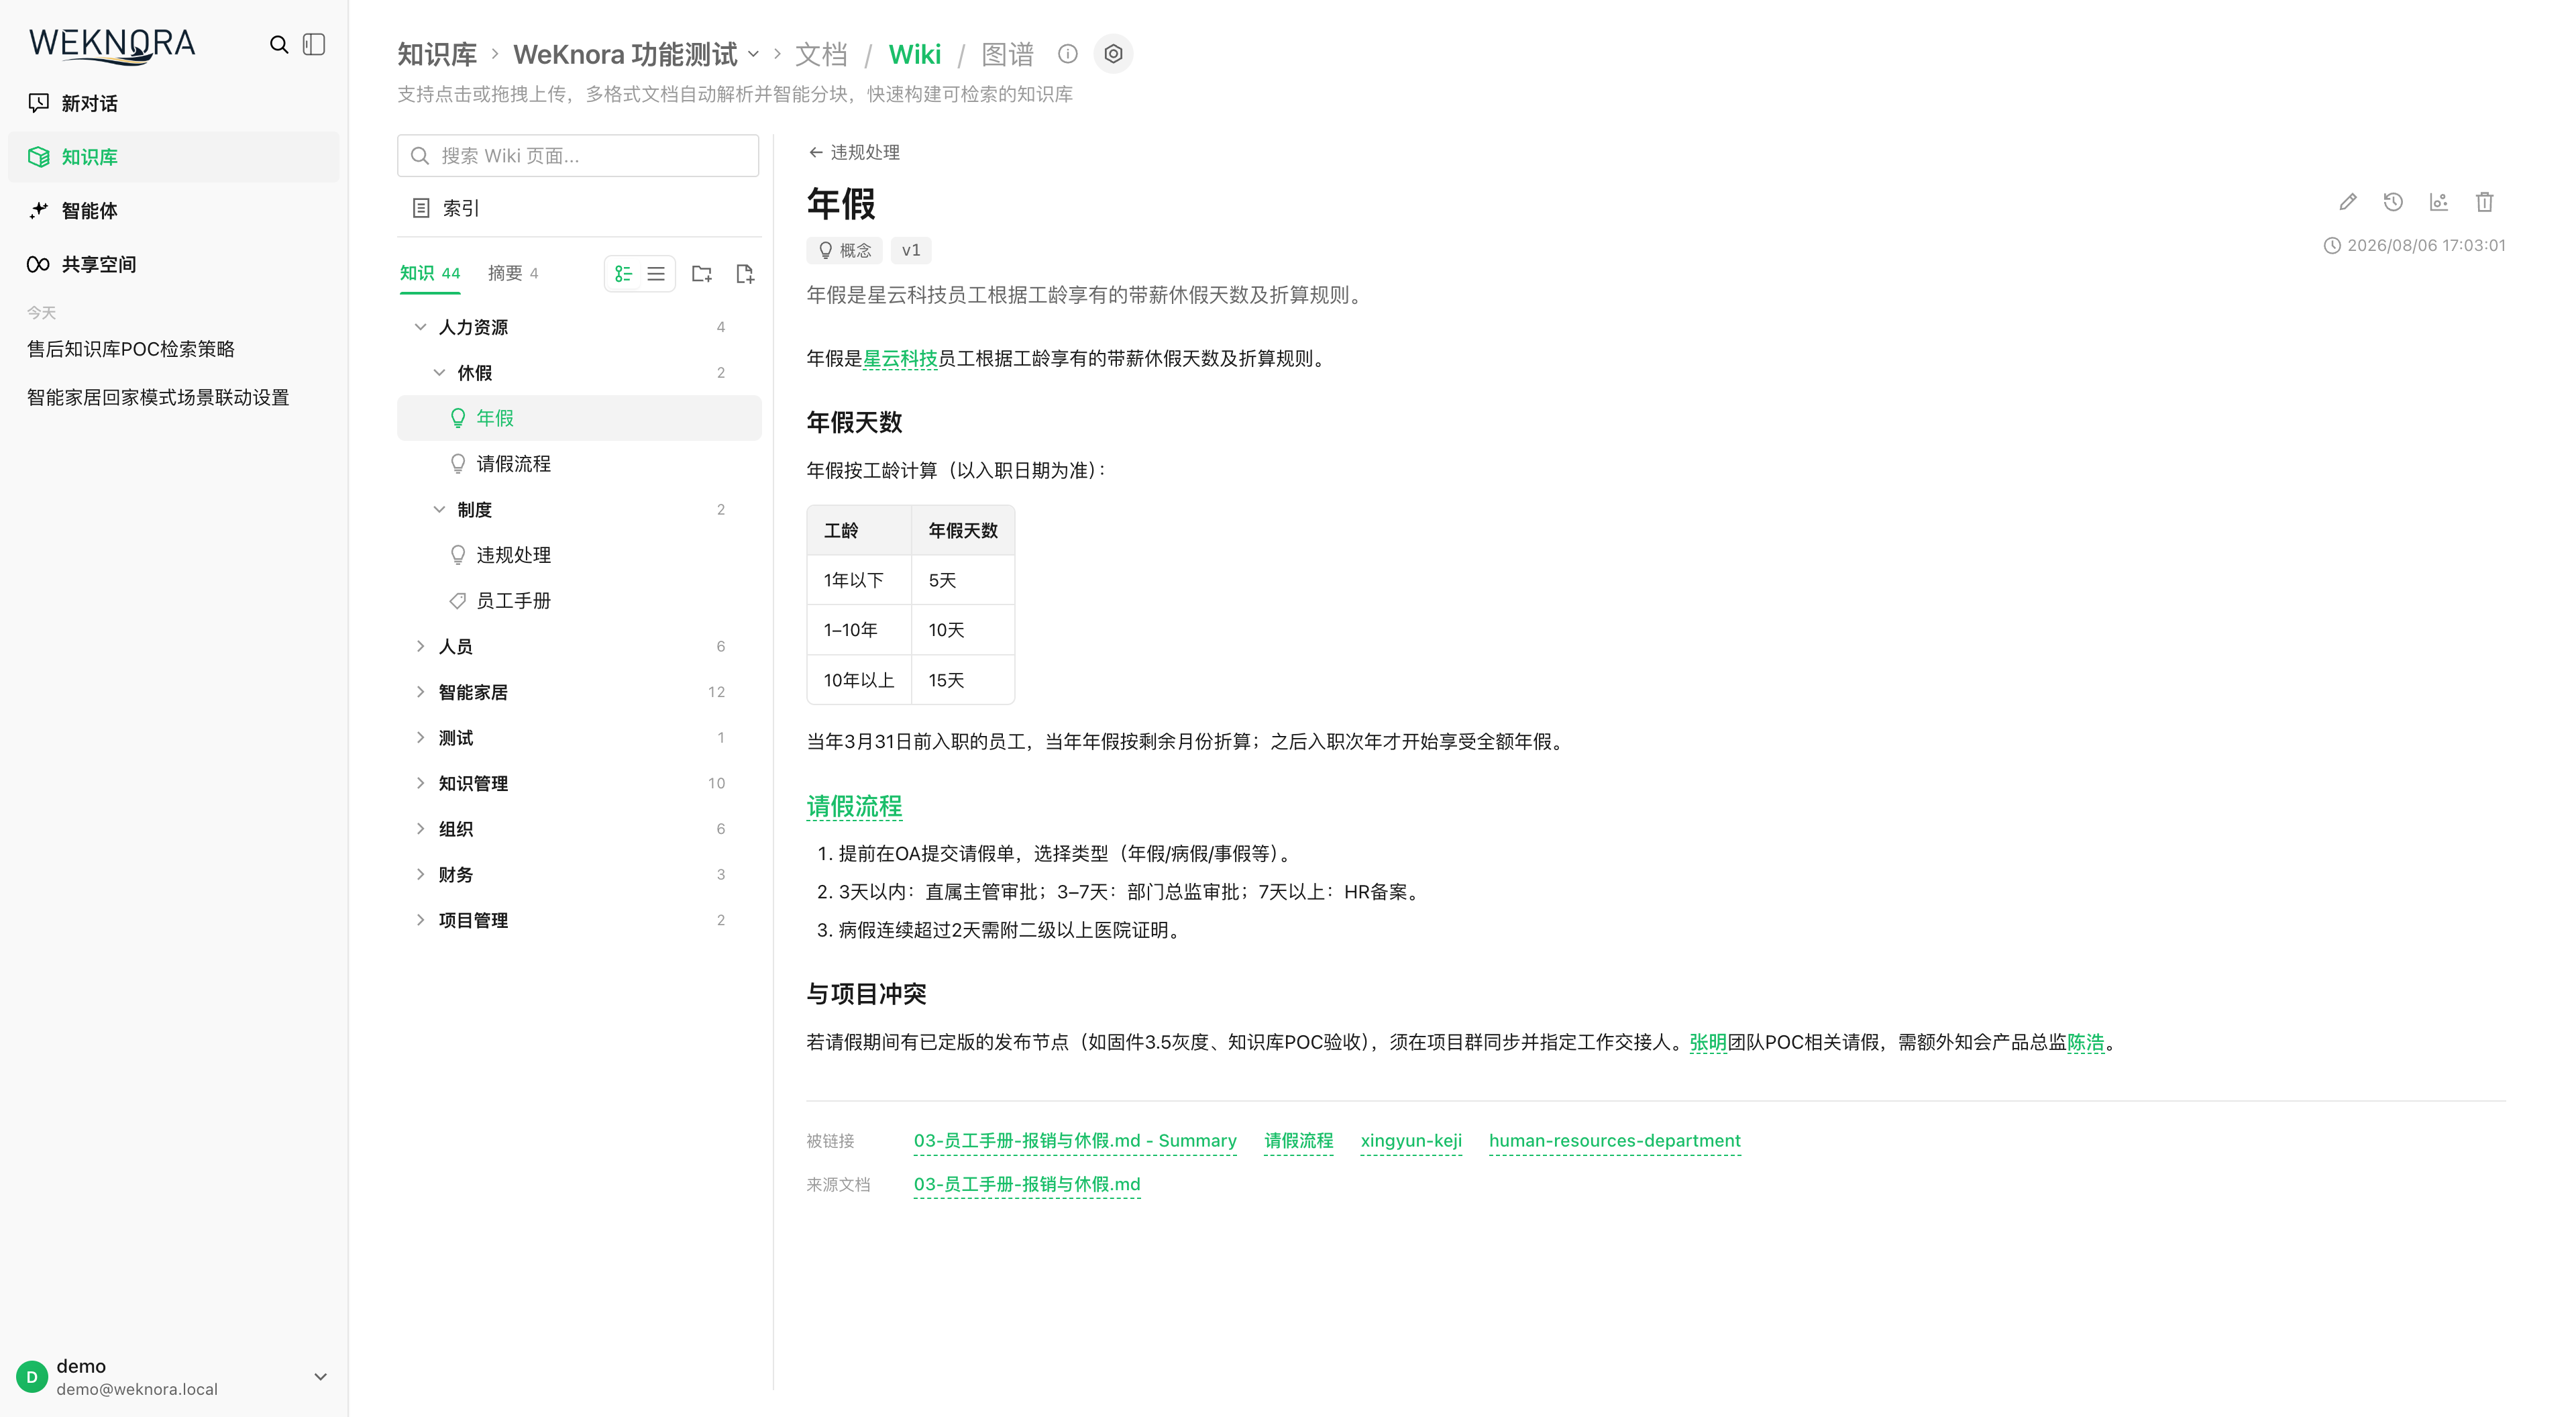 |
🕸️ Wiki Knowledge Graph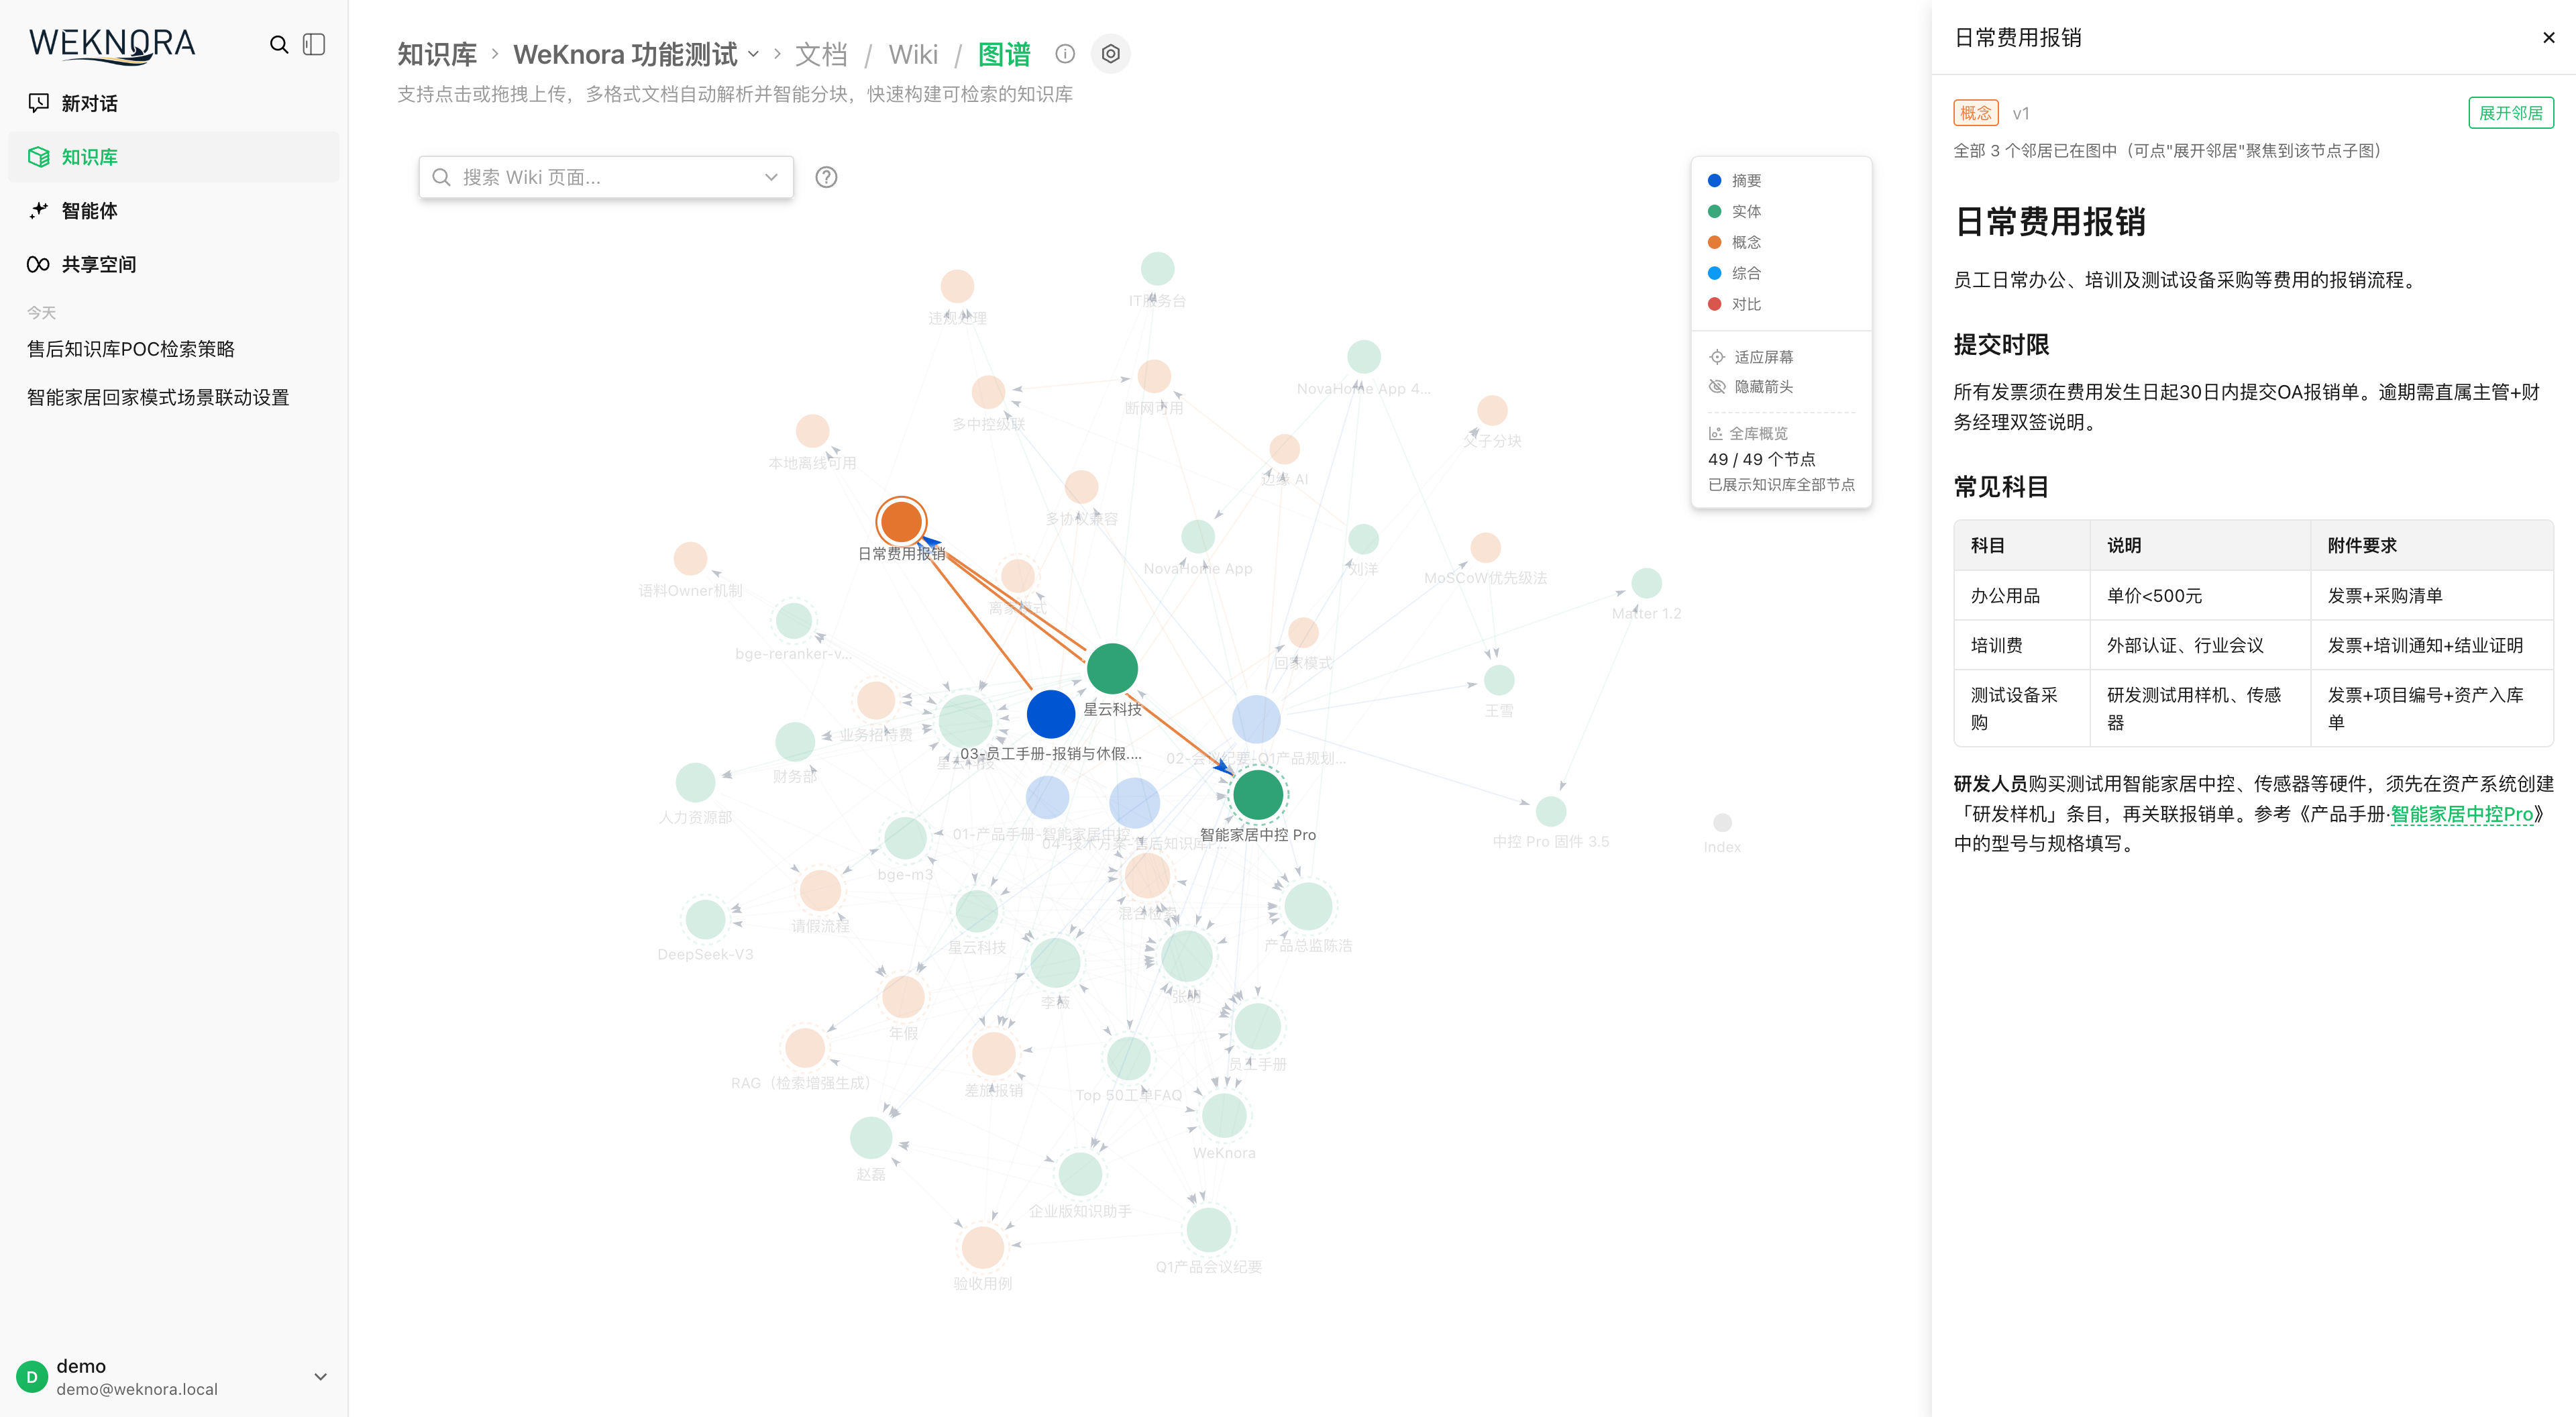 |
🕘 Wiki Page Revision History & Rollback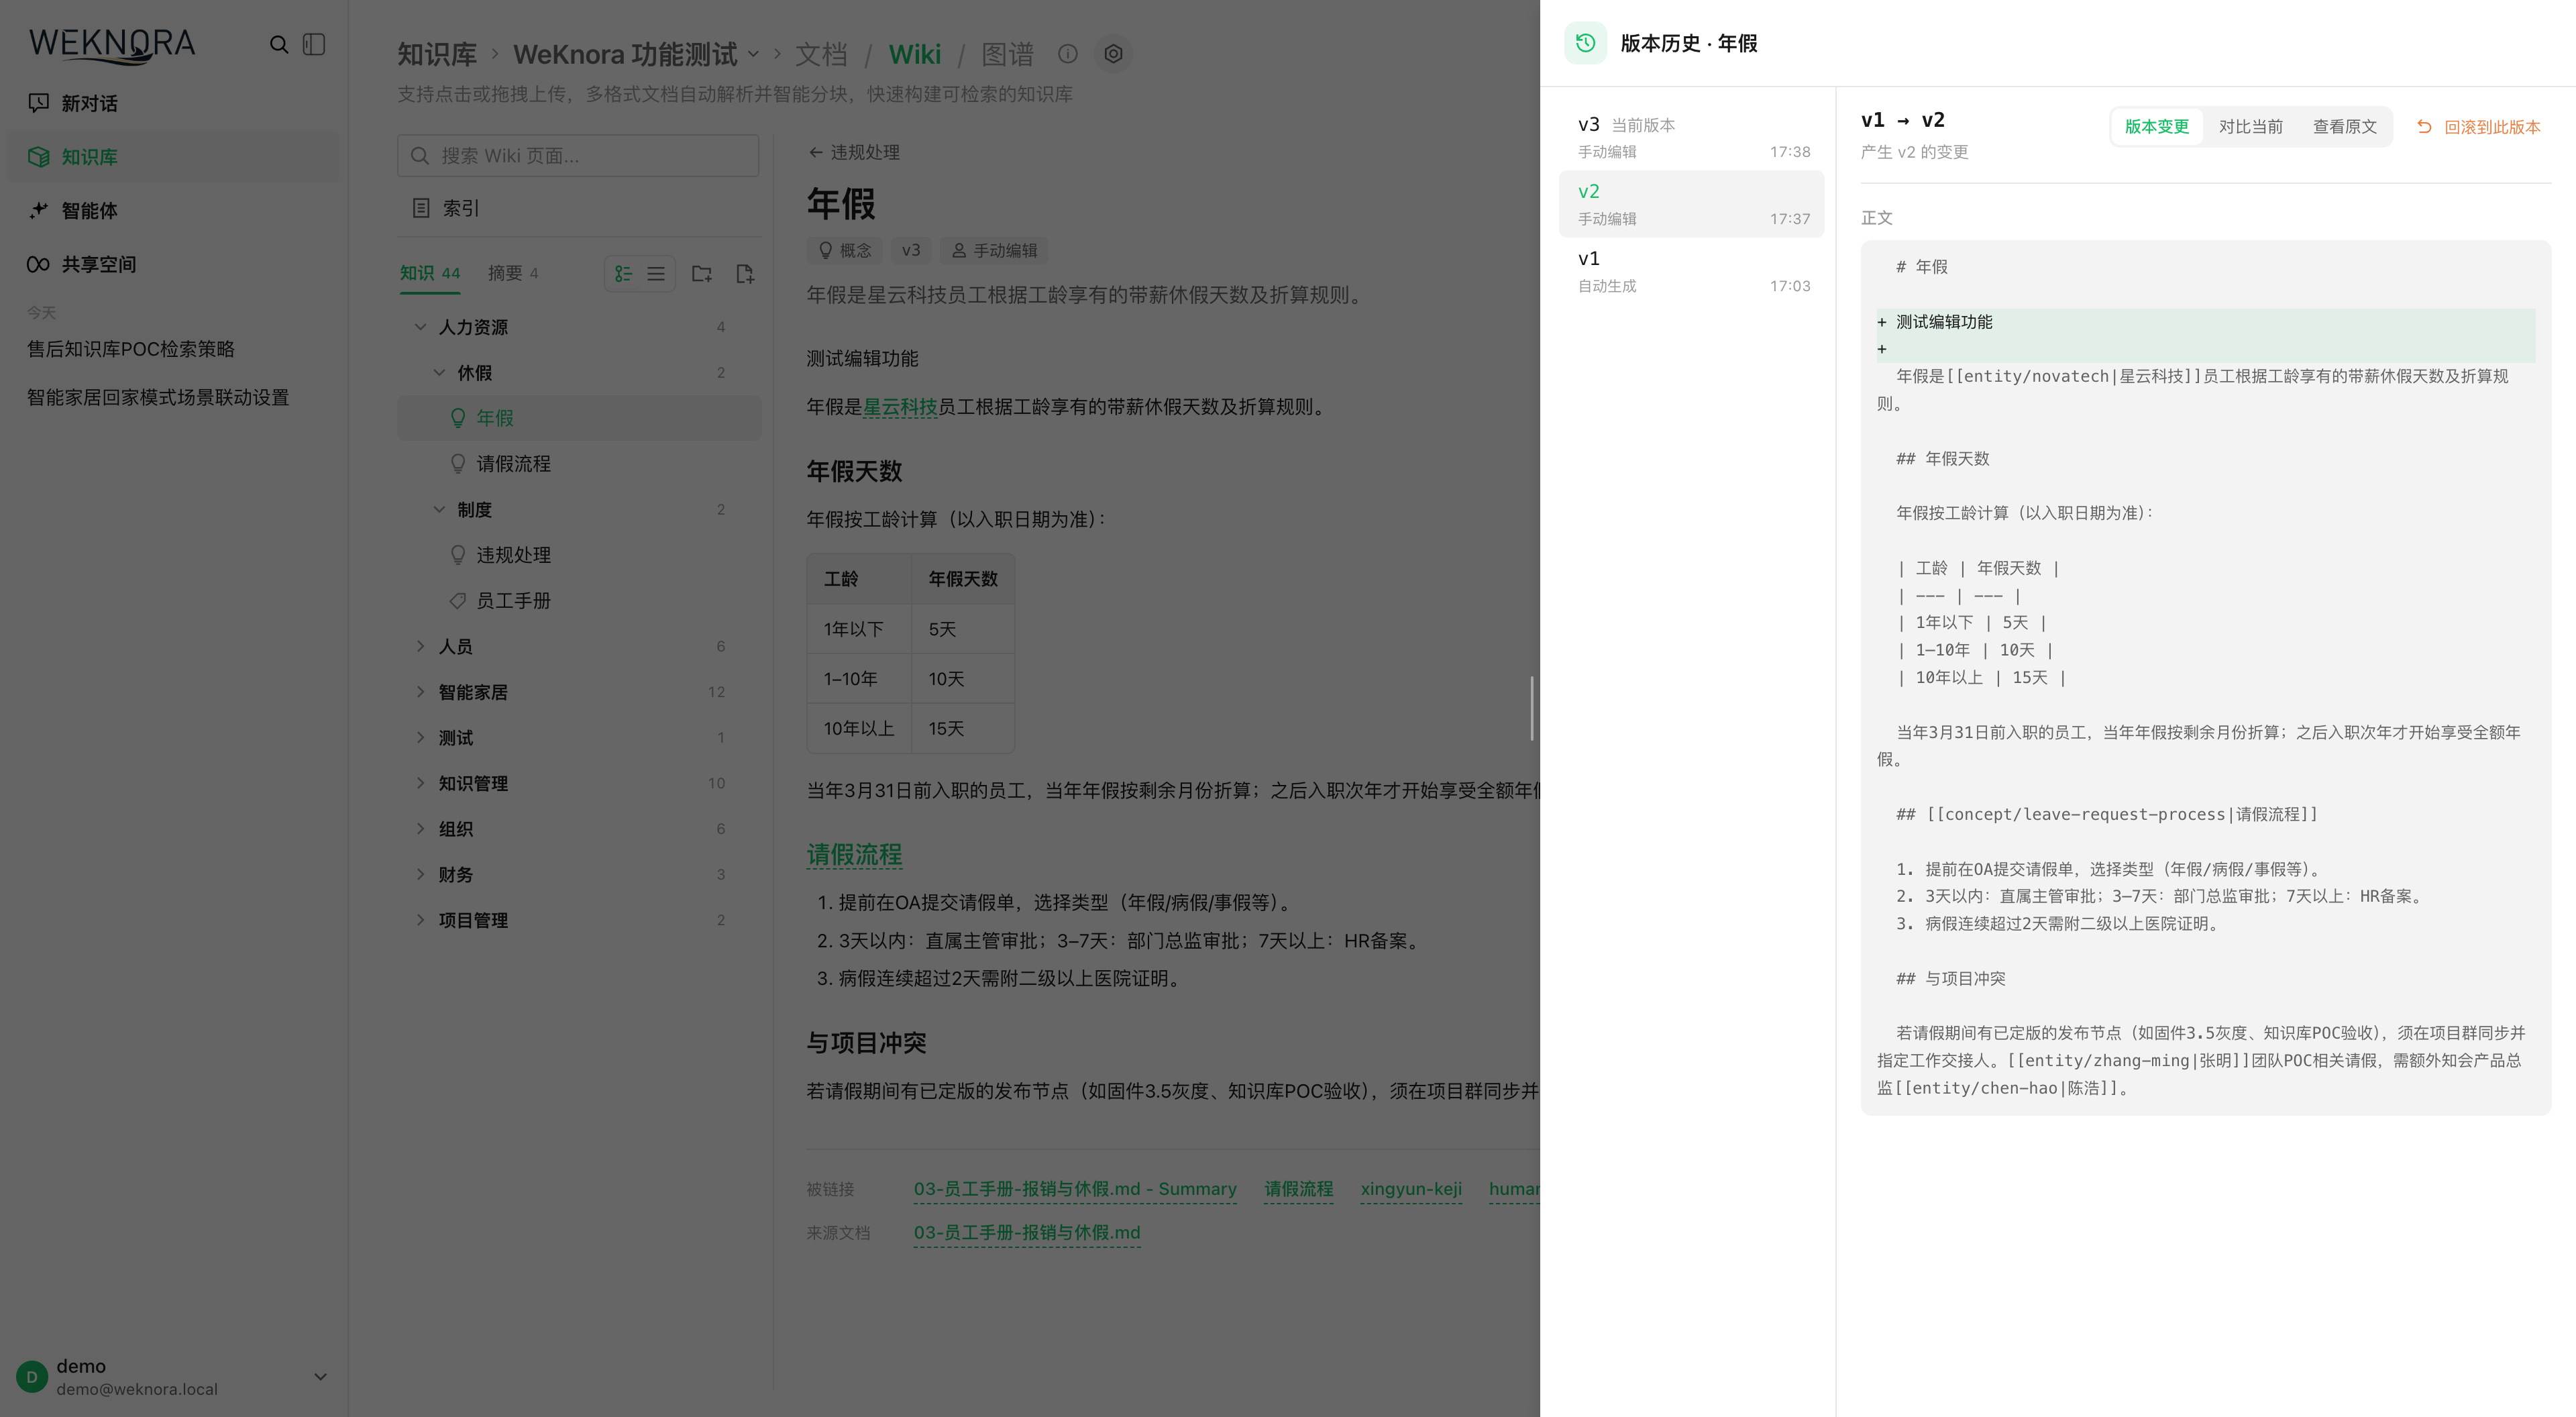 |
✂️ Chunk Editing & Revision History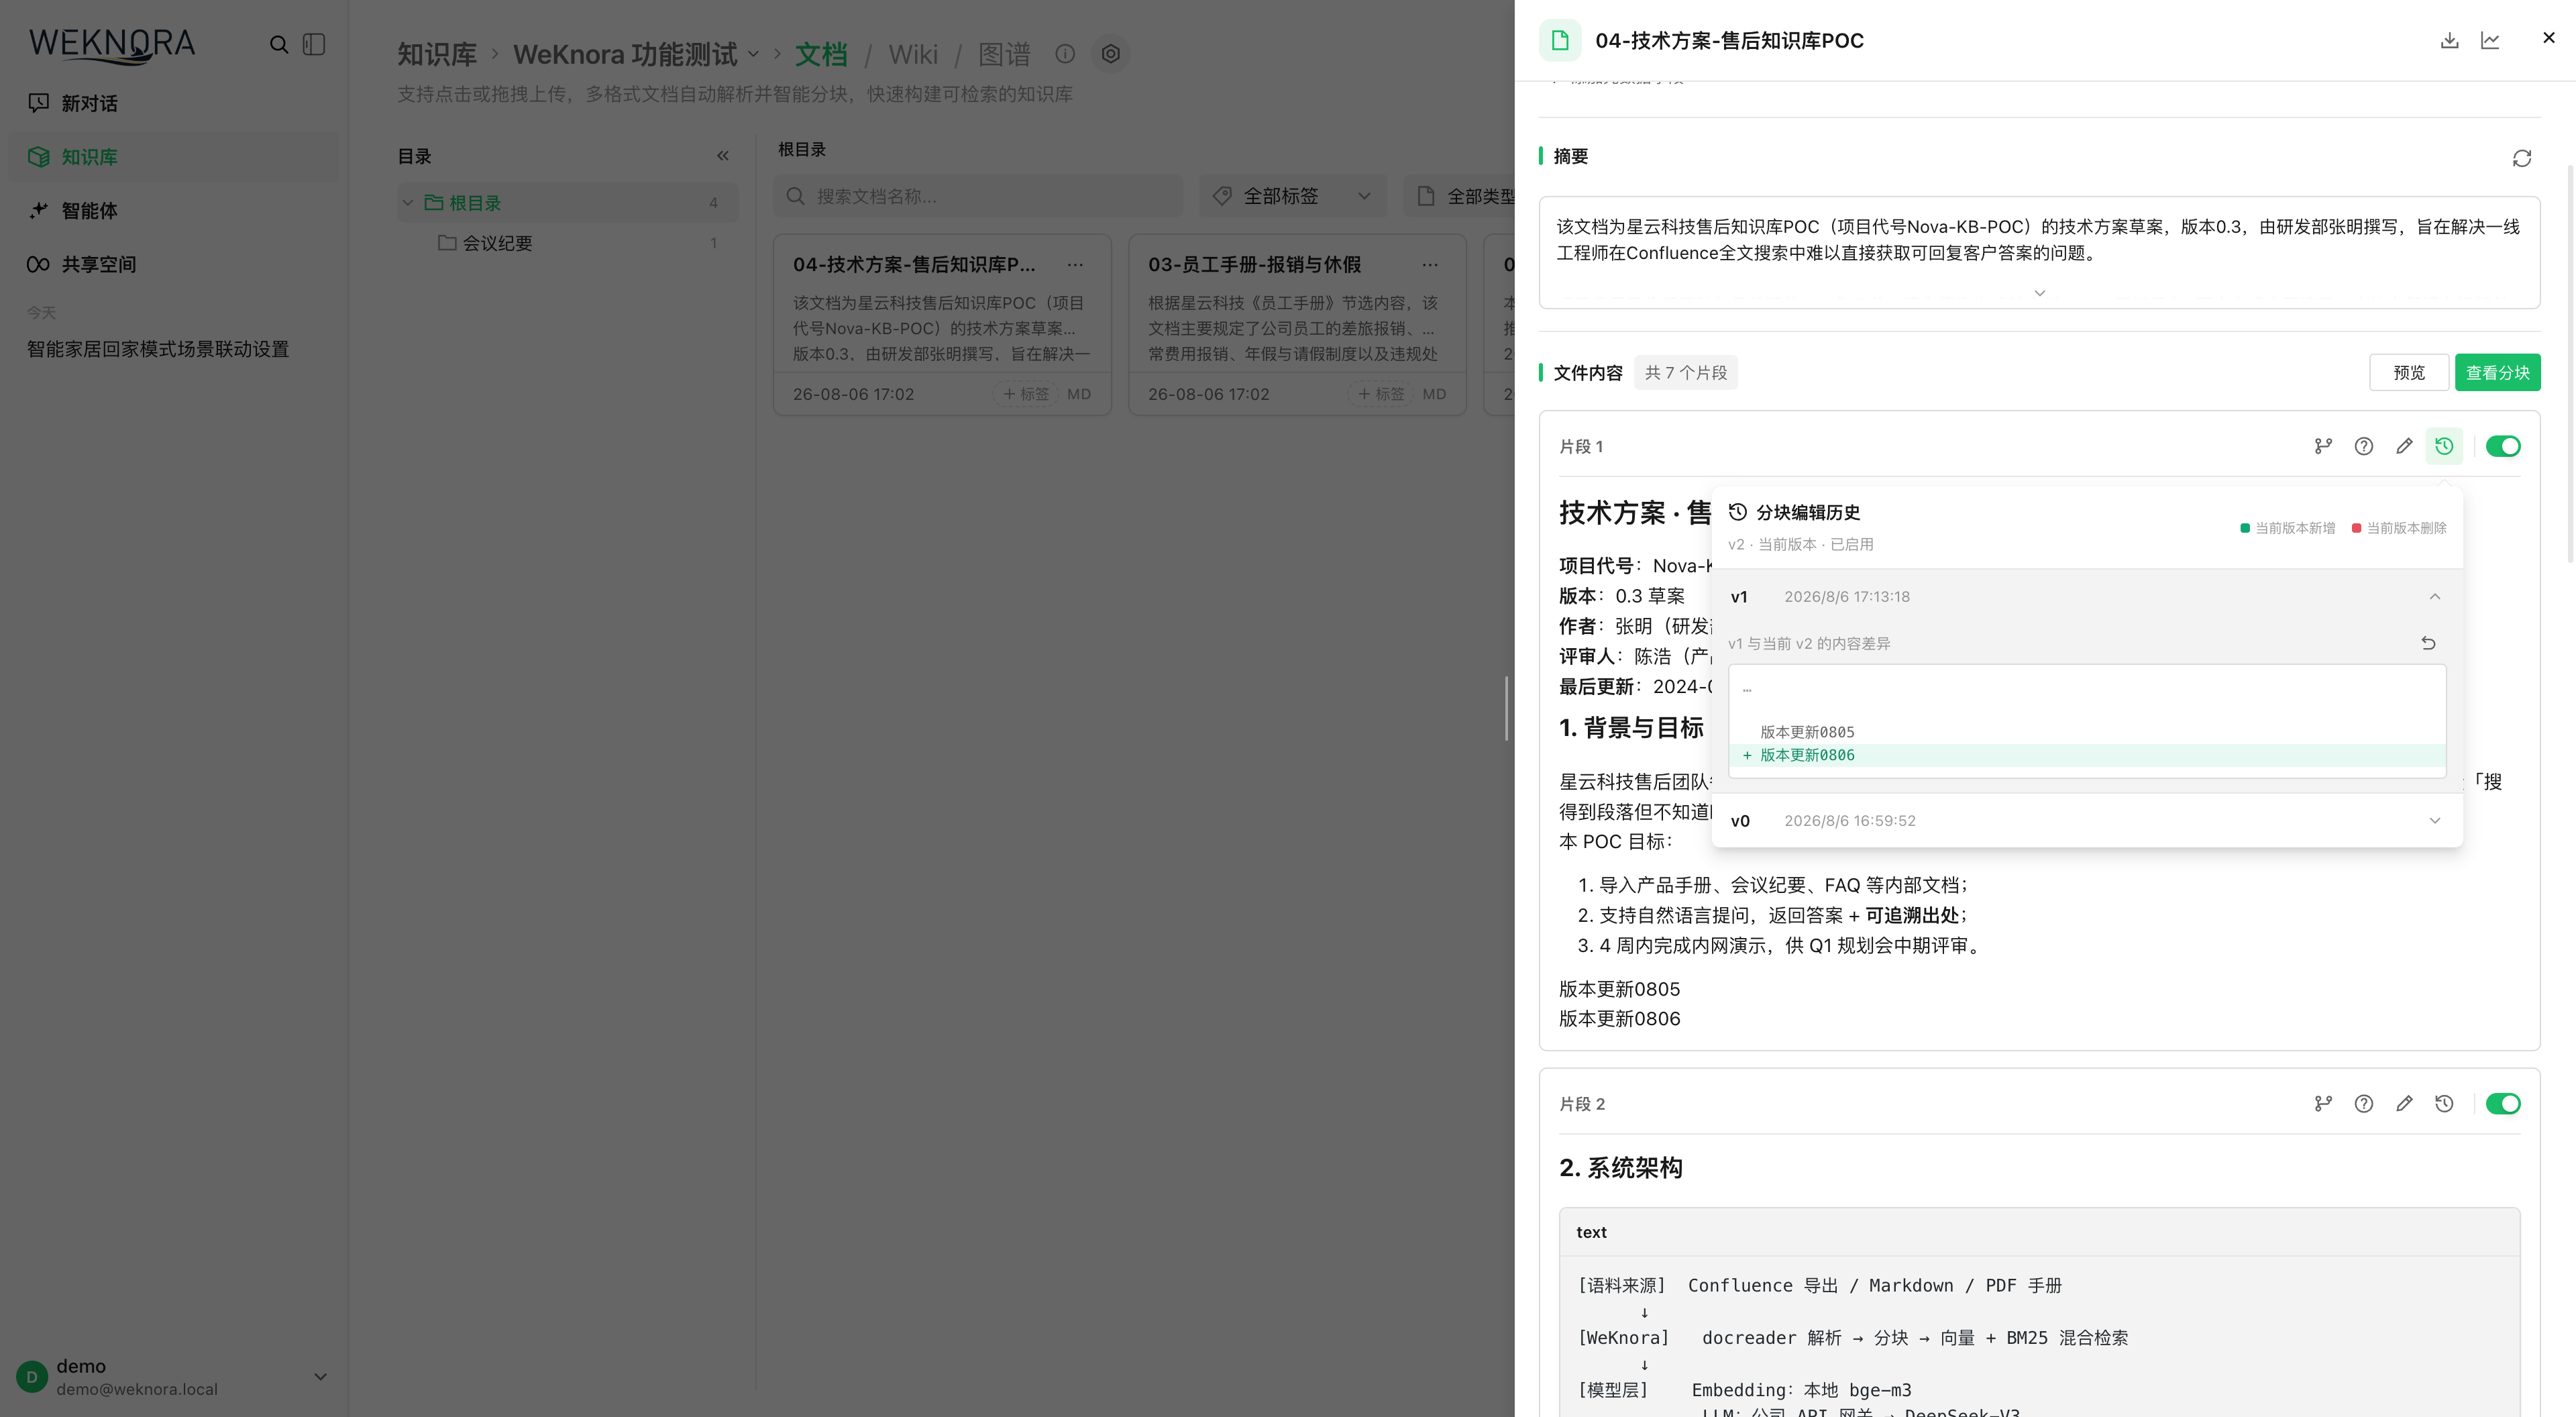 |
📁 Folder Tree & Batch Operations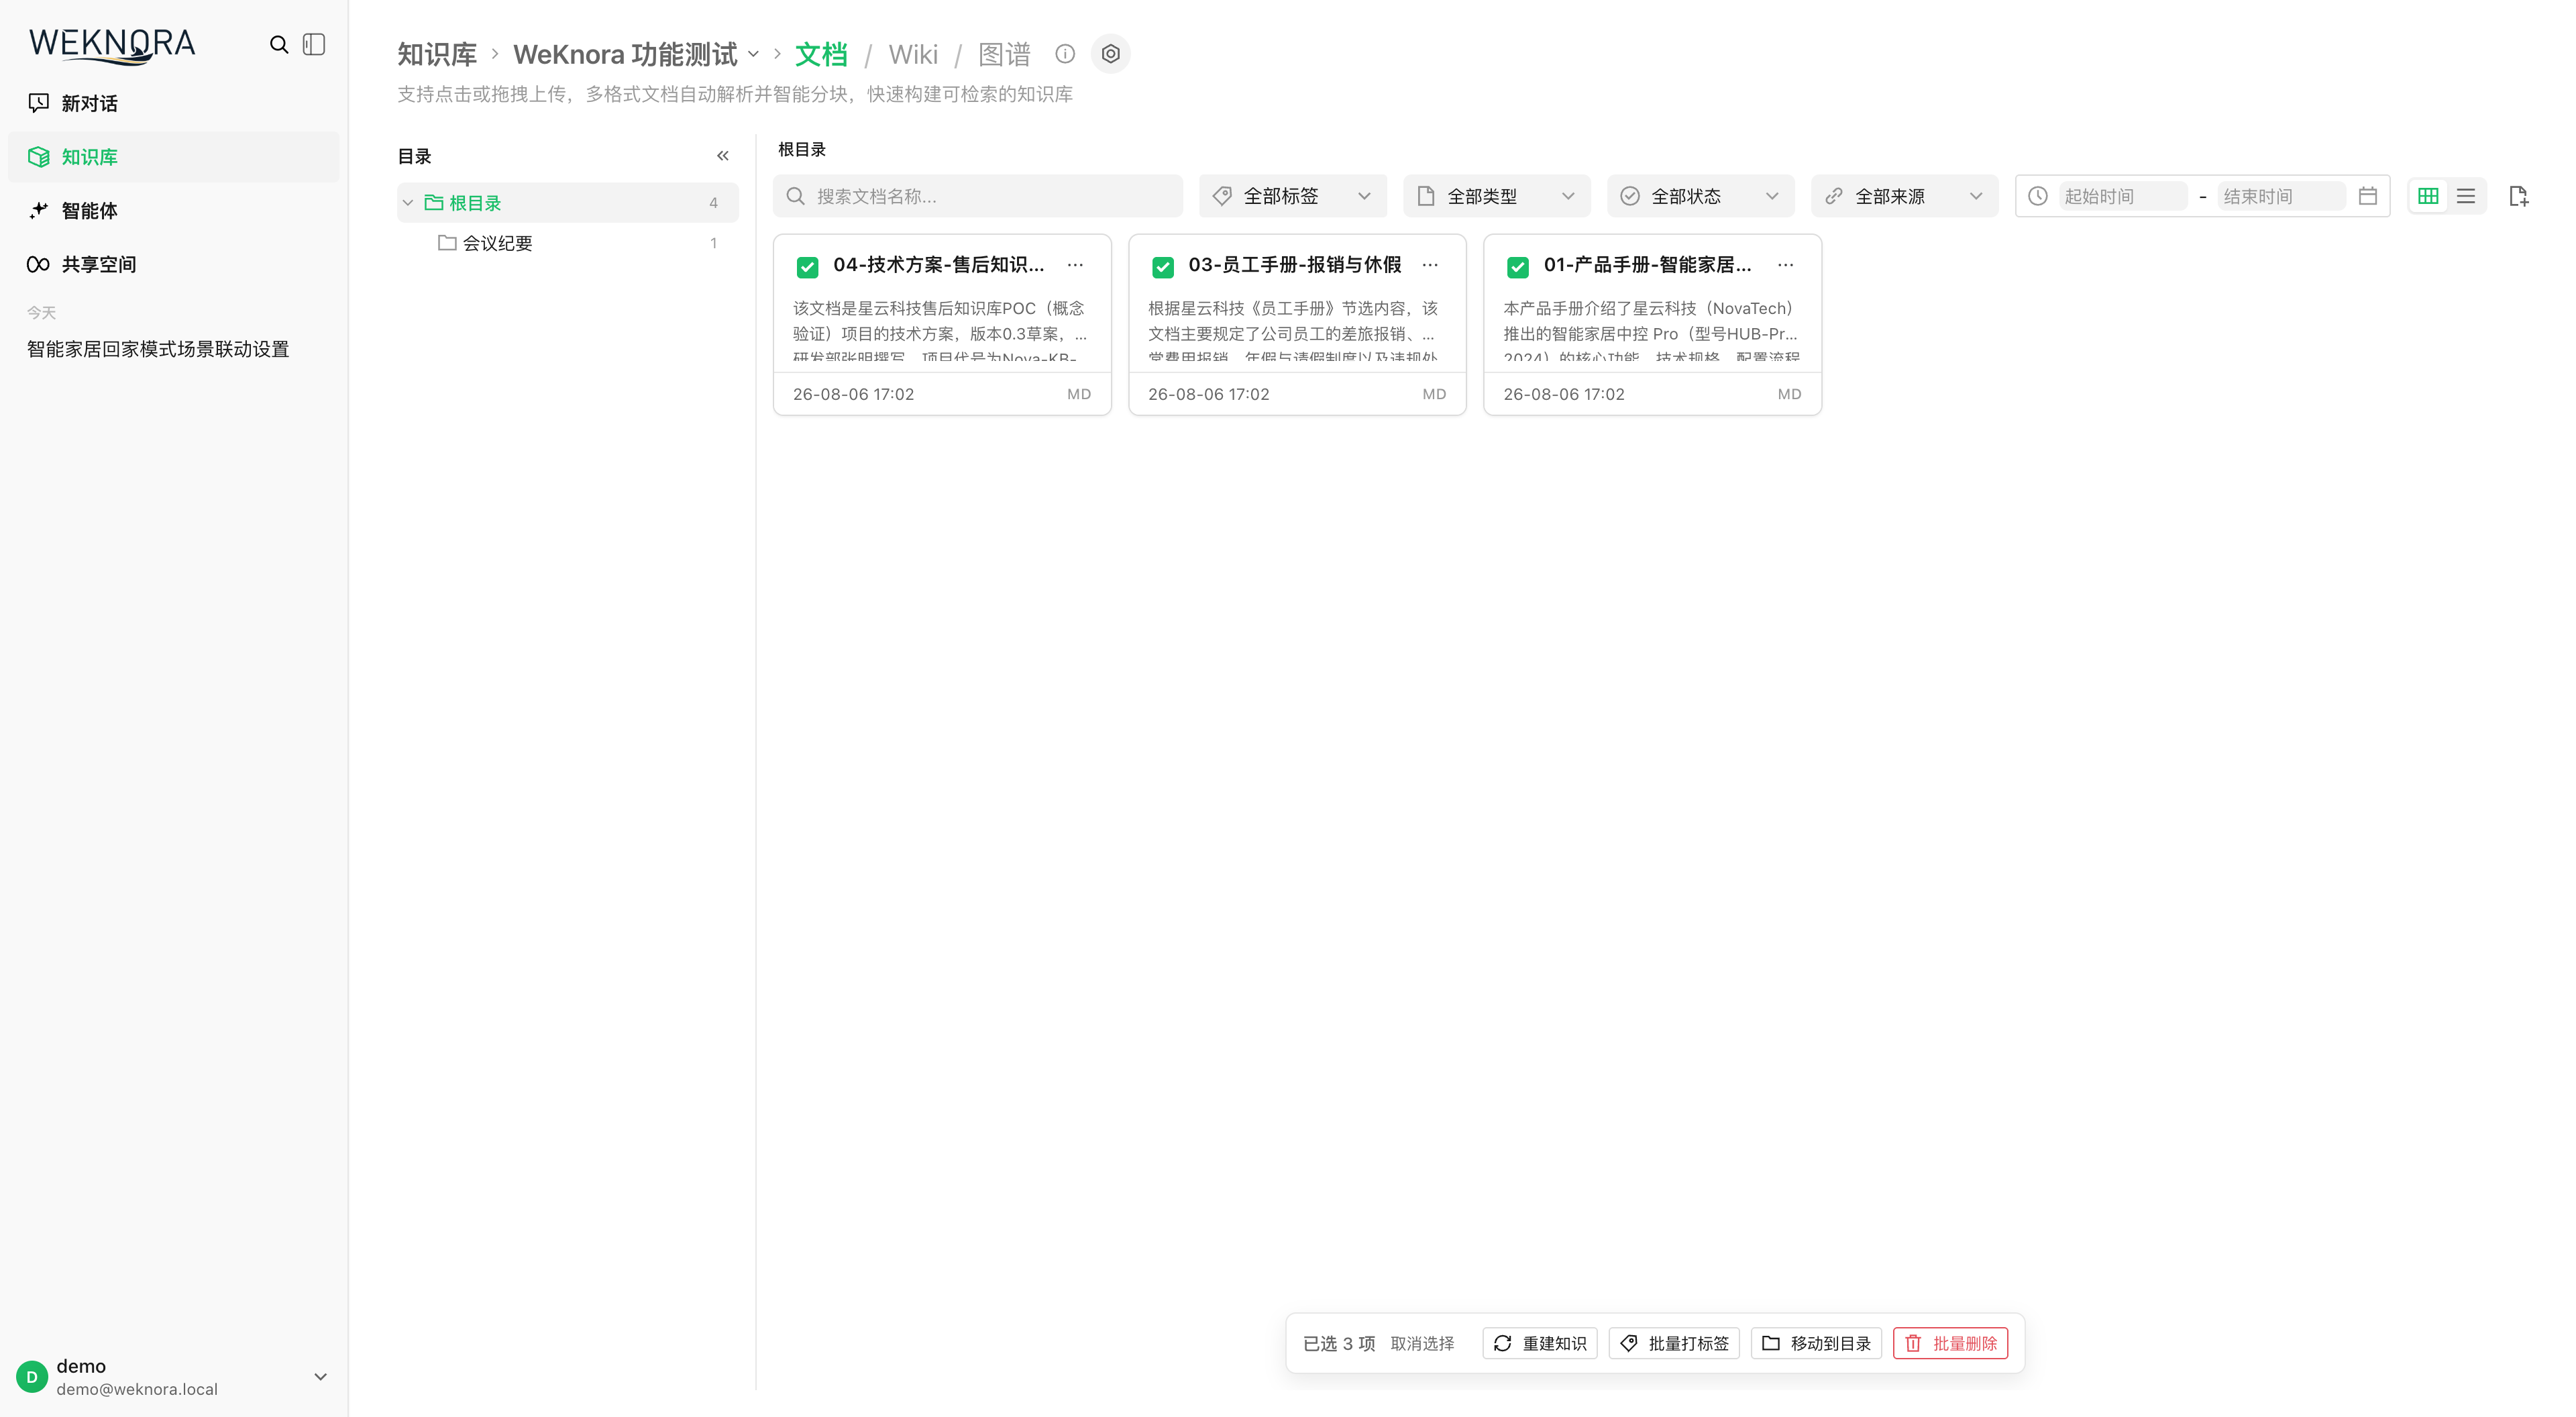 |
🔭 Observability · Langfuse Tracing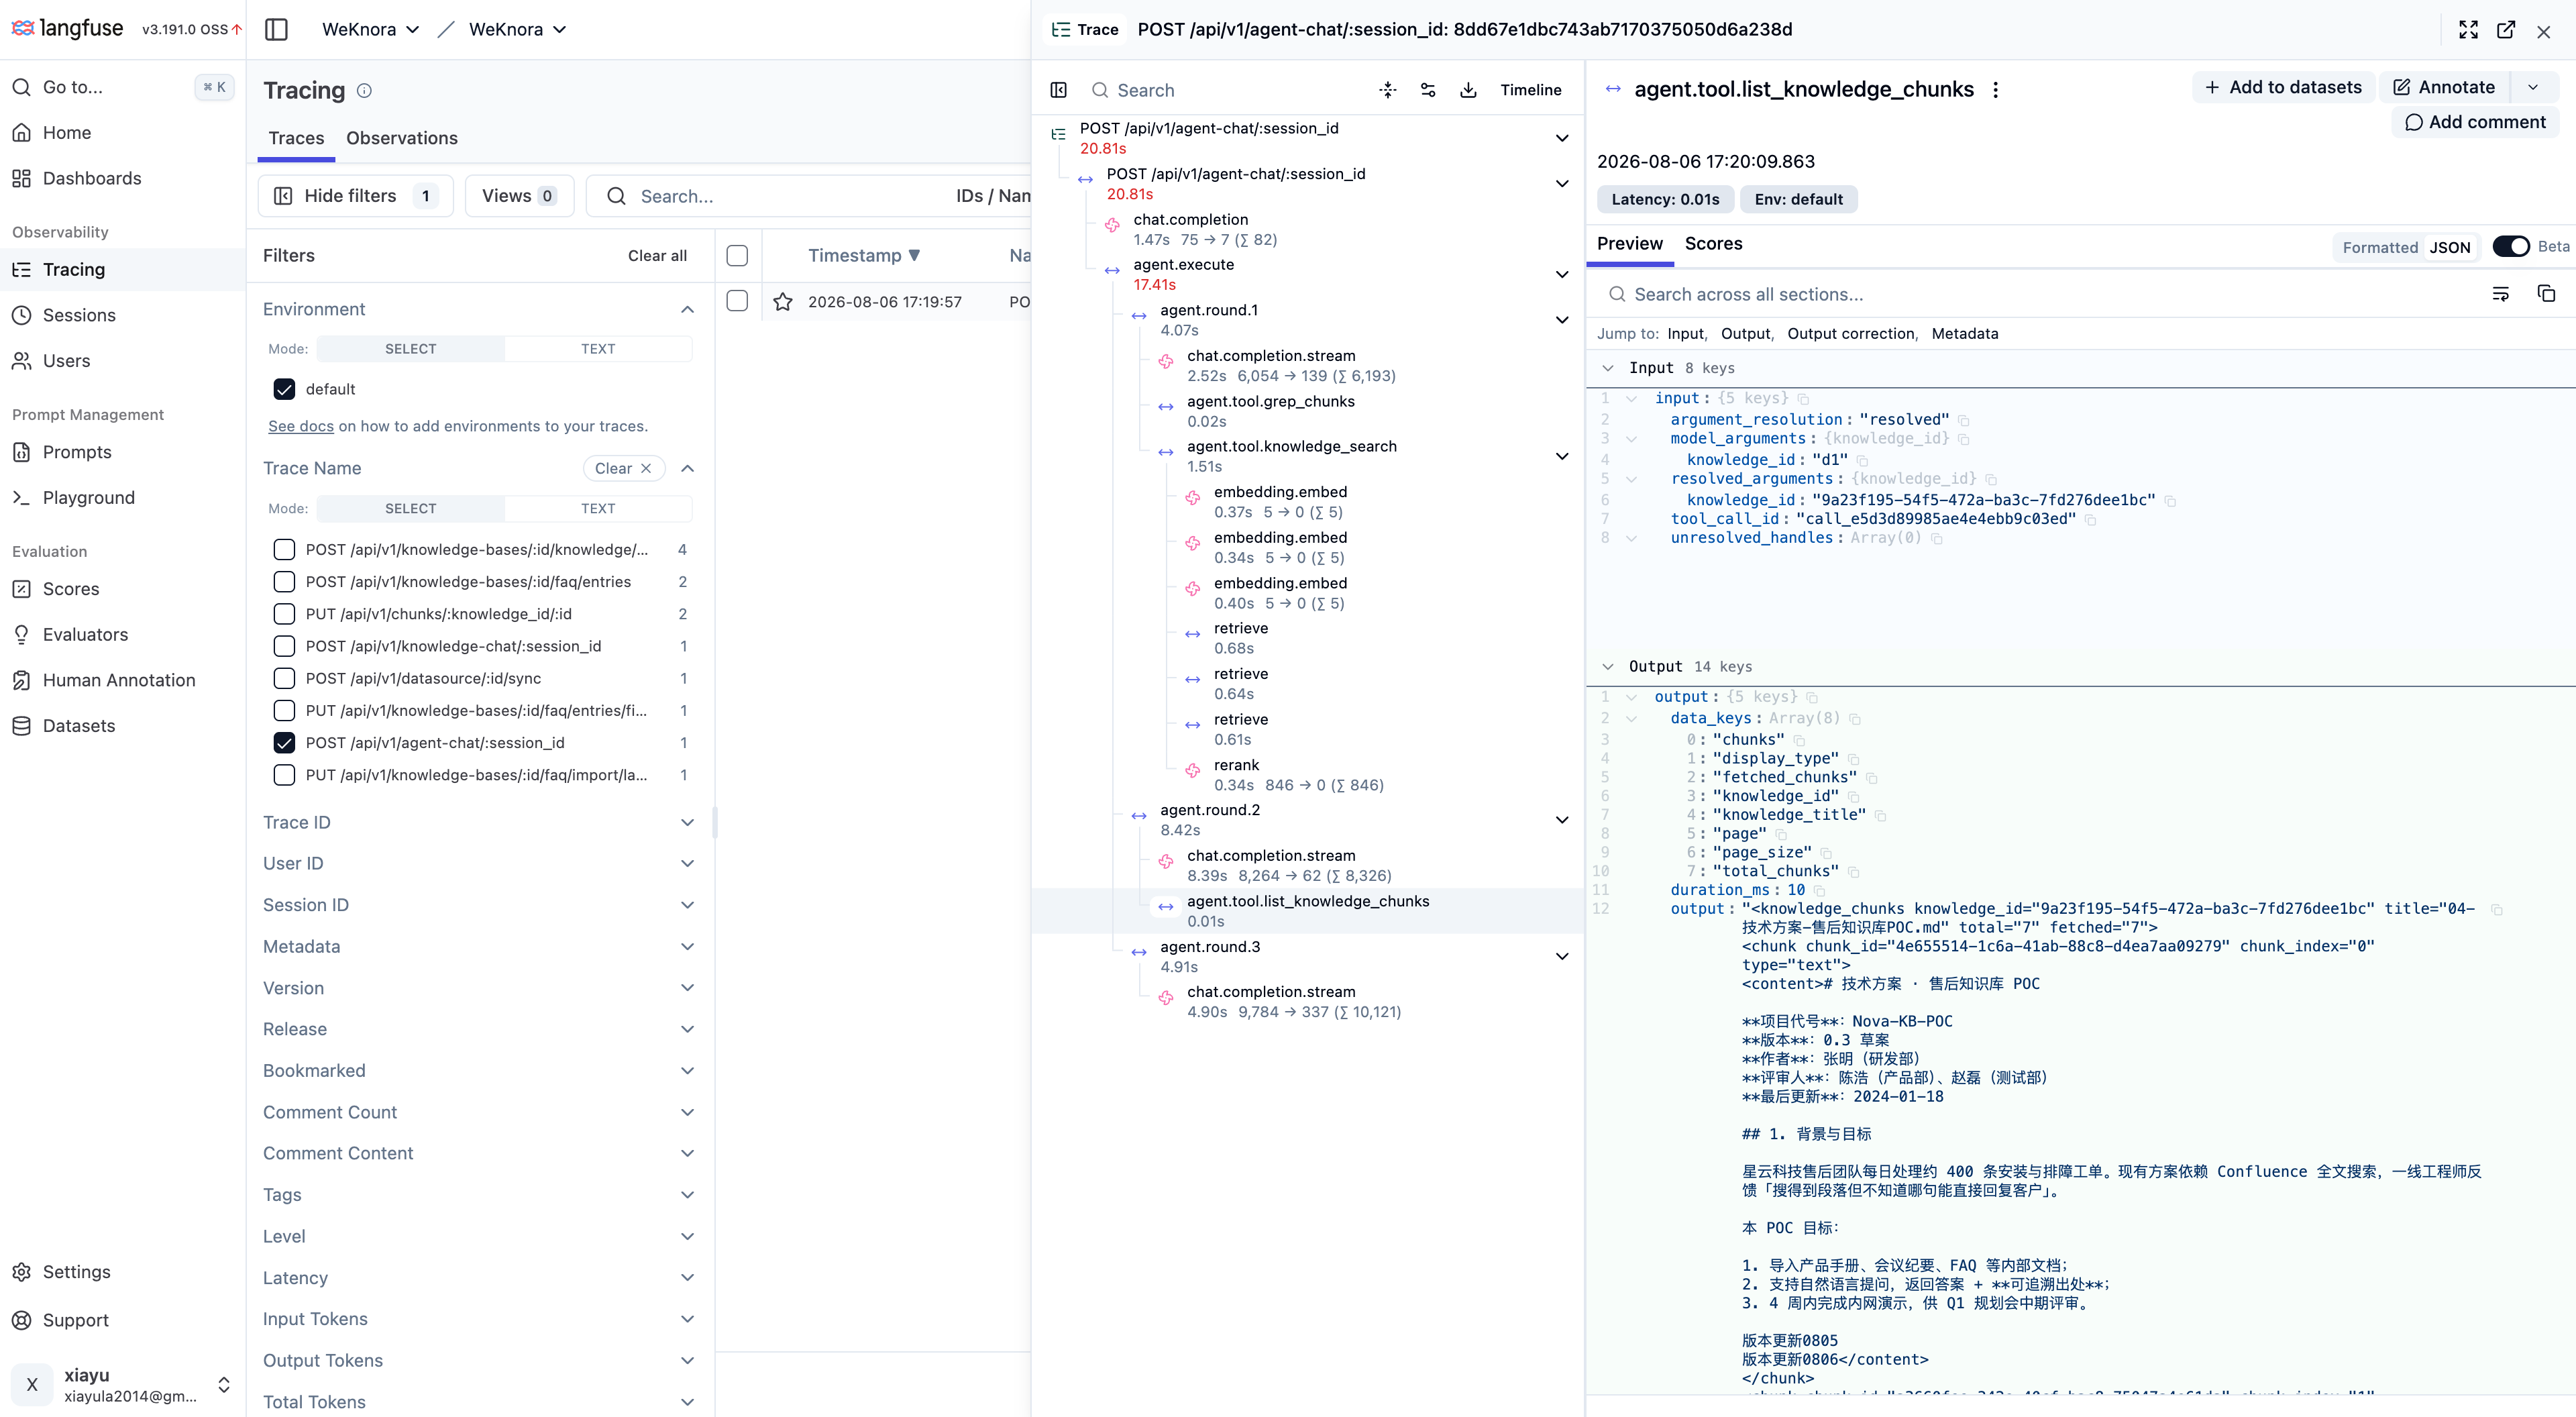 |
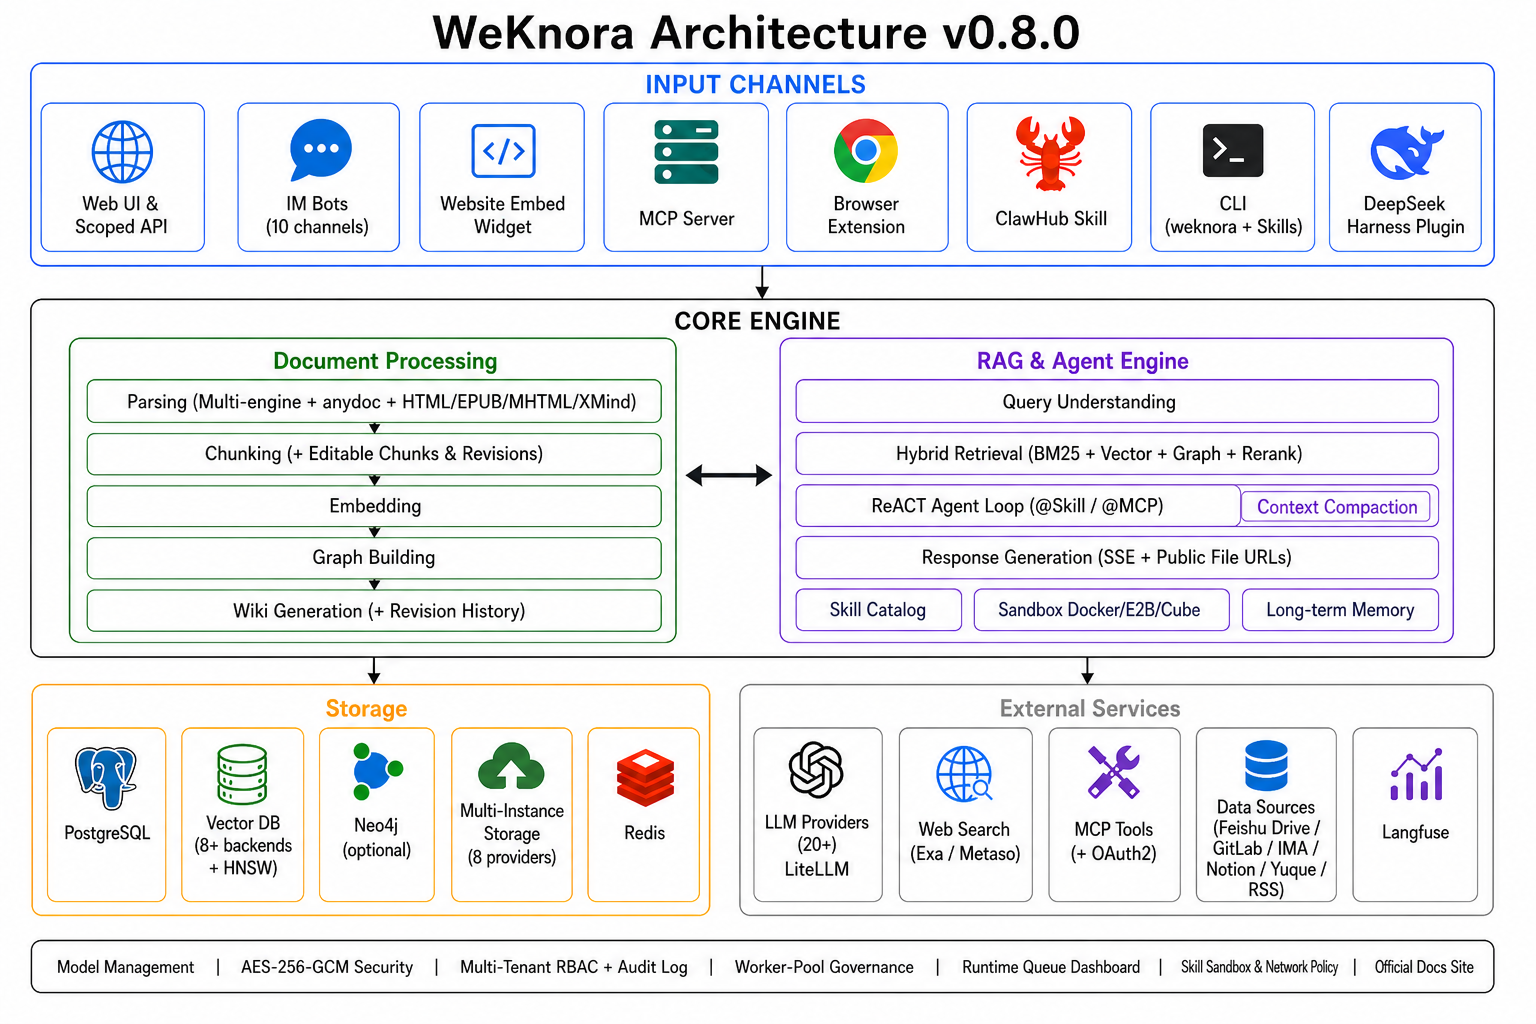
Fully modular pipeline from document parsing, vectorization, and retrieval to LLM inference — every component is swappable and extensible. Supports local / private cloud deployment with full data sovereignty and a zero-barrier Web UI for quick onboarding.
Intelligent Conversation
| Capability | Details |
|------------|---------|
| Intelligent Reasoning | ReACT progressive multi-step reasoning, autonomously orchestrating knowledge retrieval, MCP tools, skill sandboxes, and web search |
| Quick Q&A | RAG-based Q&A over knowledge bases for fast and accurate answers |
| Wiki Mode | Agent-driven auto-generation of structured, interlinked markdown Wiki pages from raw documents; in-browser manual editing, page revision history, line-level diff and one-click rollback |
| Skill Catalog & Sandbox | Workspace skill catalog (ClawHub / SkillHub / git / zip) installed onto session-persistent Docker / E2B / Cube sandboxes; shell_exec, file tools, artifacts, per-config network policy; Local host-process backend removed |
| Long-term Memory | Cross-session memory (profile / preference / fact / task / interest) with auto-extract, user confirm, and on-demand search_memory |
| Tool Calling | Built-in tools, MCP tools (incl. OAuth2 remote services, mid-conversation OAuth), web search; @Skill / @MCP mentions to scope the agent runtime per turn |
| Conversation Strategy | Online Prompt editing, retrieval threshold tuning, multi-turn context awareness, per-agent citation output toggle |
| Suggested Questions | Auto-generated question suggestions and after-answer follow-ups based on knowledge base content |
| Temporary Attachments | Session-scoped image / document uploads with async parsing for one-off Q&A, with a combined image + attachment limit |
| Citations & RAG Progress | Inline citation popovers and a references drawer (web / KB source distinction), shared markdown rendering, and stage-by-stage RAG pipeline progress in chat |
| Session Management | Filter and group sidebar sessions by source (Web / IM / Embed), with inline session-title rename |
Knowledge Management
| Capability | Details |
|------------|---------|
| Knowledge Base Types | FAQ / Document / Wiki with folder import, URL import, multi-tag management, and online entry |
| Folder Tree | Folder uploads keep their original directory structure, with a sidebar tree for browsing, folder rename, and re-filing documents into another folder |
| Chunk Editing & Revisions | Edit retrieval chunks directly in the UI with per-version snapshots, diff and one-click rollback, and automatic reindexing after an edit; generated questions can be added, edited, deleted and regenerated; custom document metadata supported |
| Per-Upload Process Config | Override parser, chunking, multimodal (VLM / ASR), graph extraction, and question generation per upload batch via upload-confirm dialog or process_config API; reparse with new settings |
| Batch Reparse | Re-queue parsing for multiple documents at once with optional per-batch process_config |
| Data Source Import | Auto-sync from Feishu wiki / Feishu Drive / Lark / GitLab / Tencent IMA / Notion / Yuque / DingTalk Docs / RSS feeds (more data sources coming soon); incremental and full sync |
| Document Formats | PDF / Word / Txt / Markdown / HTML / EPUB / MHTML / Images / CSV / Excel / PPT / JSON / XMind |
| Auto-Tagging | After parse, pick matching tags from the knowledge base's existing set without creating tags or overwriting manual ones |
| Retrieval Strategies | BM25 sparse / Dense retrieval / GraphRAG / parent-child chunking / HNSW-accelerated pgvector (1024-dim) / multi-dimensional indexing |
| Batch Selection & Tagging | Marquee drag-select multiple documents in the KB list for batch reparse and batch tagging (common tags pre-selected) |
| E2E Testing | Full-pipeline visualization with recall hit rate, BLEU / ROUGE metric evaluation |
Integrations & Extensions
| Capability | Details |
|------------|---------|
| LLMs | OpenAI / Azure OpenAI / Anthropic (Claude) / DeepSeek / Qwen (Alibaba Cloud) / Zhipu / Hunyuan / Doubao (Volcengine) / Gemini / MiniMax / NVIDIA / Novita AI / SiliconFlow / OpenRouter / Requesty / LiteLLM / Ollama |
| Embeddings | Ollama / BGE / GTE / Zhipu / OpenAI-compatible APIs |
| Vector DBs | PostgreSQL (pgvector) / Elasticsearch / OpenSearch / Milvus / Weaviate / Qdrant / Apache Doris / Tencent VectorDB |
| Object Storage | Local / MinIO / AWS S3 (IAM Role / IRSA default credential chain) / Volcengine TOS / Alibaba Cloud OSS / Kingsoft Cloud KS3 / Huawei Cloud OBS; multiple storage instances per workspace with per-KB binding and a default instance |
| IM Channels | WeCom / Feishu / Lark (Feishu International) / QQBot / Slack / Telegram / DingTalk / Mattermost / WeChat / Yunzhijia |
| Website Embed | Publish agents via embed widget with domain allowlists, rate limits, and secure-mode token exchange |
| Web Search | DuckDuckGo / Bing / Google / Tavily / Baidu / Ollama / SearXNG / Keenable / Zhipu AI / Exa / Metaso |
| API Integration | Scoped API keys (capability-level grants + per-KB restriction + throttled last-used tracking) with an API integration playground; MCP OAuth and embed sessions isolated per principal; resource_urls=public returns directly loadable file/image URLs, removing the second authenticated proxy call |
| MCP Server | Official PyPI package tencent-weknora-mcp with 29 tools over stdio / SSE / HTTP transports |
Platform
| Capability | Details |
|------------|---------|
| Deployment | Local / Docker / Kubernetes (Helm) with private and offline support |
| UI | Web UI / RESTful API / CLI (weknora) / Chrome Extension / Website Embed Widget / WeChat Mini Program |
| Access Control | Workspace RBAC with 4-tier role matrix (Owner / Admin / Contributor / Viewer), per-KB resource ownership, per-workspace audit log, invite-only workspaces, tenantless provisioning & gated self-service workspace creation, admin password reset (session revocation), cross-workspace superuser, scoped API keys |
| Security | AES-256-GCM at-rest encryption for API keys and MCP / data-source credentials with graceful key rotation; gRPC TLS + Token between app and docreader; Redis TLS; SSRF-safe HTTP client (data sources, URL import, redirect chains); secret redaction in responses; skill sandbox isolation (Docker opt-in / E2B / Cube) with per-config network policy; OIDC ID-token JWKS verification; optional complex-password policy |
| Observability | Integrated Langfuse (sole tracing backend) for ReAct loops, token tracking, tool calls, and pipeline tracing; built-in Langfuse-style document parsing trace timeline with stage-by-stage progress; system-admin runtime task-queue dashboard (queue depth, per-model concurrency, failed-task inspection & manual retry) |
| Task Management | MQ async tasks with per-stage worker-pool governance (core / post-process / enrichment / maintenance + elastic shared pool, plus an independent Wiki pool) and per-model background concurrency governors; automatic database migration on version upgrade |
| Model Management | Centralized config, declarative built-in models via YAML, per-knowledge-base model selection, per-model thinking-mode and embedding-dimension overrides, interactive model test debugger, multi-workspace built-in model sharing, WeKnora Cloud hosted models and parsing |
WeKnora Chrome Extension lets you capture web content directly into your WeKnora knowledge base. Select text, images, or entire pages in the browser and save them as knowledge entries with one click — no copy-paste or file upload needed.
The WeKnora Mini Program provides a lightweight mobile client for configuring WeKnora API access, selecting knowledge bases, importing URLs, and asking knowledge chat from WeChat.
WeKnora ClawHub Skill is a WeKnora skill published on the ClawHub platform. Once installed, it enables document import (file / URL / Markdown), hybrid search (vector + keyword) across knowledge bases, and knowledge entry management — all through the WeKnora REST API.
→ →
 →
 →
 →
 →