1
 →
MiniCPM5: SOTA on-device LLMs, small yet powerful.
中文 | English
MiniCPM Tech Report | MiniCPM Wiki (in Chinese) | MiniCPM-V Repo | UltraData | Online Demo
Join our discord and Feishu/Lark | Join Us
We are releasing MiniCPM5-2B, the second model in the MiniCPM5 series, following MiniCPM5-1B. It is a dense 2B Transformer that scales up the same training recipe, built for on-device, local deployment, and resource-constrained scenarios, reaching 2B-class open-source SOTA.
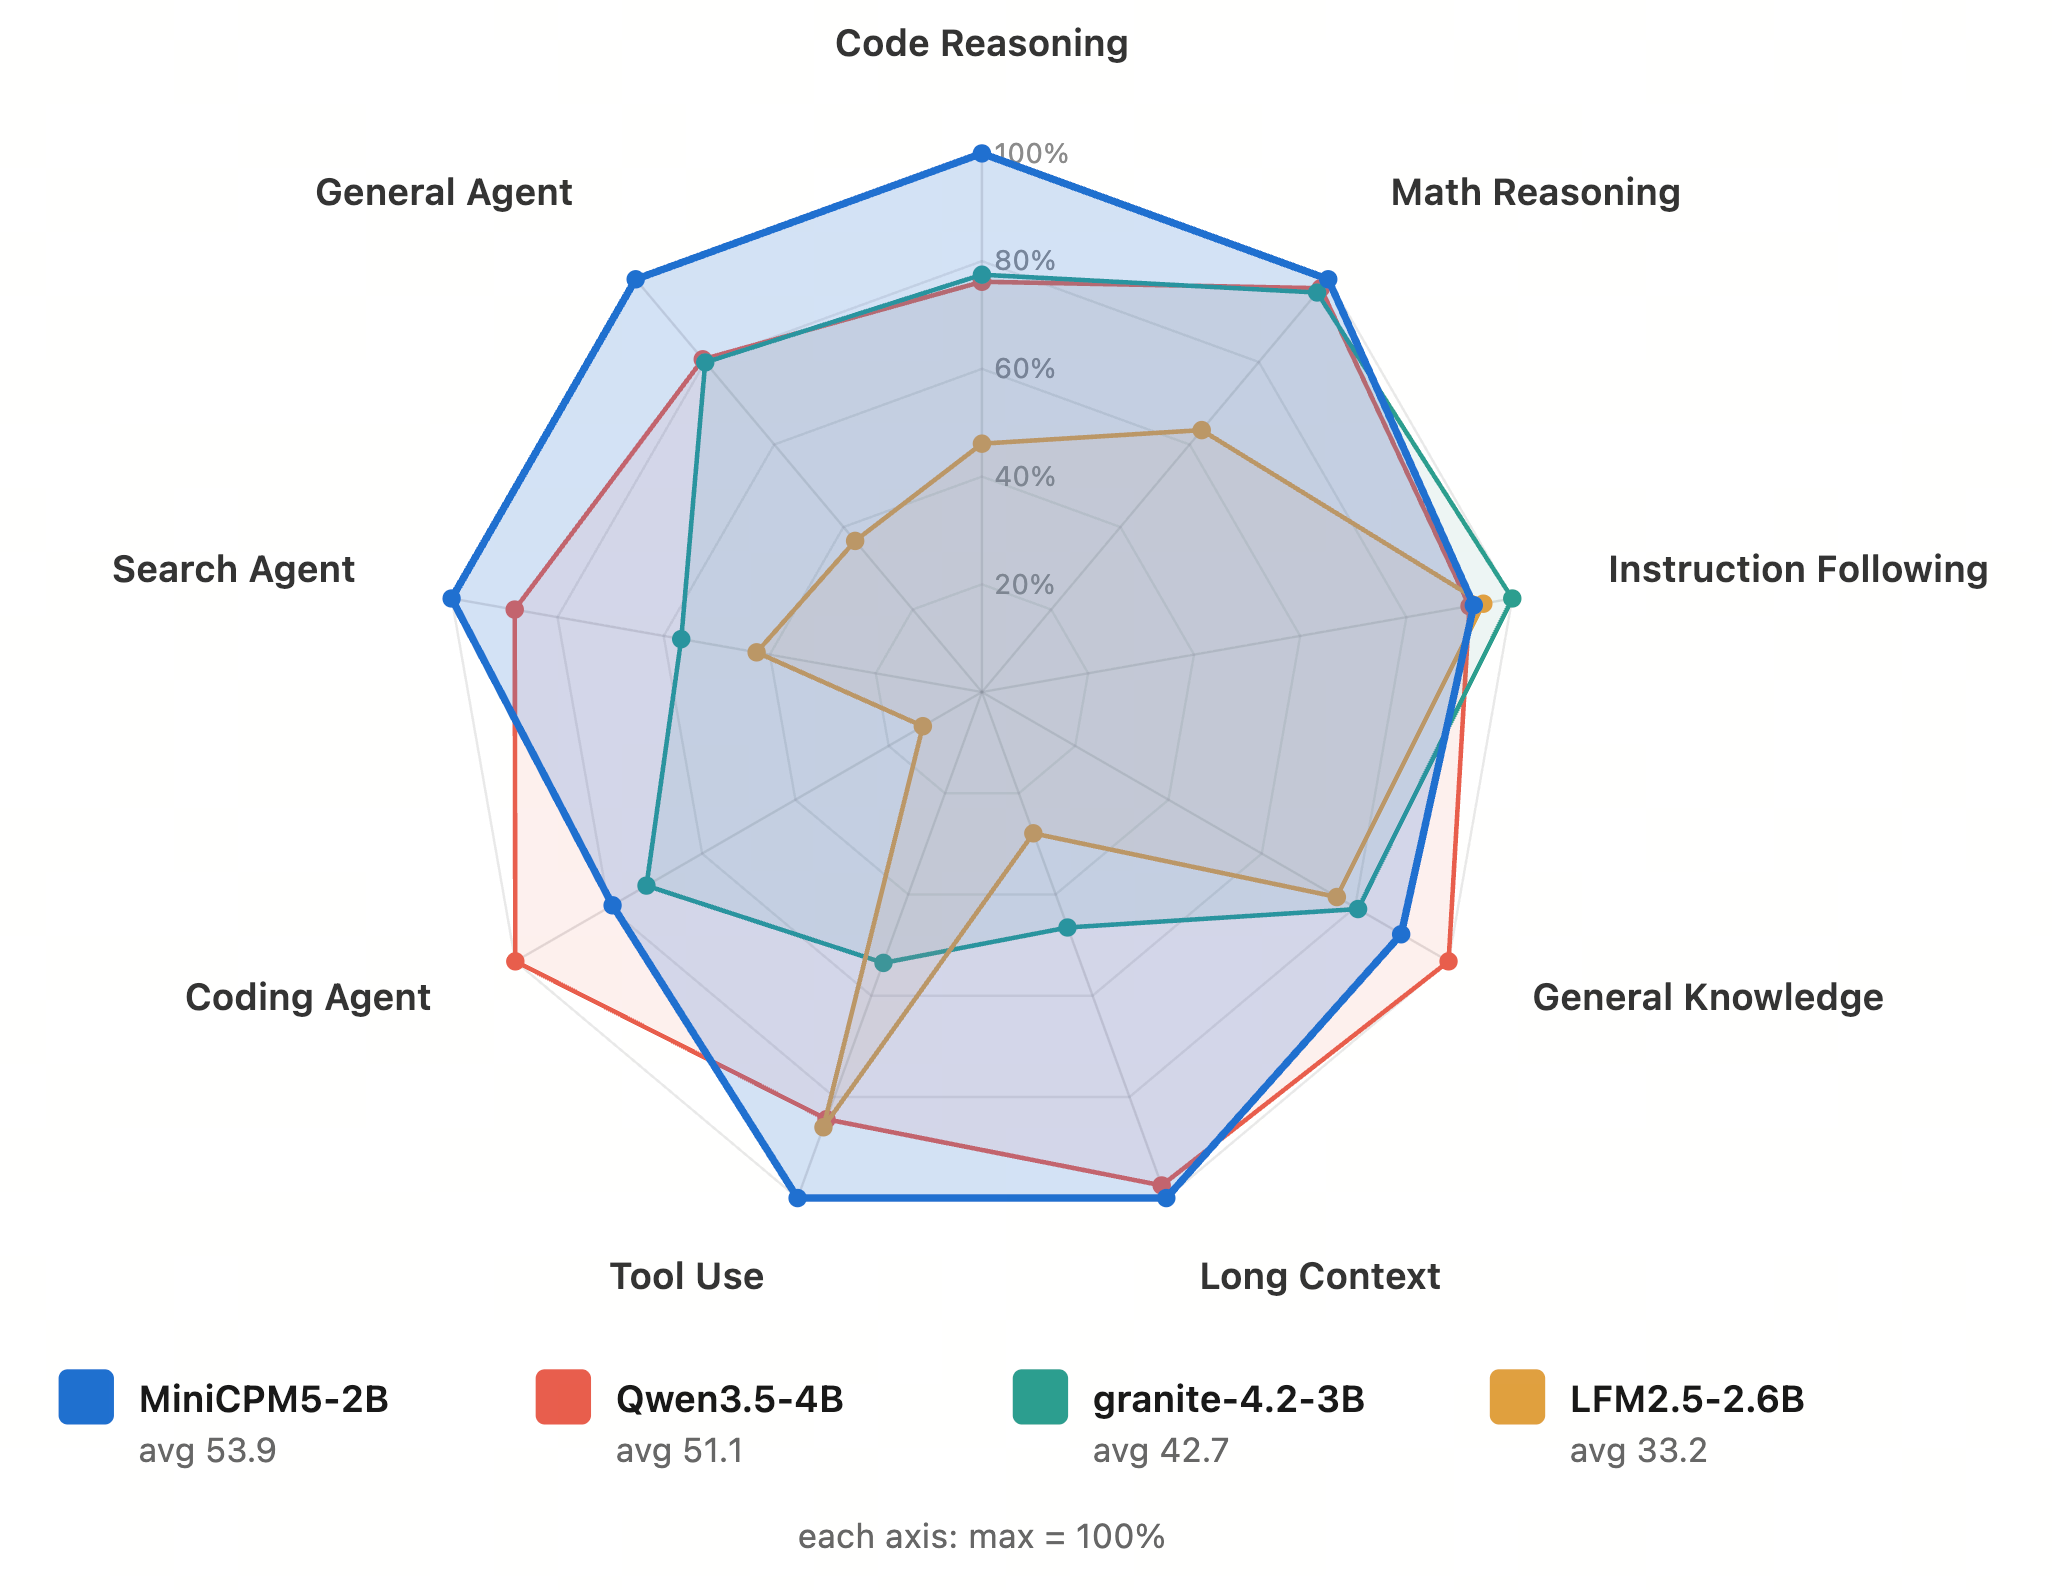
🏆 2B-class open-source SOTA: compared with strong open-source models of similar size, MiniCPM5-2B achieves SOTA performance within this comparison set. It remains competitive with 4B-class models overall, while showing its advantages over models of comparable size in coding, mathematics, long-context understanding, tool use, and agentic tasks.
📂 Open High-Quality Data: Alongside the model, we are releasing the high-quality training datasets behind it as part of the UltraData family: UltraX, a high-quality web pre-training dataset; UltraData-Code, featuring L0–L3 tiered code data management to drive a significant leap in coding capabilities; UltraData-SFT-Agent-2609, comprising 500K agent training samples to enhance comprehensive on-device agent capabilities; and UltraData-RL-2609, with 80K+ high-quality RL training samples covering mathematics, code, general knowledge, and long-context reasoning.
Current release: MiniCPM5-2B / MiniCPM5-1B(BF16 / GGUF / MLX):
MiniCPM5-2B
| HuggingFace | ModelScope | |---|---| | MiniCPM5-2B | MiniCPM5-2B | | MiniCPM5-2B-SFT | MiniCPM5-2B-SFT | | MiniCPM5-2B-Midtrain | MiniCPM5-2B-Midtrain | | MiniCPM5-2B-Base | MiniCPM5-2B-Base | | MiniCPM5-2B-GGUF | MiniCPM5-2B-GGUF | | MiniCPM5-2B-MLX | MiniCPM5-2B-MLX | | MiniCPM5-2B-GPTQ | MiniCPM5-2B-GPTQ | | MiniCPM5-2B-DSpark | MiniCPM5-2B-DSpark |
MiniCPM5-1B
| HuggingFace | ModelScope | |---|---| | MiniCPM5-1B | MiniCPM5-1B | | MiniCPM5-1B-SFT | MiniCPM5-1B-SFT | | MiniCPM5-1B-Base | MiniCPM5-1B-Base | | MiniCPM5-1B-GGUF | MiniCPM5-1B-GGUF | | MiniCPM5-1B-MLX | MiniCPM5-1B-MLX |
Other key releases:
| HuggingFace | ModelScope | |---|---| | MiniCPM-SALA | MiniCPM-SALA | | MiniCPM4.1-8B | MiniCPM4.1-8B | | MiniCPM4-0.5B | MiniCPM4-0.5B |
Earlier flagships:
| HuggingFace | ModelScope | |---|---| | MiniCPM4-8B | MiniCPM4-8B |
MiniCPM4.1 quantized & speculative variants:
| HuggingFace | ModelScope | |---|---| | MiniCPM4.1-8B-GPTQ | MiniCPM4.1-8B-GPTQ | | MiniCPM4.1-8B-AutoAWQ | MiniCPM4.1-8B-AutoAWQ | | MiniCPM-4.1-8B-Marlin | MiniCPM-4.1-8B-Marlin | | MiniCPM4.1-8B-GGUF | MiniCPM4.1-8B-GGUF | | MiniCPM4.1-8B-MLX | MiniCPM4.1-8B-MLX | | MiniCPM4.1-8B-Eagle3 | MiniCPM4.1-8B-Eagle3 |
BitCPM4 ternary-quantized + MiniCPM4 Applications:
| HuggingFace | ModelScope | |---|---| | BitCPM4-1B | BitCPM4-1B | | BitCPM4-0.5B | BitCPM4-0.5B | | MiniCPM4-Survey | MiniCPM4-Survey | | MiniCPM4-MCP | MiniCPM4-MCP |
MiniCPM4 Eagle speculative decoding, QAT, and pre-2025 releases:
| HuggingFace | ModelScope | |---|---| | MiniCPM4-8B-Eagle-FRSpec | MiniCPM4-8B-Eagle-FRSpec | | MiniCPM4-8B-Eagle-FRSpec-QAT | MiniCPM4-8B-Eagle-FRSpec-QAT | | MiniCPM4-8B-Eagle-vLLM | MiniCPM4-8B-Eagle-vLLM | | MiniCPM4-8B-marlin-Eagle-vLLM | MiniCPM4-8B-marlin-Eagle-vLLM | | MiniCPM4-0.5B-QAT-Int4-unquantized | MiniCPM4-0.5B-QAT-Int4-unquantized | | MiniCPM4-0.5B-QAT-Int4-GPTQ-format | MiniCPM4-0.5B-QAT-Int4-GPTQ-format | | MiniCPM3-4B | MiniCPM3-4B | | MiniCPM-2B-sft | MiniCPM-2B-sft | | MiniCPM-2B-dpo | MiniCPM-2B-dpo | | MiniCPM-2B-128k | MiniCPM-2B-128k | | MiniCPM-MoE-8x2B | MiniCPM-MoE-8x2B | | MiniCPM-1B | MiniCPM-1B | | MiniCPM-S-1B | MiniCPM-S-1B |
MiniCPM5-2B is the second checkpoint in the MiniCPM5 series, scaling the MiniCPM5-1B recipe up to 2B parameters for users who can afford a larger footprint in exchange for stronger capability. It is designed for local assistants, coding agents, tool-use workflows, and reasoning scenarios where a compact model is preferred. The model keeps a small deployment footprint while providing native long-context support.
| | |
|---|---|
| Architecture | Standard LlamaForCausalLM |
| Parameters | 2,516,756,480 (non-embedding: 1,981,982,720) |
| Layers | 42 |
| Attention Heads (GQA) | 16 Q / 2 KV |
| Context Length | 131,072 |
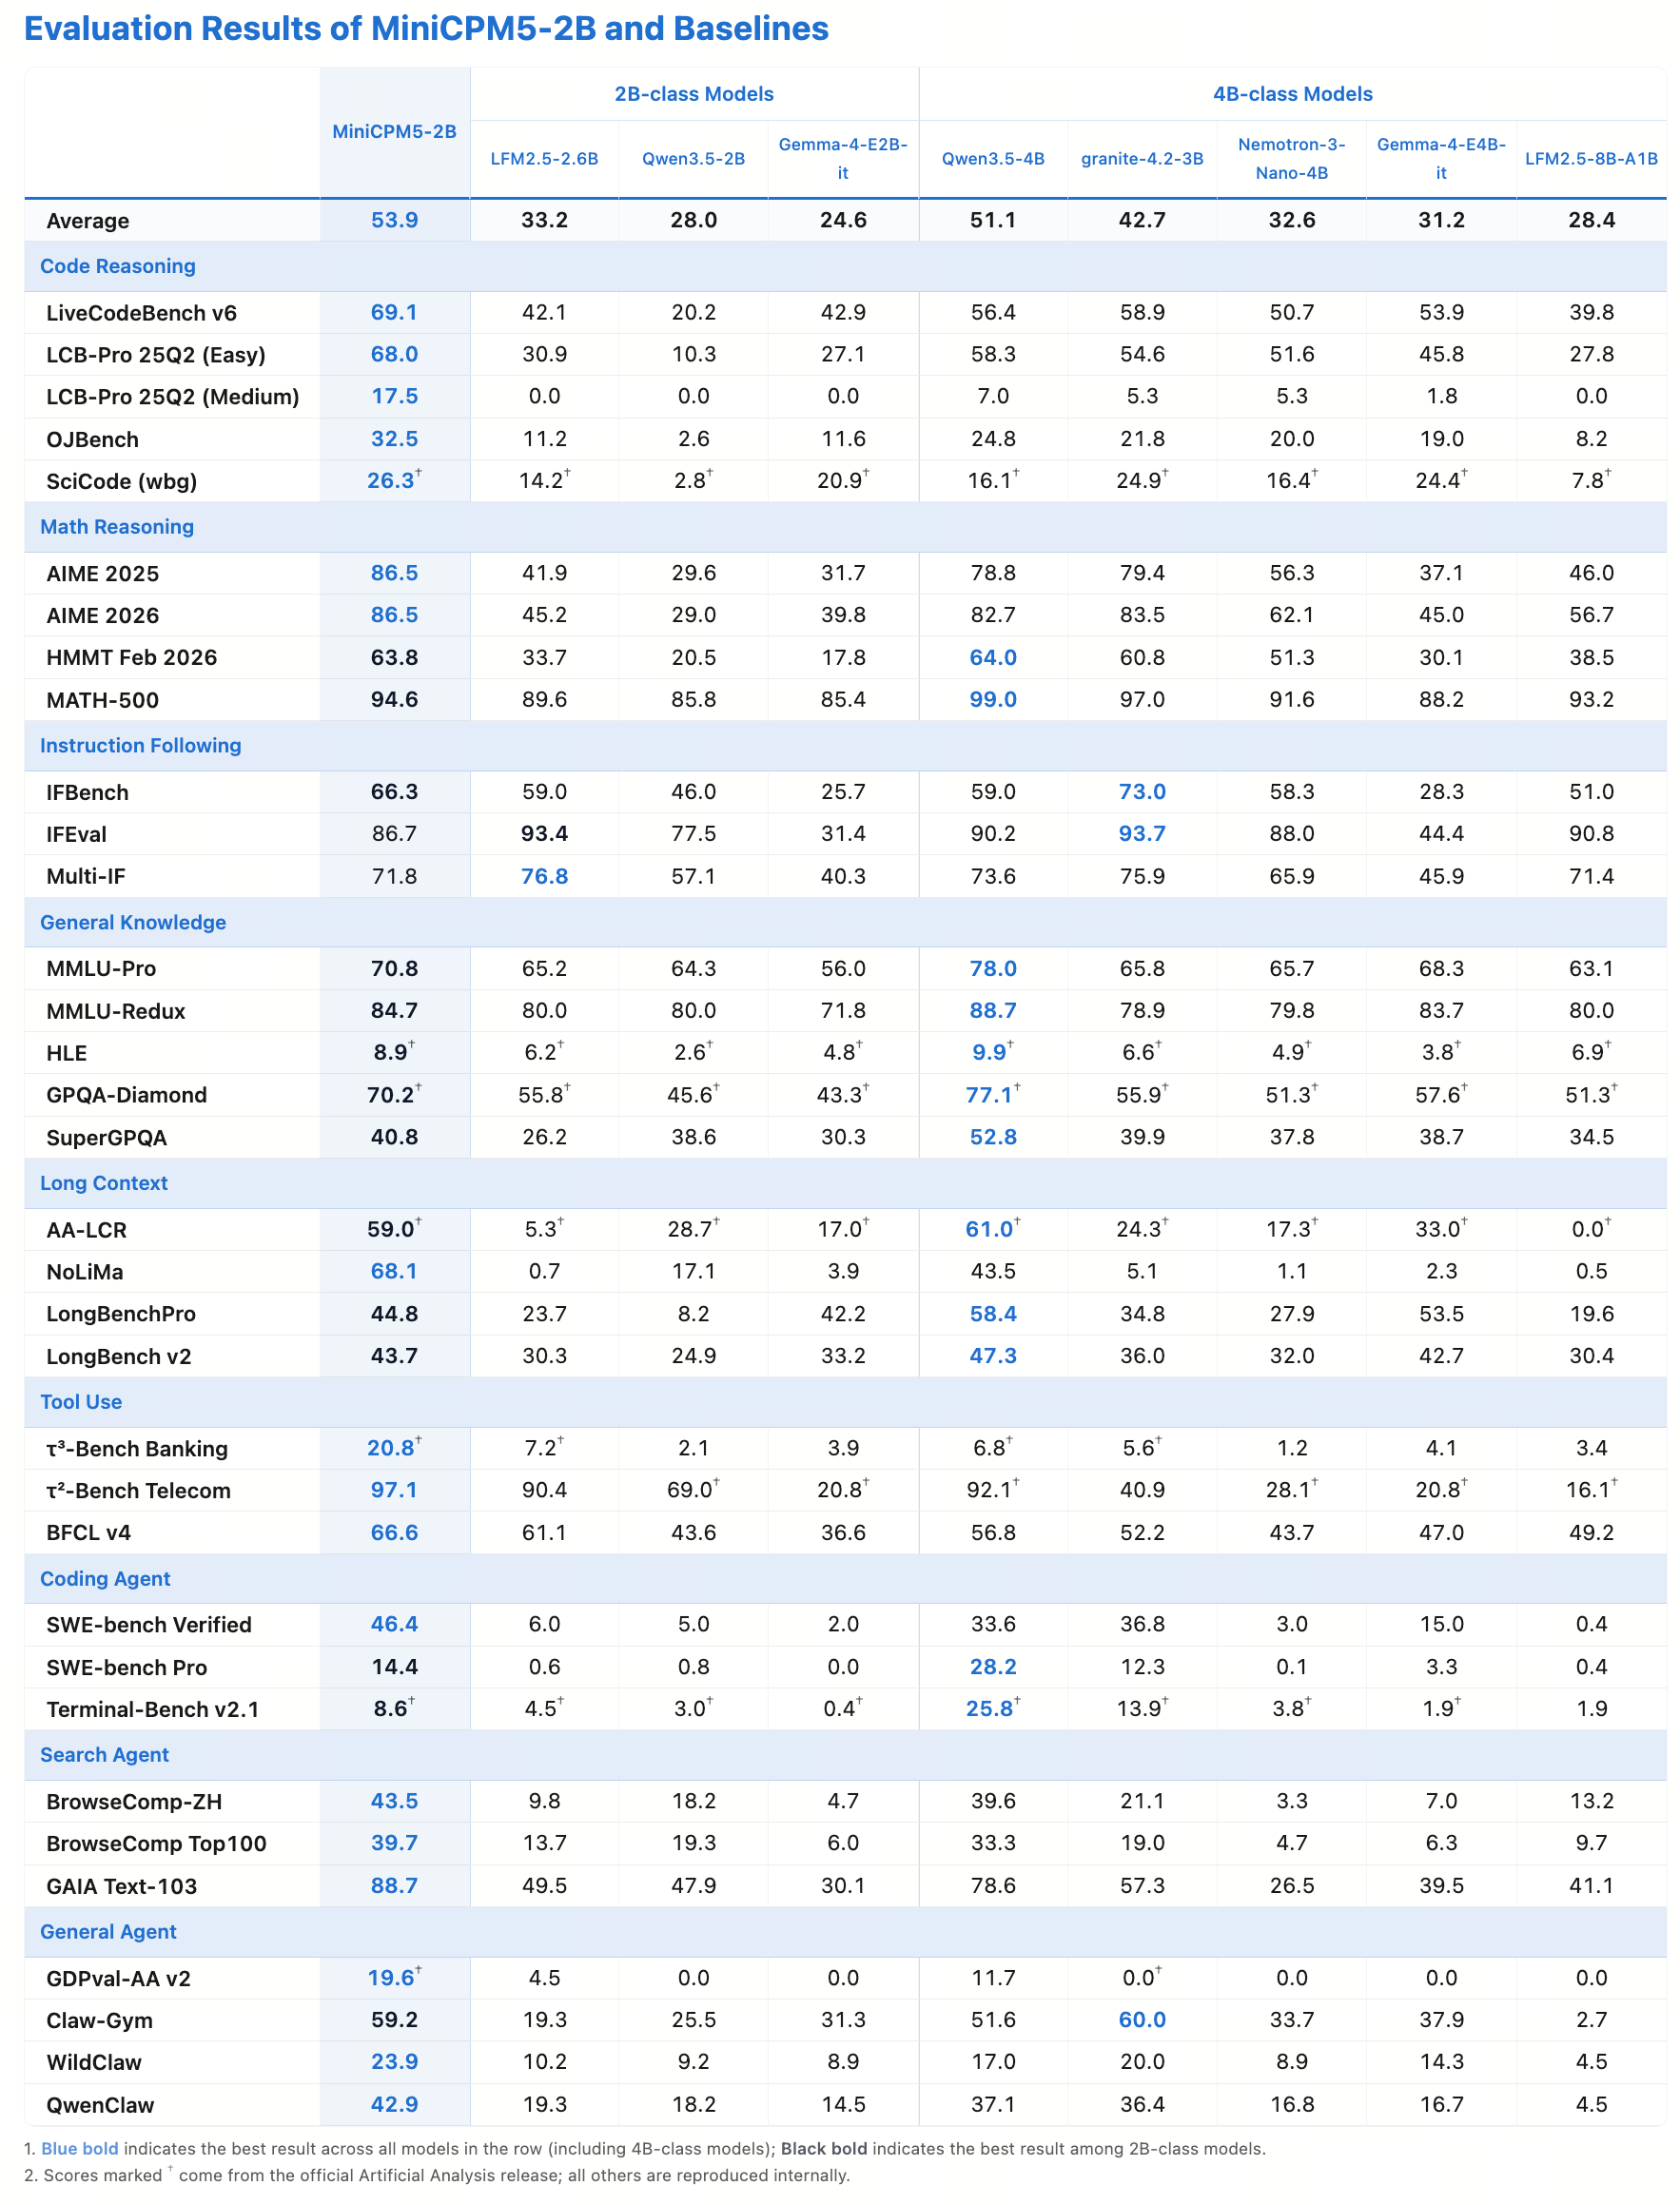
We compare MiniCPM5-2B with strong open-source models in the same size class, including LFM2.5-2.6B, Qwen3.5-2B, and Gemma-4-E2B-it, while also listing larger models such as Qwen3.5-4B, granite-4.2-3B, Nemotron-3-Nano-4B, Gemma-4-E4B-it, and LFM2.5-8B-A1B for reference.
Within this comparison set, MiniCPM5-2B reaches 2B-class open-source SOTA with an average score of 53.9, and also exceeds all of the larger models included here (the highest is 51.1). Its advantages are most visible in code reasoning, math reasoning, long-context understanding, tool use, and multiple agentic tasks.
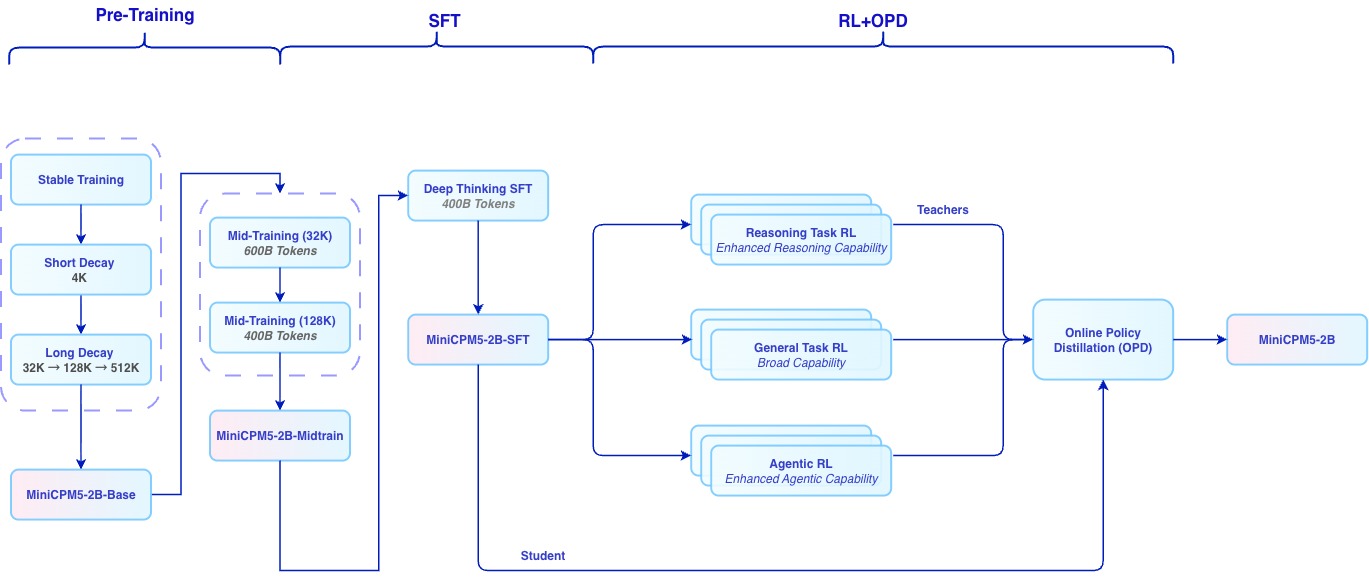
The training of MiniCPM5-2B is a full-stack practice of UltraData Tiered Data Management, covering three stages: base training, mid-training, and post-training.
During base training, the model goes through stable training and decay training to build core language capability and training stability. It then enters mid-training to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as Ultra-FineWeb, Ultra-FineWeb-L3, UltraX, UltraData-Code and UltraData-Math.
During post-training, we proceed in three steps: SFT, RL, and OPD. We first use 400B tokens of deep-thinking SFT to establish deep-thinking and general chat abilities; the SFT data is released as UltraData-SFT-2605 and Agent SFT data as UltraData-SFT-Agent-2609. We then train specialized RL teachers for math, code, agentic tasks, writing, and related domains(with the corresponding data also open-sourced as UltraData-RL-2609), and use On-Policy Distillation (OPD) to distill these teachers back into one release model.
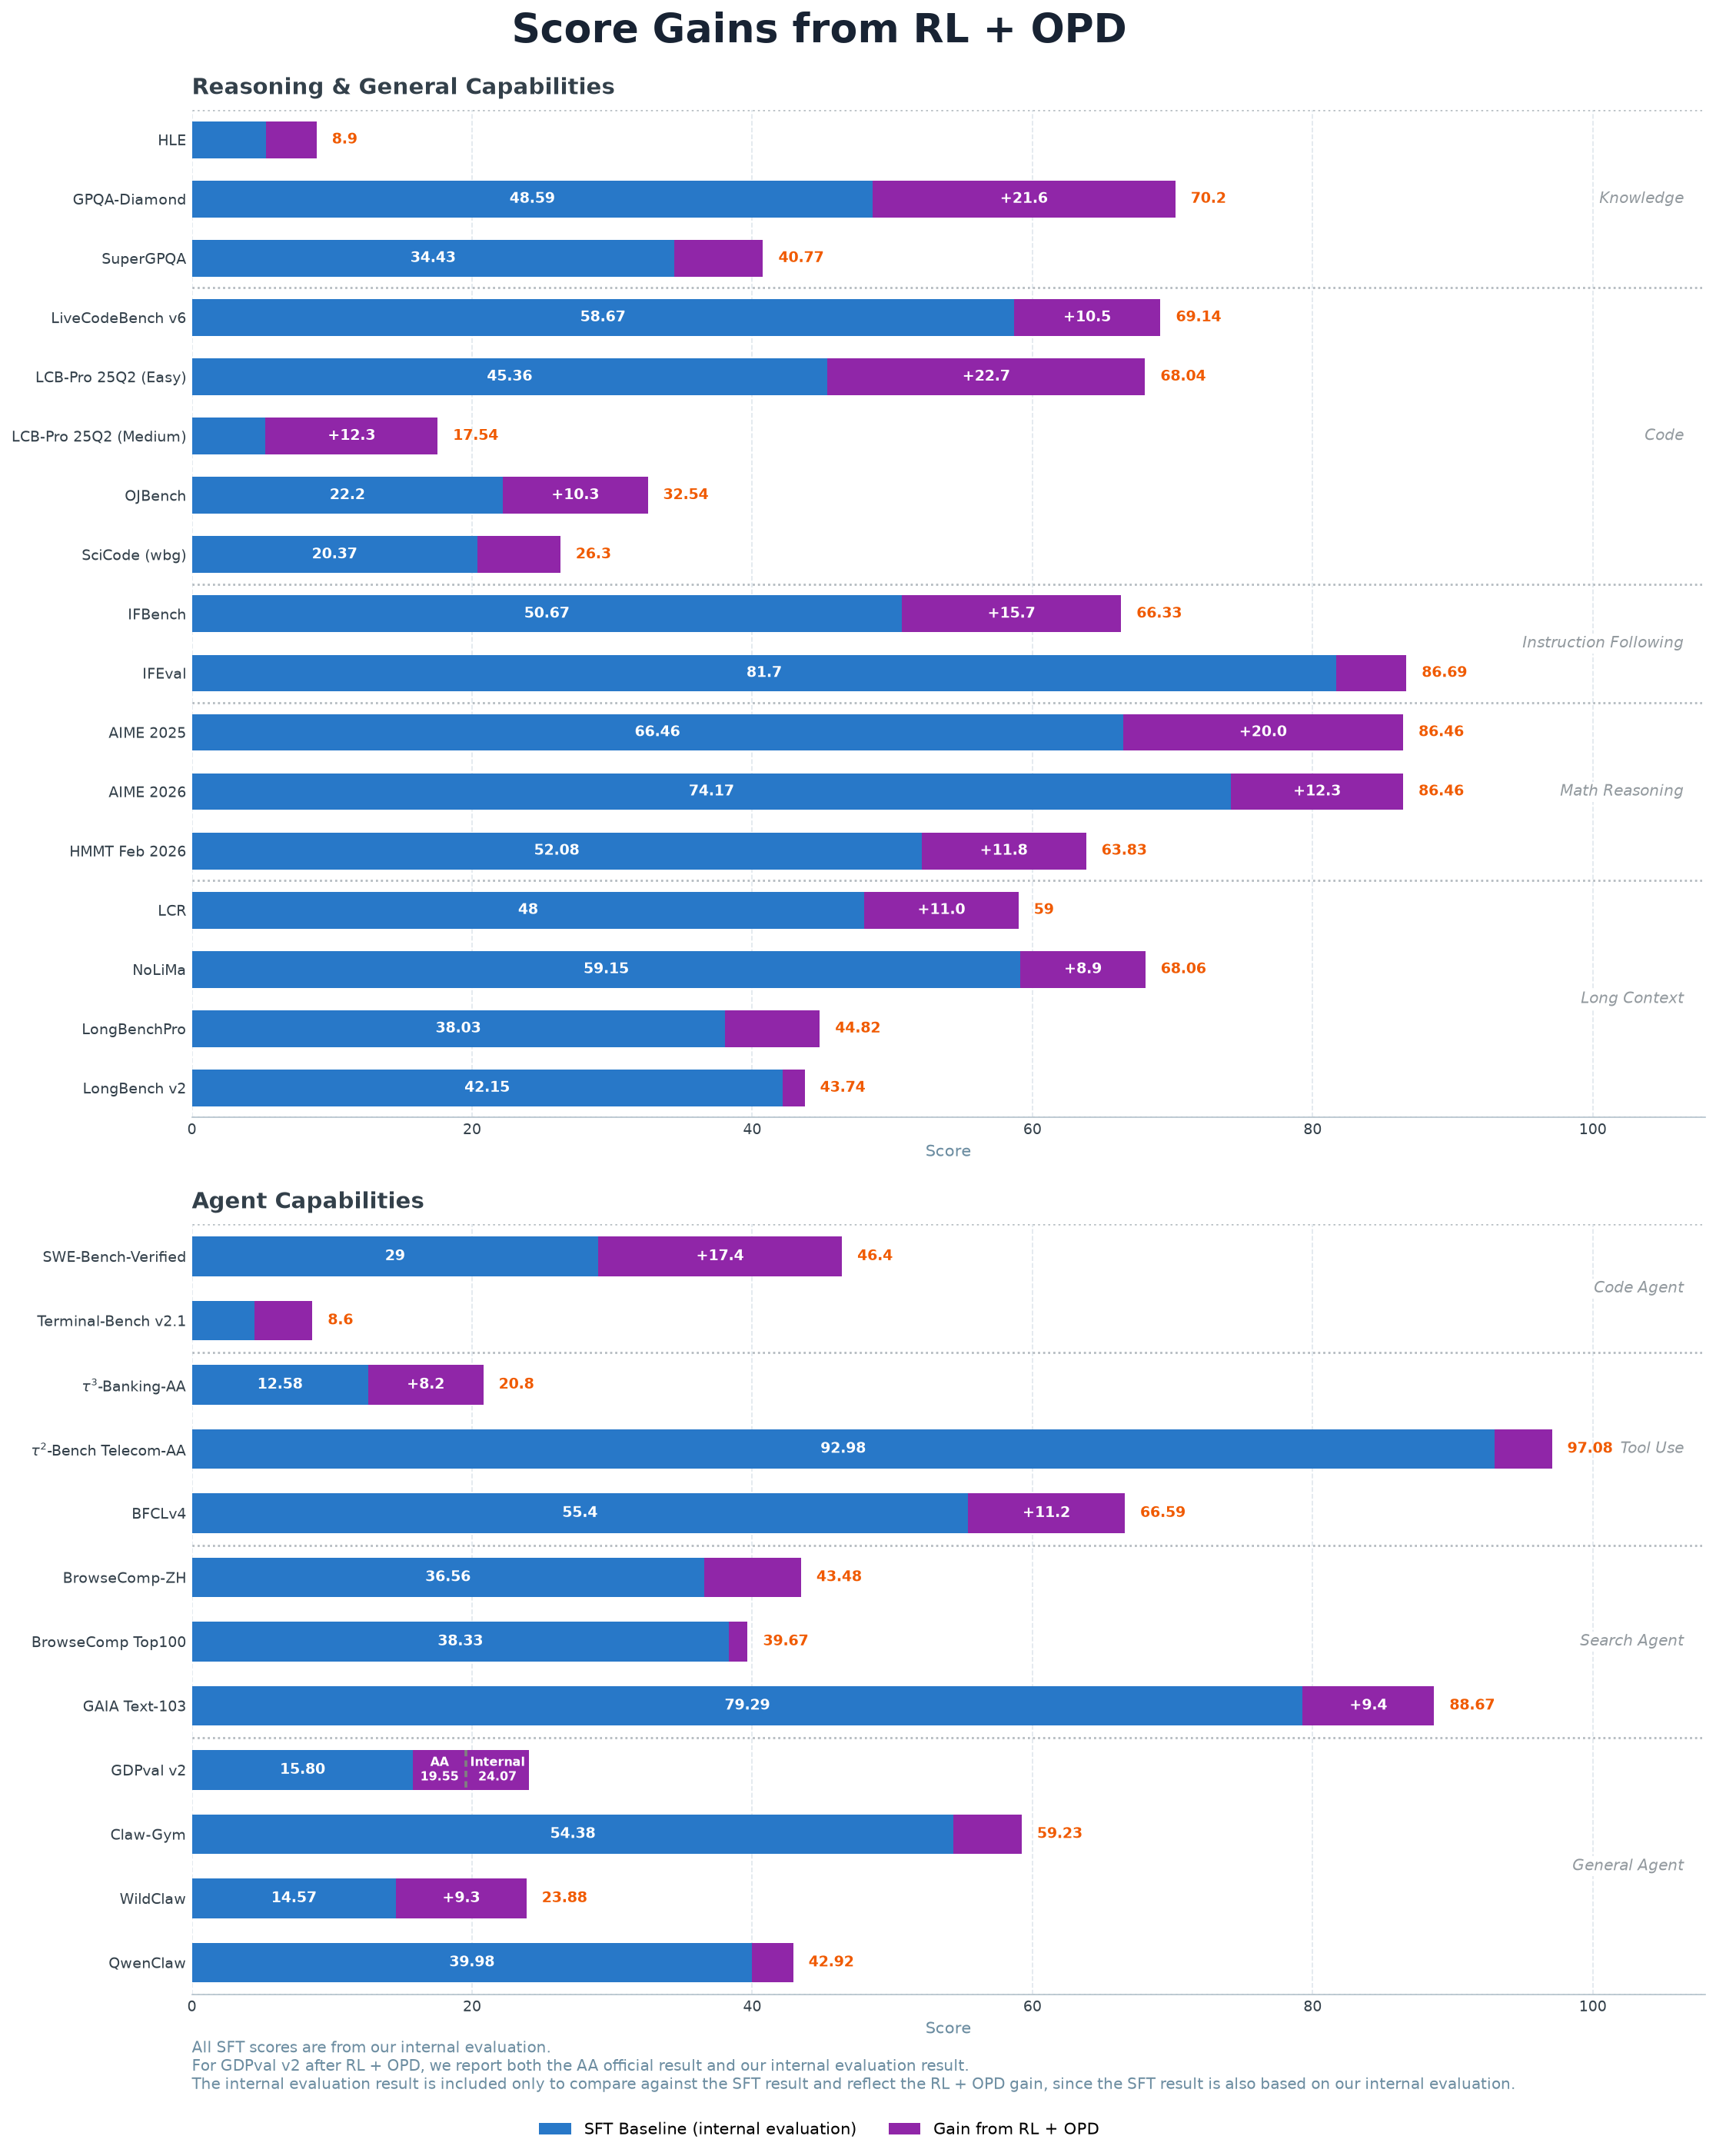
RL + OPD is a key part of MiniCPM5-2B post-training. During the RL stage, we adopted the critic-based algorithm described in JustRL II, substantially improving training stability and achieving significant gains across multiple domains. On the benchmarks listed below, RL + OPD improves reasoning and general capabilities by an average of ↑10.96 points, and agentic capabilities by ↑6.96 points.
OPD merges the capabilities of 16 expert models produced by RL training, including 5 agentic expert models. At each response position, we compute the full-vocabulary reverse KL divergence between student and teacher logits as the advantage estimate, replacing the original verification-based advantage. OPD directly reuses the prompts used to train each RL teacher as distillation data, so no additional corpus construction is required.
We recommend using the following sets of sampling parameters for generation: temperature=1.0, top_p=0.95, min_p=0.0.
If you encounter repetitive outputs, try: temperature=1.0, top_p=0.95, min_p=0.0, repetition_penalty=1.05.
Please note that the support for sampling parameters varies according to inference frameworks.
pip install "vllm>=0.21"
vllm serve openbmb/MiniCPM5-2B --port 8000
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openbmb/MiniCPM5-2B",
    "messages": [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}],
    "max_tokens": 128,
    "temperature": 1.0, "top_p": 0.95
  }'
pip install "sglang[srt]>=0.5.16"
python -m sglang.launch_server --model-path openbmb/MiniCPM5-2B --port 30000
curl http://localhost:30000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openbmb/MiniCPM5-2B",
    "messages": [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}],
    "max_tokens": 128,
    "temperature": 1.0, "top_p": 0.95
  }'
Speculative decoding (DSpark): we also release MiniCPM5-2B-DSpark, a DSpark draft model trained for MiniCPM5-2B. Enable it in SGLang to accelerate decoding while keeping the target model's outputs unchanged:
python -m sglang.launch_server \
  --model-path openbmb/MiniCPM5-2B \
  --trust-remote-code \
  --speculative-algorithm DSPARK \
  --speculative-draft-model-path openbmb/MiniCPM5-2B-DSpark \
  --speculative-dspark-block-size 7 \
  --port 30000
llama-server -m MiniCPM5-2B-F16.gguf -a MiniCPM5-2B --port 8080 -ngl 99 -c 8192 --jinja
-c 8192 sets the context length. You can adjust this value as needed.
curl http://localhost:8080/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d '{
        "model": "MiniCPM5-2B",
        "messages": [{"role": "user", "content": "1+1=?"}],
        "temperature": 1.0, "top_p": 0.95, "min_p": 0.0, "max_tokens": 256
    }'
In llama.cpp, the default min_p=0.05 can lead to repetitive output: it filters out tokens whose probability is below 5% of the highest-probability token, potentially discarding the exact tokens needed to break out of a repetition loop. To prevent this, we set min_p=0.0.
pip install -U "transformers>=5.6" accelerate torch
from transformers import AutoModelForCausalLM, AutoTokenizer
model_id = "openbmb/MiniCPM5-2B"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype="auto",
    device_map="auto",
)
messages = [{"role": "user", "content": "Who are you? Please briefly introduce yourself."}]
inputs = tokenizer.apply_chat_template(
    messages,
    tokenize=True,
    add_generation_prompt=True,
    enable_thinking=True,
    return_dict=True,
    return_tensors="pt",
).to(model.device)
outputs = model.generate(inputs, max_new_tokens=128)
print(tokenizer.decode(outputs[0][inputs["input_ids"].shape[-1]:], skip_special_tokens=True))
For tool / function calling, SGLang is the recommended backend. MiniCPM5-2B emits XML-style tool calls and SGLang's built-in minicpm5 parser converts them to OpenAI-compatible tool_calls natively:
python -m sglang.launch_server --model-path openbmb/MiniCPM5-2B --port 30000 \
    --tool-call-parser minicpm5      # or: --tool-call-parser auto
MiniCPM5-2B uses the standard LlamaForCausalLM architecture, so mainstream inference engines can load it directly: no custom kernels, no model-code fork**. For step-by-step deployment and fine-tuning instructions, use the GitHub cookbooks below. Agent Skills are linked as GitHub resources for users working with Cursor / Claude Code style coding agents.
| Backend | Model format / use case | Cookbook | Agent Skill |
| --- | --- | --- | --- |
| Transformers | BF16 / FP16 local Python inference, GPU + CPU | transformers.md | minicpm5-deploy-transformers |
| vLLM | BF16 / FP16 OpenAI server | vllm.md | minicpm5-deploy-vllm |
| SGLang | BF16 / FP16 OpenAI server, recommended for tool calling | sglang.md | minicpm5-deploy-sglang |
| llama.cpp | GGUF local inference, CPU/GPU | llama_cpp.md | minicpm5-deploy-llama-cpp |
| Ollama | GGUF local on-device runtime | ollama.md | minicpm5-deploy-ollama |
| LM Studio | GGUF Mac desktop app and OpenAI server | lmstudio.md | minicpm5-deploy-lmstudio |
| MLX | MLX / 4bit local inference on Apple Silicon | mlx.md | minicpm5-deploy-mlx |
| ArcLight | GGUF local on-device, CPU, Desktop & Server | arclight.md | minicpm5-deploy-arclight |
| LiteRT-LM | .litertlm on-device runtime: Android / iOS / desktop / IoT, CPU + GPU | litert.md | minicpm5-deploy-litert |
| vLLM Ascend | BF16 / FP16 OpenAI server | vllm_ascend.md | [minicpm5-deploy-vllm-ascend](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-deploy-vl
→ →
 →
 →
 →
 →