1
 →

LLM inference in C/C++
LLM inference in C/C++


ggml / ops / maintainer PRs%20sort%3Aupdated-desc) / dev stats / lib llama API / llama-server REST API
A few options to get llama.cpp installed on your machine:
# Download and run a model directly from Hugging Face
llama cli -hf ggml-org/Qwen3.5-0.8B-GGUF
Launch OpenAI-compatible API server
llama serve -hf ggml-org/Qwen3.5-0.8B-GGUF
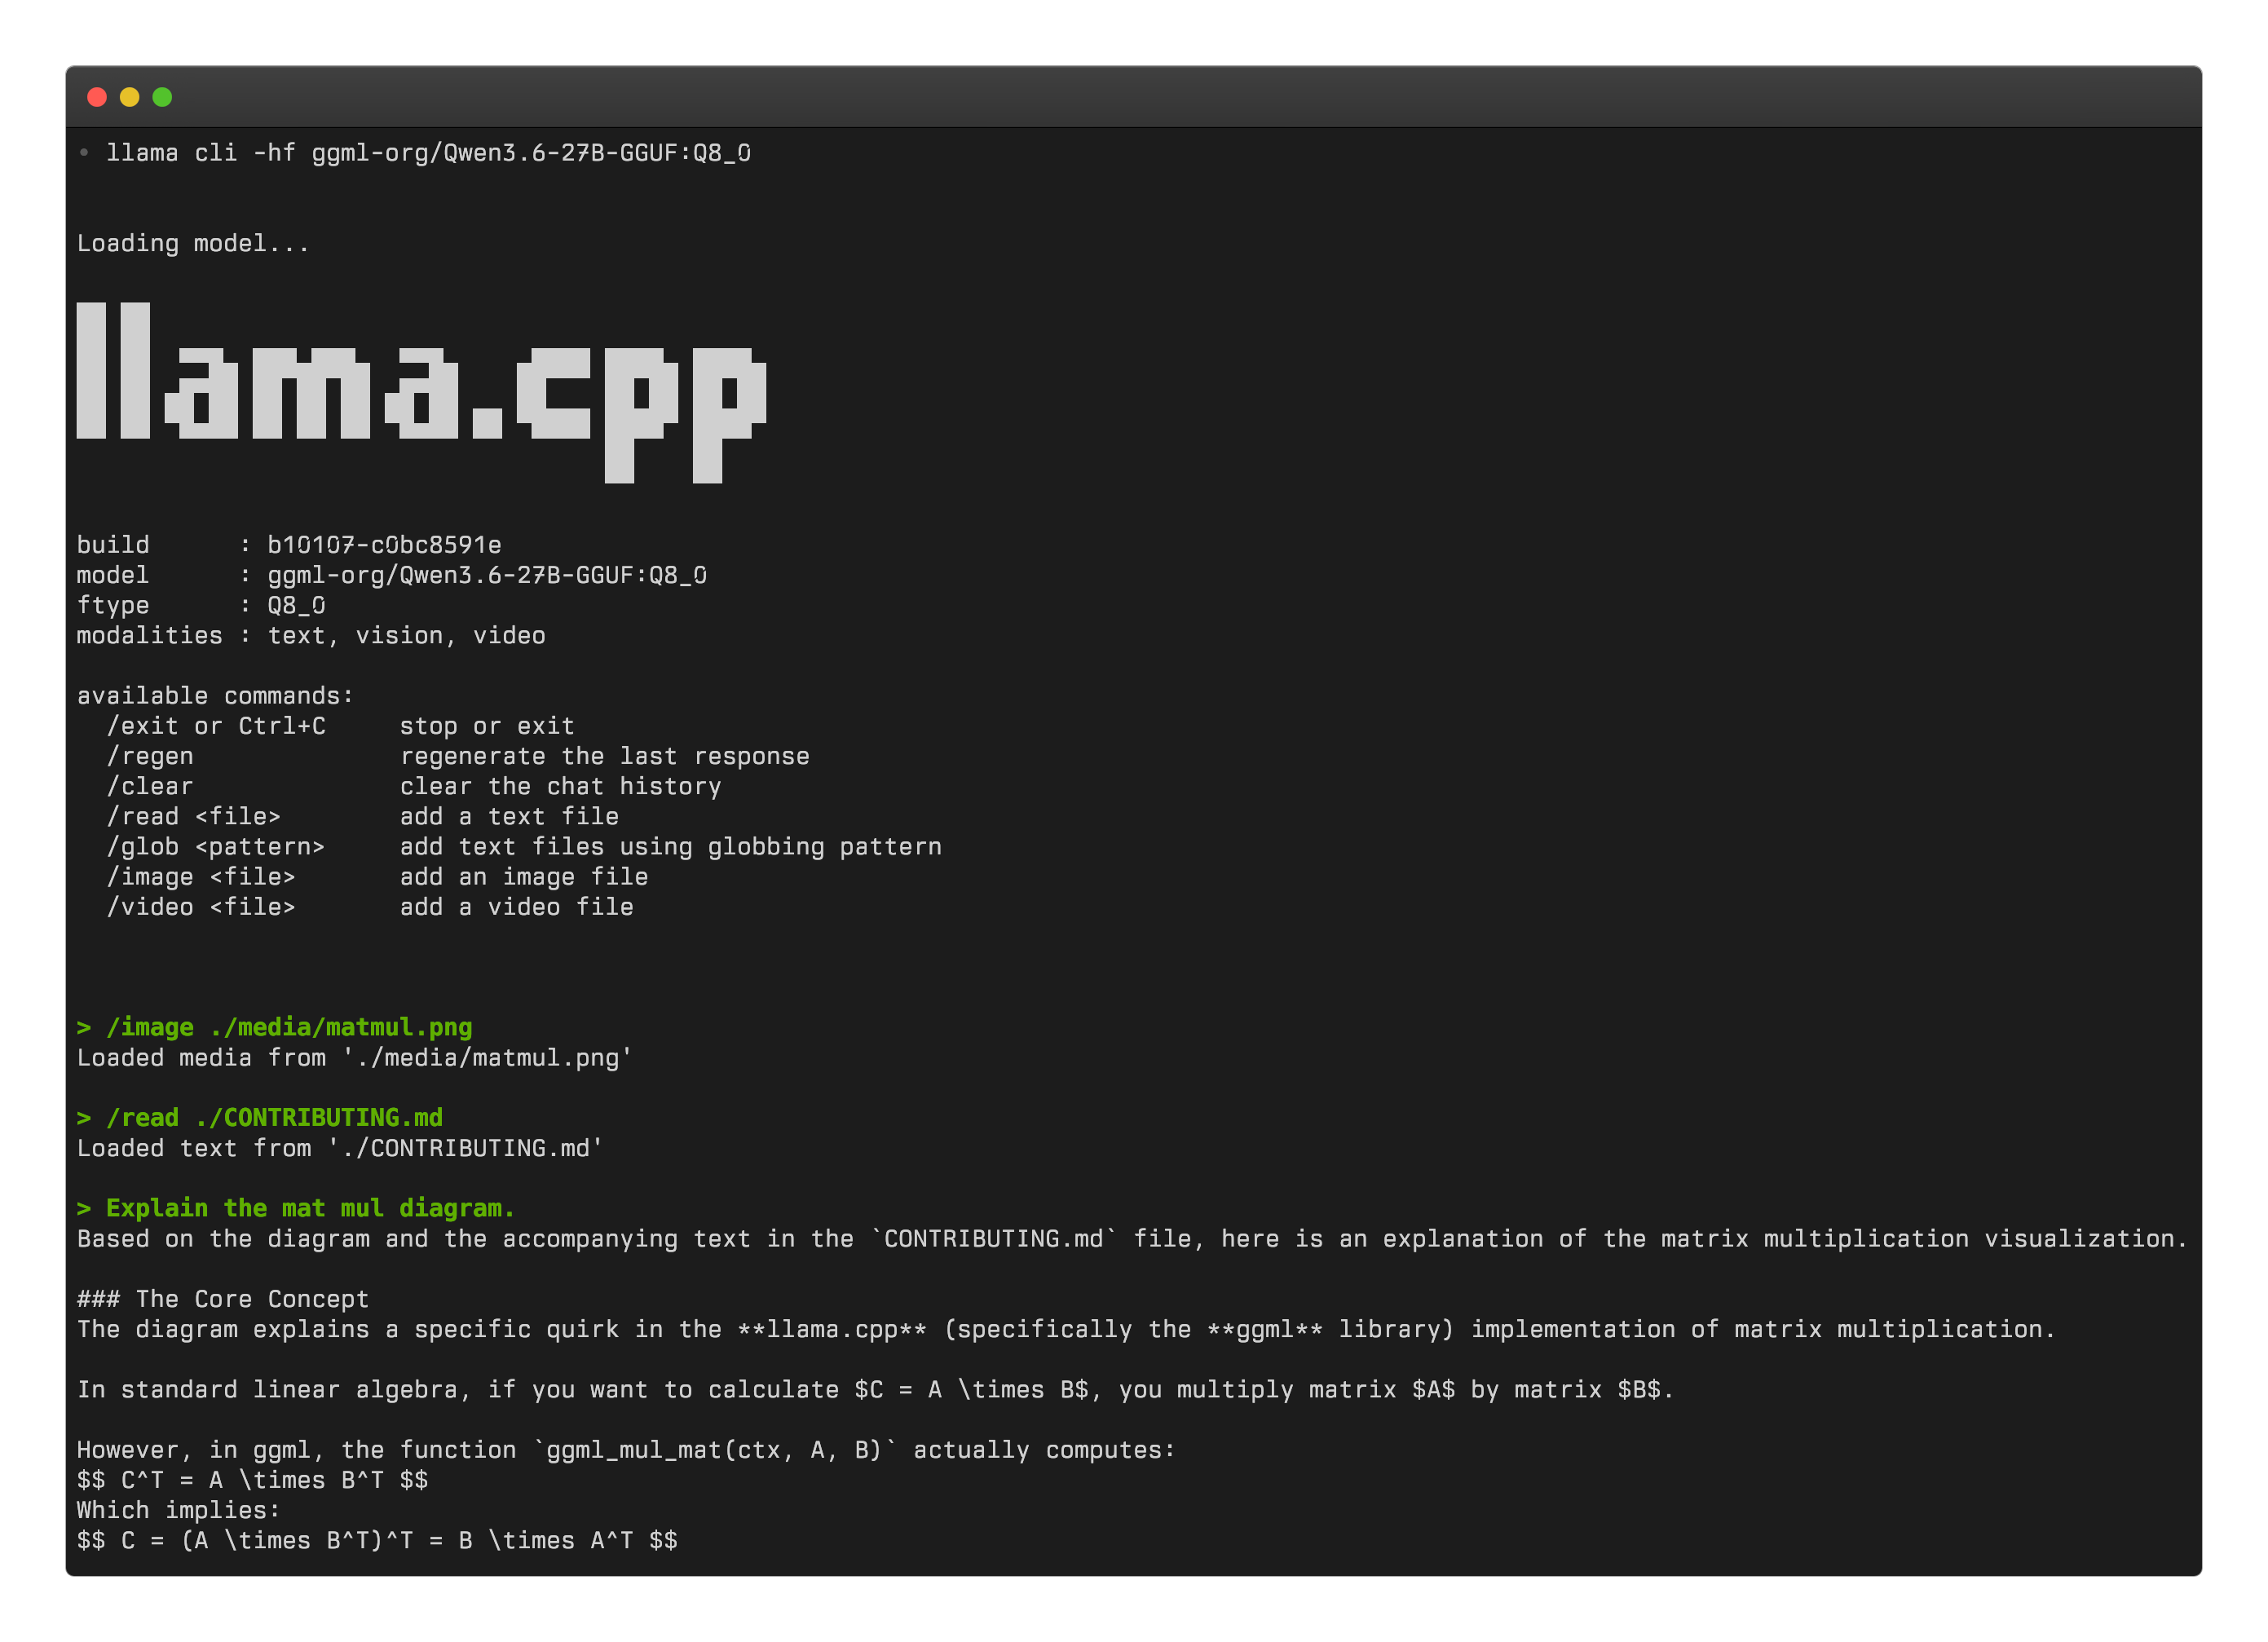 VLM session with llama cli |
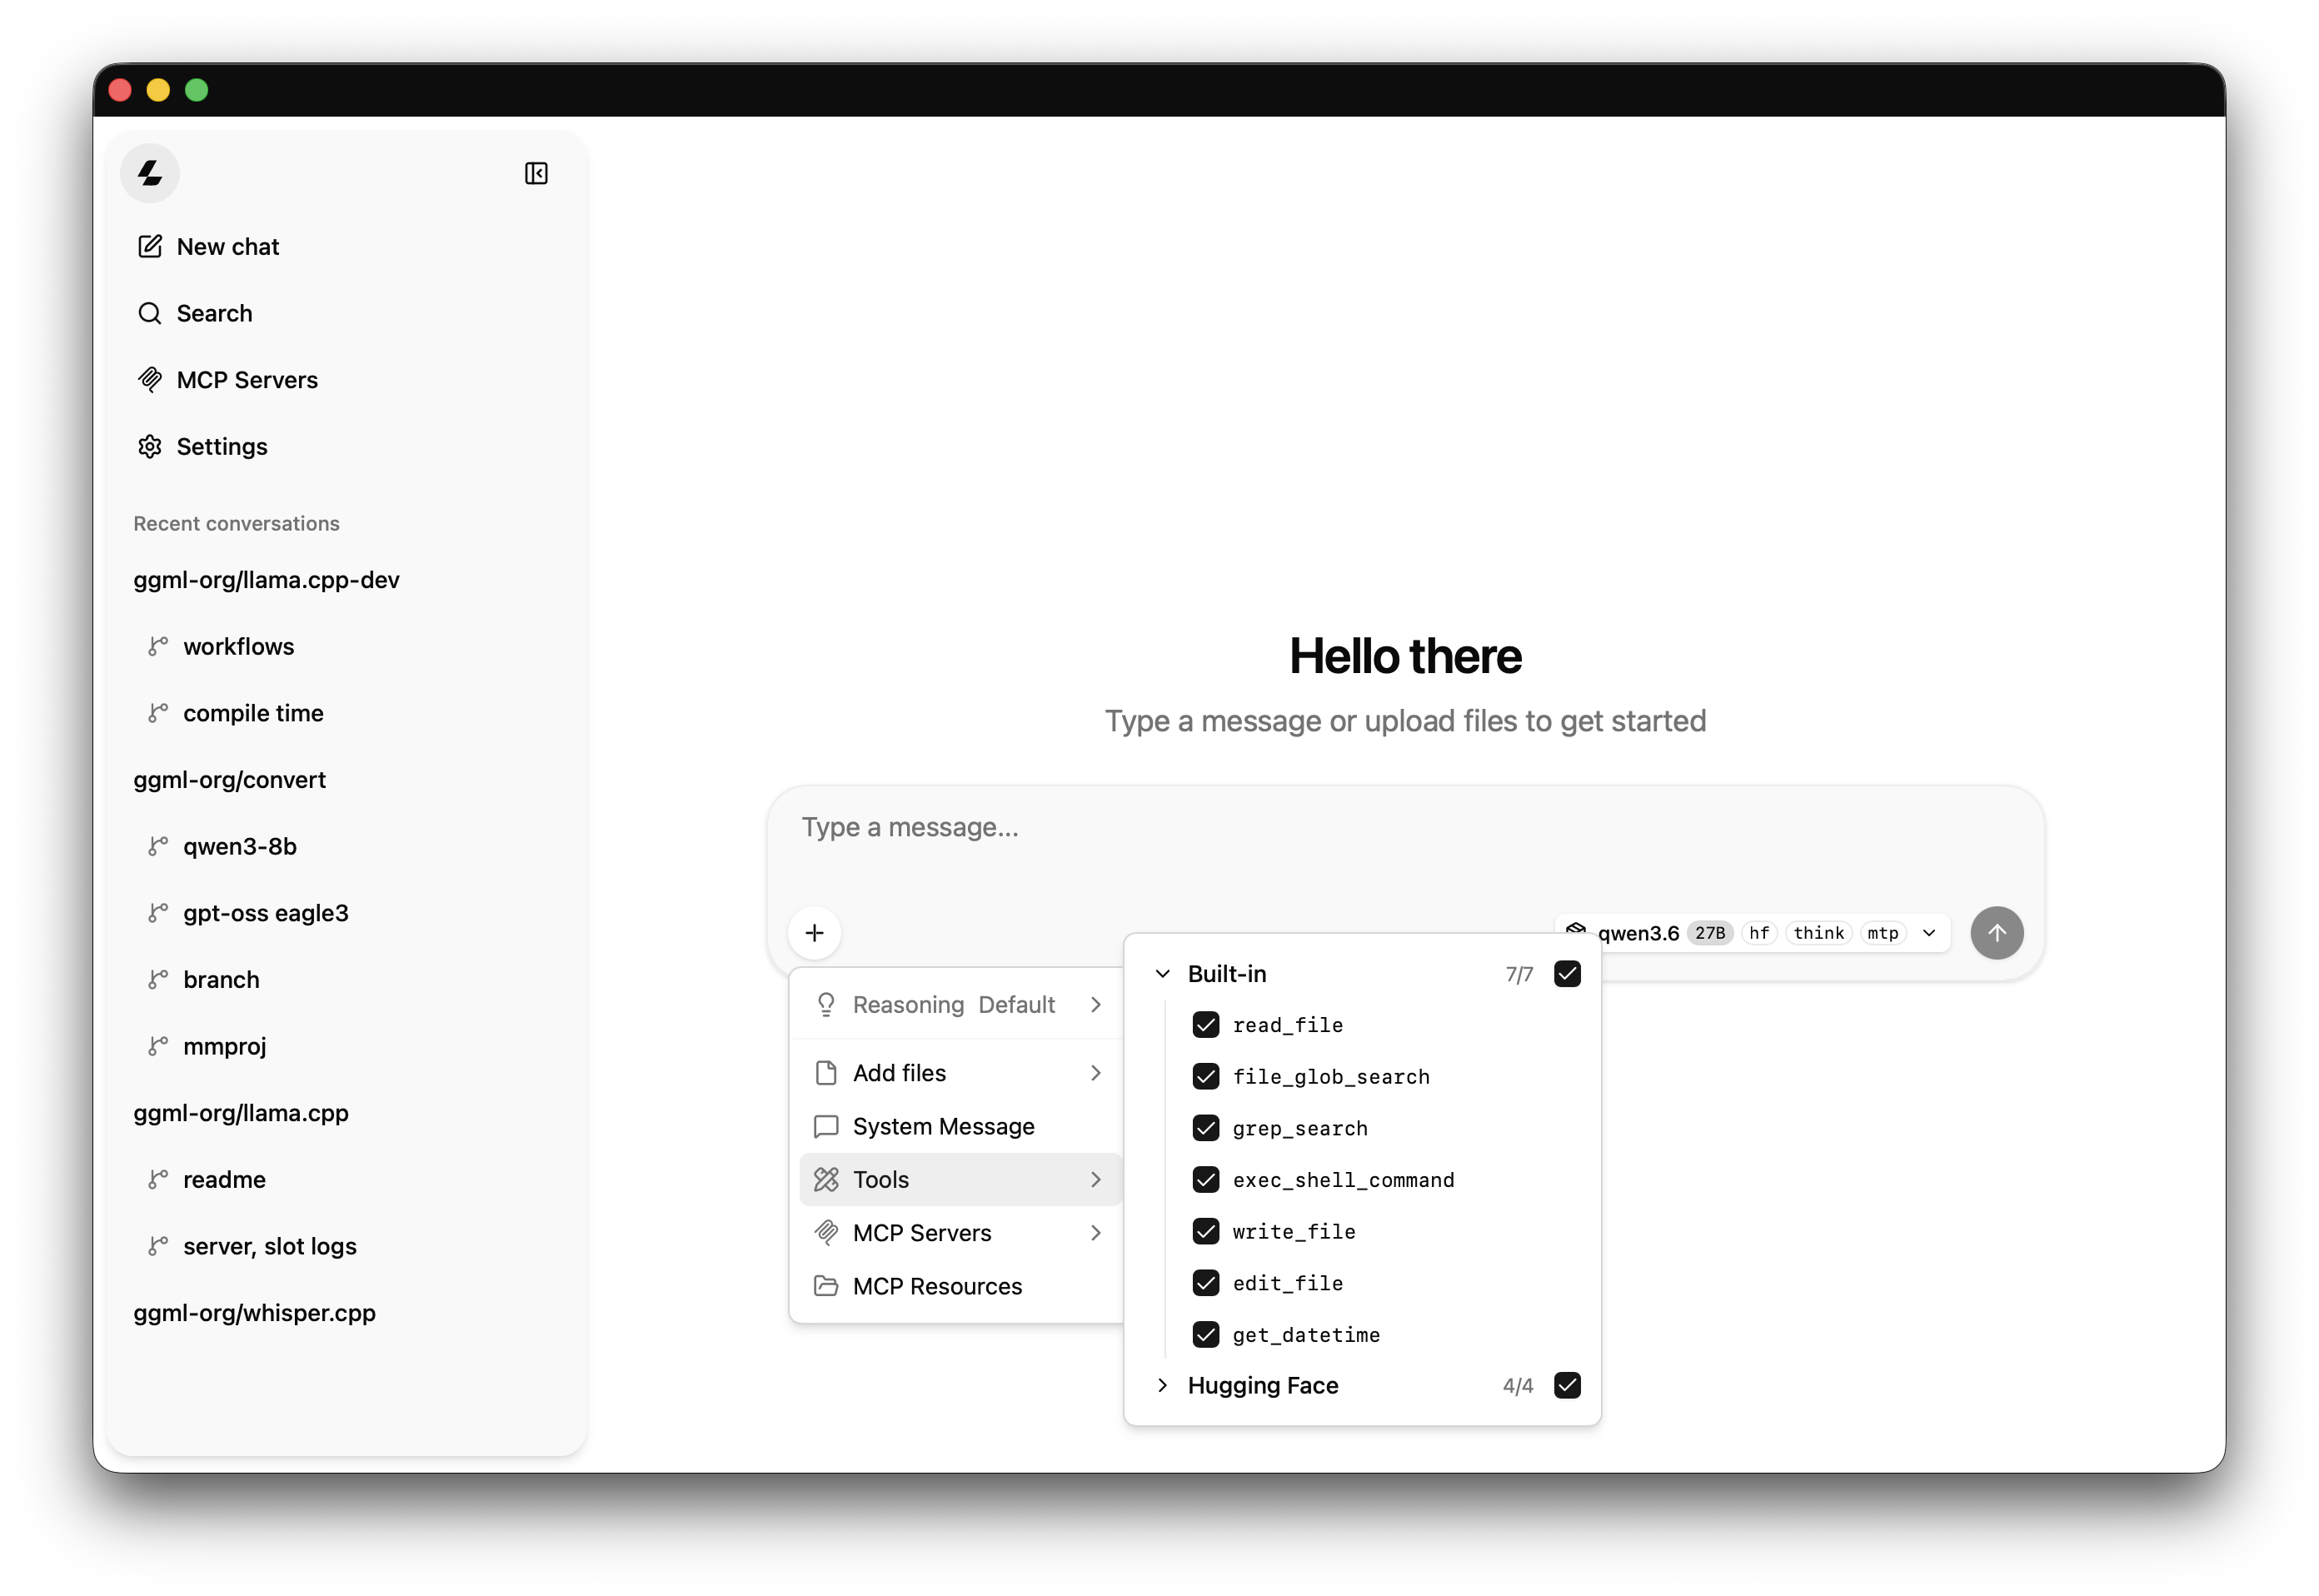 Built-in web UI against llama serve |